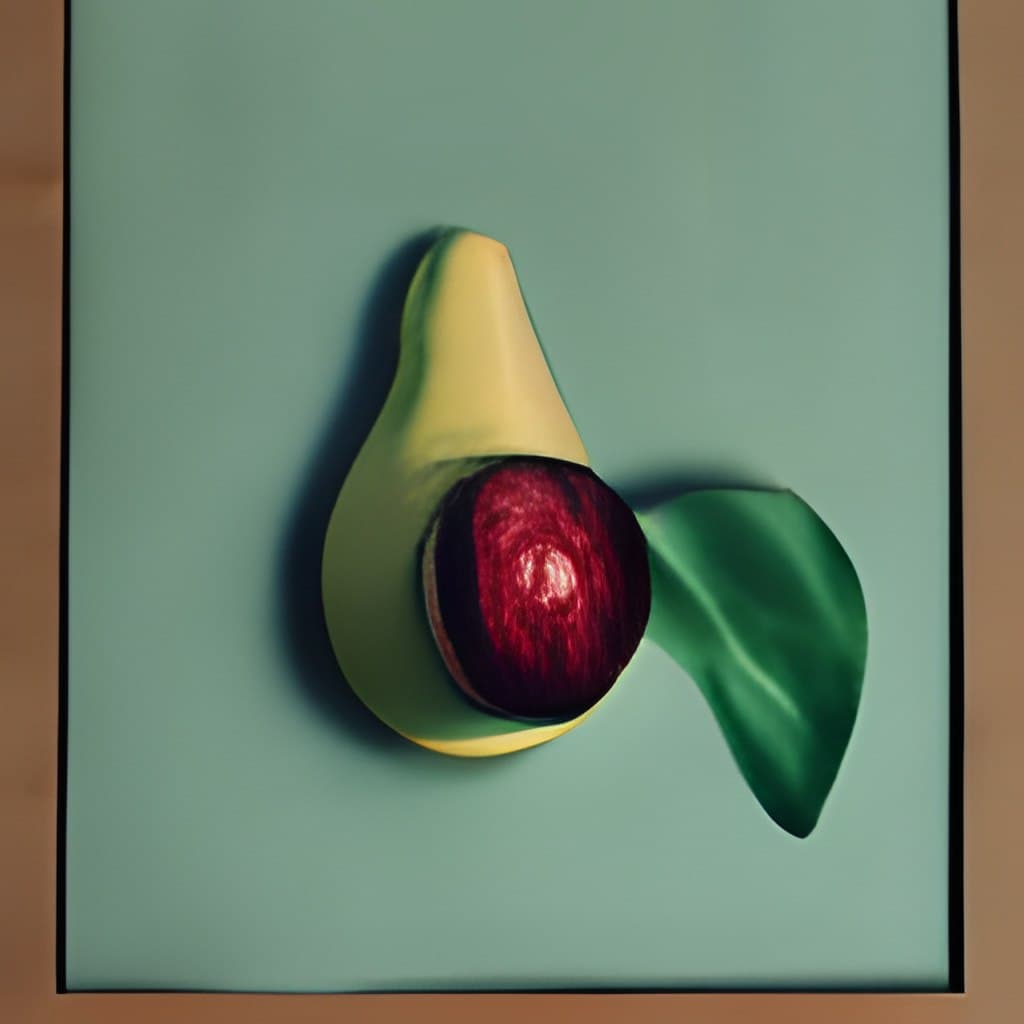
 "Avocado painting in the style of Malevich"
Model was trained by Sber AI and SberDevices teams.
text2image generationencoder-decoder1.3 B120 million text-image pairsThis is a 1.3 billion parameter model for Russian, recreating OpenAI's DALL·E, a model capable of generating arbitrary images from a text prompt that describes the desired result.
The generation pipeline includes ruDALL-E, ruCLIP for ranging results, and a superresolution model. You can use automatic translation into Russian to create desired images with ruDALL-E.
The easiest way to get familiar with the code and the models is to follow the inference notebook we provide in our github repo.
One might say that “investigate, master, and train” is our engineering motto. Well, we caught the scent, and today we can say that we created from scratch a complete pipeline for generating images from descriptive textual input written in Russian.
Teams at SberAI, SberDevices, Samara University, AIRI and SberCloud all actively contributed.
We trained two versions of the model, each a different size, and named them after Russia’s great abstractionists: Vasily Kandinsky and Kazimir Malevich.
Some of our models are already freely available:
The models ruDALL-E Malevich (XL), ruDALL-E Kandinsky (XXL), ruCLIP Small, ruCLIP Large, and Super Resolution (Real ESRGAN) will also soon be available on DataHub.
Training the ruDALL-E neural networks on the Christofari cluster has become the largest calculation task in Russia:
Accordingly, training for both models totalled 24,256 GPU-days.
The long term goal of this research is the creation of multimodal neural networks. They will be able to pull on concepts from a variety of mediums---from text and visuals at first---in order to better understand the world as a whole.
Image generation might seem like the wrong rabbit hole in our century of big data and search engines. But it actually addresses two important requirements that search is currently unable to cope with:
"Grand Canyon"

"Salvador Dali picture"

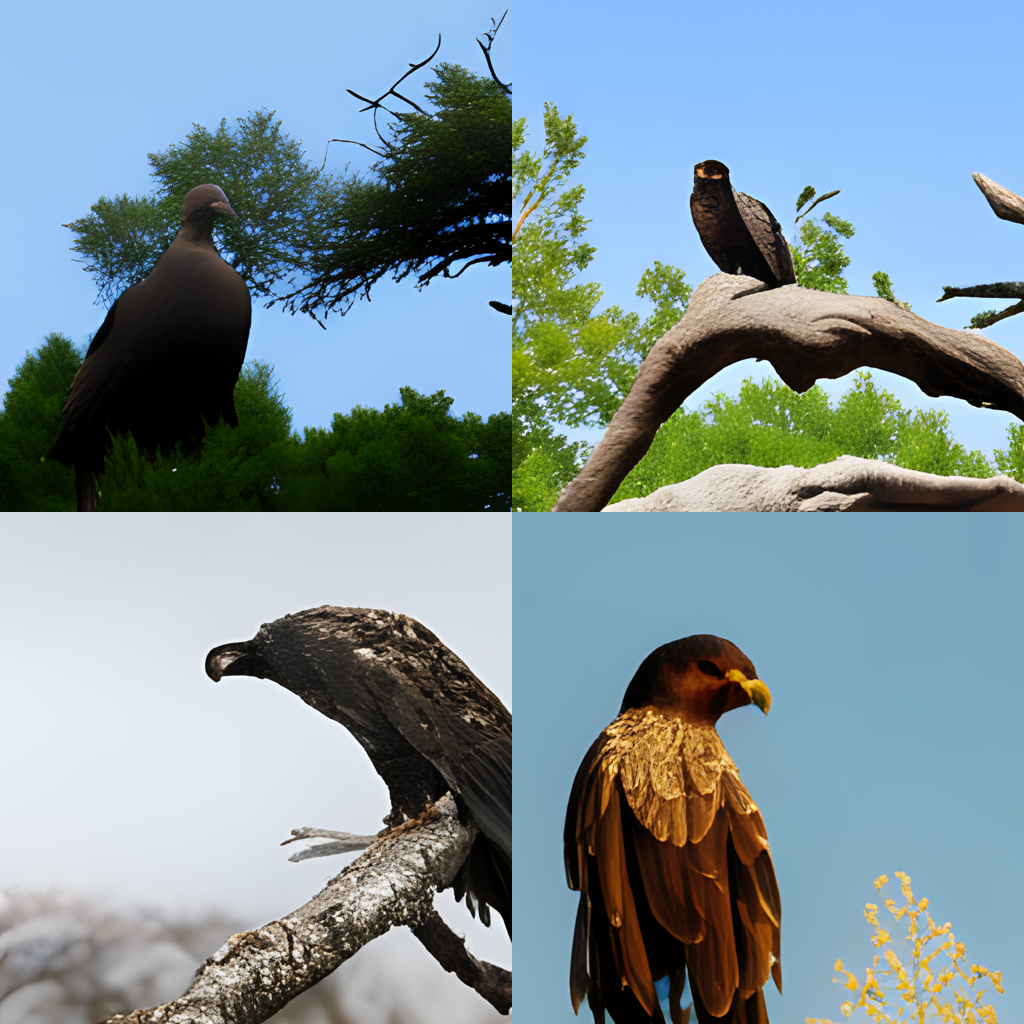
"An eagle sits in a tree, looking to the side"
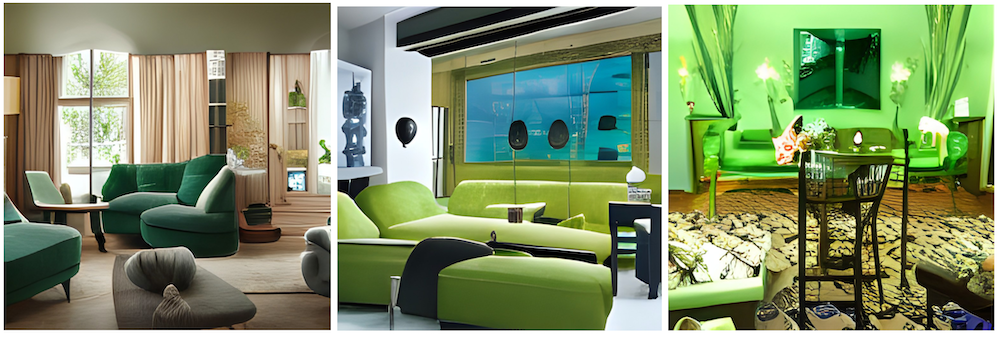
"Elegant living room with green stuffed chairs"
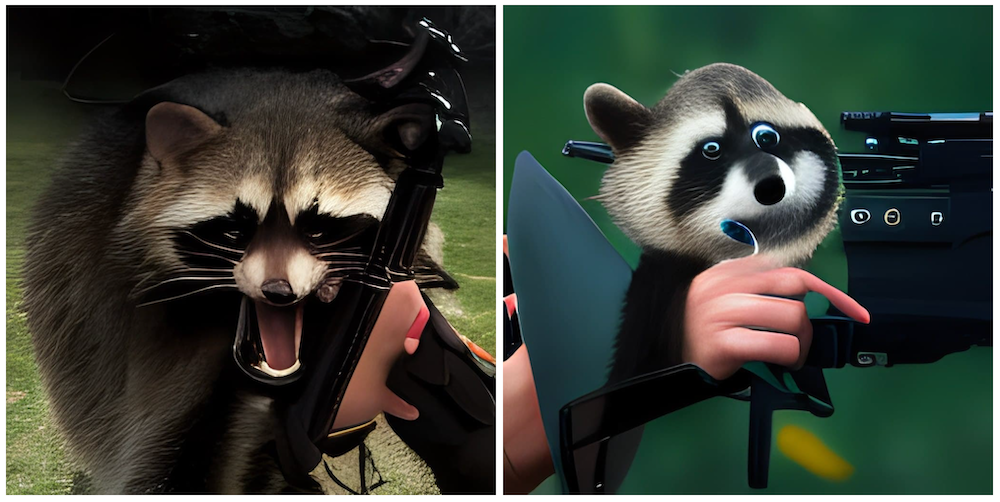
“Raccoon with a gun”
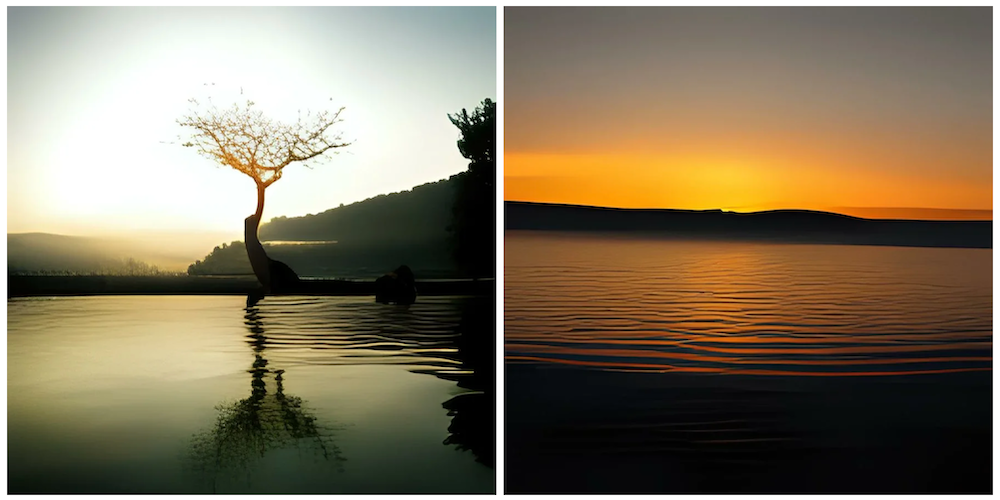
“Pretty lake at sunset”
"Avocado painting in the style of Malevich"
Model was trained by Sber AI and SberDevices teams.
text2image generationencoder-decoder1.3 B120 million text-image pairsThis is a 1.3 billion parameter model for Russian, recreating OpenAI's DALL·E, a model capable of generating arbitrary images from a text prompt that describes the desired result.
The generation pipeline includes ruDALL-E, ruCLIP for ranging results, and a superresolution model. You can use automatic translation into Russian to create desired images with ruDALL-E.
The easiest way to get familiar with the code and the models is to follow the inference notebook we provide in our github repo.
One might say that “investigate, master, and train” is our engineering motto. Well, we caught the scent, and today we can say that we created from scratch a complete pipeline for generating images from descriptive textual input written in Russian.
Teams at SberAI, SberDevices, Samara University, AIRI and SberCloud all actively contributed.
We trained two versions of the model, each a different size, and named them after Russia’s great abstractionists: Vasily Kandinsky and Kazimir Malevich.
Some of our models are already freely available:
The models ruDALL-E Malevich (XL), ruDALL-E Kandinsky (XXL), ruCLIP Small, ruCLIP Large, and Super Resolution (Real ESRGAN) will also soon be available on DataHub.
Training the ruDALL-E neural networks on the Christofari cluster has become the largest calculation task in Russia:
Accordingly, training for both models totalled 24,256 GPU-days.
The long term goal of this research is the creation of multimodal neural networks. They will be able to pull on concepts from a variety of mediums---from text and visuals at first---in order to better understand the world as a whole.
Image generation might seem like the wrong rabbit hole in our century of big data and search engines. But it actually addresses two important requirements that search is currently unable to cope with:
"Grand Canyon"
"Salvador Dali picture"
"An eagle sits in a tree, looking to the side"
"Elegant living room with green stuffed chairs"
“Raccoon with a gun”
“Pretty lake at sunset”