README
ScholarBERT-XL_100 Model
This is the ScholarBERT-XL_100 variant of the ScholarBERT model family.
The model is pretrained on a large collection of scientific research articles (221B tokens).
This is a cased (case-sensitive) model. The tokenizer will not convert all inputs to lower-case by default.
The model has a total of 770M parameters.
Model Architecture
| Hyperparameter | Value |
|---|---|
| Layers | 36 |
| Hidden Size | 1280 |
| Attention Heads | 20 |
| Total Parameters | 770M |
Training Dataset
The vocab and the model are pertrained on 100% of the PRD scientific literature dataset.
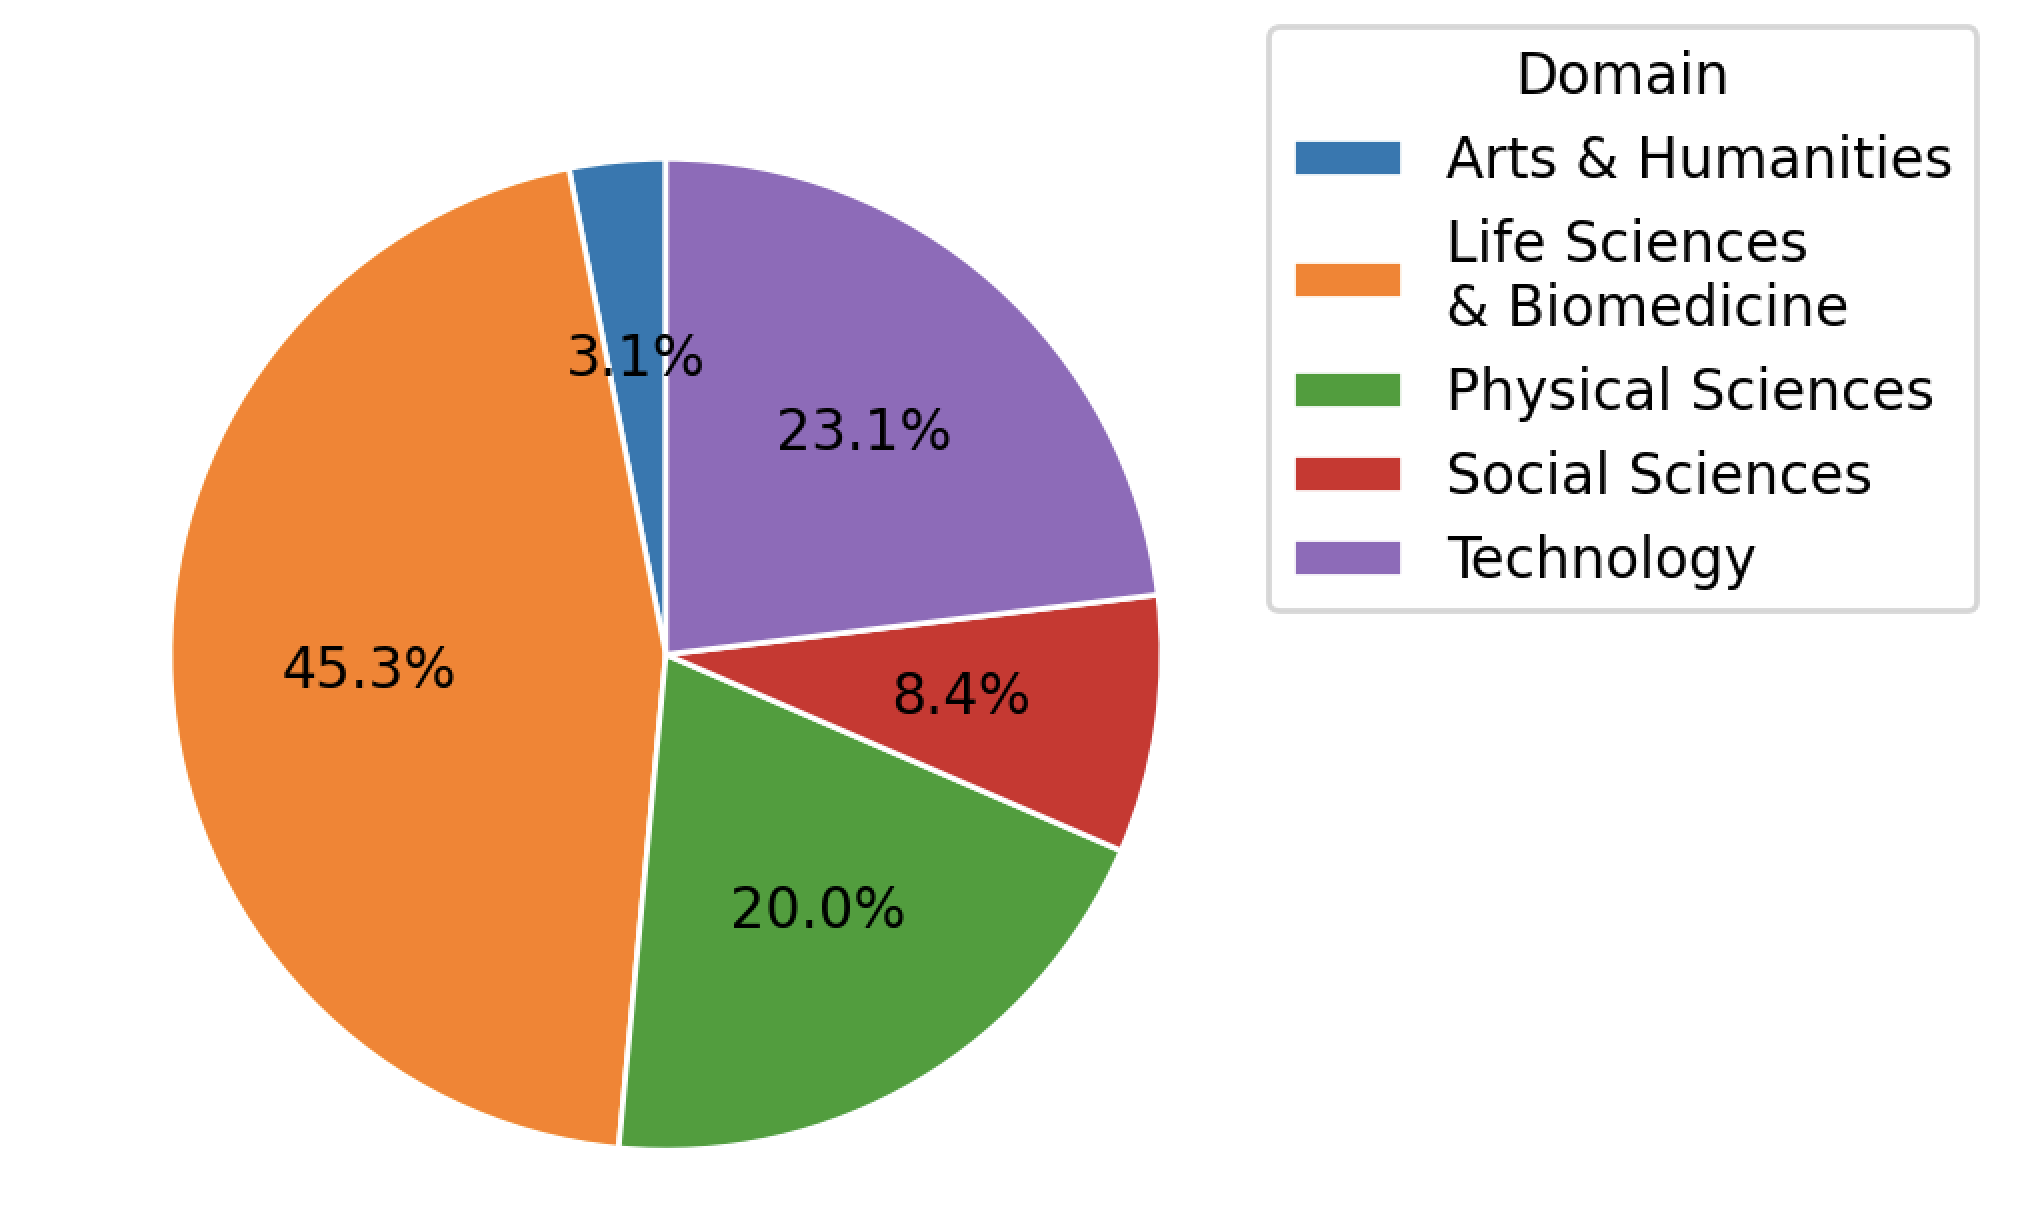
The PRD dataset is provided by Public.Resource.Org, Inc. (“Public Resource”), a nonprofit organization based in California. This dataset was constructed from a corpus of journal article files, from which We successfully extracted text from 75,496,055 articles from 178,928 journals. The articles span across Arts & Humanities, Life Sciences & Biomedicine, Physical Sciences, Social Sciences, and Technology. The distribution of articles is shown below.
BibTeX entry and citation info
If using this model, please cite this paper:
@inproceedings{hong2023diminishing,
  title={The diminishing returns of masked language models to science},
  author={Hong, Zhi and Ajith, Aswathy and Pauloski, James and Duede, Eamon and Chard, Kyle and Foster, Ian},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2023},
  pages={1270--1283},
  year={2023}
}
Contributors
8 commits
1 commits
Similar repos



README
ScholarBERT-XL_100 Model
This is the ScholarBERT-XL_100 variant of the ScholarBERT model family.
The model is pretrained on a large collection of scientific research articles (221B tokens).
This is a cased (case-sensitive) model. The tokenizer will not convert all inputs to lower-case by default.
The model has a total of 770M parameters.
Model Architecture
| Hyperparameter | Value |
|---|---|
| Layers | 36 |
| Hidden Size | 1280 |
| Attention Heads | 20 |
| Total Parameters | 770M |
Training Dataset
The vocab and the model are pertrained on 100% of the PRD scientific literature dataset.
The PRD dataset is provided by Public.Resource.Org, Inc. (“Public Resource”), a nonprofit organization based in California. This dataset was constructed from a corpus of journal article files, from which We successfully extracted text from 75,496,055 articles from 178,928 journals. The articles span across Arts & Humanities, Life Sciences & Biomedicine, Physical Sciences, Social Sciences, and Technology. The distribution of articles is shown below.
BibTeX entry and citation info
If using this model, please cite this paper:
@inproceedings{hong2023diminishing,
  title={The diminishing returns of masked language models to science},
  author={Hong, Zhi and Ajith, Aswathy and Pauloski, James and Duede, Eamon and Chard, Kyle and Foster, Ian},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2023},
  pages={1270--1283},
  year={2023}
}
Similar repos
Contributors
8 commits
1 commits