README
Puffin-World: Scaling a Unified Multimodal Model with Native 3D World States
📖 Project Page | 📄 Paper | 💻 GitHub | 🤗 Models | 🗂️ Dataset | 🤗 HF Blog
Overview
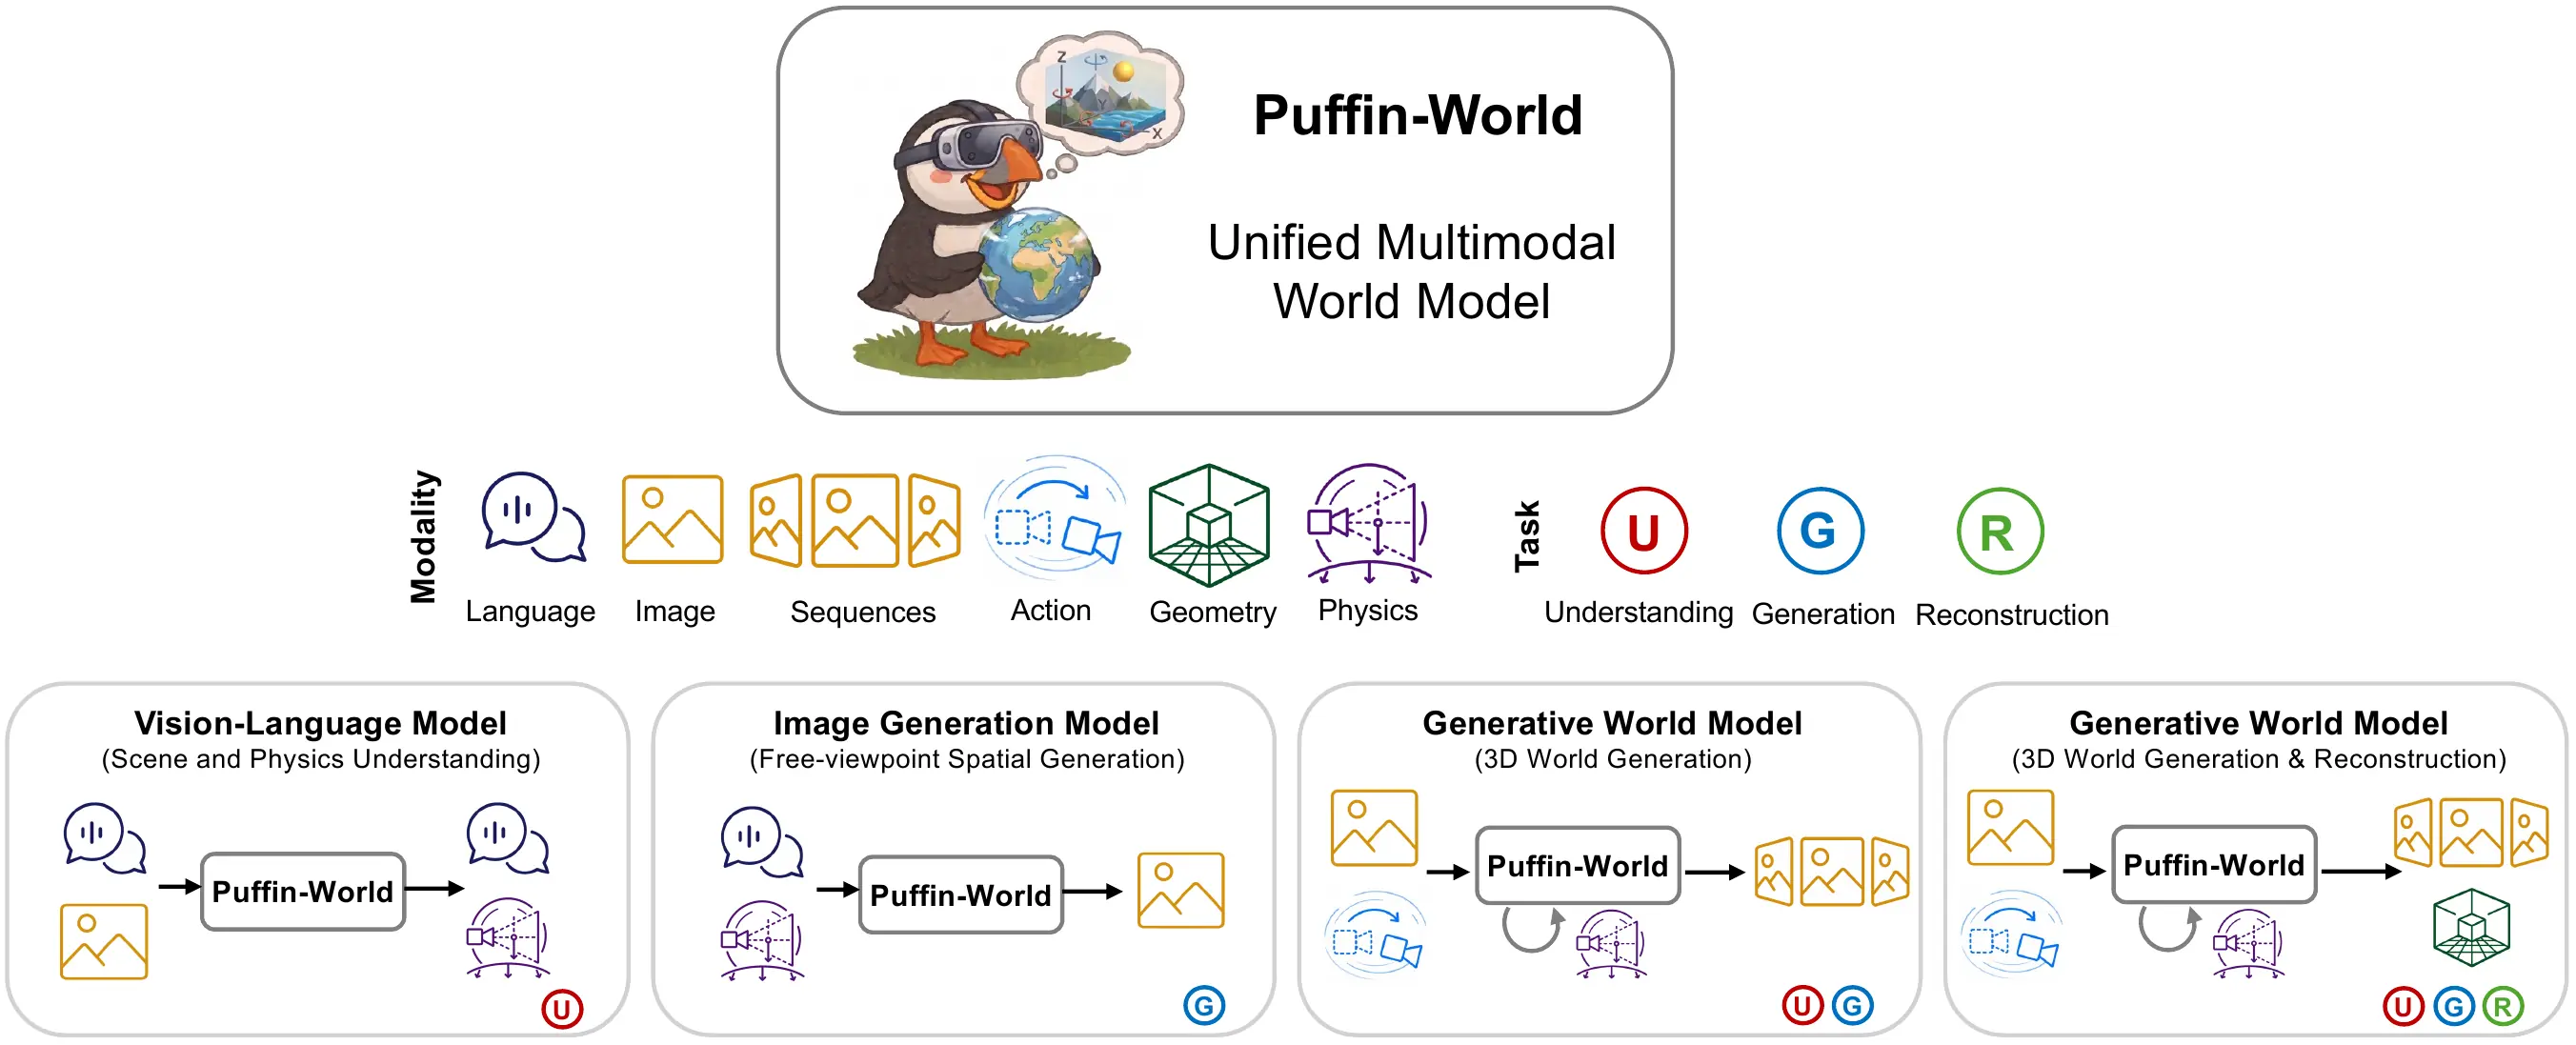
Puffin-World is a unified multimodal world model that perceives, simulates, generates, and reconstructs the 3D world within one framework. Instead of representing a world only as a sequence of RGB frames, it explicitly models three complementary native 3D world states:
- Physics: gravity fields and latitude maps that anchor observations and generated trajectories to the real world.
- Geometry: dense depth that exposes the underlying 3D structure and supports direct reconstruction.
- Appearance: high-fidelity images and sequences that remain spatially coherent as the camera moves.
A single integrated framework of a geometry-aligned vision encoder, an LLM, a diffusion model, and a lightweight connector supports physical-world perception, free-viewpoint spatial simulation, 3D world modeling, and closed-loop interaction without task-specific external perception or reconstruction modules.
At its core is camera-centric multi-view world modeling: given one initial view and a camera trajectory, Puffin-World jointly generates the remaining RGB and depth views and consolidates them into a gauge-aligned 3D point-cloud reconstruction.
Highlights
- Native 3D world states: physics, geometry, and appearance are modeled together rather than leaving physical orientation and scene structure implicit.
- Omni-Camera: a 9-channel dense camera condition combines a gravity-aware absolute perspective field with ray-based relative geometry, supporting camera-to-world grounding, rotation, translation, and compound motion.
- Physics propagation: the gravity direction perceived from the reference view is propagated through the target camera trajectory to keep generated views in one coherent physical frame.
- Unified understanding and generation: autoregressive camera understanding and diffusion-based generation share the same multimodal framework.
- Scaled world modeling: Puffin-World is trained with Puffin-16M, comprising 15M vision-language-camera triplets and 1M diverse camera trajectories curated from 28 public datasets.
Results at a Glance
| Capability | Result |
|---|---|
| Camera-to-world understanding | Best median errors in 12/12 comparisons and best AUC in 33/36 metrics, including ties, across Stanford2D3D, MegaDepth, TartanAir, and LaMAR |
| Camera-controllable generation | 0.84° up-vector, 1.26° latitude, and 0.79° gravity median errors, with the lowest FID on Puffin-Cam-Bench |
| 3D world modeling | PSNR (17.22) and LPIPS (0.318) on RealEstate10K |
| Challenging trajectories | Lowest median roll and pitch errors on Puffin-Traj-Bench: 0.80° and 1.10° |
See the project page and supplementary results for complete quantitative and qualitative evaluations.
Model Details
| Field | Description |
|---|---|
| Developed by | Kang Liao, Yihang Luo, Xiao-Ming Wu, Linyi Jin, Size Wu, Chunyu Lin, Yao Zhao, Fei Wang, Wei Li, Chen Change Loy |
| Affiliations | S-Lab, Nanyang Technological University; University of Michigan; Beijing Jiaotong University; ACE Robotics |
| First released | Preprint, 2026 |
| Model type | Unified multimodal world model with autoregressive understanding and diffusion-based multi-view RGB-D generation |
| Modalities | Image → Text + Camera; Text + Camera → Image; Image + Trajectory → Multi-view RGB-D + 3D point cloud |
Model Zoo
| Checkpoint | LLM | Vision Encoder | Diffusion | Purpose |
|---|---|---|---|---|
Puffin-World-Base.pth | Qwen2.5-7B | C-RADIOv3-H | SD3.5-medium | Comprehensive understanding and RGB-D world modeling |
Puffin-World-Pro.pth | Qwen2.5-1.5B | C-RADIOv4-H | SD3.5-large | High-quality generation and RGB-D world modeling |
Puffin-World-Caption.pth | Qwen3.5-0.8B | C-RADIOv3-H | — | Understanding-only physical captioning expert model |
Intended Use
- Camera-to-world understanding from a single image, including roll, pitch, vertical field-of-view.
- Camera-controllable text-to-image generation across explicit camera intrinsics and orientations.
- Image-conditioned or text-conditioned 3D world generation along long, extreme, or compound camera trajectories.
- Joint multi-view RGB-D generation and direct 3D point-cloud reconstruction.
- Closed-loop mimic world exploration and self-calibrated world exploration.
Installation
The reference implementation uses Python 3.10, PyTorch 2.7.0, and CUDA 12.6.
git clone https://github.com/KangLiao929/Puffin
cd Puffin/Puffin-World

conda create -n puffin-world python=3.10 -y
conda activate puffin-world

pip install torch==2.7.0 torchvision==0.22.0 torchaudio==2.7.0 \
  --index-url https://download.pytorch.org/whl/cu126
pip install -r requirements.txt
pip install flash-attn==2.8.3 --no-build-isolation
Sanity check:
export PYTHONPATH=./:$PYTHONPATH
python -c "import torch, transformers, deepspeed, xtuner, flash_attn, trimesh; print('ok')"
Download all released checkpoints:
pip install -U huggingface_hub
hf download KangLiao/Puffin-World --local-dir checkpoints
Quick Start
Multi-view world modeling from an initial view and camera trajectory:
export PYTHONPATH=./:$PYTHONPATH
python scripts/demo/world_modeling.py \
  --model Puffin-World \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --dataset re10k \
  --sample_index 0 \
  --output output/demo_world
Physical-world perception from a single image:
python scripts/demo/physics_perception.py demo.jpg \
  --model Puffin-World-Pro \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --output output/demo_camera
Camera-controlled spatial simulation:
python scripts/demo/spatial_simulation.py \
  "A cozy living room with wooden furniture and warm sunlight." \
  --model Puffin-World-Pro \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --camera "0.05, -0.12, 1.2" \
  --num 4 \
  --vis_pf
Micmic world exploration and self-calibration:
python scripts/demo/freeview_world_exp.py \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --input <image> \
  --scene_dir <re10k-style-scene-dir> \
  --chunk 3

python scripts/demo/self_calibration.py <image> \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --output output/demo_self_calib
Detailed instructions:
- Training
- World-model evaluation and reconstruction
- Camera-centric understanding and generation evaluation
- Dataset construction and annotation
Limitations
Puffin-World currently focuses on static scenes and models physics primarily through gravity and latitude. Dynamic environments, longer temporal horizons, richer object interactions, and broader physical states remain important directions for future work. Generated content may also inherit biases or failure modes from its training data and underlying pretrained components.
Citation
If the Puffin series supports your research, please consider citing our work:
@article{liao2026puffinworld,
  title   = {Puffin-World: Scaling a Unified Multimodal Model with Native 3D World States},
  author  = {Liao, Kang and Luo, Yihang and Wu, Xiao-Ming and Jin, Linyi and Wu, Size and Lin, Chunyu and Zhao, Yao and Wang, Fei and Li, Wei and Loy, Chen Change},
  journal = {arXiv preprint arXiv:2609.04196},
  year    = {2026}
}

@article{liao2025puffin,
  title   = {Thinking with Camera: A Unified Multimodal Model for Camera-Centric Understanding and Generation},
  author  = {Liao, Kang and Wu, Size and Wu, Zhonghua and Jin, Linyi and Wang, Chao and Wang, Yikai and Wang, Fei and Li, Wei and Loy, Chen Change},
  journal = {arXiv preprint arXiv:2510.08673},
  year    = {2025}
}
License
This project is released under the NTU S-Lab License 1.0.
Contributors
11 commits
Similar repos



README
Puffin-World: Scaling a Unified Multimodal Model with Native 3D World States
📖 Project Page | 📄 Paper | 💻 GitHub | 🤗 Models | 🗂️ Dataset | 🤗 HF Blog
Overview
Puffin-World is a unified multimodal world model that perceives, simulates, generates, and reconstructs the 3D world within one framework. Instead of representing a world only as a sequence of RGB frames, it explicitly models three complementary native 3D world states:
- Physics: gravity fields and latitude maps that anchor observations and generated trajectories to the real world.
- Geometry: dense depth that exposes the underlying 3D structure and supports direct reconstruction.
- Appearance: high-fidelity images and sequences that remain spatially coherent as the camera moves.
A single integrated framework of a geometry-aligned vision encoder, an LLM, a diffusion model, and a lightweight connector supports physical-world perception, free-viewpoint spatial simulation, 3D world modeling, and closed-loop interaction without task-specific external perception or reconstruction modules.
At its core is camera-centric multi-view world modeling: given one initial view and a camera trajectory, Puffin-World jointly generates the remaining RGB and depth views and consolidates them into a gauge-aligned 3D point-cloud reconstruction.
Highlights
- Native 3D world states: physics, geometry, and appearance are modeled together rather than leaving physical orientation and scene structure implicit.
- Omni-Camera: a 9-channel dense camera condition combines a gravity-aware absolute perspective field with ray-based relative geometry, supporting camera-to-world grounding, rotation, translation, and compound motion.
- Physics propagation: the gravity direction perceived from the reference view is propagated through the target camera trajectory to keep generated views in one coherent physical frame.
- Unified understanding and generation: autoregressive camera understanding and diffusion-based generation share the same multimodal framework.
- Scaled world modeling: Puffin-World is trained with Puffin-16M, comprising 15M vision-language-camera triplets and 1M diverse camera trajectories curated from 28 public datasets.
Results at a Glance
| Capability | Result |
|---|---|
| Camera-to-world understanding | Best median errors in 12/12 comparisons and best AUC in 33/36 metrics, including ties, across Stanford2D3D, MegaDepth, TartanAir, and LaMAR |
| Camera-controllable generation | 0.84° up-vector, 1.26° latitude, and 0.79° gravity median errors, with the lowest FID on Puffin-Cam-Bench |
| 3D world modeling | PSNR (17.22) and LPIPS (0.318) on RealEstate10K |
| Challenging trajectories | Lowest median roll and pitch errors on Puffin-Traj-Bench: 0.80° and 1.10° |
See the project page and supplementary results for complete quantitative and qualitative evaluations.
Model Details
| Field | Description |
|---|---|
| Developed by | Kang Liao, Yihang Luo, Xiao-Ming Wu, Linyi Jin, Size Wu, Chunyu Lin, Yao Zhao, Fei Wang, Wei Li, Chen Change Loy |
| Affiliations | S-Lab, Nanyang Technological University; University of Michigan; Beijing Jiaotong University; ACE Robotics |
| First released | Preprint, 2026 |
| Model type | Unified multimodal world model with autoregressive understanding and diffusion-based multi-view RGB-D generation |
| Modalities | Image → Text + Camera; Text + Camera → Image; Image + Trajectory → Multi-view RGB-D + 3D point cloud |
Model Zoo
| Checkpoint | LLM | Vision Encoder | Diffusion | Purpose |
|---|---|---|---|---|
Puffin-World-Base.pth | Qwen2.5-7B | C-RADIOv3-H | SD3.5-medium | Comprehensive understanding and RGB-D world modeling |
Puffin-World-Pro.pth | Qwen2.5-1.5B | C-RADIOv4-H | SD3.5-large | High-quality generation and RGB-D world modeling |
Puffin-World-Caption.pth | Qwen3.5-0.8B | C-RADIOv3-H | — | Understanding-only physical captioning expert model |
Intended Use
- Camera-to-world understanding from a single image, including roll, pitch, vertical field-of-view.
- Camera-controllable text-to-image generation across explicit camera intrinsics and orientations.
- Image-conditioned or text-conditioned 3D world generation along long, extreme, or compound camera trajectories.
- Joint multi-view RGB-D generation and direct 3D point-cloud reconstruction.
- Closed-loop mimic world exploration and self-calibrated world exploration.
Installation
The reference implementation uses Python 3.10, PyTorch 2.7.0, and CUDA 12.6.
git clone https://github.com/KangLiao929/Puffin
cd Puffin/Puffin-World

conda create -n puffin-world python=3.10 -y
conda activate puffin-world

pip install torch==2.7.0 torchvision==0.22.0 torchaudio==2.7.0 \
  --index-url https://download.pytorch.org/whl/cu126
pip install -r requirements.txt
pip install flash-attn==2.8.3 --no-build-isolation
Sanity check:
export PYTHONPATH=./:$PYTHONPATH
python -c "import torch, transformers, deepspeed, xtuner, flash_attn, trimesh; print('ok')"
Download all released checkpoints:
pip install -U huggingface_hub
hf download KangLiao/Puffin-World --local-dir checkpoints
Quick Start
Multi-view world modeling from an initial view and camera trajectory:
export PYTHONPATH=./:$PYTHONPATH
python scripts/demo/world_modeling.py \
  --model Puffin-World \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --dataset re10k \
  --sample_index 0 \
  --output output/demo_world
Physical-world perception from a single image:
python scripts/demo/physics_perception.py demo.jpg \
  --model Puffin-World-Pro \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --output output/demo_camera
Camera-controlled spatial simulation:
python scripts/demo/spatial_simulation.py \
  "A cozy living room with wooden furniture and warm sunlight." \
  --model Puffin-World-Pro \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --camera "0.05, -0.12, 1.2" \
  --num 4 \
  --vis_pf
Micmic world exploration and self-calibration:
python scripts/demo/freeview_world_exp.py \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --input <image> \
  --scene_dir <re10k-style-scene-dir> \
  --chunk 3

python scripts/demo/self_calibration.py <image> \
  --checkpoint checkpoints/Puffin-World-Pro.pth \
  --output output/demo_self_calib
Detailed instructions:
- Training
- World-model evaluation and reconstruction
- Camera-centric understanding and generation evaluation
- Dataset construction and annotation
Limitations
Puffin-World currently focuses on static scenes and models physics primarily through gravity and latitude. Dynamic environments, longer temporal horizons, richer object interactions, and broader physical states remain important directions for future work. Generated content may also inherit biases or failure modes from its training data and underlying pretrained components.
Citation
If the Puffin series supports your research, please consider citing our work:
@article{liao2026puffinworld,
  title   = {Puffin-World: Scaling a Unified Multimodal Model with Native 3D World States},
  author  = {Liao, Kang and Luo, Yihang and Wu, Xiao-Ming and Jin, Linyi and Wu, Size and Lin, Chunyu and Zhao, Yao and Wang, Fei and Li, Wei and Loy, Chen Change},
  journal = {arXiv preprint arXiv:2609.04196},
  year    = {2026}
}

@article{liao2025puffin,
  title   = {Thinking with Camera: A Unified Multimodal Model for Camera-Centric Understanding and Generation},
  author  = {Liao, Kang and Wu, Size and Wu, Zhonghua and Jin, Linyi and Wang, Chao and Wang, Yikai and Wang, Fei and Li, Wei and Loy, Chen Change},
  journal = {arXiv preprint arXiv:2510.08673},
  year    = {2025}
}
License
This project is released under the NTU S-Lab License 1.0.
Similar repos
Linked in READMEs
Contributors
11 commits