README
Index-Echo-S2ST-2B
Online demo · GitHub · Technical report · Hugging Face collection · ModelScope collection
Index-Echo-S2ST-2B translates a Chinese or English speech clip into another language and generates speech conditioned on the source speaker's voice. It combines a frozen Index-Echo-S2TT-2B backbone, a learned Hidden2CV mapper, and CosyVoice3 speech generation in one self-contained package and Python process.
The release supports six directions: Chinese → English/Spanish/Japanese and English → Chinese/Spanish/Japanese. The caller specifies the target language; the package infers the source language from its source transcript. The 9B sibling exposes the same interface. 2B denotes the speech translator's decoder size, rather than the total size of all packaged components.
Architecture
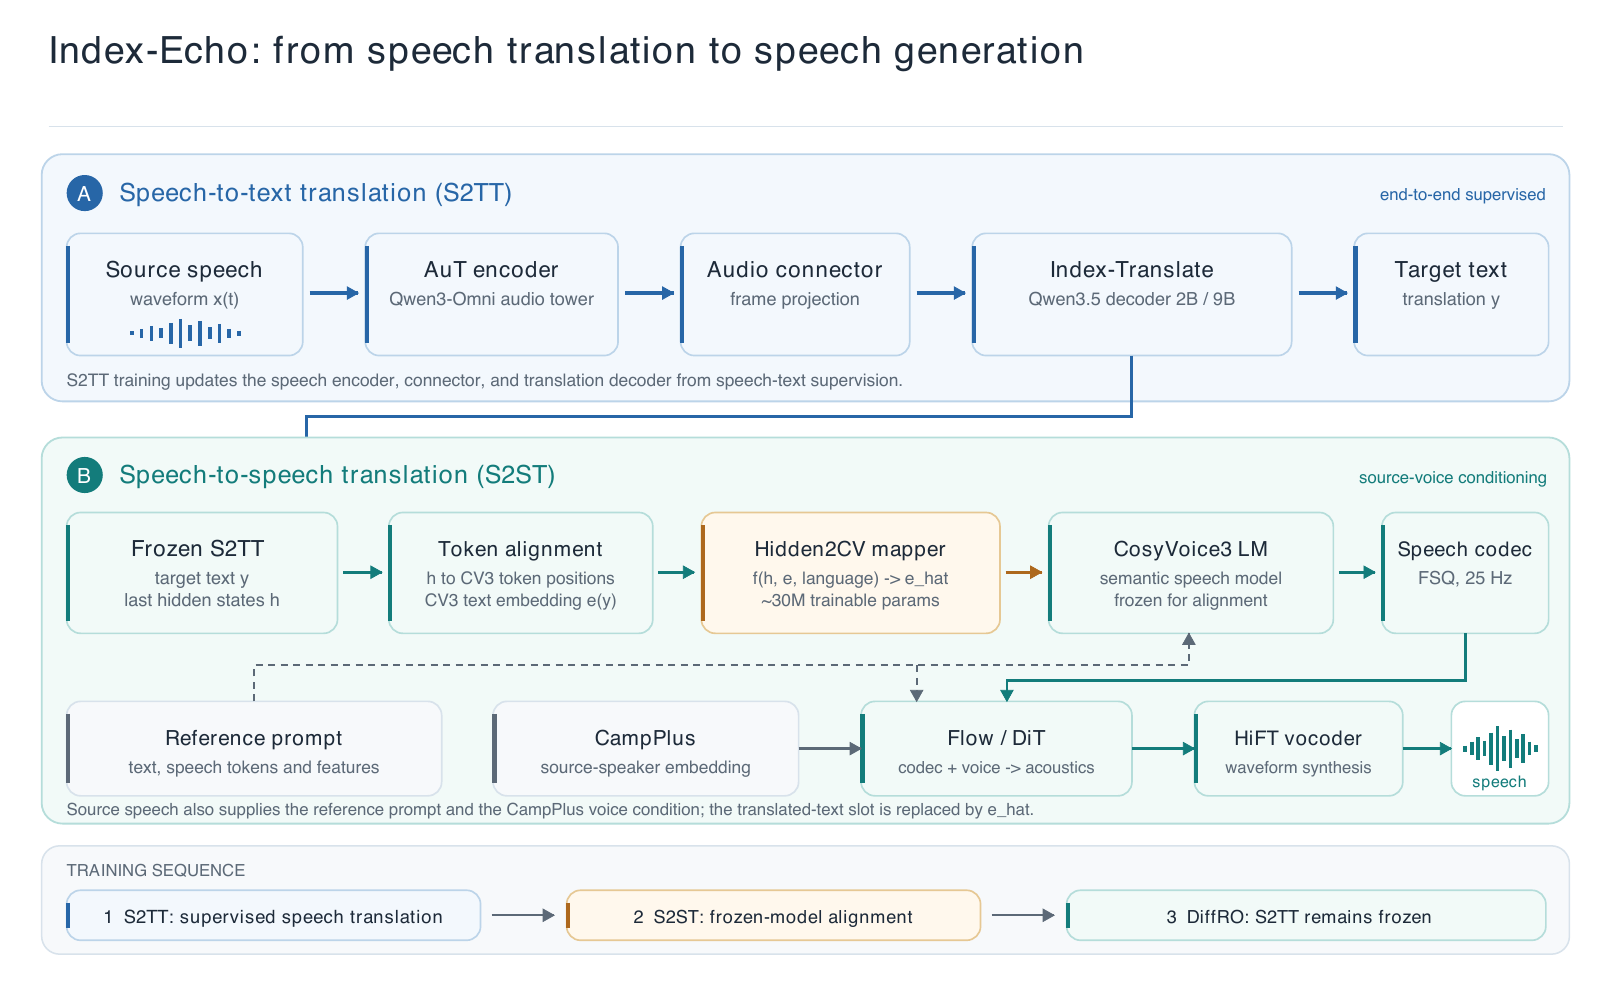
The report's lower path extends S2TT to S2ST: the frozen speech translator supplies its final hidden states to Hidden2CV, which connects to CosyVoice3 speech generation. Source audio supplies the reference prompt and CampPlus speaker embedding for voice conditioning. The diagram also shows mapper alignment and DiffRO training; the S2TT backbone remains frozen throughout S2ST training.
Model and training
The technical report initializes S2ST from the trained Index-Echo S2TT model, whose Qwen3-Omni AuT audio encoder and connector feed an Index-Translate decoder. The speech-generation path uses a roughly 30M-parameter Hidden2CV mapper to connect the translator's final hidden states to the CosyVoice3 semantic layer.
Training first distills the mapper with both the S2TT backbone and speech generator frozen, then applies differentiable reward optimization (DiffRO). A Token2Text content-consistency reward is backpropagated through Gumbel-Softmax speech-token samples. The S2TT backbone remains frozen throughout S2ST training. At inference, source audio supplies the reference prompt and CampPlus speaker embedding for voice conditioning. Voice similarity varies with the source, target language, and synthesis result.
Inference
Download the complete model package before importing its local modeling_dubbing.py:
pip install -U huggingface_hub
hf download IndexTeam/Index-Echo-S2ST-2B --local-dir ./Index-Echo-S2ST-2B
cd Index-Echo-S2ST-2B
Pinned environment
The release documents the following tested dependency pins. Use CUDA-compatible PyTorch wheels; the +cu129 builds require a wheel source that provides that CUDA build. System ffmpeg must be on PATH.
pip install torch==2.11.0+cu129 torchaudio==2.11.0+cu129 transformers==5.6.0 \
    tokenizers==0.22.2 librosa==1.0.0 onnxruntime==1.30.0 wetext==0.0.4 \
    kaldifst==1.8.0 conformer==0.3.2 hydra-core==1.3.7 HyperPyYAML==1.2.3 \
    lightning==2.6.6 x-transformers==2.11.24 einx==0.4.3 frozendict==2.4.7 \
    pyworld==0.3.5 soundfile==0.13.1 modelscope==1.37.1 safetensors==0.7.0 \
    numpy==2.4.6 openai-whisper==20250625
openai-whisper is used only for the package's ASR-based evaluation/self-check. The Japanese frontend (pyopenjtalk==0.4.1, including its dictionary, and pykakasi==2.3.0) is vendored under code/ja_ext/; the pipeline adds it to the import path automatically. All components run in one Python environment and process.
The package automatically applies two CosyVoice3 compatibility patches for Transformers 5.6 in code/tts/pipeline.py: keeping the CosyVoice3 LLM in fp32, and providing the full visible attention mask during autoregressive decoding. Keep the bundled code and dependency pins together.
Python API
Run this from the downloaded package directory, with input clips available at the indicated paths:
from modeling_dubbing import DubbingBridgeModel

model = DubbingBridgeModel.from_pretrained('.', device='cuda')

# Chinese source: three supported targets.
wav, sr = model.dub('input_zh.wav', lang='en', out_wav='dub_en.wav')
model.dub('input_zh.wav', lang='es', out_wav='dub_es.wav')
model.dub('input_zh.wav', lang='ja', out_wav='dub_ja.wav')

# English source: three supported targets.
model.dub('input_en.wav', lang='zh', out_wav='dub_zh.wav')
model.dub('input_en.wav', lang='es', out_wav='dub_es2.wav')
model.dub('input_en.wav', lang='ja', out_wav='dub_ja2.wav')

wav, sr, info = model.dub('input_en.wav', lang='zh', return_info=True)
print(sr)               # 24000 Hz
print(info['zh'])       # Source transcript; the key name is retained for both sources.
print(info['tgt_raw'])  # Model translation, before the speech frontend's normalization.
print(info['tgt_cv'])   # Speech-frontend text; Japanese uses a katakana representation.
print(info['src_lang']) # 'zh' or 'en'
lang always means the target language: en, es, ja, or zh. The source-language heuristic treats a source transcript containing CJK characters as Chinese and otherwise as English; it is not a general language identifier. Source and target must differ. The waveform is a float32 tensor of shape (1, T) at 24 kHz. out_wav saves it to a file. With return_info=True, the third return value includes the transcript, translation, source language, and synthesis diagnostics.
At the lower pipeline layer, extract(audio_path, lang) returns the translated text and aligned hidden states separately from synthesis. See the S2ST inference guide for the dub.py wrapper, and the video pipeline for segmentation and video timeline alignment.
Default inference settings
| Stage or setting | Released default |
|---|---|
| Transcription and translation | Greedy, temperature=0.0 / do_sample=False |
| Transcription/translation budget | max_new_tokens=1024 |
| Speech mode | h2cv (the only supported mode in this package) |
| Speech-token budget | max_tokens=1500; actual cap min(20 * m, 1500), where m is aligned target-text token count |
| Minimum speech length | 2 * m tokens before stop tokens are allowed |
| Speech sampling | sampling=25; release notes describe ras_sampling, top-k 25 / top-p 0.8 |
| Speech-generation seed | 42 |
| Synthesis speed | 1.0 |
| Output sample rate | 24000 Hz |
| CosyVoice3 execution | stream=False, load_trt=False, load_vllm=False, fp16=False; LLM kept in fp32 |
| Chunked orchestration | Disabled (chunk=False) |
Both sizes use these settings. Greedy transcription/translation does not make speech synthesis greedy. The public DubbingBridgeModel.dub wrapper does not expose a seed argument; seed changes are available through the lower-level pipeline's dub/synth APIs. Sampling may vary between calls even with the default seed, as documented in the release notes.
Configurable API parameters
The public wrapper and lower pipeline expose different controls. The defaults below are shared by both sizes.
| Interface | Parameter | Default | Behavior |
|---|---|---|---|
from_pretrained | model_dir | Required | Local directory containing the full package |
from_pretrained | device | cuda | CUDA device for the loaded components |
from_pretrained | mode | None → config default h2cv | Sets the default speech mode |
Public dub | audio_path | Required | Chinese or English source clip |
Public dub | lang | en | Target language: en, es, ja, zh; must differ from detected source |
Public dub | out_wav | None | Save path; None creates a temporary WAV |
Public dub | mode | None → loaded default | Only h2cv is accepted |
Public dub | chunk | False | True is unsupported in this release |
Public dub | return_info | False | Adds transcript, translation, and synthesis diagnostics to the return value |
Pipeline extract | lang | en | Target language for transcription/translation and alignment |
Pipeline extract | max_new_tokens | 1024 | Transcription/translation output budget |
Pipeline synth | out_wav | None | Optional output save path |
Pipeline synth | max_tokens | 1500 | Upper bound on generated speech tokens |
Pipeline synth | seed | 42 | Seed set before speech-token generation and acoustic synthesis |
Pipeline synth | prompt_wav | None | Uses the source audio unless a reference clip is supplied |
Pipeline synth | prompt_text | None | Uses the source transcript unless reference text is supplied |
For explicit text/speech budgets or seed control, use the lower pipeline after loading model as above:
pipe = model._pipe
ext = pipe.extract('input_zh.wav', lang='en', max_new_tokens=1024)
wav, info = pipe.synth(ext, out_wav='dub_en.wav', max_tokens=1500, seed=42)
The lower pipeline's dub(..., **kw) forwards synthesis options such as seed and max_tokens; changing the translation budget requires calling extract separately. Sampling argument 25 and synthesis speed 1.0 are fixed in the released pipeline code, not keyword arguments of the public wrapper. Translation stops at tokenizer EOS or <|im_end|>; speech generation uses CosyVoice3's defined stop tokens and the length limits above. The script does not explicitly override other text-generation knobs such as top_p, top_k, or repetition penalties.
Evaluation
The report compares end-to-end dubbing with a matched Index-Echo-S2TT + CosyVoice3 pipeline on in-house video dubbing data. Each pair shares the same frozen S2TT model and text translation, so the comparison measures the speech-generation path under a shared translation. For 2B, end-to-end dubbing lowers mean content error in four of six directions: zh→es, zh→ja, en→zh, and en→es. Across both sizes it improves eight of twelve size–direction pairs; Chinese → English favors the pipeline.
| Direction | Translator size | Content metric | Text judge ↑ | Pipeline error ↓ mean / median | E2E error ↓ mean / median | Pipeline speaker ↑ | E2E speaker ↑ |
|---|---|---|---|---|---|---|---|
| zh→en | 2B | WER | 0.830 | 0.0450 / 0.000 | 0.0709 / 0.029 | 0.722 | 0.743 |
| zh→en | 9B | WER | 0.840 | 0.0477 / 0.000 | 0.0615 / 0.000 | 0.718 | 0.739 |
| zh→es | 2B | WER | 0.728 | 0.0811 / 0.070 | 0.0704 / 0.051 | 0.747 | 0.743 |
| zh→es | 9B | WER | 0.793 | 0.0916 / 0.071 | 0.0773 / 0.057 | 0.746 | 0.746 |
| zh→ja | 2B | Kata CER | 0.760 | 0.0575 / 0.034 | 0.0493 / 0.027 | 0.777 | 0.780 |
| zh→ja | 9B | Kata CER | 0.815 | 0.0552 / 0.029 | 0.0436 / 0.021 | 0.778 | 0.782 |
| en→zh | 2B | CER | 0.825 | 0.0614 / 0.000 | 0.0372 / 0.000 | 0.630 | 0.623 |
| en→zh | 9B | CER | 0.800 | 0.0463 / 0.000 | 0.0485 / 0.000 | 0.632 | 0.623 |
| en→es | 2B | WER | 0.805 | 0.0867 / 0.070 | 0.0702 / 0.000 | 0.732 | 0.735 |
| en→es | 9B | WER | 0.820 | 0.0819 / 0.000 | 0.0660 / 0.000 | 0.736 | 0.729 |
| en→ja | 2B | Kata CER | 0.790 | 0.0342 / 0.000 | 0.0345 / 0.000 | 0.707 | 0.698 |
| en→ja | 9B | Kata CER | 0.803 | 0.0347 / 0.000 | 0.0337 / 0.000 | 0.705 | 0.710 |
The table includes both Index-Echo sizes, with this card's 2B translator rows emphasized. Every pipeline uses the same translator size and text translation as its E2E counterpart. Bold content-error values mark the lower mean within each matched row. Content error compares synthesized speech with the intended translated text using WER for English and Spanish, normalized CER for Chinese, and katakana CER for Japanese. These are different metrics and test sets; do not compare their values directly across target languages. Text translation is judged by Gemini-3.1-Pro and is shared within each pair. Speaker similarity is cosine similarity against the source speaker, rather than a guarantee of perfect voice preservation.
Chinese-source tests contain 100 examples for English and 200 each for Spanish and Japanese. English-source tests start with 200 examples per target, with 146–198 retained after filtering in the reported evaluation. Speaker similarity differs by 0.021 for Chinese → English and by at most 0.01 elsewhere in the complete matched table. These results use the report's stated protocol and are separate from the website's deployed-system comparison or earlier Chinese-source evaluations. See the technical report for details.
Earlier Chinese-source S2ST evaluation (2B)
The report also records an external comparison for the 2B model on an earlier Chinese-source test set. Its data and protocol differ from the matched study above; the scores should be read within this comparison.
| Target | Index-Echo-2B S2ST MT judge ↑ | SeamlessM4T-v2 MT judge ↑ |
|---|---|---|
| English | 0.905 | 0.370 |
| Spanish | 0.823 | 0.343 |
| Japanese | 0.838 | 0.310 |
SeamlessM4T-v2 is an external speech-translation baseline; this comparison does not establish equal total parameter counts. The report does not provide 9B results for this earlier test. The current 2B/9B comparison is the matched six-direction table above.
Package details
| File or directory | Purpose |
|---|---|
config.json, modeling_dubbing.py | Component configuration and DubbingBridgeModel interface |
stlm_llm/ | Qwen3.5-family translator decoder and tokenizer |
stlm_ckpt/ | Trained audio encoder/connector checkpoint |
stlm_omni/ | Qwen3-Omni configuration and AuT source components |
cosyvoice3/ | CosyVoice3 LLM, flow, HiFT, and ONNX assets |
bridge/ | mapper.safetensors, mapper_config.json, and checkpoint archive |
wetext_en_tn/, wetext_repo/ | Offline text-normalization assets |
code/tts/, code/stlm/, code/bridge/ | Dubbing, speech translation, and mapper implementation |
code/ja_ext/, code/cosyvoice_repo/ | Vendored Japanese frontend and CosyVoice inference code |
_legacy/ | Original pre-conversion checkpoint archives, when present |
samples/, verify_export.py | Input clips, reference dubs, and export/self-check assets |
The loader prefers safetensors for the translator, mapper, and CosyVoice3 components, with original-format fallback. The export records version v4.0.0-fulldir-2b (2026-09-27), translator EXP-53-2B iter12613, and mapper rft_fd2b53_sw_lam20/mapper_best. Keep bundled assets together for offline loading. Use materialized copies (cp -rL or an appropriate rsync configuration) when copying training-side packages whose weight files are hard links.
Text normalization and alignment
| Direction | Translator text used for alignment | Speech-frontend text | Hidden-state alignment |
|---|---|---|---|
| zh→en | Normalized English | Same normalized text | Character-overlap mean pooling |
| zh→es | Normalized Spanish | Same normalized text | Character-overlap mean pooling |
| zh→ja | Original mixed-script Japanese | Katakana frontend representation | Word mapping to original text, then pooling |
| en→zh | Original translation | Wetext-normalized Chinese | Character-overlap mean pooling |
| en→es | Original translation | Normalized Spanish | Character-overlap mean pooling |
| en→ja | Original mixed-script Japanese | Katakana frontend representation | Word mapping to original text, then pooling |
The source transcript is the first nonempty line and the translation is the last nonempty line of translator output. The mapper's training language list is ['en', 'es', 'ja', 'zh', 'ja', 'es'], with first-occurrence indices en=0, es=1, ja=2, and zh=3; the duplicate trailing slots are unused. The loader asserts this mapping. Do not reorder it when modifying or converting the package.
Limitations
- Use one CUDA GPU with at least 12 GB VRAM. CPU inference is unverified; memory use depends on the runtime and input.
- The release is tuned for utterance-level dubbing. Keep individual utterances at or below approximately 30 seconds; use the full video pipeline for longer recordings.
chunk=TrueraisesNotImplementedErrorin this release. - The release notes report occasional failures on roughly 1–2% of tested short English-source inputs, including a CosyVoice convolution-kernel error or a one-token collapse producing approximately 0.04 seconds of audio. Check the generated audio and retry through the lower-level pipeline with a different seed, or discard the failed result.
- Translation errors propagate into speech. Inspect
tgt_rawandtgt_cvwhen fidelity is important. - Source-voice conditioning does not guarantee identical timbre, pronunciation, or delivery. The source-language heuristic can misclassify atypical or mixed-language transcripts.
- Reported reward-optimization gains for English-source synthesis are small and direction-dependent; quality still depends strongly on the underlying translator and speech generator.
Related models
| Family | Task | Released sizes |
|---|---|---|
| Index-Translate | Text translation and translation instructions across 150 languages | 2B, 9B, 35B-A3B (preview) |
| Index-Echo S2TT | Speech-to-text translation and subtitles | 2B, 9B |
| Index-Echo S2ST | Speech-to-speech translation with source-voice conditioning | 2B, 9B |
| Index-Homura | Translation with a target syllable count | 2B, 9B |
| Index-NativeLong | Native long-document translation; released as Index-Nailong | 2B, 9B |
The text foundation's 150-language coverage does not describe the released speech interfaces. Use the task-specific directions documented above.
Citation
@techreport{indextranslate2026,
  author={Tianjiao Li and Mengran Yu and Chenyu Shi and Lusheng Zhang and
          Qisi Chen and Yanshan Zhou and Ji Qi and Jingying Liu and
          Yuang Feng and Ziang Cui and Tianxing Yan},
  title={Index-Translate: A Multilingual Translation Model Family --- Text, Speech, Controlled Dubbing, and Long-Document Translation},
  institution={Index LLM Team},
  year={2026},
  month={September}
}
License and feedback
Apache-2.0. Questions and feedback are welcome through GitHub Issues.
Similar repos

Linked in READMEs
README
Index-Echo-S2ST-2B
Online demo · GitHub · Technical report · Hugging Face collection · ModelScope collection
Index-Echo-S2ST-2B translates a Chinese or English speech clip into another language and generates speech conditioned on the source speaker's voice. It combines a frozen Index-Echo-S2TT-2B backbone, a learned Hidden2CV mapper, and CosyVoice3 speech generation in one self-contained package and Python process.
The release supports six directions: Chinese → English/Spanish/Japanese and English → Chinese/Spanish/Japanese. The caller specifies the target language; the package infers the source language from its source transcript. The 9B sibling exposes the same interface. 2B denotes the speech translator's decoder size, rather than the total size of all packaged components.
Architecture
The report's lower path extends S2TT to S2ST: the frozen speech translator supplies its final hidden states to Hidden2CV, which connects to CosyVoice3 speech generation. Source audio supplies the reference prompt and CampPlus speaker embedding for voice conditioning. The diagram also shows mapper alignment and DiffRO training; the S2TT backbone remains frozen throughout S2ST training.
Model and training
The technical report initializes S2ST from the trained Index-Echo S2TT model, whose Qwen3-Omni AuT audio encoder and connector feed an Index-Translate decoder. The speech-generation path uses a roughly 30M-parameter Hidden2CV mapper to connect the translator's final hidden states to the CosyVoice3 semantic layer.
Training first distills the mapper with both the S2TT backbone and speech generator frozen, then applies differentiable reward optimization (DiffRO). A Token2Text content-consistency reward is backpropagated through Gumbel-Softmax speech-token samples. The S2TT backbone remains frozen throughout S2ST training. At inference, source audio supplies the reference prompt and CampPlus speaker embedding for voice conditioning. Voice similarity varies with the source, target language, and synthesis result.
Inference
Download the complete model package before importing its local modeling_dubbing.py:
pip install -U huggingface_hub
hf download IndexTeam/Index-Echo-S2ST-2B --local-dir ./Index-Echo-S2ST-2B
cd Index-Echo-S2ST-2B
Pinned environment
The release documents the following tested dependency pins. Use CUDA-compatible PyTorch wheels; the +cu129 builds require a wheel source that provides that CUDA build. System ffmpeg must be on PATH.
pip install torch==2.11.0+cu129 torchaudio==2.11.0+cu129 transformers==5.6.0 \
    tokenizers==0.22.2 librosa==1.0.0 onnxruntime==1.30.0 wetext==0.0.4 \
    kaldifst==1.8.0 conformer==0.3.2 hydra-core==1.3.7 HyperPyYAML==1.2.3 \
    lightning==2.6.6 x-transformers==2.11.24 einx==0.4.3 frozendict==2.4.7 \
    pyworld==0.3.5 soundfile==0.13.1 modelscope==1.37.1 safetensors==0.7.0 \
    numpy==2.4.6 openai-whisper==20250625
openai-whisper is used only for the package's ASR-based evaluation/self-check. The Japanese frontend (pyopenjtalk==0.4.1, including its dictionary, and pykakasi==2.3.0) is vendored under code/ja_ext/; the pipeline adds it to the import path automatically. All components run in one Python environment and process.
The package automatically applies two CosyVoice3 compatibility patches for Transformers 5.6 in code/tts/pipeline.py: keeping the CosyVoice3 LLM in fp32, and providing the full visible attention mask during autoregressive decoding. Keep the bundled code and dependency pins together.
Python API
Run this from the downloaded package directory, with input clips available at the indicated paths:
from modeling_dubbing import DubbingBridgeModel

model = DubbingBridgeModel.from_pretrained('.', device='cuda')

# Chinese source: three supported targets.
wav, sr = model.dub('input_zh.wav', lang='en', out_wav='dub_en.wav')
model.dub('input_zh.wav', lang='es', out_wav='dub_es.wav')
model.dub('input_zh.wav', lang='ja', out_wav='dub_ja.wav')

# English source: three supported targets.
model.dub('input_en.wav', lang='zh', out_wav='dub_zh.wav')
model.dub('input_en.wav', lang='es', out_wav='dub_es2.wav')
model.dub('input_en.wav', lang='ja', out_wav='dub_ja2.wav')

wav, sr, info = model.dub('input_en.wav', lang='zh', return_info=True)
print(sr)               # 24000 Hz
print(info['zh'])       # Source transcript; the key name is retained for both sources.
print(info['tgt_raw'])  # Model translation, before the speech frontend's normalization.
print(info['tgt_cv'])   # Speech-frontend text; Japanese uses a katakana representation.
print(info['src_lang']) # 'zh' or 'en'
lang always means the target language: en, es, ja, or zh. The source-language heuristic treats a source transcript containing CJK characters as Chinese and otherwise as English; it is not a general language identifier. Source and target must differ. The waveform is a float32 tensor of shape (1, T) at 24 kHz. out_wav saves it to a file. With return_info=True, the third return value includes the transcript, translation, source language, and synthesis diagnostics.
At the lower pipeline layer, extract(audio_path, lang) returns the translated text and aligned hidden states separately from synthesis. See the S2ST inference guide for the dub.py wrapper, and the video pipeline for segmentation and video timeline alignment.
Default inference settings
| Stage or setting | Released default |
|---|---|
| Transcription and translation | Greedy, temperature=0.0 / do_sample=False |
| Transcription/translation budget | max_new_tokens=1024 |
| Speech mode | h2cv (the only supported mode in this package) |
| Speech-token budget | max_tokens=1500; actual cap min(20 * m, 1500), where m is aligned target-text token count |
| Minimum speech length | 2 * m tokens before stop tokens are allowed |
| Speech sampling | sampling=25; release notes describe ras_sampling, top-k 25 / top-p 0.8 |
| Speech-generation seed | 42 |
| Synthesis speed | 1.0 |
| Output sample rate | 24000 Hz |
| CosyVoice3 execution | stream=False, load_trt=False, load_vllm=False, fp16=False; LLM kept in fp32 |
| Chunked orchestration | Disabled (chunk=False) |
Both sizes use these settings. Greedy transcription/translation does not make speech synthesis greedy. The public DubbingBridgeModel.dub wrapper does not expose a seed argument; seed changes are available through the lower-level pipeline's dub/synth APIs. Sampling may vary between calls even with the default seed, as documented in the release notes.
Configurable API parameters
The public wrapper and lower pipeline expose different controls. The defaults below are shared by both sizes.
| Interface | Parameter | Default | Behavior |
|---|---|---|---|
from_pretrained | model_dir | Required | Local directory containing the full package |
from_pretrained | device | cuda | CUDA device for the loaded components |
from_pretrained | mode | None → config default h2cv | Sets the default speech mode |
Public dub | audio_path | Required | Chinese or English source clip |
Public dub | lang | en | Target language: en, es, ja, zh; must differ from detected source |
Public dub | out_wav | None | Save path; None creates a temporary WAV |
Public dub | mode | None → loaded default | Only h2cv is accepted |
Public dub | chunk | False | True is unsupported in this release |
Public dub | return_info | False | Adds transcript, translation, and synthesis diagnostics to the return value |
Pipeline extract | lang | en | Target language for transcription/translation and alignment |
Pipeline extract | max_new_tokens | 1024 | Transcription/translation output budget |
Pipeline synth | out_wav | None | Optional output save path |
Pipeline synth | max_tokens | 1500 | Upper bound on generated speech tokens |
Pipeline synth | seed | 42 | Seed set before speech-token generation and acoustic synthesis |
Pipeline synth | prompt_wav | None | Uses the source audio unless a reference clip is supplied |
Pipeline synth | prompt_text | None | Uses the source transcript unless reference text is supplied |
For explicit text/speech budgets or seed control, use the lower pipeline after loading model as above:
pipe = model._pipe
ext = pipe.extract('input_zh.wav', lang='en', max_new_tokens=1024)
wav, info = pipe.synth(ext, out_wav='dub_en.wav', max_tokens=1500, seed=42)
The lower pipeline's dub(..., **kw) forwards synthesis options such as seed and max_tokens; changing the translation budget requires calling extract separately. Sampling argument 25 and synthesis speed 1.0 are fixed in the released pipeline code, not keyword arguments of the public wrapper. Translation stops at tokenizer EOS or <|im_end|>; speech generation uses CosyVoice3's defined stop tokens and the length limits above. The script does not explicitly override other text-generation knobs such as top_p, top_k, or repetition penalties.
Evaluation
The report compares end-to-end dubbing with a matched Index-Echo-S2TT + CosyVoice3 pipeline on in-house video dubbing data. Each pair shares the same frozen S2TT model and text translation, so the comparison measures the speech-generation path under a shared translation. For 2B, end-to-end dubbing lowers mean content error in four of six directions: zh→es, zh→ja, en→zh, and en→es. Across both sizes it improves eight of twelve size–direction pairs; Chinese → English favors the pipeline.
| Direction | Translator size | Content metric | Text judge ↑ | Pipeline error ↓ mean / median | E2E error ↓ mean / median | Pipeline speaker ↑ | E2E speaker ↑ |
|---|---|---|---|---|---|---|---|
| zh→en | 2B | WER | 0.830 | 0.0450 / 0.000 | 0.0709 / 0.029 | 0.722 | 0.743 |
| zh→en | 9B | WER | 0.840 | 0.0477 / 0.000 | 0.0615 / 0.000 | 0.718 | 0.739 |
| zh→es | 2B | WER | 0.728 | 0.0811 / 0.070 | 0.0704 / 0.051 | 0.747 | 0.743 |
| zh→es | 9B | WER | 0.793 | 0.0916 / 0.071 | 0.0773 / 0.057 | 0.746 | 0.746 |
| zh→ja | 2B | Kata CER | 0.760 | 0.0575 / 0.034 | 0.0493 / 0.027 | 0.777 | 0.780 |
| zh→ja | 9B | Kata CER | 0.815 | 0.0552 / 0.029 | 0.0436 / 0.021 | 0.778 | 0.782 |
| en→zh | 2B | CER | 0.825 | 0.0614 / 0.000 | 0.0372 / 0.000 | 0.630 | 0.623 |
| en→zh | 9B | CER | 0.800 | 0.0463 / 0.000 | 0.0485 / 0.000 | 0.632 | 0.623 |
| en→es | 2B | WER | 0.805 | 0.0867 / 0.070 | 0.0702 / 0.000 | 0.732 | 0.735 |
| en→es | 9B | WER | 0.820 | 0.0819 / 0.000 | 0.0660 / 0.000 | 0.736 | 0.729 |
| en→ja | 2B | Kata CER | 0.790 | 0.0342 / 0.000 | 0.0345 / 0.000 | 0.707 | 0.698 |
| en→ja | 9B | Kata CER | 0.803 | 0.0347 / 0.000 | 0.0337 / 0.000 | 0.705 | 0.710 |
The table includes both Index-Echo sizes, with this card's 2B translator rows emphasized. Every pipeline uses the same translator size and text translation as its E2E counterpart. Bold content-error values mark the lower mean within each matched row. Content error compares synthesized speech with the intended translated text using WER for English and Spanish, normalized CER for Chinese, and katakana CER for Japanese. These are different metrics and test sets; do not compare their values directly across target languages. Text translation is judged by Gemini-3.1-Pro and is shared within each pair. Speaker similarity is cosine similarity against the source speaker, rather than a guarantee of perfect voice preservation.
Chinese-source tests contain 100 examples for English and 200 each for Spanish and Japanese. English-source tests start with 200 examples per target, with 146–198 retained after filtering in the reported evaluation. Speaker similarity differs by 0.021 for Chinese → English and by at most 0.01 elsewhere in the complete matched table. These results use the report's stated protocol and are separate from the website's deployed-system comparison or earlier Chinese-source evaluations. See the technical report for details.
Earlier Chinese-source S2ST evaluation (2B)
The report also records an external comparison for the 2B model on an earlier Chinese-source test set. Its data and protocol differ from the matched study above; the scores should be read within this comparison.
| Target | Index-Echo-2B S2ST MT judge ↑ | SeamlessM4T-v2 MT judge ↑ |
|---|---|---|
| English | 0.905 | 0.370 |
| Spanish | 0.823 | 0.343 |
| Japanese | 0.838 | 0.310 |
SeamlessM4T-v2 is an external speech-translation baseline; this comparison does not establish equal total parameter counts. The report does not provide 9B results for this earlier test. The current 2B/9B comparison is the matched six-direction table above.
Package details
| File or directory | Purpose |
|---|---|
config.json, modeling_dubbing.py | Component configuration and DubbingBridgeModel interface |
stlm_llm/ | Qwen3.5-family translator decoder and tokenizer |
stlm_ckpt/ | Trained audio encoder/connector checkpoint |
stlm_omni/ | Qwen3-Omni configuration and AuT source components |
cosyvoice3/ | CosyVoice3 LLM, flow, HiFT, and ONNX assets |
bridge/ | mapper.safetensors, mapper_config.json, and checkpoint archive |
wetext_en_tn/, wetext_repo/ | Offline text-normalization assets |
code/tts/, code/stlm/, code/bridge/ | Dubbing, speech translation, and mapper implementation |
code/ja_ext/, code/cosyvoice_repo/ | Vendored Japanese frontend and CosyVoice inference code |
_legacy/ | Original pre-conversion checkpoint archives, when present |
samples/, verify_export.py | Input clips, reference dubs, and export/self-check assets |
The loader prefers safetensors for the translator, mapper, and CosyVoice3 components, with original-format fallback. The export records version v4.0.0-fulldir-2b (2026-09-27), translator EXP-53-2B iter12613, and mapper rft_fd2b53_sw_lam20/mapper_best. Keep bundled assets together for offline loading. Use materialized copies (cp -rL or an appropriate rsync configuration) when copying training-side packages whose weight files are hard links.
Text normalization and alignment
| Direction | Translator text used for alignment | Speech-frontend text | Hidden-state alignment |
|---|---|---|---|
| zh→en | Normalized English | Same normalized text | Character-overlap mean pooling |
| zh→es | Normalized Spanish | Same normalized text | Character-overlap mean pooling |
| zh→ja | Original mixed-script Japanese | Katakana frontend representation | Word mapping to original text, then pooling |
| en→zh | Original translation | Wetext-normalized Chinese | Character-overlap mean pooling |
| en→es | Original translation | Normalized Spanish | Character-overlap mean pooling |
| en→ja | Original mixed-script Japanese | Katakana frontend representation | Word mapping to original text, then pooling |
The source transcript is the first nonempty line and the translation is the last nonempty line of translator output. The mapper's training language list is ['en', 'es', 'ja', 'zh', 'ja', 'es'], with first-occurrence indices en=0, es=1, ja=2, and zh=3; the duplicate trailing slots are unused. The loader asserts this mapping. Do not reorder it when modifying or converting the package.
Limitations
- Use one CUDA GPU with at least 12 GB VRAM. CPU inference is unverified; memory use depends on the runtime and input.
- The release is tuned for utterance-level dubbing. Keep individual utterances at or below approximately 30 seconds; use the full video pipeline for longer recordings.
chunk=TrueraisesNotImplementedErrorin this release. - The release notes report occasional failures on roughly 1–2% of tested short English-source inputs, including a CosyVoice convolution-kernel error or a one-token collapse producing approximately 0.04 seconds of audio. Check the generated audio and retry through the lower-level pipeline with a different seed, or discard the failed result.
- Translation errors propagate into speech. Inspect
tgt_rawandtgt_cvwhen fidelity is important. - Source-voice conditioning does not guarantee identical timbre, pronunciation, or delivery. The source-language heuristic can misclassify atypical or mixed-language transcripts.
- Reported reward-optimization gains for English-source synthesis are small and direction-dependent; quality still depends strongly on the underlying translator and speech generator.
Related models
| Family | Task | Released sizes |
|---|---|---|
| Index-Translate | Text translation and translation instructions across 150 languages | 2B, 9B, 35B-A3B (preview) |
| Index-Echo S2TT | Speech-to-text translation and subtitles | 2B, 9B |
| Index-Echo S2ST | Speech-to-speech translation with source-voice conditioning | 2B, 9B |
| Index-Homura | Translation with a target syllable count | 2B, 9B |
| Index-NativeLong | Native long-document translation; released as Index-Nailong | 2B, 9B |
The text foundation's 150-language coverage does not describe the released speech interfaces. Use the task-specific directions documented above.
Citation
@techreport{indextranslate2026,
  author={Tianjiao Li and Mengran Yu and Chenyu Shi and Lusheng Zhang and
          Qisi Chen and Yanshan Zhou and Ji Qi and Jingying Liu and
          Yuang Feng and Ziang Cui and Tianxing Yan},
  title={Index-Translate: A Multilingual Translation Model Family --- Text, Speech, Controlled Dubbing, and Long-Document Translation},
  institution={Index LLM Team},
  year={2026},
  month={September}
}
License and feedback
Apache-2.0. Questions and feedback are welcome through GitHub Issues.