
README
FireRedAudio
Official PyTorch code for
FireRedAudio: A General-Purpose Audio Language Model with Decoupled Continuous Representations for Understanding and Generation



Overview
One model to listen, understand, reason, speak, and edit.
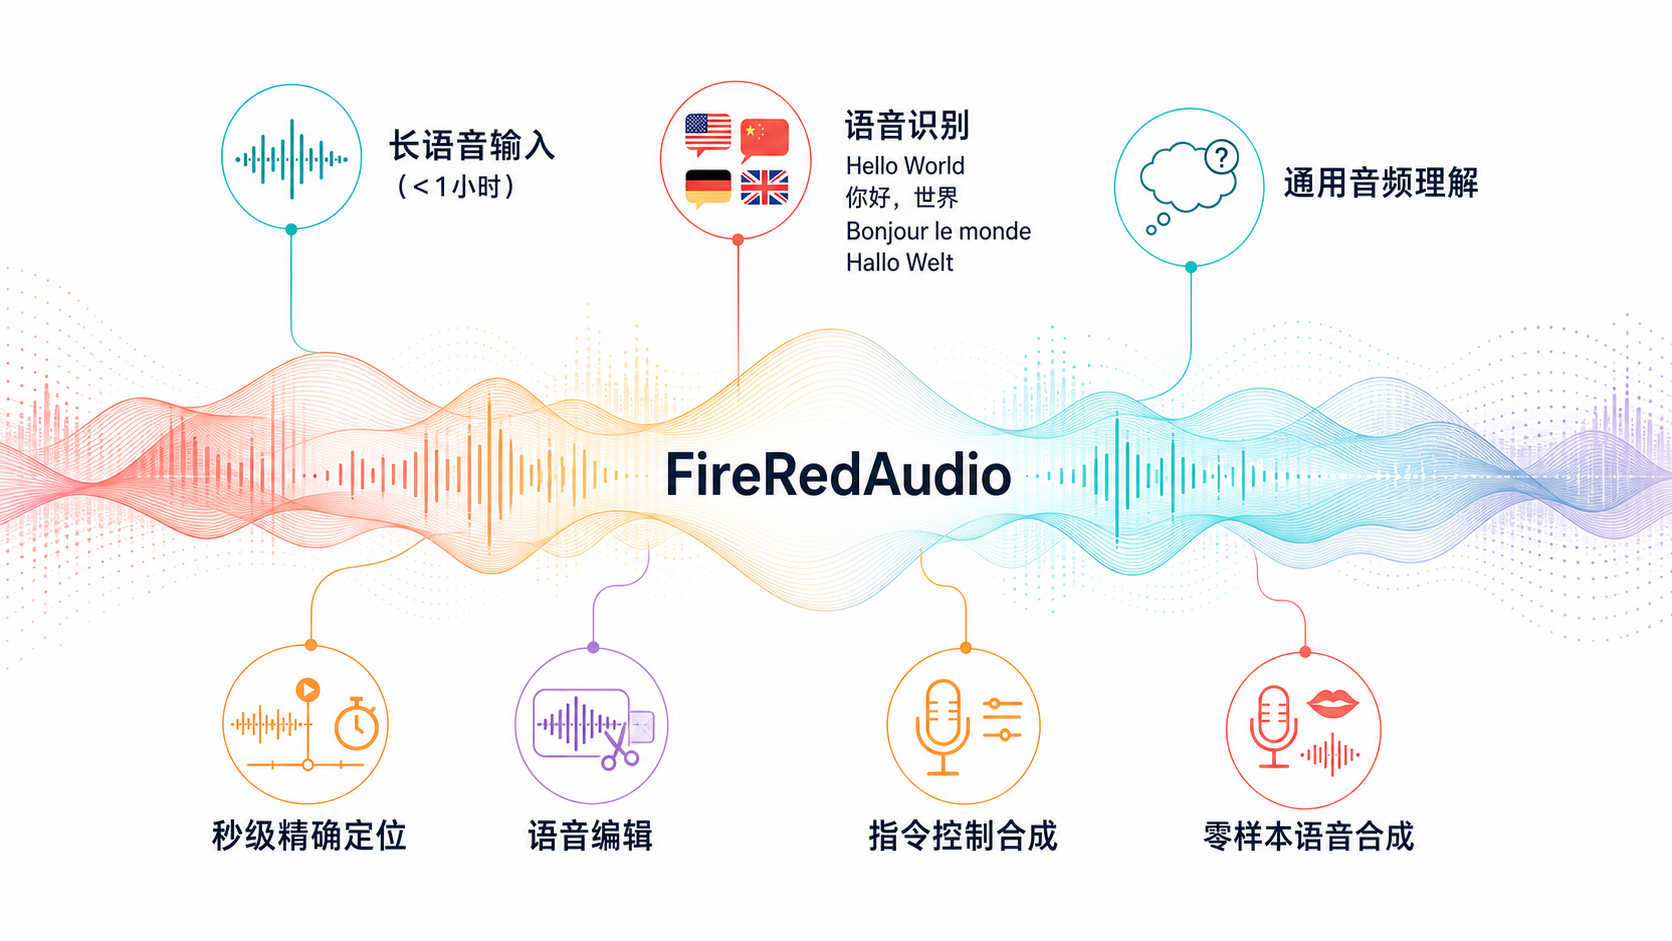
FireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM with decoupled continuous representations: an Audio Encoder handles understanding, while a RedAE pathway handles generation. A single model supports ASR, audio understanding, zero-shot TTS, instruct TTS, semantic/acoustic speech editing, and accurate temporal grounding over recordings up to one hour long.
Highlights ✨
- 🧩 Purpose-built representations, one shared backbone — The Audio Encoder pathway serves understanding, while the RedAE-Patch pathway serves speech generation. Their representations remain decoupled but share the same language and reasoning backbone. To the best of our knowledge, this is the first publicly disclosed design of its kind in a unified audio-language model.
- 📊 One model, a full audio stack — FireRedAudio spans ASR, broad and fine-grained audio understanding, zero-shot TTS, Instruct TTS, and free-form speech editing, achieving competitive or leading results across MMAU, MMSU, Seed-TTS-Eval, InstructTTSEval, and Ming-Freeform-Audio-Edit.
- 🎙️ Create and edit speech with natural language — Clone a voice from a reference clip, design a voice from a description, or edit what was said and how it sounds through one continuous-latent generation pathway.
- ⏱️ Go from minutes to hour-long recordings — Understand recordings up to one hour with precise time-to-content alignment. Organize audio into timestamped structures, produce grounded summaries, retrieve content by time (or time by content), and reason over evidence distributed across the recording.
Long-Audio Understanding: Time–Content Alignment Demo
| English | Chinese |
|---|---|
News
- [2026.08.21] We release the FireRedAudio code and model.
Contents
Quick Start 🚀
Installation
Requires Python 3.10 and uv. System prerequisites: a CUDA toolkit (GPU inference + compiling the causal-conv1d / flash-attn kernels) and ffmpeg (audio decoding via torchaudio/torchcodec).
Wheels target CUDA 12.8 (cu128) by default. For a different CUDA version, change the
pytorch-cu128 index URL in pyproject.toml (e.g. cu126 / cu129) and
re-run uv sync.
uv sync --extra accel --extra accel-build --group tools # + compile causal-conv1d, flash-attn
Model Download
Download the pretrained model from Hugging Face with the hf CLI:
uv run hf download FireRedTeam/FireRedAudio --local-dir pretrained_models/
Alternatively, download the pretrained model using modelscope CLI:
uv pip install modelscope
uv run modelscope download --model FireRedTeam/FireRedAudio --local_dir pretrained_models/
Python API
import torch
import torchaudio
from inference import FireRedAudioInference

# Init the model. Understanding tasks need only --model; generation tasks
# additionally need the RedAE decoder weights.
engine = FireRedAudioInference(
    model_path="pretrained_models/FireRedAudio",
    vae_decoder_path="pretrained_models/RedAE_decoder/model.pt",   # only for tts / edit / voice_design
    device="cuda:0",
)

# ---- 1) Speech recognition (ASR) -----------------------------------------
res = engine.understand("assets/examples/asr_zh_fleurs.wav", "Transcribe speech to text.", task="asr")
print(res.answer)

# ---- 2) Audio understanding (with optional chain-of-thought) --------------
res = engine.understand(
    "assets/examples/assets_mmau_test.wav",
    "What illness did Second speaker's friend suffer from?\n(A) Progressive arthritis (B) Progressive cancer (C) Acute pneumonia (D) Chronic heart disease",
    task="understand", enable_thinking=True, max_new_tokens=10240,
)
print("CoT:")
print(res.reasoning)   # CoT reasoning, or None
print("Answer")
print(res.answer)

# ---- 3) Zero-shot TTS (ICL voice cloning) ---------------------------------
res = engine.tts(
    prompt_text="同时,他强调微调要科学有序。",
    prompt_audio="assets/examples/tts_zh_prompt.wav",
    target_text="安徽淮南秦师傅发现,停在小区的爱车右前驾驶窗玻璃被砸。",
    language="zh",
)
torchaudio.save("tts.wav", res.audio.cpu(), sample_rate=24000)

# ---- 4) Speech editing -----------------------------------------------------
# semantic: rewrite / substitute / insert / delete content. The model first writes
#          <|sot|>{rewritten text}<|eot|> then renders the audio.
res = engine.edit("assets/examples/edit_semantic_zh_ref.wav", "delete '比普通的茶叶要'", edit_type="semantic")
print(res.text)
torchaudio.save("edit_semantic.wav", res.audio.cpu(), sample_rate=24000)

# acoustic: change pitch / speed / volume. The instruction must follow the exact
#           templates below (the model is trained on these, not free-form phrasing):
#   pitch   ->  "shift the pitch by N step(s)"       N in {-6, ..., -1, 1, ..., +6}
#   speed   ->  "adjust the speed to X"              X in [0.5, 2.0], step 0.1
#   volume  ->  "adjust the volume to X"             X in [0.3, 2.0], step 0.1
res = engine.edit("assets/examples/edit_acoustic_zh_ref.wav", "shift the pitch by 3 steps", edit_type="acoustic")
torchaudio.save("edit_acoustic.wav", res.audio.cpu(), sample_rate=24000)

# ---- 5) Voice design (synthesis from a timbre description) -----------------
res = engine.voice_design(
    instruction="以女性高音区的清亮音色,表现出青年阶段的特质,音量略强,语速适中稍快,语调带有解释意味和急切的情感流露,确保语音流畅自然。",
    text="是我请他来的,可他什么也不知道,他来只是想打听一下,你们厂是不是有旧锅炉?",
)
torchaudio.save("voice_design.wav", res.audio.cpu(), sample_rate=24000)
Command Line Inference
# speech recognition
uv run inference.py --task asr --model pretrained_models/FireRedAudio --audio assets/examples/asr_zh_fleurs.wav

# audio understanding and QA; several --audio for e.g. speaker verification,
# --enable-thinking to let the model reason first
uv run inference.py --task understand --model pretrained_models/FireRedAudio --audio assets/examples/assets_mmau_test.wav \
    --prompt "What illness did Second speaker's friend suffer from?\n(A) Progressive arthritis (B) Progressive cancer (C) Acute pneumonia (D) Chronic heart disease" --enable-thinking --max-new-tokens 4096


# ICL voice cloning from a reference audio and its transcript
uv run inference.py --task tts --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --prompt-audio assets/examples/tts_zh_prompt.wav --prompt-text "同时,他强调微调要科学有序。" \
    --target-text "安徽淮南秦师傅发现,停在小区的爱车右前驾驶窗玻璃被砸。" --language zh --output tts.wav

# speech editing; semantic rewrites content, acoustic changes pitch / speed / volume.
uv run inference.py --task edit --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --audio assets/examples/edit_semantic_zh_ref.wav --instruction "delete '比普通的茶叶要'" --edit-type semantic \
    --output edit_semantic.wav

# acoustic: instructions must use the exact trained templates, e.g.
#   "shift the pitch by N step(s)"  in  -6..6 steps        (pitch)
#   "adjust the speed to X"         in  [0.5, 2.0], step .1 (speed)
#   "adjust the volume to X"        in  [0.3, 2.0], step .1 (volume)
uv run inference.py --task edit --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --audio assets/examples/edit_acoustic_zh_ref.wav --instruction "shift the pitch by 3 steps" --edit-type acoustic \
    --output edit_acoustic.wav

# voice design
uv run inference.py --task voice_design --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --instruction "以女性高音区的清亮音色,表现出青年阶段的特质,音量略强,语速适中稍快,语调带有解释意味和急切的情感流露,确保语音流畅自然。" \
    --text "是我请他来的,可他什么也不知道,他来只是想打听一下,你们厂是不是有旧锅炉?" --output voice_design.wav
Performance
Audio Understanding
Model | MMAU test-mini | MMAU test | MMSU |
|---|---|---|---|
| Step-Audio-R1.1 | 77.7 | – | 75.9 |
| Step-Audio 2 | 78.0 | – | – |
| MiMo-Audio-7B-Instruct | 74.9 | – | 61.7 |
| Kimi-Audio | 65.2 | – | – |
| LongCat-Next | 76.4 | – | – |
| Qwen3-Omni-30B-A3B-Instruct | 77.5 | – | 69.0 |
| Gemini 3.1 Pro | 80.7* | 78.8* | 82.7* |
| Qwen3.5-Omni-Plus | 81.4* | 79.9* | 80.7* |
| FireRedAudio | 82.0 | 80.9 | 83.3 |
- Results marked with * are obtained from our own evaluation.
ASR
Model | AISHELL‑1 | AISHELL‑2 test‑ios | WenetSpeech Net | Meeting | LibriSpeech clean | other | FLEURS en | zh | FLEURS‑102 avg | KeSpeech | Opencpop |
|---|---|---|---|---|---|---|---|---|
| Step‑Audio 2 | 0.63 | 2.10 | 4.67 | 4.75 | 1.17 | 2.42 | 3.03 | 2.68 | – | 3.63 | – |
| MiMo‑Audio‑7B‑Instruct | 1.65 | – | – | 3.50 | – | – | – | – | – |
| Ming‑UniAudio‑16B‑A3B | – | 2.84 | – | 1.62 | – | – | – | – | – |
| Kimi‑Audio | 0.60 | 2.56 | 5.37 | 6.28 | 1.28 | 2.42 | 4.44 | 2.69 | – | – | – |
| LongCat‑Next | 1.47 | 2.82 | 5.98 | 8.19 | 1.63 | 3.42 | 5.24 | 3.24 | – | – | – |
| Qwen3‑Omni‑30B‑A3B‑Instruct | – | – | 4.69 | 5.89 | 1.22 | 2.48 | 2.72 | 2.20 | – | – | 1.54 |
| Gemini 3.1 Pro | 3.66* | 7.10* | 11.53 | 14.21 | 3.36 | 4.41 | 2.97* | 4.28* | 18.23* | 23.67 | 6.83 |
| Qwen3.5‑Omni‑Plus | 0.82* | 2.26* | 4.30 | 5.84 | 1.11 | 2.23 | 3.33* | 2.46* | 23.66* | 3.46 | 1.49 |
| FireRedAudio | 0.71 | 2.63 | 5.18 | 5.33 | 0.67 | 2.91 | 2.53 | 3.14 | 14.94 | 4.82 | 1.63 |
- Results marked with * are obtained from our own evaluation.
Zero-Shot TTS
Model | Seed-ZH CER↓ | SIM↑ | Seed-EN WER↓ | SIM↑ | Avg. CER/WER↓ | SIM↑ |
|---|---|---|---|
| Seed-TTS | 1.12 | 0.80 | 2.25 | 0.76 | 1.69 | 0.78 |
| FireRedTTS | 1.51 | 0.65 | 3.82 | 0.53 | 2.67 | 0.59 |
| FireRedTTS-2 | 1.14 | 0.74 | 1.95 | 0.65 | 1.55 | 0.69 |
| DiTAR (1B) | 1.02 | 0.75 | 1.69 | 0.74 | 1.36 | 0.75 |
| F5-TTS | 1.56 | 0.74 | 1.83 | 0.65 | 1.70 | 0.70 |
| CosyVoice 2 | 1.45 | 0.75 | 2.57 | 0.65 | 2.01 | 0.70 |
| CosyVoice 3-1.5B | 1.12 | 0.78 | 2.21 | 0.72 | 1.67 | 0.75 |
| MiMo-Audio-7B-Instruct | 1.96 | – | 5.37 | – | 3.67 | – |
| Qwen2.5-Omni-7B (RL) | 1.42 | 0.75 | 2.33 | 0.64 | 1.88 | 0.70 |
| Qwen3-Omni-30B-A3B-Instruct | 1.07 | – | 1.39 | – | 1.23 | – |
| Ming-UniAudio-16B-A3B | 0.95 | 0.70 | 1.85 | 0.58 | 1.40 | 0.64 |
| FireRedAudio | 0.83 | 0.74 | 1.56 | 0.68 | 1.20 | 0.71 |
Instruct TTS
Model | ZH APS↑ | DSD↑ | RP↑ | EN APS↑ | DSD↑ | RP↑ |
|---|---|---|
| VoiceSculptor-VD | 74.6 | 63.5 | 62.0 | – | – | – |
| MOSS-VoiceGenerator | 71.6 | 72.5 | 61.3 | 58.8 | 71.8 | 61.6 |
| Ming-Omni-TTS-16B | 84.6 | 70.7 | 56.0 | – | – | – |
| Qwen3-TTS-VD | 83.7 | 81.7 | 65.8 | 76.4 | 81.4 | 64.2 |
| FireRedAudio | 86.0 | 84.1 | 70.1 | 81.1 | 83.6 | 70.3 |
- These results are obtained from our own evaluation.
Semantic Editing
Task | Setting | Metric | Ming-UniAudio-Edit zh | en | FireRedAudio zh | en |
|---|---|---|---|---|
| Deletion | basic | WER (%)↓ | 11.89 | 14.85 | 10.82 | 12.78 |
| SIM↑ | 0.78 | 0.76 | 0.78 | 0.79 | ||
| ACC (%)↑ | 100.00 | 82.22 | 100.00 | 97.78 | ||
| no-edit WER (%)↓ | 11.49 | 24.26 | 10.70 | 23.16 | ||
| open | WER (%)↓ | 22.92 | 27.60 | 10.49 | 16.65 | |
| SIM↑ | 0.81 | 0.74 | 0.80 | 0.80 | ||
| ACC (%)↑ | 82.92 | 85.00 | 89.32 | 86.50 | ||
| no-edit WER (%)↓ | 17.50 | 35.21 | 7.84 | 25.43 | ||
| Insertion | basic | WER (%)↓ | 3.42 | 6.63 | 3.28 | 4.98 |
| SIM↑ | 0.83 | 0.79 | 0.83 | 0.84 | ||
| ACC (%)↑ | 80.00 | 71.43 | 83.53 | 87.58 | ||
| no-edit WER (%)↓ | 3.52 | 17.70 | 3.51 | 16.56 | ||
| open | WER (%)↓ | 3.89 | 7.59 | 2.57 | 6.98 | |
| SIM↑ | 0.83 | 0.79 | 0.83 | 0.84 | ||
| ACC (%)↑ | 79.31 | 62.31 | 86.90 | 69.85 | ||
| no-edit WER (%)↓ | 4.10 | 18.84 | 2.77 | 17.83 | ||
| Substitution | basic | WER (%)↓ | 4.52 | 8.99 | 2.66 | 4.46 |
| SIM↑ | 0.82 | 0.78 | 0.84 | 0.81 | ||
| ACC (%)↑ | 78.62 | 59.78 | 87.42 | 75.98 | ||
| no-edit WER (%)↓ | 4.63 | 19.28 | 2.91 | 16.34 | ||
| open | WER (%)↓ | 4.56 | 7.64 | 2.45 | 4.41 | |
| SIM↑ | 0.83 | 0.77 | 0.84 | 0.81 | ||
| ACC (%)↑ | 76.62 | 65.62 | 90.15 | 76.95 | ||
| no-edit WER (%)↓ | 4.75 | 18.39 | 2.71 | 16.16 |
Acoustic Editing
Task | Metric | Ming-UniAudio-Edit zh | en | FireRedAudio zh | en |
|---|---|---|---|
| Speed Alteration | WER (%)↓ | 5.88 | 17.53 | 2.00 | 4.43 |
| SIM↑ | 0.66 | 0.57 | 0.79 | 0.71 | |
| RDE (%)↓ | 6.36 | 5.92 | 2.60 | 4.02 | |
| Pitch Alteration | WER (%)↓ | 7.45 | 13.37 | 2.00 | 3.04 |
| SIM↑ | 0.36 | 0.24 | 0.52 | 0.44 | |
| Volume Alteration | WER (%)↓ | 1.71 | 1.35 | 1.60 | 1.30 |
| SIM↑ | 0.86 | 0.80 | 0.94 | 0.93 | |
| RAE (%)↓ | 14.90 | 11.70 | 2.39 | 3.74 |
Limitations
- Everything but ASR is Chinese/English only. Speech generation (
tts/edit/voice_design) and audio understanding are limited to Chinese and English —ttsselects the language via--language zh/en. ASR is the only task that supports more languages. - Zero-shot TTS is not deterministic by default. The flow-matching decoder samples random noise, so output varies run to run; pass a fixed seed (
set_seed(...)in the API,--seedon the CLI) for reproducibility, and note that quality can differ across seeds. - Long-form input is supported up to about one hour. Beyond that the model is untested and time-to-content alignment may degrade.
Usage Disclaimer
- The project incorporates zero-shot voice cloning functionality; Please note that this capability is intended solely for academic research purposes.
- DO NOT use this model for ANY illegal activities❗️❗️
- The developers assume no liability for any misuse of this model.
- If you identify any instances of abuse, misuse, or fraudulent activities related to this project, please report them to our team immediately.
Citation
@article{fireredaudio,
  title   = {FireRedAudio: A General-Purpose Audio Language Model with Decoupled Continuous Representations for Understanding and Generation},
  author  = {FireRed Team},
  journal = {arXiv preprint},
  year    = {2026},
}
Acknowledgements
- Qwen3.5 for the language model foundation
- Whisper-large-v3 for the Audio Encoder initialization
- x-transformers for RotaryEmbedding
- vocos for ISTFT implementation
License
Released under the Apache-2.0 license.
Contributors

7 commits
Similar repos

Linked in READMEs


README
FireRedAudio
Official PyTorch code for
FireRedAudio: A General-Purpose Audio Language Model with Decoupled Continuous Representations for Understanding and Generation
Overview
One model to listen, understand, reason, speak, and edit.
FireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM with decoupled continuous representations: an Audio Encoder handles understanding, while a RedAE pathway handles generation. A single model supports ASR, audio understanding, zero-shot TTS, instruct TTS, semantic/acoustic speech editing, and accurate temporal grounding over recordings up to one hour long.
Highlights ✨
- 🧩 Purpose-built representations, one shared backbone — The Audio Encoder pathway serves understanding, while the RedAE-Patch pathway serves speech generation. Their representations remain decoupled but share the same language and reasoning backbone. To the best of our knowledge, this is the first publicly disclosed design of its kind in a unified audio-language model.
- 📊 One model, a full audio stack — FireRedAudio spans ASR, broad and fine-grained audio understanding, zero-shot TTS, Instruct TTS, and free-form speech editing, achieving competitive or leading results across MMAU, MMSU, Seed-TTS-Eval, InstructTTSEval, and Ming-Freeform-Audio-Edit.
- 🎙️ Create and edit speech with natural language — Clone a voice from a reference clip, design a voice from a description, or edit what was said and how it sounds through one continuous-latent generation pathway.
- ⏱️ Go from minutes to hour-long recordings — Understand recordings up to one hour with precise time-to-content alignment. Organize audio into timestamped structures, produce grounded summaries, retrieve content by time (or time by content), and reason over evidence distributed across the recording.
Long-Audio Understanding: Time–Content Alignment Demo
| English | Chinese |
|---|---|
News
- [2026.08.21] We release the FireRedAudio code and model.
Contents
Quick Start 🚀
Installation
Requires Python 3.10 and uv. System prerequisites: a CUDA toolkit (GPU inference + compiling the causal-conv1d / flash-attn kernels) and ffmpeg (audio decoding via torchaudio/torchcodec).
Wheels target CUDA 12.8 (cu128) by default. For a different CUDA version, change the
pytorch-cu128 index URL in pyproject.toml (e.g. cu126 / cu129) and
re-run uv sync.
uv sync --extra accel --extra accel-build --group tools # + compile causal-conv1d, flash-attn
Model Download
Download the pretrained model from Hugging Face with the hf CLI:
uv run hf download FireRedTeam/FireRedAudio --local-dir pretrained_models/
Alternatively, download the pretrained model using modelscope CLI:
uv pip install modelscope
uv run modelscope download --model FireRedTeam/FireRedAudio --local_dir pretrained_models/
Python API
import torch
import torchaudio
from inference import FireRedAudioInference

# Init the model. Understanding tasks need only --model; generation tasks
# additionally need the RedAE decoder weights.
engine = FireRedAudioInference(
    model_path="pretrained_models/FireRedAudio",
    vae_decoder_path="pretrained_models/RedAE_decoder/model.pt",   # only for tts / edit / voice_design
    device="cuda:0",
)

# ---- 1) Speech recognition (ASR) -----------------------------------------
res = engine.understand("assets/examples/asr_zh_fleurs.wav", "Transcribe speech to text.", task="asr")
print(res.answer)

# ---- 2) Audio understanding (with optional chain-of-thought) --------------
res = engine.understand(
    "assets/examples/assets_mmau_test.wav",
    "What illness did Second speaker's friend suffer from?\n(A) Progressive arthritis (B) Progressive cancer (C) Acute pneumonia (D) Chronic heart disease",
    task="understand", enable_thinking=True, max_new_tokens=10240,
)
print("CoT:")
print(res.reasoning)   # CoT reasoning, or None
print("Answer")
print(res.answer)

# ---- 3) Zero-shot TTS (ICL voice cloning) ---------------------------------
res = engine.tts(
    prompt_text="同时,他强调微调要科学有序。",
    prompt_audio="assets/examples/tts_zh_prompt.wav",
    target_text="安徽淮南秦师傅发现,停在小区的爱车右前驾驶窗玻璃被砸。",
    language="zh",
)
torchaudio.save("tts.wav", res.audio.cpu(), sample_rate=24000)

# ---- 4) Speech editing -----------------------------------------------------
# semantic: rewrite / substitute / insert / delete content. The model first writes
#          <|sot|>{rewritten text}<|eot|> then renders the audio.
res = engine.edit("assets/examples/edit_semantic_zh_ref.wav", "delete '比普通的茶叶要'", edit_type="semantic")
print(res.text)
torchaudio.save("edit_semantic.wav", res.audio.cpu(), sample_rate=24000)

# acoustic: change pitch / speed / volume. The instruction must follow the exact
#           templates below (the model is trained on these, not free-form phrasing):
#   pitch   ->  "shift the pitch by N step(s)"       N in {-6, ..., -1, 1, ..., +6}
#   speed   ->  "adjust the speed to X"              X in [0.5, 2.0], step 0.1
#   volume  ->  "adjust the volume to X"             X in [0.3, 2.0], step 0.1
res = engine.edit("assets/examples/edit_acoustic_zh_ref.wav", "shift the pitch by 3 steps", edit_type="acoustic")
torchaudio.save("edit_acoustic.wav", res.audio.cpu(), sample_rate=24000)

# ---- 5) Voice design (synthesis from a timbre description) -----------------
res = engine.voice_design(
    instruction="以女性高音区的清亮音色,表现出青年阶段的特质,音量略强,语速适中稍快,语调带有解释意味和急切的情感流露,确保语音流畅自然。",
    text="是我请他来的,可他什么也不知道,他来只是想打听一下,你们厂是不是有旧锅炉?",
)
torchaudio.save("voice_design.wav", res.audio.cpu(), sample_rate=24000)
Command Line Inference
# speech recognition
uv run inference.py --task asr --model pretrained_models/FireRedAudio --audio assets/examples/asr_zh_fleurs.wav

# audio understanding and QA; several --audio for e.g. speaker verification,
# --enable-thinking to let the model reason first
uv run inference.py --task understand --model pretrained_models/FireRedAudio --audio assets/examples/assets_mmau_test.wav \
    --prompt "What illness did Second speaker's friend suffer from?\n(A) Progressive arthritis (B) Progressive cancer (C) Acute pneumonia (D) Chronic heart disease" --enable-thinking --max-new-tokens 4096


# ICL voice cloning from a reference audio and its transcript
uv run inference.py --task tts --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --prompt-audio assets/examples/tts_zh_prompt.wav --prompt-text "同时,他强调微调要科学有序。" \
    --target-text "安徽淮南秦师傅发现,停在小区的爱车右前驾驶窗玻璃被砸。" --language zh --output tts.wav

# speech editing; semantic rewrites content, acoustic changes pitch / speed / volume.
uv run inference.py --task edit --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --audio assets/examples/edit_semantic_zh_ref.wav --instruction "delete '比普通的茶叶要'" --edit-type semantic \
    --output edit_semantic.wav

# acoustic: instructions must use the exact trained templates, e.g.
#   "shift the pitch by N step(s)"  in  -6..6 steps        (pitch)
#   "adjust the speed to X"         in  [0.5, 2.0], step .1 (speed)
#   "adjust the volume to X"        in  [0.3, 2.0], step .1 (volume)
uv run inference.py --task edit --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --audio assets/examples/edit_acoustic_zh_ref.wav --instruction "shift the pitch by 3 steps" --edit-type acoustic \
    --output edit_acoustic.wav

# voice design
uv run inference.py --task voice_design --model pretrained_models/FireRedAudio --vae-decoder pretrained_models/RedAE_decoder/model.pt \
    --instruction "以女性高音区的清亮音色,表现出青年阶段的特质,音量略强,语速适中稍快,语调带有解释意味和急切的情感流露,确保语音流畅自然。" \
    --text "是我请他来的,可他什么也不知道,他来只是想打听一下,你们厂是不是有旧锅炉?" --output voice_design.wav
Performance
Audio Understanding
Model | MMAU test-mini | MMAU test | MMSU |
|---|---|---|---|
| Step-Audio-R1.1 | 77.7 | – | 75.9 |
| Step-Audio 2 | 78.0 | – | – |
| MiMo-Audio-7B-Instruct | 74.9 | – | 61.7 |
| Kimi-Audio | 65.2 | – | – |
| LongCat-Next | 76.4 | – | – |
| Qwen3-Omni-30B-A3B-Instruct | 77.5 | – | 69.0 |
| Gemini 3.1 Pro | 80.7* | 78.8* | 82.7* |
| Qwen3.5-Omni-Plus | 81.4* | 79.9* | 80.7* |
| FireRedAudio | 82.0 | 80.9 | 83.3 |
- Results marked with * are obtained from our own evaluation.
ASR
Model | AISHELL‑1 | AISHELL‑2 test‑ios | WenetSpeech Net | Meeting | LibriSpeech clean | other | FLEURS en | zh | FLEURS‑102 avg | KeSpeech | Opencpop |
|---|---|---|---|---|---|---|---|---|
| Step‑Audio 2 | 0.63 | 2.10 | 4.67 | 4.75 | 1.17 | 2.42 | 3.03 | 2.68 | – | 3.63 | – |
| MiMo‑Audio‑7B‑Instruct | 1.65 | – | – | 3.50 | – | – | – | – | – |
| Ming‑UniAudio‑16B‑A3B | – | 2.84 | – | 1.62 | – | – | – | – | – |
| Kimi‑Audio | 0.60 | 2.56 | 5.37 | 6.28 | 1.28 | 2.42 | 4.44 | 2.69 | – | – | – |
| LongCat‑Next | 1.47 | 2.82 | 5.98 | 8.19 | 1.63 | 3.42 | 5.24 | 3.24 | – | – | – |
| Qwen3‑Omni‑30B‑A3B‑Instruct | – | – | 4.69 | 5.89 | 1.22 | 2.48 | 2.72 | 2.20 | – | – | 1.54 |
| Gemini 3.1 Pro | 3.66* | 7.10* | 11.53 | 14.21 | 3.36 | 4.41 | 2.97* | 4.28* | 18.23* | 23.67 | 6.83 |
| Qwen3.5‑Omni‑Plus | 0.82* | 2.26* | 4.30 | 5.84 | 1.11 | 2.23 | 3.33* | 2.46* | 23.66* | 3.46 | 1.49 |
| FireRedAudio | 0.71 | 2.63 | 5.18 | 5.33 | 0.67 | 2.91 | 2.53 | 3.14 | 14.94 | 4.82 | 1.63 |
- Results marked with * are obtained from our own evaluation.
Zero-Shot TTS
Model | Seed-ZH CER↓ | SIM↑ | Seed-EN WER↓ | SIM↑ | Avg. CER/WER↓ | SIM↑ |
|---|---|---|---|
| Seed-TTS | 1.12 | 0.80 | 2.25 | 0.76 | 1.69 | 0.78 |
| FireRedTTS | 1.51 | 0.65 | 3.82 | 0.53 | 2.67 | 0.59 |
| FireRedTTS-2 | 1.14 | 0.74 | 1.95 | 0.65 | 1.55 | 0.69 |
| DiTAR (1B) | 1.02 | 0.75 | 1.69 | 0.74 | 1.36 | 0.75 |
| F5-TTS | 1.56 | 0.74 | 1.83 | 0.65 | 1.70 | 0.70 |
| CosyVoice 2 | 1.45 | 0.75 | 2.57 | 0.65 | 2.01 | 0.70 |
| CosyVoice 3-1.5B | 1.12 | 0.78 | 2.21 | 0.72 | 1.67 | 0.75 |
| MiMo-Audio-7B-Instruct | 1.96 | – | 5.37 | – | 3.67 | – |
| Qwen2.5-Omni-7B (RL) | 1.42 | 0.75 | 2.33 | 0.64 | 1.88 | 0.70 |
| Qwen3-Omni-30B-A3B-Instruct | 1.07 | – | 1.39 | – | 1.23 | – |
| Ming-UniAudio-16B-A3B | 0.95 | 0.70 | 1.85 | 0.58 | 1.40 | 0.64 |
| FireRedAudio | 0.83 | 0.74 | 1.56 | 0.68 | 1.20 | 0.71 |
Instruct TTS
Model | ZH APS↑ | DSD↑ | RP↑ | EN APS↑ | DSD↑ | RP↑ |
|---|---|---|
| VoiceSculptor-VD | 74.6 | 63.5 | 62.0 | – | – | – |
| MOSS-VoiceGenerator | 71.6 | 72.5 | 61.3 | 58.8 | 71.8 | 61.6 |
| Ming-Omni-TTS-16B | 84.6 | 70.7 | 56.0 | – | – | – |
| Qwen3-TTS-VD | 83.7 | 81.7 | 65.8 | 76.4 | 81.4 | 64.2 |
| FireRedAudio | 86.0 | 84.1 | 70.1 | 81.1 | 83.6 | 70.3 |
- These results are obtained from our own evaluation.
Semantic Editing
Task | Setting | Metric | Ming-UniAudio-Edit zh | en | FireRedAudio zh | en |
|---|---|---|---|---|
| Deletion | basic | WER (%)↓ | 11.89 | 14.85 | 10.82 | 12.78 |
| SIM↑ | 0.78 | 0.76 | 0.78 | 0.79 | ||
| ACC (%)↑ | 100.00 | 82.22 | 100.00 | 97.78 | ||
| no-edit WER (%)↓ | 11.49 | 24.26 | 10.70 | 23.16 | ||
| open | WER (%)↓ | 22.92 | 27.60 | 10.49 | 16.65 | |
| SIM↑ | 0.81 | 0.74 | 0.80 | 0.80 | ||
| ACC (%)↑ | 82.92 | 85.00 | 89.32 | 86.50 | ||
| no-edit WER (%)↓ | 17.50 | 35.21 | 7.84 | 25.43 | ||
| Insertion | basic | WER (%)↓ | 3.42 | 6.63 | 3.28 | 4.98 |
| SIM↑ | 0.83 | 0.79 | 0.83 | 0.84 | ||
| ACC (%)↑ | 80.00 | 71.43 | 83.53 | 87.58 | ||
| no-edit WER (%)↓ | 3.52 | 17.70 | 3.51 | 16.56 | ||
| open | WER (%)↓ | 3.89 | 7.59 | 2.57 | 6.98 | |
| SIM↑ | 0.83 | 0.79 | 0.83 | 0.84 | ||
| ACC (%)↑ | 79.31 | 62.31 | 86.90 | 69.85 | ||
| no-edit WER (%)↓ | 4.10 | 18.84 | 2.77 | 17.83 | ||
| Substitution | basic | WER (%)↓ | 4.52 | 8.99 | 2.66 | 4.46 |
| SIM↑ | 0.82 | 0.78 | 0.84 | 0.81 | ||
| ACC (%)↑ | 78.62 | 59.78 | 87.42 | 75.98 | ||
| no-edit WER (%)↓ | 4.63 | 19.28 | 2.91 | 16.34 | ||
| open | WER (%)↓ | 4.56 | 7.64 | 2.45 | 4.41 | |
| SIM↑ | 0.83 | 0.77 | 0.84 | 0.81 | ||
| ACC (%)↑ | 76.62 | 65.62 | 90.15 | 76.95 | ||
| no-edit WER (%)↓ | 4.75 | 18.39 | 2.71 | 16.16 |
Acoustic Editing
Task | Metric | Ming-UniAudio-Edit zh | en | FireRedAudio zh | en |
|---|---|---|---|
| Speed Alteration | WER (%)↓ | 5.88 | 17.53 | 2.00 | 4.43 |
| SIM↑ | 0.66 | 0.57 | 0.79 | 0.71 | |
| RDE (%)↓ | 6.36 | 5.92 | 2.60 | 4.02 | |
| Pitch Alteration | WER (%)↓ | 7.45 | 13.37 | 2.00 | 3.04 |
| SIM↑ | 0.36 | 0.24 | 0.52 | 0.44 | |
| Volume Alteration | WER (%)↓ | 1.71 | 1.35 | 1.60 | 1.30 |
| SIM↑ | 0.86 | 0.80 | 0.94 | 0.93 | |
| RAE (%)↓ | 14.90 | 11.70 | 2.39 | 3.74 |
Limitations
- Everything but ASR is Chinese/English only. Speech generation (
tts/edit/voice_design) and audio understanding are limited to Chinese and English —ttsselects the language via--language zh/en. ASR is the only task that supports more languages. - Zero-shot TTS is not deterministic by default. The flow-matching decoder samples random noise, so output varies run to run; pass a fixed seed (
set_seed(...)in the API,--seedon the CLI) for reproducibility, and note that quality can differ across seeds. - Long-form input is supported up to about one hour. Beyond that the model is untested and time-to-content alignment may degrade.
Usage Disclaimer
- The project incorporates zero-shot voice cloning functionality; Please note that this capability is intended solely for academic research purposes.
- DO NOT use this model for ANY illegal activities❗️❗️
- The developers assume no liability for any misuse of this model.
- If you identify any instances of abuse, misuse, or fraudulent activities related to this project, please report them to our team immediately.
Citation
@article{fireredaudio,
  title   = {FireRedAudio: A General-Purpose Audio Language Model with Decoupled Continuous Representations for Understanding and Generation},
  author  = {FireRed Team},
  journal = {arXiv preprint},
  year    = {2026},
}
Acknowledgements
- Qwen3.5 for the language model foundation
- Whisper-large-v3 for the Audio Encoder initialization
- x-transformers for RotaryEmbedding
- vocos for ISTFT implementation
License
Released under the Apache-2.0 license.
Similar repos
Linked in READMEs
Contributors
7 commits