**You can download the zip dataset directly, and both *train* and *test* subsets are collected in Multi-modal-Self-instruct.zip.**
34
55 commits
2 linked in READMEs
updated Jan 27, 2025
README


You can download the zip dataset directly, and both train and test subsets are collected in Multi-modal-Self-instruct.zip.
Dataset Description
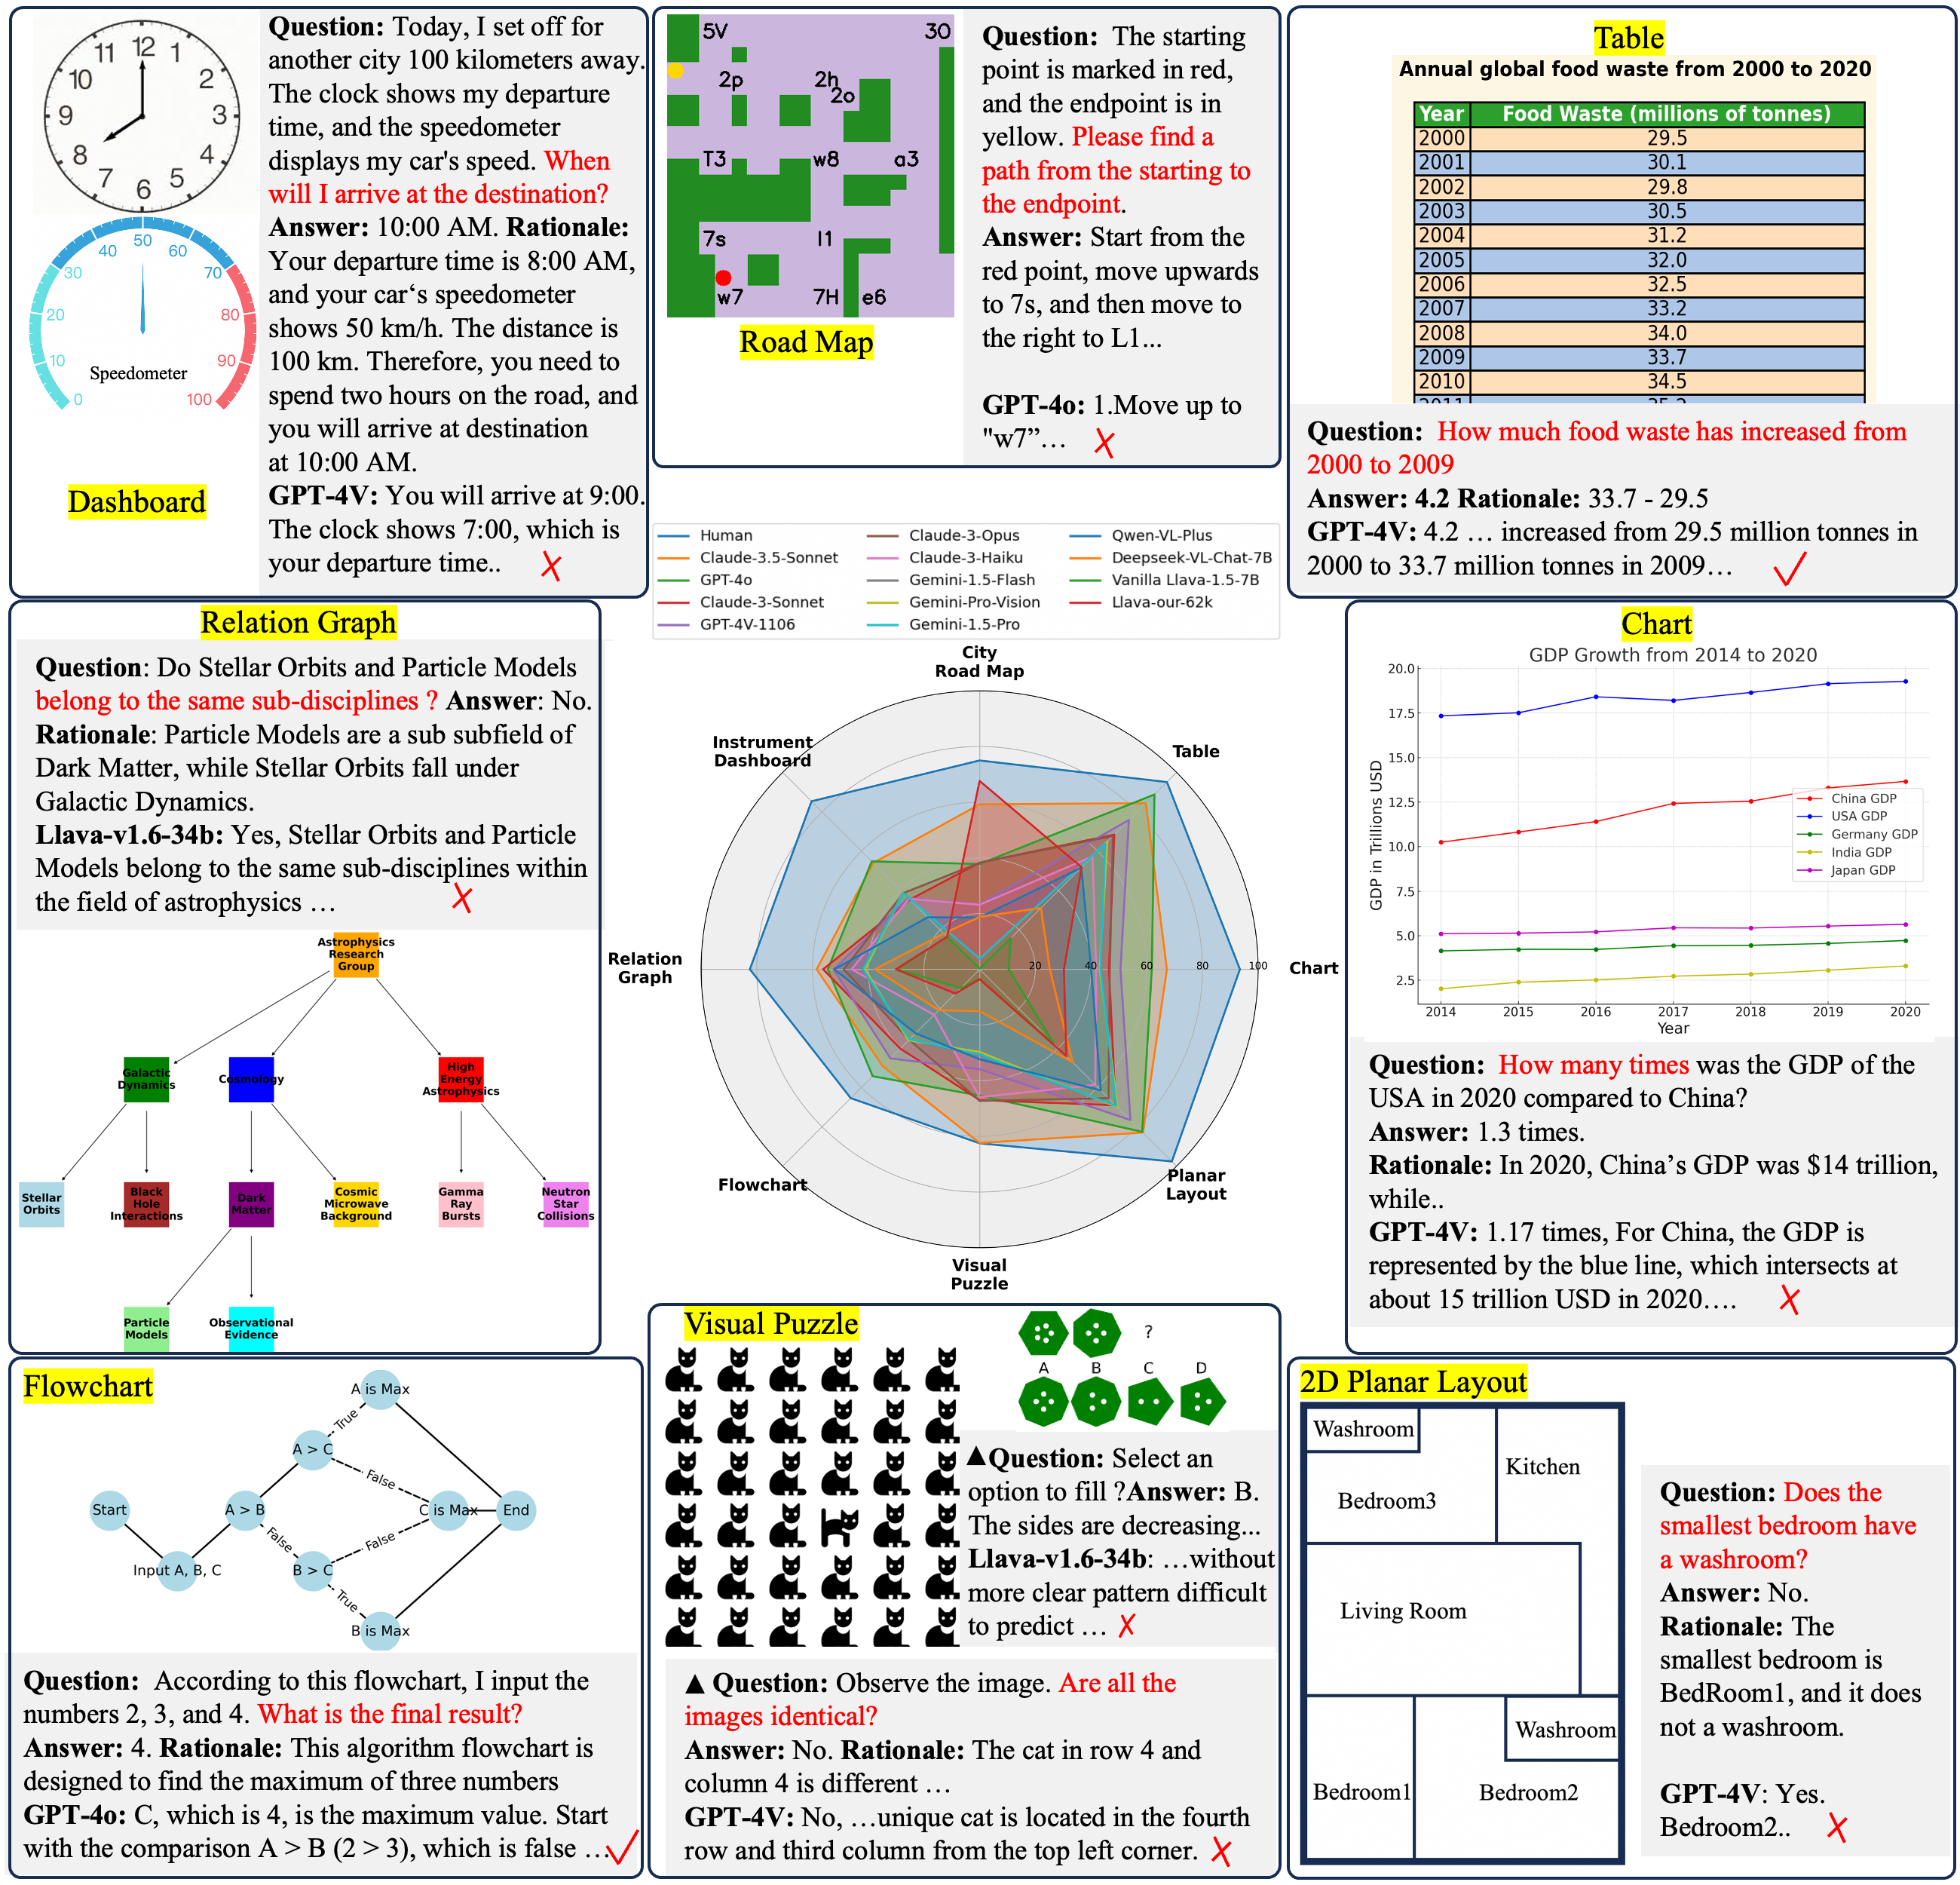
Multi-Modal Self-Instruct dataset utilizes large language models and their code capabilities to synthesize massive abstract images and visual reasoning instructions across daily scenarios. This benchmark contains eight visual scenarios with 11,193 instructions: charts, tables, simulated maps, dashboards, flowcharts, relation graphs, floor plans, and visual puzzles. Besides, we also use 64,796 synthetic chart, table and road map instructions to fine-tune an LMM. The results demonstrate improved chart understanding and map navigation performance, and also demonstrate potential benefits for other visual reasoning tasks.
| Task | #Image | # Instruction | #Usage |
|---|---|---|---|
| Chart | 1,768 | 34,590 | Train Set |
| Table | 570 | 10,886 | Train Set |
| Road map | 17,000 | 17,000 | Train Set |
| All | 19,338 | 64,796 | Train Set |
| ----- | -------- | ------- | ------- |
| Chart | 149 | 3,018 | Benchmark |
| Table | 58 | 1,108 | Benchmark |
| Road map | 3,000 | 3,000 | Benchmark |
| Dashboard | 73 | 1,013 | Benchmark |
| Relation Graph | 66 | 822 | Benchmark |
| Flowchart | 98 | 1,451 | Benchmark |
| Visual Puzzle | 189 | 529 | Benchmark |
| Planar Layout | 25 | 252 | Benchmark |
| All | 3,658 | 11,193 | Benchmark |
Paper Information
- Paper: https://arxiv.org/abs/2407.07053
- Code: https://github.com/zwq2018/Multi-modal-Self-instruct
- Project: https://multi-modal-self-instruct.github.io/
- Leaderboard: https://multi-modal-self-instruct.github.io/#leaderboard
Dataset Examples
Examples of our annotated datasets: Charts, Tables, Simulated Maps, Dashboards, Flowcharts, Relation Graphs, Floor Plans, Visual Puzzles:
🔍 Click to expand/collapse more examples
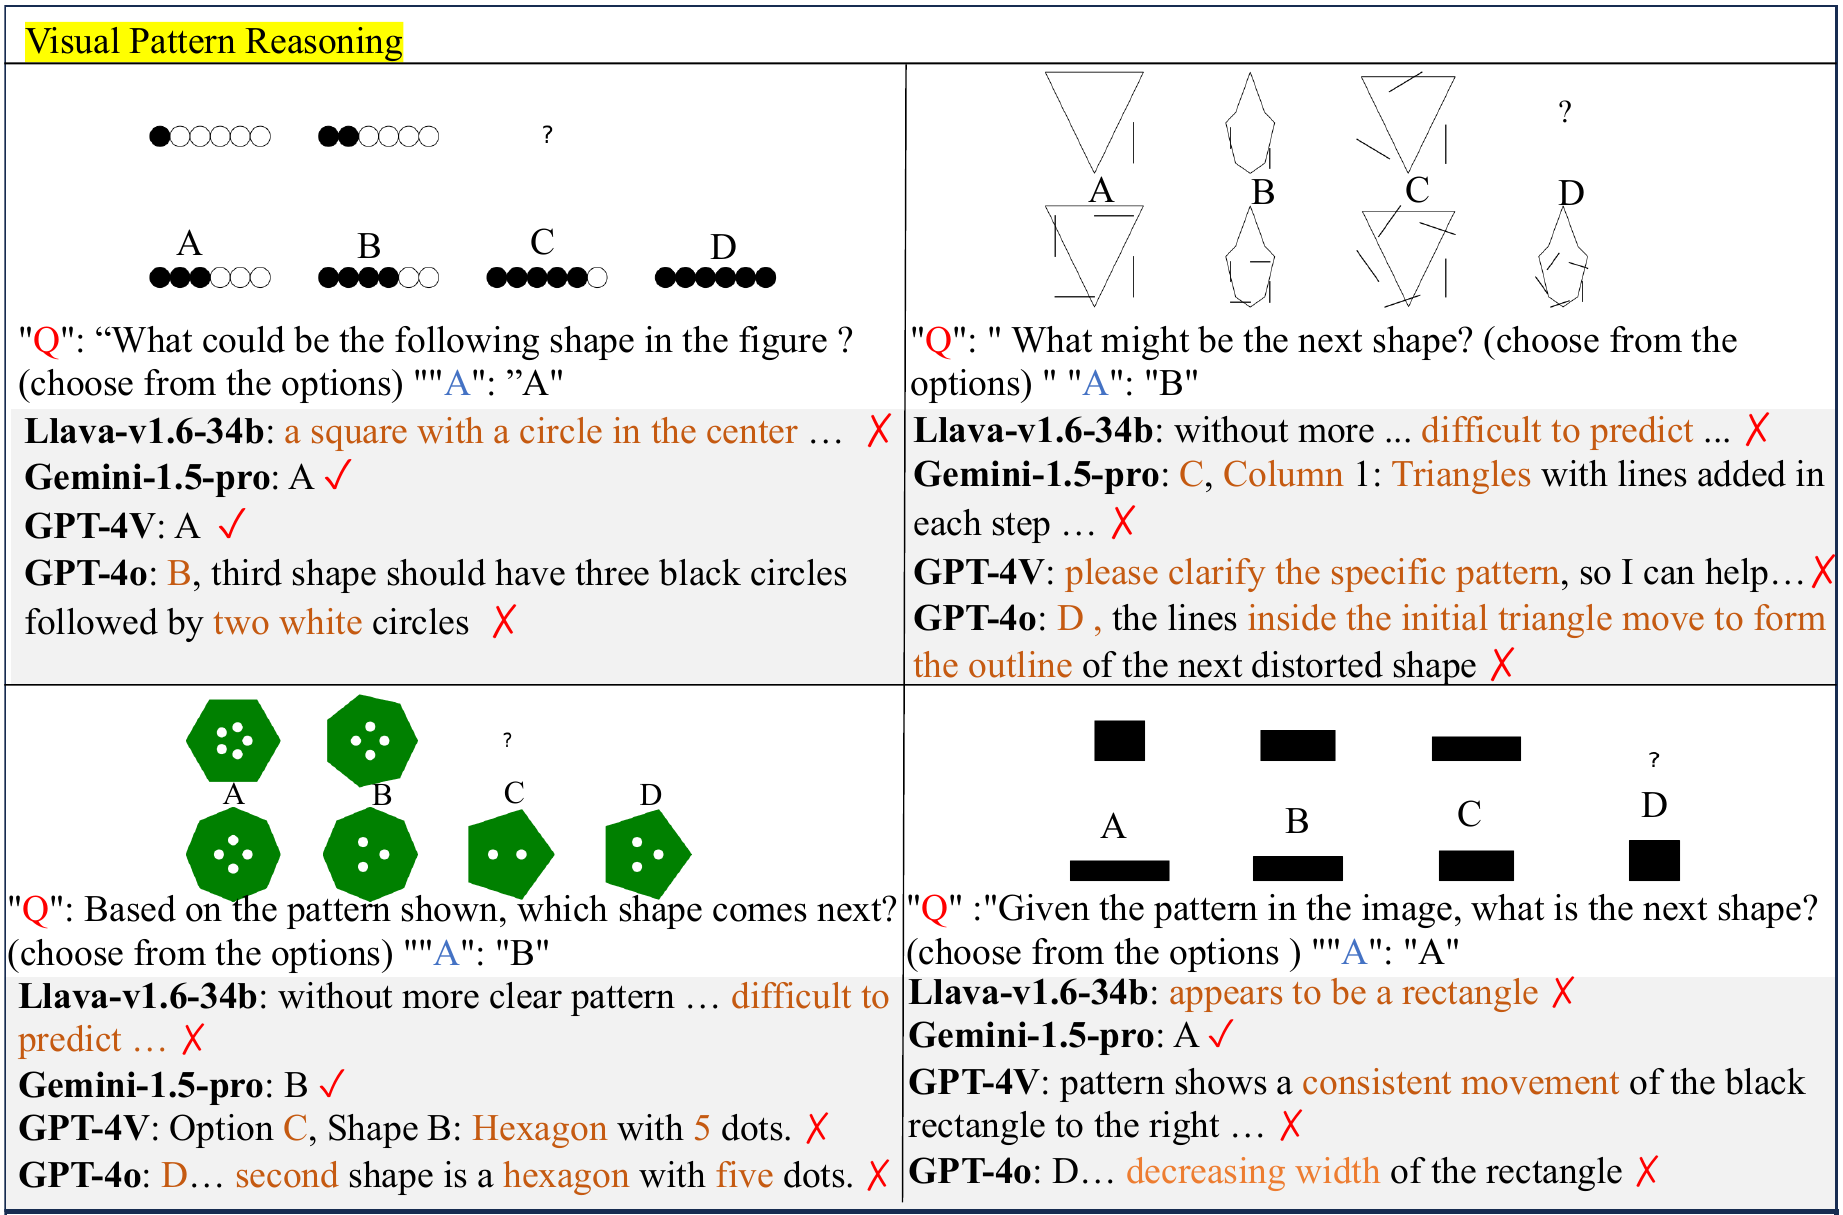
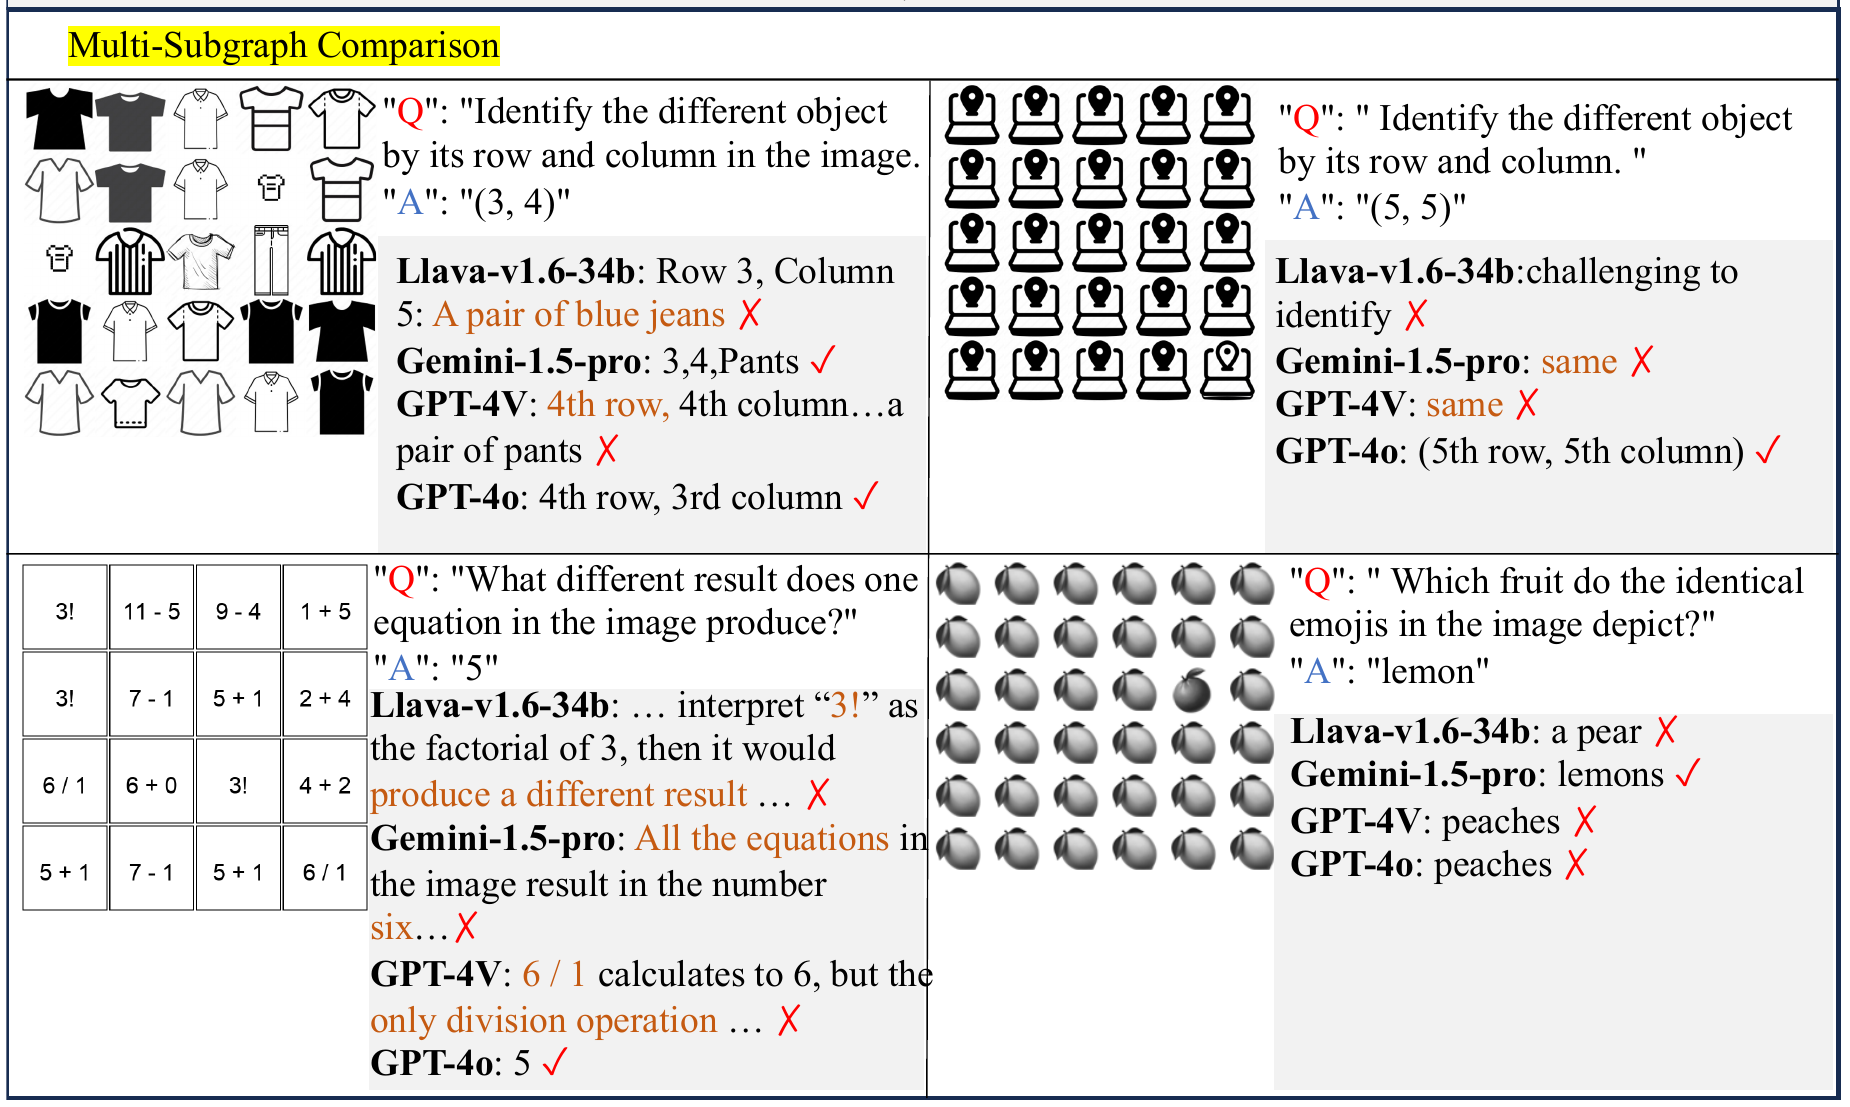
Examples of seven mathematical reasoning skills:
- Visual Pattern Reasoning
- Multi-Subgraph Comparison
- Planar Layout Reasoning
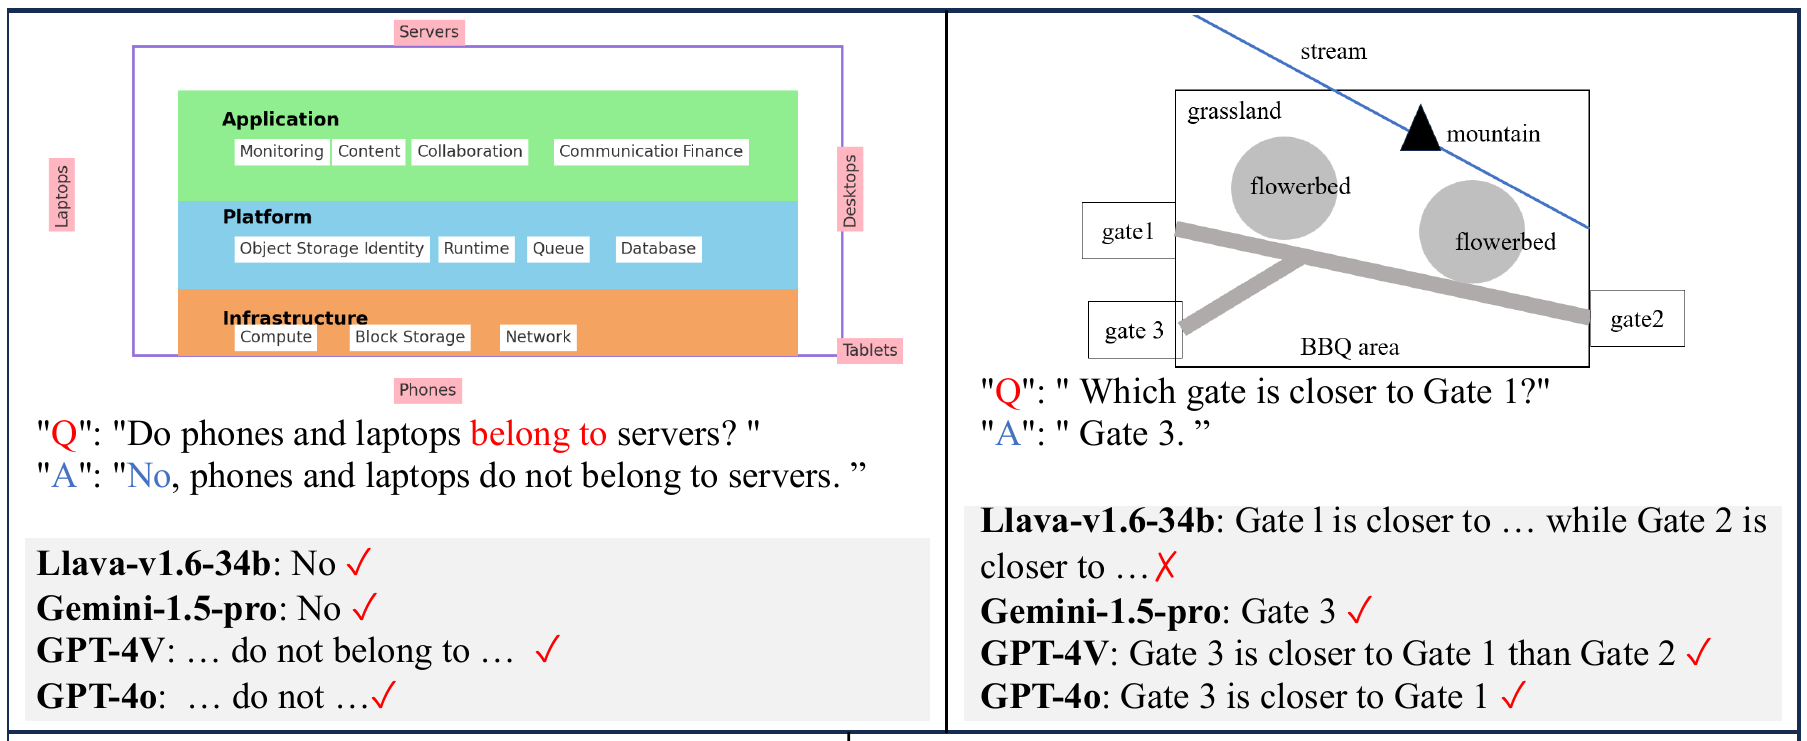
- Website Structure Reasoning
Leaderboard
🏆 The leaderboard for the abstract image benchmark (11,193 examples) is available here.
Dataset Usage
Data Downloading
All the data examples were divided into two subsets: train and test.
- train: 64,796 synthetic chart, table and road map instructions.
- test: 11,193 instructions for eight visual scenarios: charts, tables, simulated maps, dashboards, flowcharts, relation graphs, floor plans, and visual puzzles.
You can download the zip dataset directly, and both train and test subsets are collected in Multi-modal-Self-instruct.zip.
You can also download this dataset by the following command (make sure that you have installed Huggingface Datasets):
from datasets import load_dataset

dataset = load_dataset("zwq2018/Multi-modal-Self-instruct")

dataset.save_to_disk("./data")
Data Format
Conform to LLaVA-1.5 data format.
- Training data format: please refer to LLaVA's instructions.
- Testing data format: please refer to LLaVA's instructions.
{
    "question_id": [string] The question text,
    "image_path": [string] A file path pointing to the associated image,
    "question": [list] The question corresponds to the above image,
    "answer": [string] The correct answer for the problem,
    "image": [image] The corresponding image,
}
Evaluation
In scripts folder, we provide automatic evaluation pipeline to evaluate your models.
-
Run
eval_model.pyto produce evaluation result for a specificy model and a task.You need to fill in
engine = 'xxx',task = 'xxx'andxxx/eval_xxxk.jsonto specify the model and the task.In
llm_tools.py, you need to fill in<Your-Api Key>,url = "xxx"andengine == "xxx".python eval_model.py -
Run
eval_vqa.pyto check the accuracy of a model on a task.Function
evaluator('./xxx.json')will test the accuracy of the model on charts, tables, dashboards, flowcharts, relation graphs, floor plans, and visual puzzles(7 tasks).Function
evaluator_map('./xxx.json')will test the accuracy of the model on simulated maps(1 task).python eval_vqa.py
License
The new contributions to our dataset are distributed under the CC BY-SA 4.0 license, including
The creation of eight testing sets and three training sets The standard formalization of instances for evaluation purposes;
Purpose: The eight benchmarks were primarily designed as a test set. The three training sets can be used as training set. Commercial Use: The eight benchmarks can be used commercially as a test set, but using it as a training set is prohibited. By accessing or using this dataset, you acknowledge and agree to abide by these terms in conjunction with the CC BY-SA 4.0 license.
Citation
@inproceedings{zhang-etal-2024-multimodal,
    title = "Multimodal Self-Instruct: Synthetic Abstract Image and Visual Reasoning Instruction Using Language Model",
    author = "Zhang, Wenqi  and
      Cheng, Zhenglin  and
      He, Yuanyu  and
      Wang, Mengna  and
      Shen, Yongliang  and
      Tan, Zeqi  and
      Hou, Guiyang  and
      He, Mingqian  and
      Ma, Yanna  and
      Lu, Weiming  and
      Zhuang, Yueting",
    booktitle = "Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing",
    year = "2024",
    address = "Miami, Florida, USA",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2024.emnlp-main.1072/",
    pages = "19228--19252"}
Contributors

55 commits
Similar repos





**You can download the zip dataset directly, and both *train* and *test* subsets are collected in Multi-modal-Self-instruct.zip.**
34
55 commits
2 linked in READMEs
updated Jan 27, 2025
README
You can download the zip dataset directly, and both train and test subsets are collected in Multi-modal-Self-instruct.zip.
Dataset Description
Multi-Modal Self-Instruct dataset utilizes large language models and their code capabilities to synthesize massive abstract images and visual reasoning instructions across daily scenarios. This benchmark contains eight visual scenarios with 11,193 instructions: charts, tables, simulated maps, dashboards, flowcharts, relation graphs, floor plans, and visual puzzles. Besides, we also use 64,796 synthetic chart, table and road map instructions to fine-tune an LMM. The results demonstrate improved chart understanding and map navigation performance, and also demonstrate potential benefits for other visual reasoning tasks.
| Task | #Image | # Instruction | #Usage |
|---|---|---|---|
| Chart | 1,768 | 34,590 | Train Set |
| Table | 570 | 10,886 | Train Set |
| Road map | 17,000 | 17,000 | Train Set |
| All | 19,338 | 64,796 | Train Set |
| ----- | -------- | ------- | ------- |
| Chart | 149 | 3,018 | Benchmark |
| Table | 58 | 1,108 | Benchmark |
| Road map | 3,000 | 3,000 | Benchmark |
| Dashboard | 73 | 1,013 | Benchmark |
| Relation Graph | 66 | 822 | Benchmark |
| Flowchart | 98 | 1,451 | Benchmark |
| Visual Puzzle | 189 | 529 | Benchmark |
| Planar Layout | 25 | 252 | Benchmark |
| All | 3,658 | 11,193 | Benchmark |
Paper Information
- Paper: https://arxiv.org/abs/2407.07053
- Code: https://github.com/zwq2018/Multi-modal-Self-instruct
- Project: https://multi-modal-self-instruct.github.io/
- Leaderboard: https://multi-modal-self-instruct.github.io/#leaderboard
Dataset Examples
Examples of our annotated datasets: Charts, Tables, Simulated Maps, Dashboards, Flowcharts, Relation Graphs, Floor Plans, Visual Puzzles:
🔍 Click to expand/collapse more examples
Examples of seven mathematical reasoning skills:
- Visual Pattern Reasoning
- Multi-Subgraph Comparison
- Planar Layout Reasoning
- Website Structure Reasoning
Leaderboard
🏆 The leaderboard for the abstract image benchmark (11,193 examples) is available here.
Dataset Usage
Data Downloading
All the data examples were divided into two subsets: train and test.
- train: 64,796 synthetic chart, table and road map instructions.
- test: 11,193 instructions for eight visual scenarios: charts, tables, simulated maps, dashboards, flowcharts, relation graphs, floor plans, and visual puzzles.
You can download the zip dataset directly, and both train and test subsets are collected in Multi-modal-Self-instruct.zip.
You can also download this dataset by the following command (make sure that you have installed Huggingface Datasets):
from datasets import load_dataset

dataset = load_dataset("zwq2018/Multi-modal-Self-instruct")

dataset.save_to_disk("./data")
Data Format
Conform to LLaVA-1.5 data format.
- Training data format: please refer to LLaVA's instructions.
- Testing data format: please refer to LLaVA's instructions.
{
    "question_id": [string] The question text,
    "image_path": [string] A file path pointing to the associated image,
    "question": [list] The question corresponds to the above image,
    "answer": [string] The correct answer for the problem,
    "image": [image] The corresponding image,
}
Evaluation
In scripts folder, we provide automatic evaluation pipeline to evaluate your models.
-
Run
eval_model.pyto produce evaluation result for a specificy model and a task.You need to fill in
engine = 'xxx',task = 'xxx'andxxx/eval_xxxk.jsonto specify the model and the task.In
llm_tools.py, you need to fill in<Your-Api Key>,url = "xxx"andengine == "xxx".python eval_model.py -
Run
eval_vqa.pyto check the accuracy of a model on a task.Function
evaluator('./xxx.json')will test the accuracy of the model on charts, tables, dashboards, flowcharts, relation graphs, floor plans, and visual puzzles(7 tasks).Function
evaluator_map('./xxx.json')will test the accuracy of the model on simulated maps(1 task).python eval_vqa.py
License
The new contributions to our dataset are distributed under the CC BY-SA 4.0 license, including
The creation of eight testing sets and three training sets The standard formalization of instances for evaluation purposes;
Purpose: The eight benchmarks were primarily designed as a test set. The three training sets can be used as training set. Commercial Use: The eight benchmarks can be used commercially as a test set, but using it as a training set is prohibited. By accessing or using this dataset, you acknowledge and agree to abide by these terms in conjunction with the CC BY-SA 4.0 license.
Citation
@inproceedings{zhang-etal-2024-multimodal,
    title = "Multimodal Self-Instruct: Synthetic Abstract Image and Visual Reasoning Instruction Using Language Model",
    author = "Zhang, Wenqi  and
      Cheng, Zhenglin  and
      He, Yuanyu  and
      Wang, Mengna  and
      Shen, Yongliang  and
      Tan, Zeqi  and
      Hou, Guiyang  and
      He, Mingqian  and
      Ma, Yanna  and
      Lu, Weiming  and
      Zhuang, Yueting",
    booktitle = "Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing",
    year = "2024",
    address = "Miami, Florida, USA",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2024.emnlp-main.1072/",
    pages = "19228--19252"}
Similar repos
Linked in READMEs
Contributors
55 commits