VANE-Bench: Video Anomaly Evaluation Benchmark for Conversational LMMs
4
11 commits
1 linked in READMEs
updated Mar 28, 2025
README
VANE-Bench: Video Anomaly Evaluation Benchmark for Conversational LMMs
Rohit Bharadwaj*, Hanan Gani*, Muzammal Naseer, Fahad Khan, Salman Khan


*denotes equal contribution
Dataset Overview
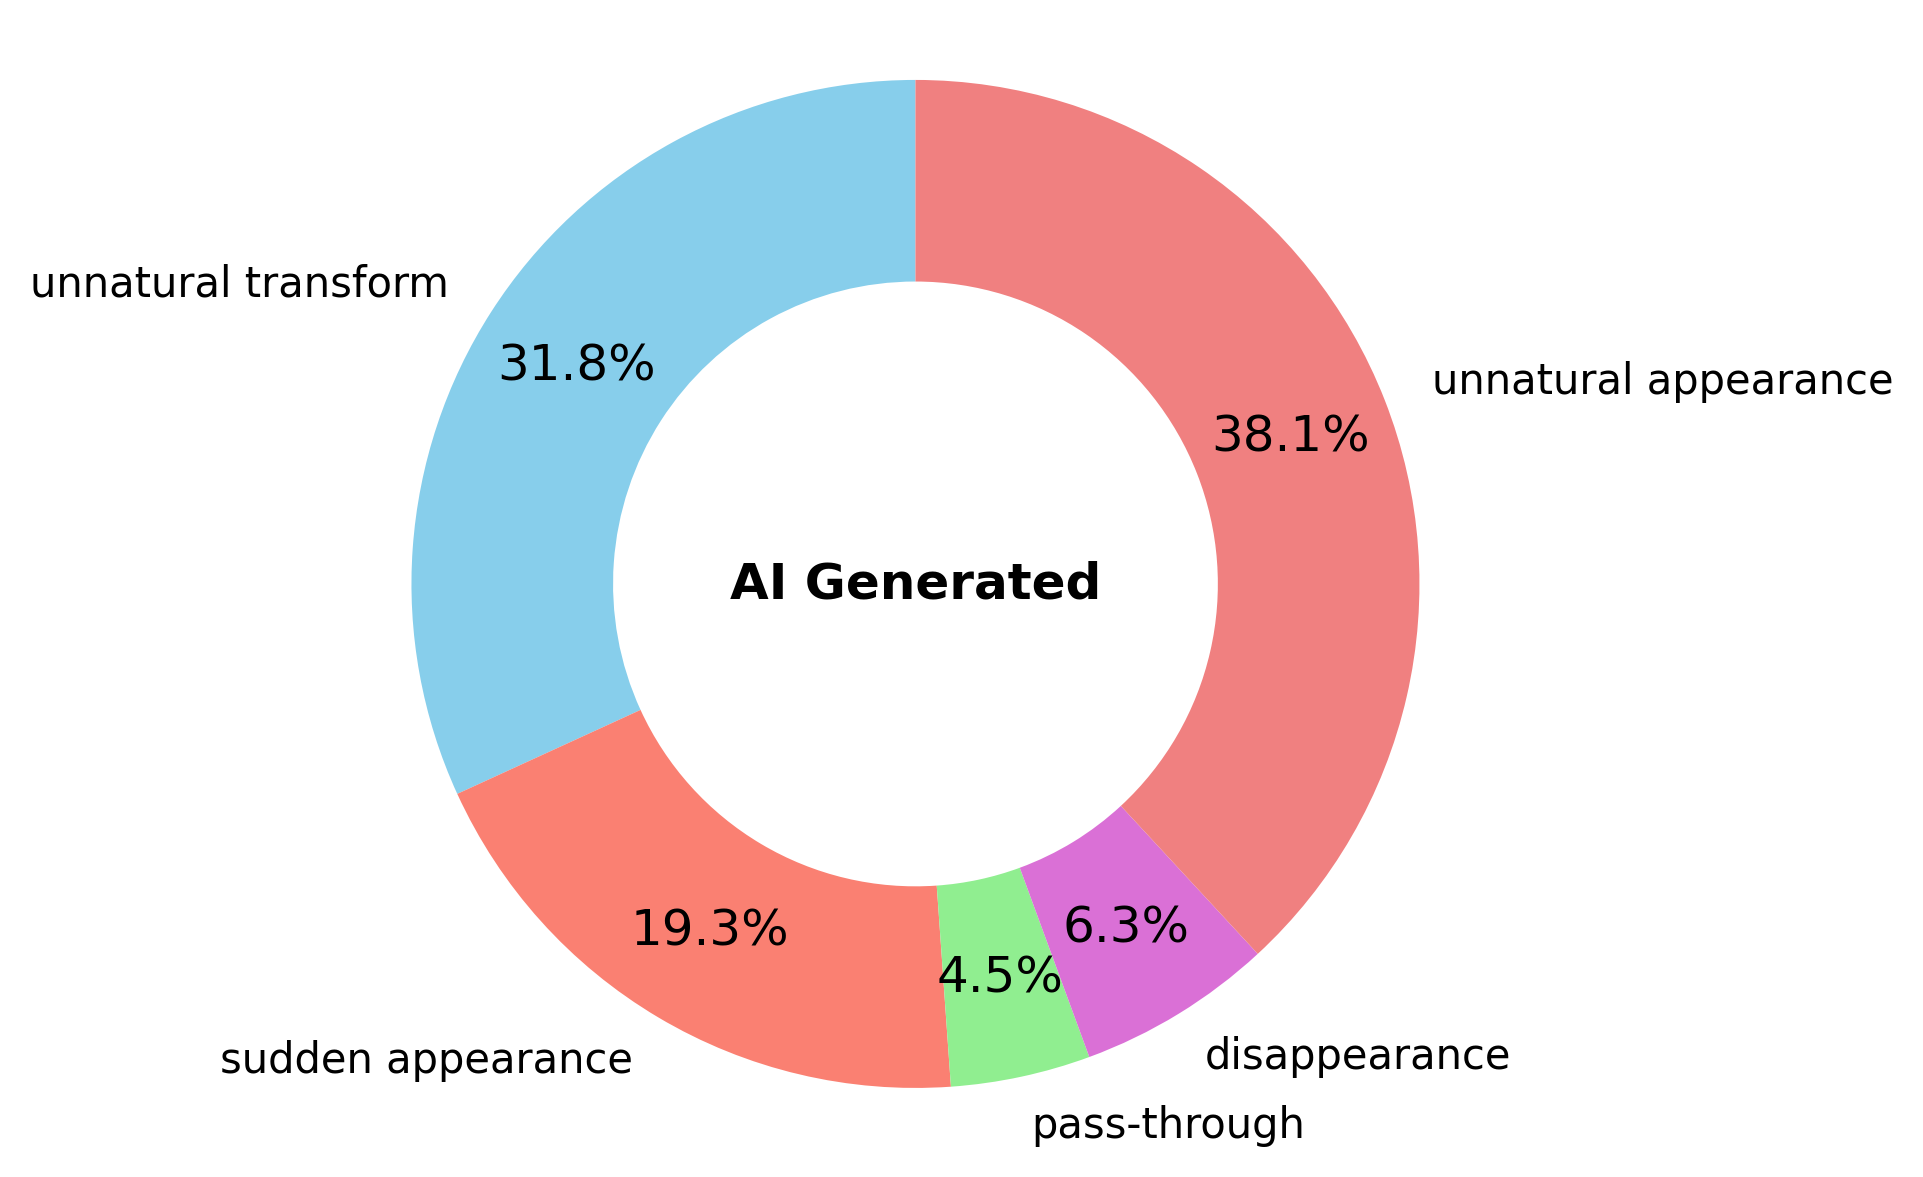
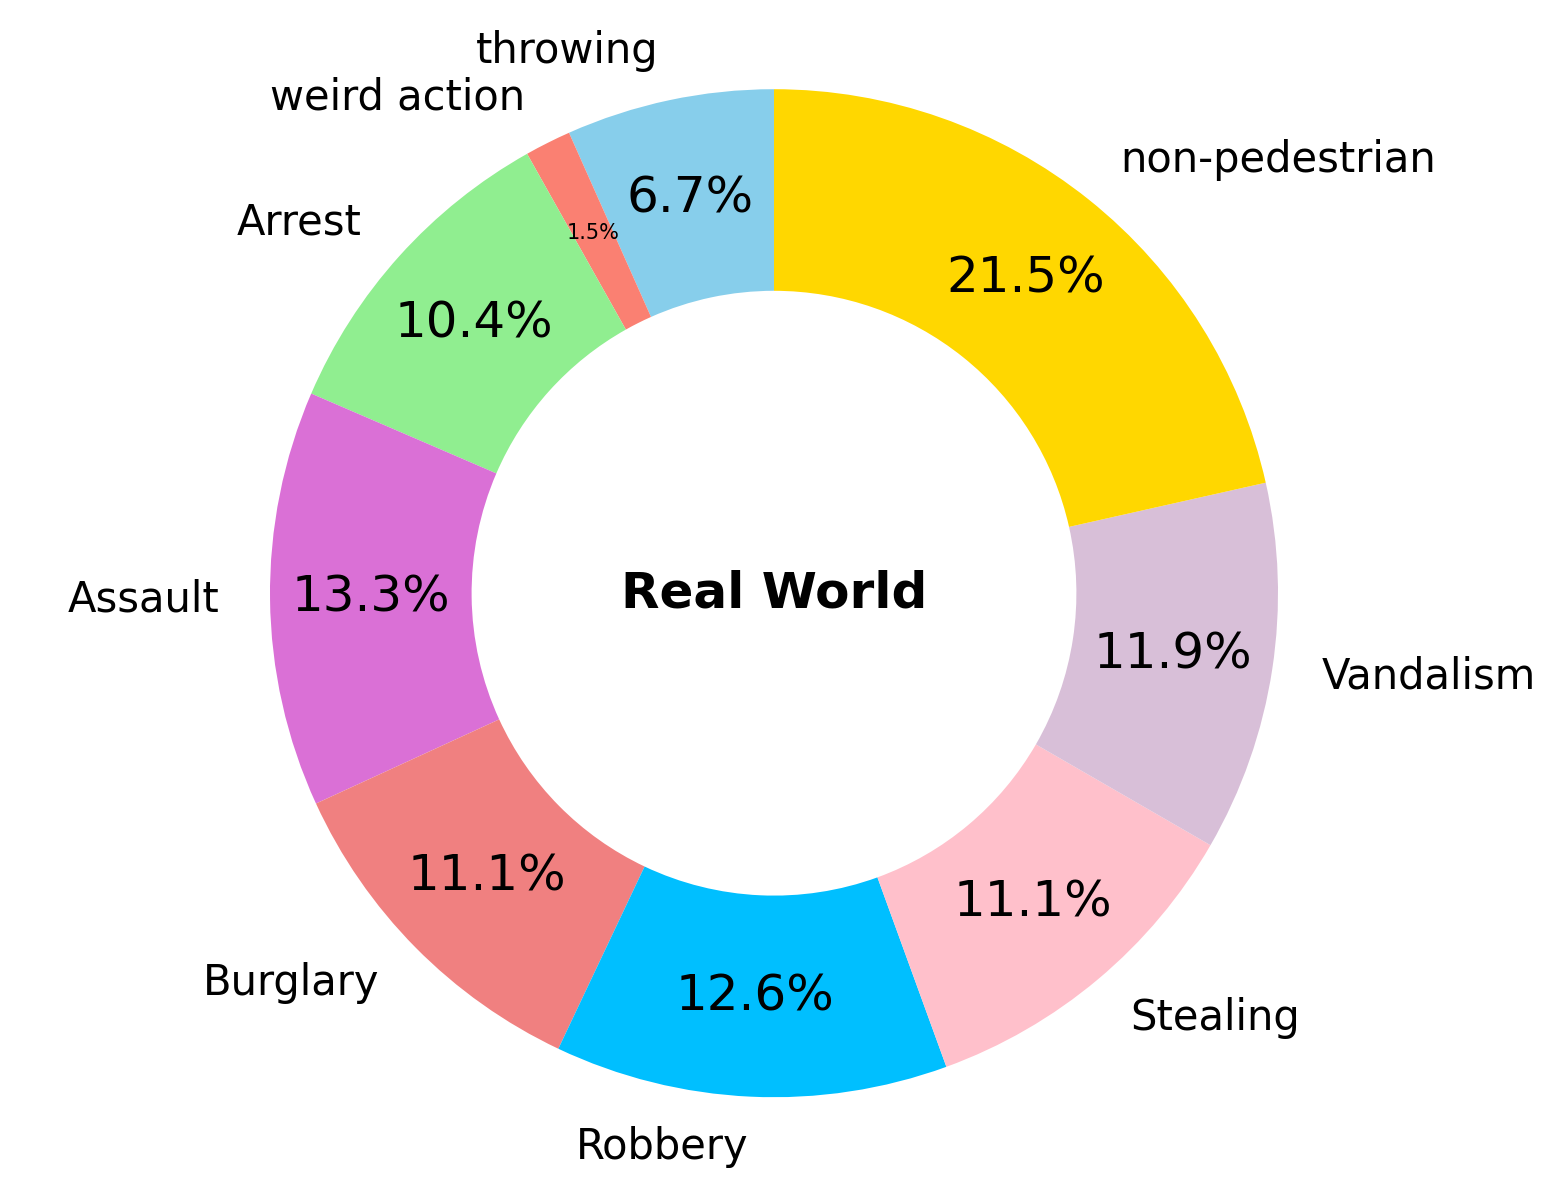
VANE-Bench is a meticulously curated benchmark dataset designed to evaluate the performance of large multimodal models (LMMs) on video anomaly detection and understanding tasks. The dataset includes a diverse set of video clips categorized into AI-Generated and Real-World anomalies, having per-frame information and associated question-answer pairs to facilitate robust evaluation of model capabilities.
Key Features:
- Categories: AI-Generated, Real-World
- Sub-Categories: Avenue, UCFCrime, UCSD-Ped1, UCSD-Ped2, ModelScopeT2V, SORA, OpenSORA, Runway Gen2, VideoLCM
- AI-Generated Anomaly Categories: unnatural transformations, unnatural appearance, pass-through, disappearance, and sudden appearance
- Real World Anomaly Categories: Arrest, Assault, Stealing, Throwing, etc.
- Data: Each video clip contains frame-level data and detailed Q&A pairs to challenge conversational LMMs in understanding and responding to video anomalies in diverse contexts.
Using the Dataset - HuggingFace
You can load the dataset in HuggingFace using the following code snippet:
from datasets import load_dataset

dataset = load_dataset("rohit901/VANE-Bench")
The above HF dataset has the following fields:
- frame_0, frame_1, ..., frame_9: The individual frames of the video (10 consecutive frames of a video).
- category: The main category of the video (AI-Generated, Real-World).
- sub_category: The specific data of anomaly within the main category (i.e. SORA, UCFCrime, Avenue, etc)
- video_folder: The folder containing the video frames.
- question: The question related to the video anomaly.
- answer: The corresponding GT answer to the question.
Using the Dataset - Zip File
You can directly download the zip file from this repository.
The zip file has the below file structure:
VQA_Data/
|–– Real World/
|   |–– UCFCrime
|   |   |–– Arrest002
|   |   |–– Arrest002_qa.txt
|   |   |–– ... # remaining video-qa pairs
|   |–– UCSD-Ped1
|   |   |–– Test_004
|   |   |–– Test_004_qa.txt
|   |   |–– ... # remaining video-qa pairs
... # remaining real-world anomaly dataset folders
|–– AI-Generated/
|   |–– SORA
|   |   |–– video_1_subset_2
|   |   |–– video_1_subset_2_qa.txt
|   |   |–– ... # remaining video-qa pairs
|   |–– opensora
|   |   |–– 1
|   |   |–– 1_qa.txt
|   |   |–– ... # remaining video-qa pairs
... # remaining AI-generated anomaly dataset folders
Results on VANE-Bench
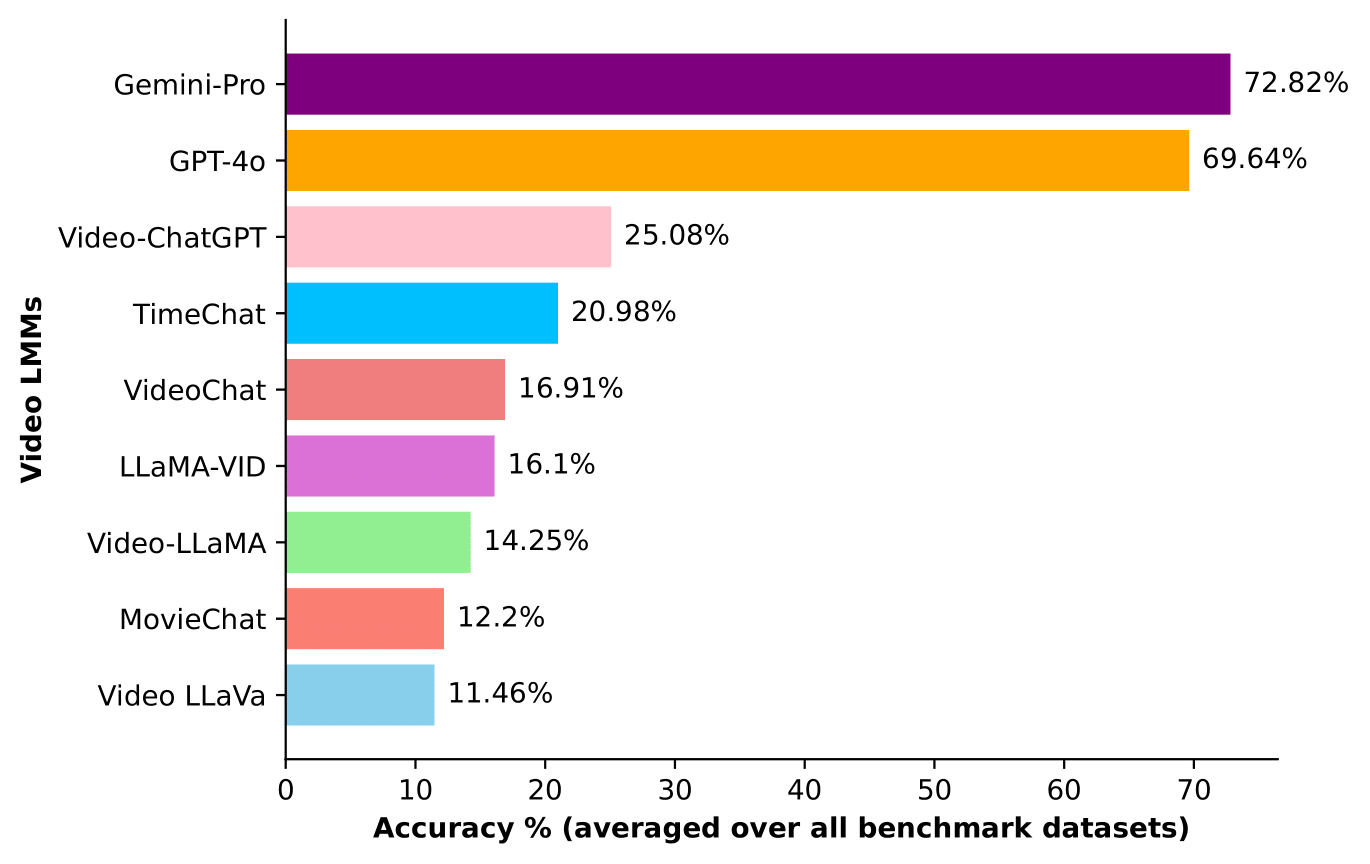 Overall performance of Video-LMMs averaged across all the benchmark datasets.
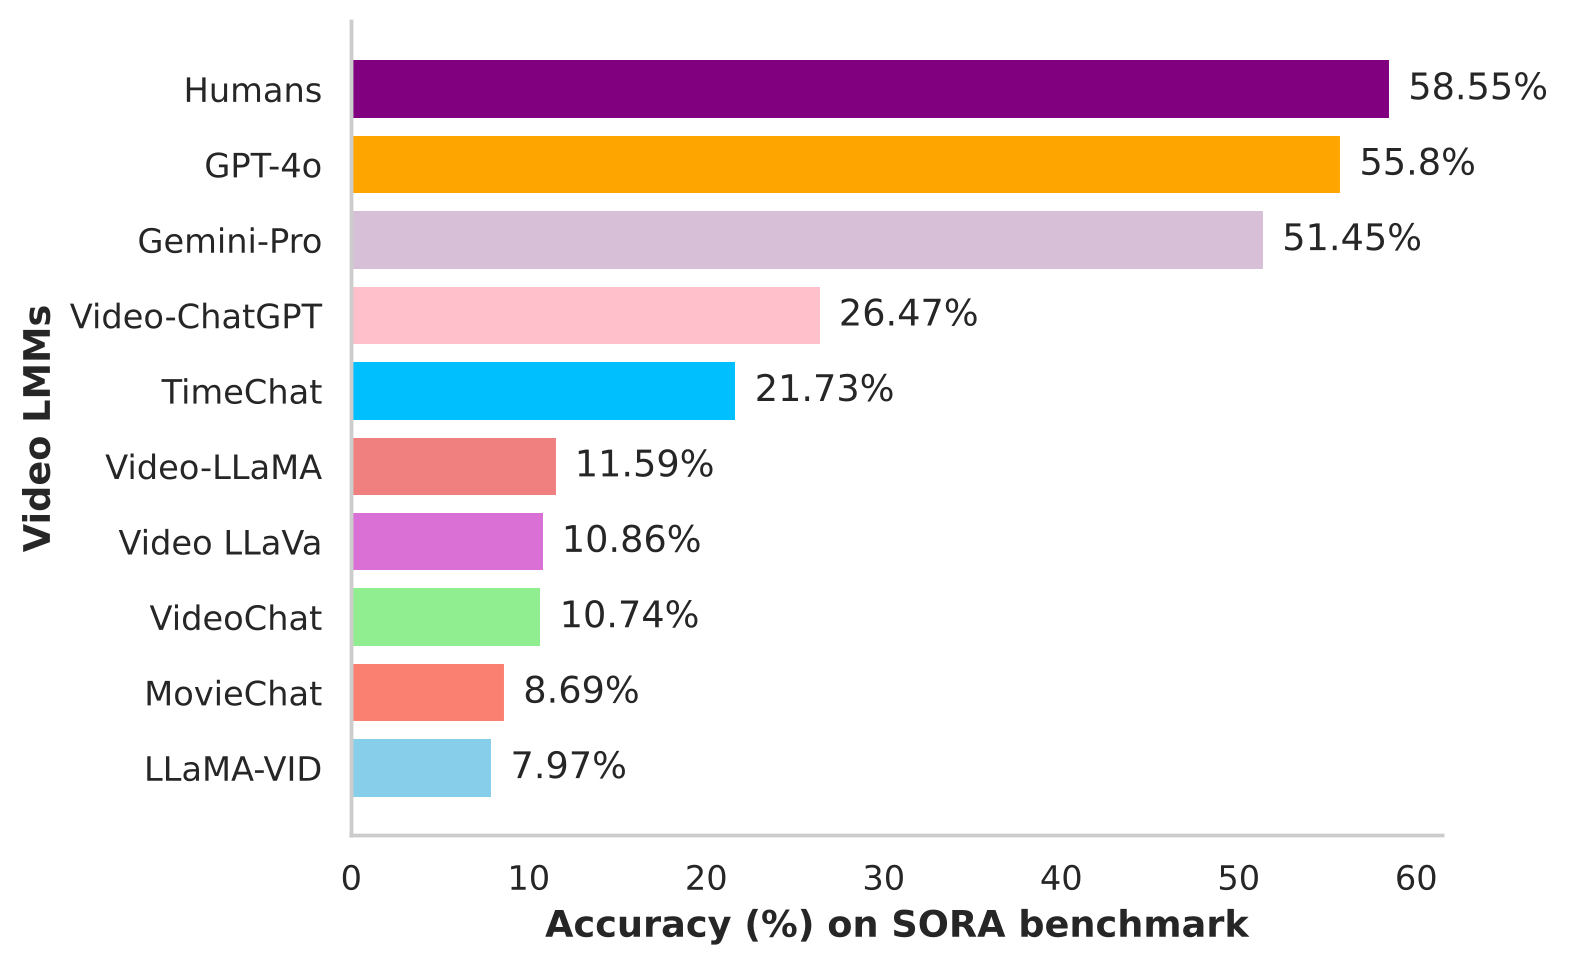 Human vs Video-LMMs' performance on only SORA data.
License
The dataset is licensed under the Creative Commons Attribution Non Commercial Share Alike 4.0 License.
Contact
For any questions or issues, please reach out to the dataset maintainers: rohit.bharadwaj@mbzuai.ac.ae or hanan.ghani@mbzuai.ac.ae
Citation
@misc{bharadwaj2024vanebench,
      title={VANE-Bench: Video Anomaly Evaluation Benchmark for Conversational LMMs},
      author={Rohit Bharadwaj and Hanan Gani and Muzammal Naseer and Fahad Shahbaz Khan and Salman Khan},
      year={2024},
      eprint={2406.10326},
      archivePrefix={arXiv},
      primaryClass={id='cs.CV' full_name='Computer Vision and Pattern Recognition' is_active=True alt_name=None in_archive='cs' is_general=False description='Covers image processing, computer vision, pattern recognition, and scene understanding. Roughly includes material in ACM Subject Classes I.2.10, I.4, and I.5.'}
}
Similar repos





VANE-Bench: Video Anomaly Evaluation Benchmark for Conversational LMMs
4
11 commits
1 linked in READMEs
updated Mar 28, 2025
README
VANE-Bench: Video Anomaly Evaluation Benchmark for Conversational LMMs
Rohit Bharadwaj*, Hanan Gani*, Muzammal Naseer, Fahad Khan, Salman Khan
*denotes equal contribution
Dataset Overview
VANE-Bench is a meticulously curated benchmark dataset designed to evaluate the performance of large multimodal models (LMMs) on video anomaly detection and understanding tasks. The dataset includes a diverse set of video clips categorized into AI-Generated and Real-World anomalies, having per-frame information and associated question-answer pairs to facilitate robust evaluation of model capabilities.
Key Features:
- Categories: AI-Generated, Real-World
- Sub-Categories: Avenue, UCFCrime, UCSD-Ped1, UCSD-Ped2, ModelScopeT2V, SORA, OpenSORA, Runway Gen2, VideoLCM
- AI-Generated Anomaly Categories: unnatural transformations, unnatural appearance, pass-through, disappearance, and sudden appearance
- Real World Anomaly Categories: Arrest, Assault, Stealing, Throwing, etc.
- Data: Each video clip contains frame-level data and detailed Q&A pairs to challenge conversational LMMs in understanding and responding to video anomalies in diverse contexts.
Using the Dataset - HuggingFace
You can load the dataset in HuggingFace using the following code snippet:
from datasets import load_dataset

dataset = load_dataset("rohit901/VANE-Bench")
The above HF dataset has the following fields:
- frame_0, frame_1, ..., frame_9: The individual frames of the video (10 consecutive frames of a video).
- category: The main category of the video (AI-Generated, Real-World).
- sub_category: The specific data of anomaly within the main category (i.e. SORA, UCFCrime, Avenue, etc)
- video_folder: The folder containing the video frames.
- question: The question related to the video anomaly.
- answer: The corresponding GT answer to the question.
Using the Dataset - Zip File
You can directly download the zip file from this repository.
The zip file has the below file structure:
VQA_Data/
|–– Real World/
|   |–– UCFCrime
|   |   |–– Arrest002
|   |   |–– Arrest002_qa.txt
|   |   |–– ... # remaining video-qa pairs
|   |–– UCSD-Ped1
|   |   |–– Test_004
|   |   |–– Test_004_qa.txt
|   |   |–– ... # remaining video-qa pairs
... # remaining real-world anomaly dataset folders
|–– AI-Generated/
|   |–– SORA
|   |   |–– video_1_subset_2
|   |   |–– video_1_subset_2_qa.txt
|   |   |–– ... # remaining video-qa pairs
|   |–– opensora
|   |   |–– 1
|   |   |–– 1_qa.txt
|   |   |–– ... # remaining video-qa pairs
... # remaining AI-generated anomaly dataset folders
Results on VANE-Bench
Overall performance of Video-LMMs averaged across all the benchmark datasets.
Human vs Video-LMMs' performance on only SORA data.
License
The dataset is licensed under the Creative Commons Attribution Non Commercial Share Alike 4.0 License.
Contact
For any questions or issues, please reach out to the dataset maintainers: rohit.bharadwaj@mbzuai.ac.ae or hanan.ghani@mbzuai.ac.ae
Citation
@misc{bharadwaj2024vanebench,
      title={VANE-Bench: Video Anomaly Evaluation Benchmark for Conversational LMMs},
      author={Rohit Bharadwaj and Hanan Gani and Muzammal Naseer and Fahad Shahbaz Khan and Salman Khan},
      year={2024},
      eprint={2406.10326},
      archivePrefix={arXiv},
      primaryClass={id='cs.CV' full_name='Computer Vision and Pattern Recognition' is_active=True alt_name=None in_archive='cs' is_general=False description='Covers image processing, computer vision, pattern recognition, and scene understanding. Roughly includes material in ACM Subject Classes I.2.10, I.4, and I.5.'}
}