
Please visit the webpage for all the information about the IIW project, data downloads, visualizations, and much more.
125
33 commits
2 linked in READMEs
updated May 25, 2024
README
ImageInWords: Unlocking Hyper-Detailed Image Descriptions
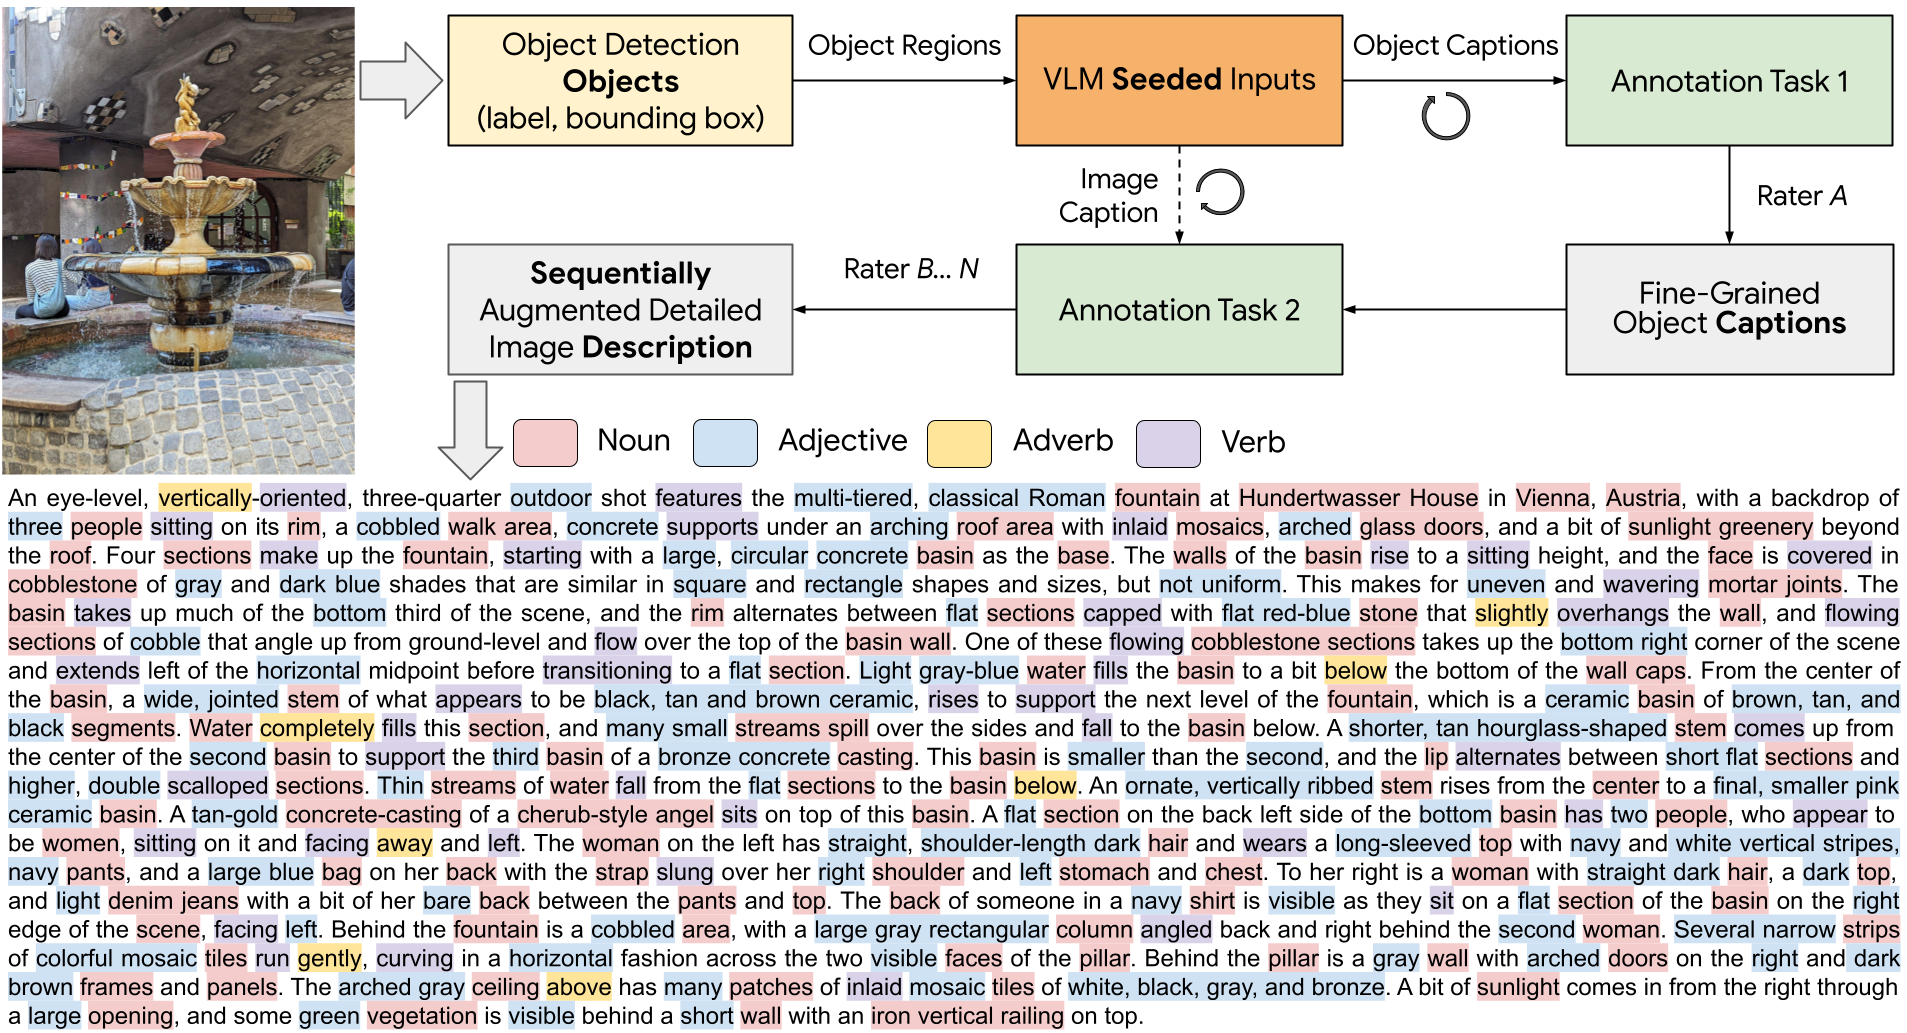
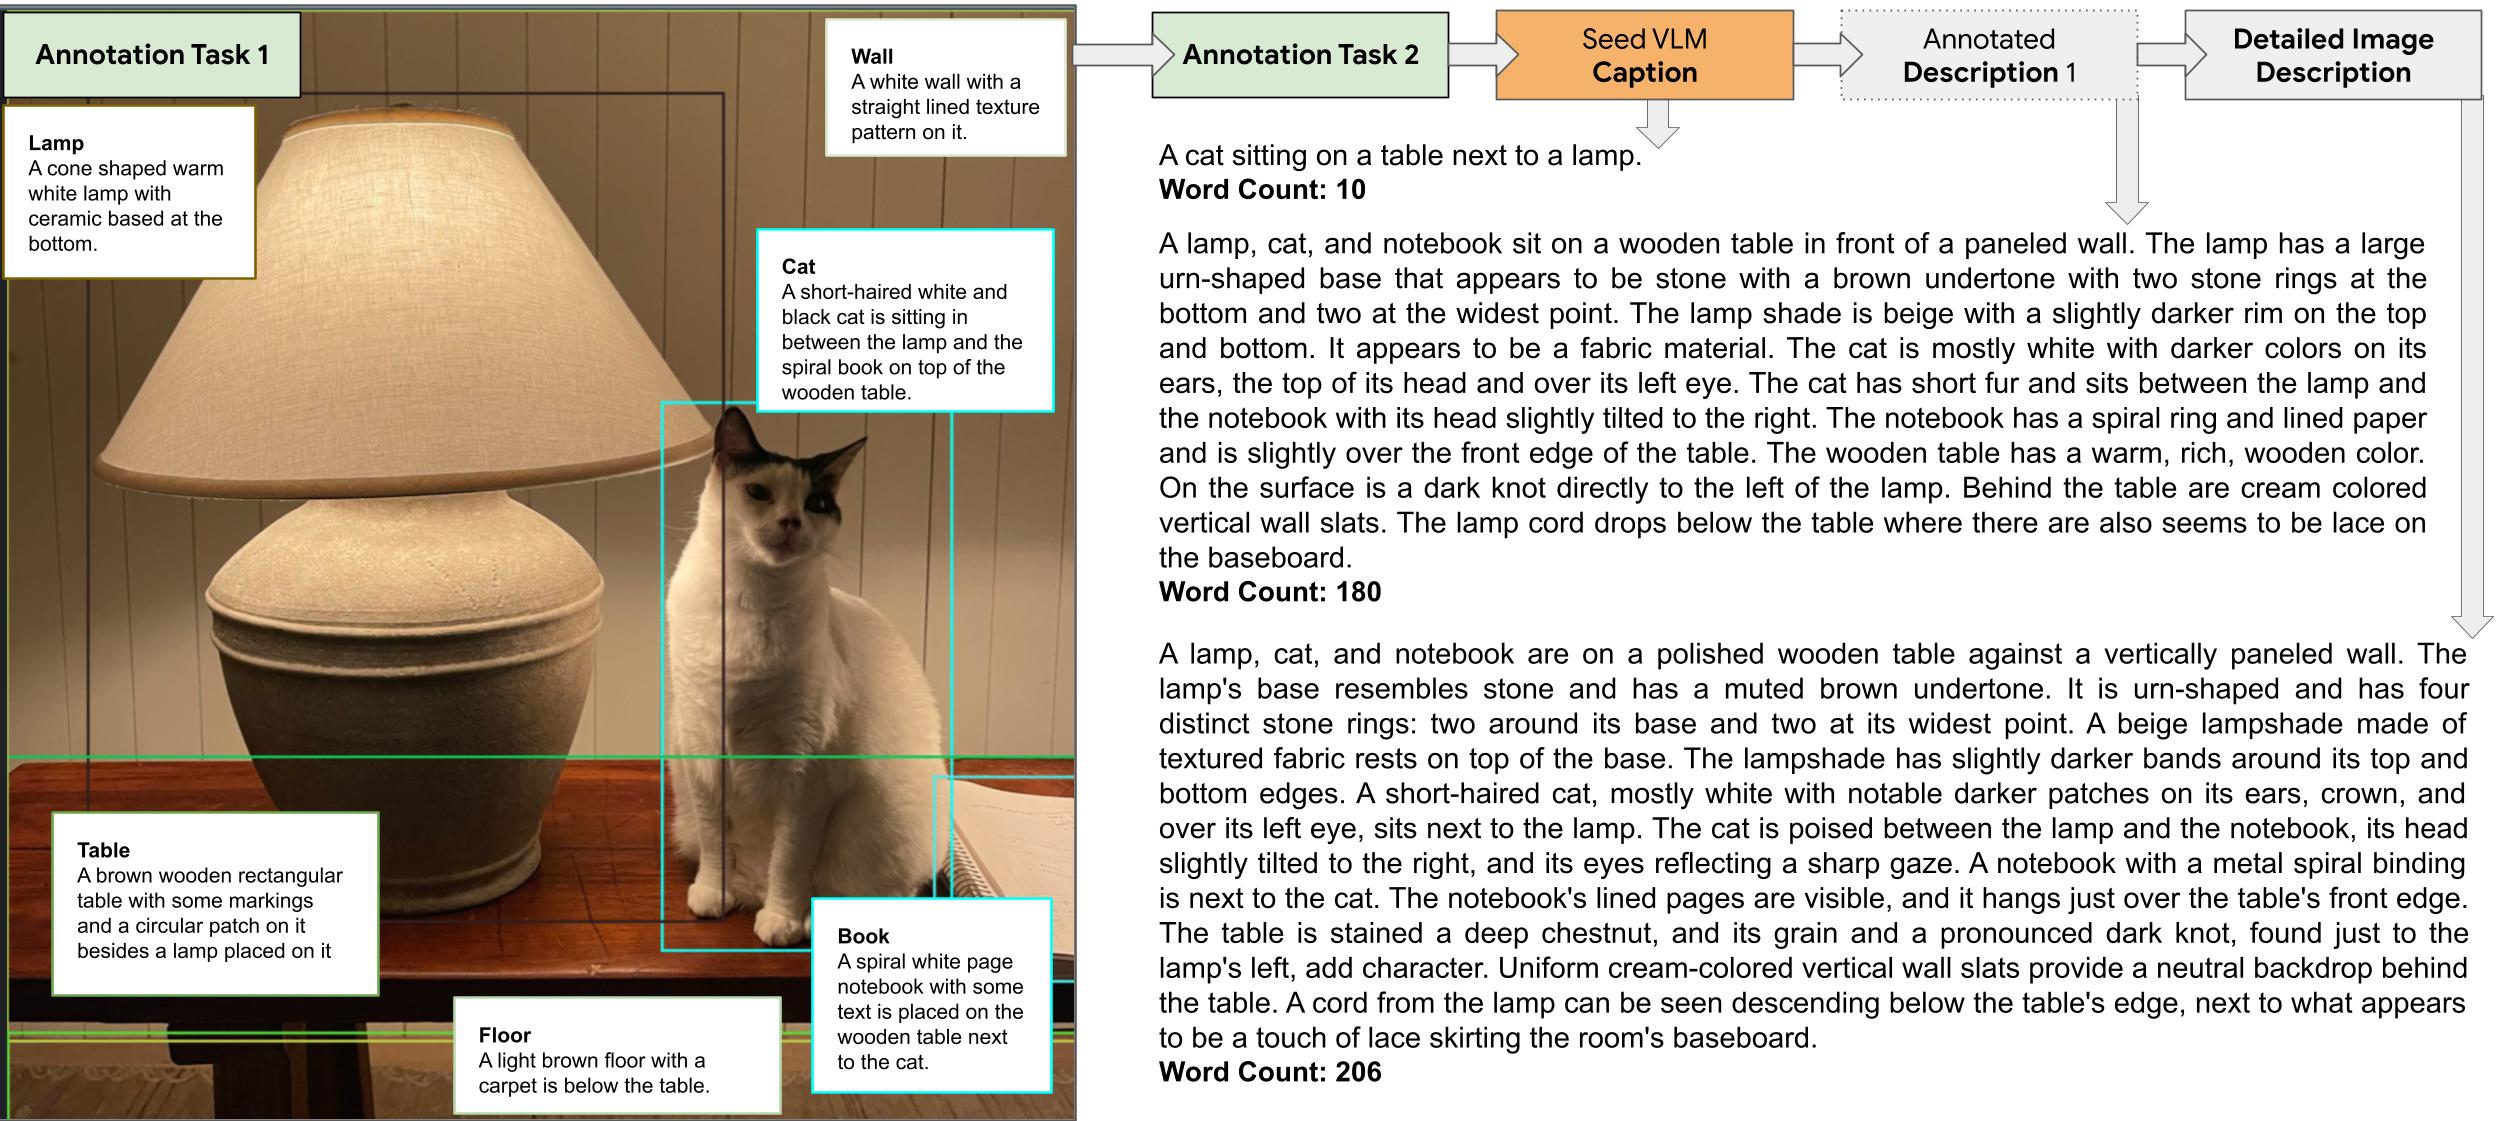
Please visit the webpage for all the information about the IIW project, data downloads, visualizations, and much more.
Please reach out to iiw-dataset@google.com for thoughts/feedback/questions/collaborations.
🤗Hugging Face🤗
from datasets import load_dataset

# `name` can be one of: IIW-400, DCI_Test, DOCCI_Test, CM_3600, LocNar_Eval
# refer: https://github.com/google/imageinwords/tree/main/datasets
dataset = load_dataset('google/imageinwords', token=None, name="IIW-400", trust_remote_code=True)
Dataset Description
- Paper: arXiv
- Homepage: https://google.github.io/imageinwords/
- Point of Contact: iiw-dataset@google.com
- Dataset Explorer: ImageInWords-Explorer
Dataset Summary
ImageInWords (IIW), a carefully designed human-in-the-loop annotation framework for curating hyper-detailed image descriptions and a new dataset resulting from this process. We validate the framework through evaluations focused on the quality of the dataset and its utility for fine-tuning with considerations for readability, comprehensiveness, specificity, hallucinations, and human-likeness.
This Data Card describes IIW-Benchmark: Eval Datasets, a mixture of human annotated and machine generated data intended to help create and capture rich, hyper-detailed image descriptions.
IIW dataset has two parts: human annotations and model outputs. The main purposes of this dataset are:
- to provide samples from SoTA human authored outputs to promote discussion on annotation guidelines to further improve the quality
- to provide human SxS results and model outputs to promote development of automatic metrics to mimic human SxS judgements.
Supported Tasks
Text-to-Image, Image-to-Text, Object Detection
Languages
English
Dataset Structure
Data Instances
Data Fields
For details on the datasets and output keys, please refer to our GitHub data page inside the individual folders.
IIW-400:
image/keyimage/urlIIW: Human generated image descriptionIIW-P5B: Machine generated image descriptioniiw-human-sxs-gpt4vandiiw-human-sxs-iiw-p5b: human SxS metrics- metrics/Comprehensiveness
- metrics/Specificity
- metrics/Hallucination
- metrics/First few line(s) as tldr
- metrics/Human Like
DCI_Test:
imageimage/urlex_idIIW: Human authored image descriptionmetrics/Comprehensivenessmetrics/Specificitymetrics/Hallucinationmetrics/First few line(s) as tldrmetrics/Human Like
DOCCI_Test:
imageimage/thumbnail_urlIIW: Human generated image descriptionDOCCI: Image description from DOCCImetrics/Comprehensivenessmetrics/Specificitymetrics/Hallucinationmetrics/First few line(s) as tldrmetrics/Human Like
LocNar_Eval:
image/keyimage/urlIIW-P5B: Machine generated image description
CM_3600:
image/keyimage/urlIIW-P5B: Machine generated image description
Please note that all fields are string.
Data Splits
| Dataset | Size |
|---|---|
| IIW-400 | 400 |
| DCI_Test | 112 |
| DOCCI_Test | 100 |
| LocNar_Eval | 1000 |
| CM_3600 | 1000 |
Annotations
Annotation process
Some text descriptions were written by human annotators and some were generated by machine models. The metrics are all from human SxS.
Personal and Sensitive Information
The images that were used for the descriptions and the machine generated text descriptions are checked (by algorithmic methods and manual inspection) for S/PII, pornographic content, and violence and any we found may contain such information have been filtered. We asked that human annotators use an objective and respectful language for the image descriptions.
Licensing Information
CC BY 4.0
Citation Information
@misc{garg2024imageinwords,
      title={ImageInWords: Unlocking Hyper-Detailed Image Descriptions},
      author={Roopal Garg and Andrea Burns and Burcu Karagol Ayan and Yonatan Bitton and Ceslee Montgomery and Yasumasa Onoe and Andrew Bunner and Ranjay Krishna and Jason Baldridge and Radu Soricut},
      year={2024},
      eprint={2405.02793},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
Contributors
32 commits

1 commits
Similar repos





Please visit the webpage for all the information about the IIW project, data downloads, visualizations, and much more.
125
33 commits
2 linked in READMEs
updated May 25, 2024
README
ImageInWords: Unlocking Hyper-Detailed Image Descriptions
Please visit the webpage for all the information about the IIW project, data downloads, visualizations, and much more.
Please reach out to iiw-dataset@google.com for thoughts/feedback/questions/collaborations.
🤗Hugging Face🤗
from datasets import load_dataset

# `name` can be one of: IIW-400, DCI_Test, DOCCI_Test, CM_3600, LocNar_Eval
# refer: https://github.com/google/imageinwords/tree/main/datasets
dataset = load_dataset('google/imageinwords', token=None, name="IIW-400", trust_remote_code=True)
Dataset Description
- Paper: arXiv
- Homepage: https://google.github.io/imageinwords/
- Point of Contact: iiw-dataset@google.com
- Dataset Explorer: ImageInWords-Explorer
Dataset Summary
ImageInWords (IIW), a carefully designed human-in-the-loop annotation framework for curating hyper-detailed image descriptions and a new dataset resulting from this process. We validate the framework through evaluations focused on the quality of the dataset and its utility for fine-tuning with considerations for readability, comprehensiveness, specificity, hallucinations, and human-likeness.
This Data Card describes IIW-Benchmark: Eval Datasets, a mixture of human annotated and machine generated data intended to help create and capture rich, hyper-detailed image descriptions.
IIW dataset has two parts: human annotations and model outputs. The main purposes of this dataset are:
- to provide samples from SoTA human authored outputs to promote discussion on annotation guidelines to further improve the quality
- to provide human SxS results and model outputs to promote development of automatic metrics to mimic human SxS judgements.
Supported Tasks
Text-to-Image, Image-to-Text, Object Detection
Languages
English
Dataset Structure
Data Instances
Data Fields
For details on the datasets and output keys, please refer to our GitHub data page inside the individual folders.
IIW-400:
image/keyimage/urlIIW: Human generated image descriptionIIW-P5B: Machine generated image descriptioniiw-human-sxs-gpt4vandiiw-human-sxs-iiw-p5b: human SxS metrics- metrics/Comprehensiveness
- metrics/Specificity
- metrics/Hallucination
- metrics/First few line(s) as tldr
- metrics/Human Like
DCI_Test:
imageimage/urlex_idIIW: Human authored image descriptionmetrics/Comprehensivenessmetrics/Specificitymetrics/Hallucinationmetrics/First few line(s) as tldrmetrics/Human Like
DOCCI_Test:
imageimage/thumbnail_urlIIW: Human generated image descriptionDOCCI: Image description from DOCCImetrics/Comprehensivenessmetrics/Specificitymetrics/Hallucinationmetrics/First few line(s) as tldrmetrics/Human Like
LocNar_Eval:
image/keyimage/urlIIW-P5B: Machine generated image description
CM_3600:
image/keyimage/urlIIW-P5B: Machine generated image description
Please note that all fields are string.
Data Splits
| Dataset | Size |
|---|---|
| IIW-400 | 400 |
| DCI_Test | 112 |
| DOCCI_Test | 100 |
| LocNar_Eval | 1000 |
| CM_3600 | 1000 |
Annotations
Annotation process
Some text descriptions were written by human annotators and some were generated by machine models. The metrics are all from human SxS.
Personal and Sensitive Information
The images that were used for the descriptions and the machine generated text descriptions are checked (by algorithmic methods and manual inspection) for S/PII, pornographic content, and violence and any we found may contain such information have been filtered. We asked that human annotators use an objective and respectful language for the image descriptions.
Licensing Information
CC BY 4.0
Citation Information
@misc{garg2024imageinwords,
      title={ImageInWords: Unlocking Hyper-Detailed Image Descriptions},
      author={Roopal Garg and Andrea Burns and Burcu Karagol Ayan and Yonatan Bitton and Ceslee Montgomery and Yasumasa Onoe and Andrew Bunner and Ranjay Krishna and Jason Baldridge and Radu Soricut},
      year={2024},
      eprint={2405.02793},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
Similar repos
Linked in READMEs
Contributors
32 commits
1 commits