I Don't Know Visual Question Answering - IDKVQA dataset - ICCV 25
2
13 commits
1 linked in READMEs
updated Jul 10, 2025
README
I Don't Know Visual Question Answering - IDKVQA dataset - ICCV 25
We introduce IDKVQA, an embodied dataset specifically designed and annotated for visual question answering using the agent’s observations during navigation,
where the answer includes not only Yes and No, but also I don’t know.
Dataset Details
Please see our ICCV 25 accepted paper: Collaborative Instance Object Navigation: Leveraging Uncertainty-Awareness to Minimize Human-Agent Dialogues
For more information, visit our Github repo.
Curated by: Francesco Taioli and Edoardo Zorzi.
Dataset Description
The dataset contains 502 rows and only one split ('val').
Each row is a triple (image, question, answers), where 'image' is the image which 'question' refers to, and 'answers' is a dictionary mapping each possible answer (Yes, No, I don't know) to the number of annotators picking that answer.
DatasetDict({
    val: Dataset({
        features: ['image', 'question', 'answers'],
        num_rows: 502
    })
})
Visualization
from datasets import load_dataset

idkvqa = load_dataset("ftaioli/IDKVQA")

sample_index = 42
split = "val"

row = idkvqa[split][sample_index]
image = row["image"]
question = row["question"]
answers = row["answers"]

print(question), print(answers)
image
You will obtain:
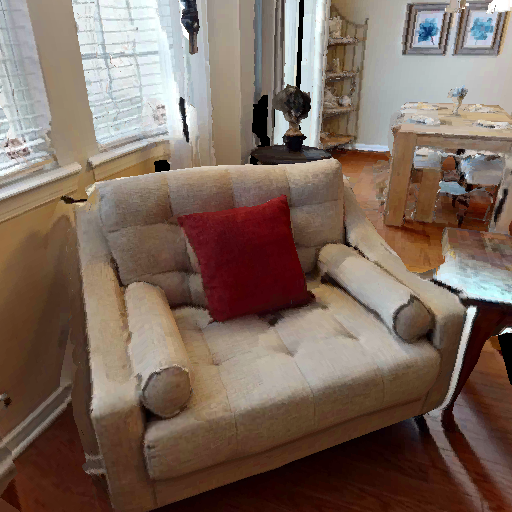
Does the couch have a tufted backrest? You must answer only with Yes, No, or ?=I don't know.
{"I don't know": 0, 'No': 0, 'Yes': 3}
Uses
You can use this dataset to train or test a model's visual-question answering capabilities about everyday objects.
To reproduce the baselines in our paper Collaborative Instance Object Navigation: Leveraging Uncertainty-Awareness to Minimize Human-Agent Dialogues, please check the README in the official repository.
Citation
BibTeX:
@misc{taioli2025collaborativeinstanceobjectnavigation,
      title={Collaborative Instance Object Navigation: Leveraging Uncertainty-Awareness to Minimize Human-Agent Dialogues},
      author={Francesco Taioli and Edoardo Zorzi and Gianni Franchi and Alberto Castellini and Alessandro Farinelli and Marco Cristani and Yiming Wang},
      year={2025},
      eprint={2412.01250},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2412.01250},
}
Similar repos




I Don't Know Visual Question Answering - IDKVQA dataset - ICCV 25
2
13 commits
1 linked in READMEs
updated Jul 10, 2025
README
I Don't Know Visual Question Answering - IDKVQA dataset - ICCV 25
We introduce IDKVQA, an embodied dataset specifically designed and annotated for visual question answering using the agent’s observations during navigation,
where the answer includes not only Yes and No, but also I don’t know.
Dataset Details
Please see our ICCV 25 accepted paper: Collaborative Instance Object Navigation: Leveraging Uncertainty-Awareness to Minimize Human-Agent Dialogues
For more information, visit our Github repo.
Curated by: Francesco Taioli and Edoardo Zorzi.
Dataset Description
The dataset contains 502 rows and only one split ('val').
Each row is a triple (image, question, answers), where 'image' is the image which 'question' refers to, and 'answers' is a dictionary mapping each possible answer (Yes, No, I don't know) to the number of annotators picking that answer.
DatasetDict({
    val: Dataset({
        features: ['image', 'question', 'answers'],
        num_rows: 502
    })
})
Visualization
from datasets import load_dataset

idkvqa = load_dataset("ftaioli/IDKVQA")

sample_index = 42
split = "val"

row = idkvqa[split][sample_index]
image = row["image"]
question = row["question"]
answers = row["answers"]

print(question), print(answers)
image
You will obtain:
Does the couch have a tufted backrest? You must answer only with Yes, No, or ?=I don't know.
{"I don't know": 0, 'No': 0, 'Yes': 3}
Uses
You can use this dataset to train or test a model's visual-question answering capabilities about everyday objects.
To reproduce the baselines in our paper Collaborative Instance Object Navigation: Leveraging Uncertainty-Awareness to Minimize Human-Agent Dialogues, please check the README in the official repository.
Citation
BibTeX:
@misc{taioli2025collaborativeinstanceobjectnavigation,
      title={Collaborative Instance Object Navigation: Leveraging Uncertainty-Awareness to Minimize Human-Agent Dialogues},
      author={Francesco Taioli and Edoardo Zorzi and Gianni Franchi and Alberto Castellini and Alessandro Farinelli and Marco Cristani and Yiming Wang},
      year={2025},
      eprint={2412.01250},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2412.01250},
}