
README
Dataset Card for Tulu V2 Mix
Note the ODC-BY license, indicating that different licenses apply to subsets of the data. This means that some portions of the dataset are non-commercial. We present the mixture as a research artifact.
Tulu is a series of language models that are trained to act as helpful assistants. The dataset consists of a mix of :
- FLAN (Apache 2.0): We use 50,000 examples sampled from FLAN v2. To emphasize CoT-style reasoning, we sample another 50,000 examples from the CoT subset of the FLAN v2 mixture.
- Open Assistant 1 (Apache 2.0): We isolate the highest-scoring paths in each conversation tree and use these samples, resulting in 7,708 examples.
- ShareGPT (Apache 2.0 listed, no official repo found): We use all 114,046 from our processed ShareGPT dataset, as we found ShareGPT gave strong performance in prior work.
- GPT4-Alpaca (CC By NC 4.0):We sample 20,000 samples from GPT-4 Alpaca to further include distilled GPT-4 data.
- Code-Alpaca (CC By NC 4.0):We use all 20,022 examples from Code Alpaca, following our prior V1 mixture, in order to improve model code abilities.
- LIMA (CC BY-NC-SA): We use 1,030 examples from LIMA as an example of carefully curated data.
- WizardLM Evol Instruct (No license provided): We subsample 30,000 examples from WizardLM, which contains distilled data of increasing diversity and complexity.
- Open-Orca (MIT): We sample 30,000 samples generated by GPT-4 from OpenOrca, a reproduction of Orca Mukherjee et al., 2023, which augments FLAN data with additional model-generated explanations
- Hardcoded: A collection of prompts such as `Tell me about yourself' such that the model generates correct outputs given inquiries about its name or developers. We wrote 14 samples and repeat each sample 10 times in the mixture, resulting in 140 total samples.
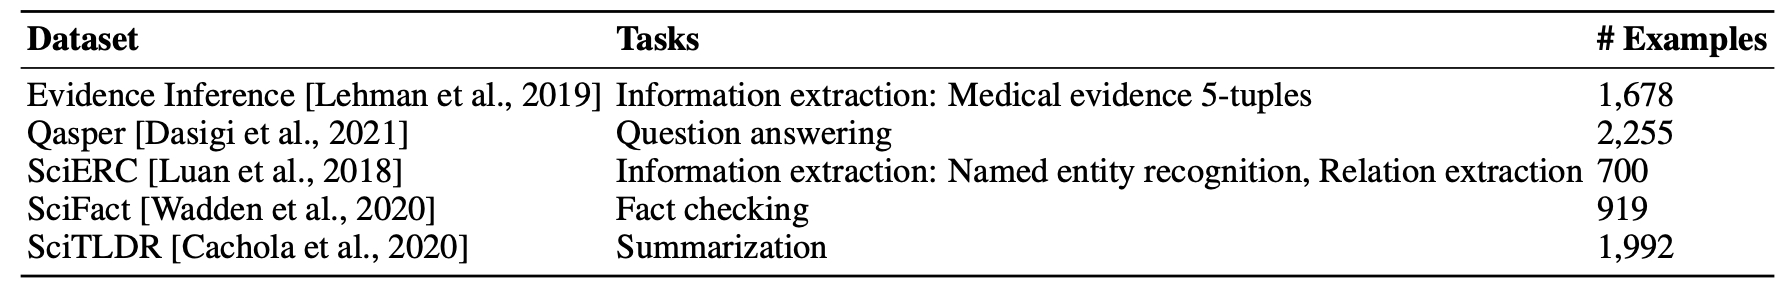
- Science: 7,544 examples from a mixture of scientific document understand tasks—including question answering, fact-checking, summarization, and information extraction (under development, standalone release soon).
These are made by taking either just the training set of the subsets or the entire section if no splits are present. Tulu V2 is presented as a singular training split. Tulu V2 DPO 70B, and is a fine-tuned version of Llama 2 that was trained on on a mix of publicly available, synthetic and human datasets using Direct Preference Optimization (DPO).
Model Family: Other models and the dataset are found in the Tulu V2 collection.
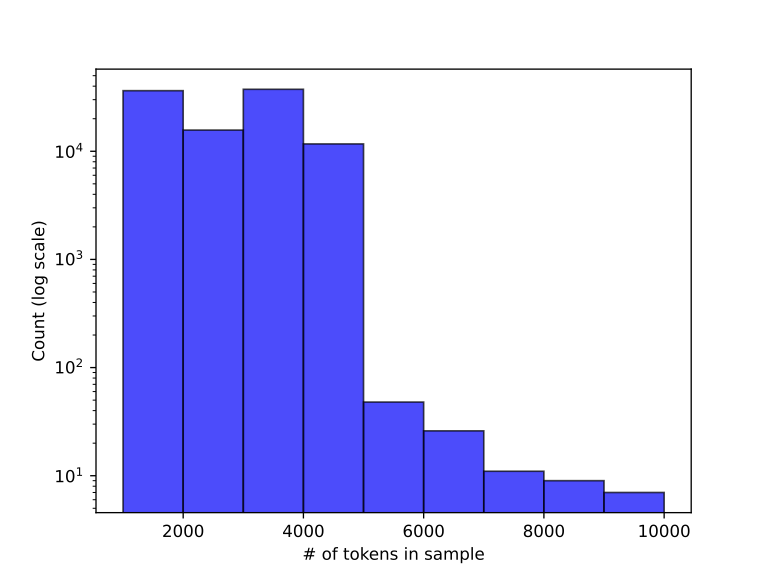
The length distribution of the dataset can be seen below:
Tulu V1 Mix can be found here.
Note: Some samples contain empty turns as noted in this github issue. We will not remove these from this release to ensure reproducibility but you may wish to explicitly filter them out when training your own models!
Science data note
The included science data is from the following categories:
Note that some of the examples include an off-by-one error in the sentence indexing that had a small or negligible impact on performance. This was found during testing and will be updated in future versions, with the detailed release of the dataset artifact itself coming in a future release.
License
We are releasing this dataset under the terms of ODC-BY. By using this, you are also bound by the Common Crawl terms of use in respect of the content contained in the dataset.
Contributors
Similar repos



Linked in READMEs


README
Dataset Card for Tulu V2 Mix
Note the ODC-BY license, indicating that different licenses apply to subsets of the data. This means that some portions of the dataset are non-commercial. We present the mixture as a research artifact.
Tulu is a series of language models that are trained to act as helpful assistants. The dataset consists of a mix of :
- FLAN (Apache 2.0): We use 50,000 examples sampled from FLAN v2. To emphasize CoT-style reasoning, we sample another 50,000 examples from the CoT subset of the FLAN v2 mixture.
- Open Assistant 1 (Apache 2.0): We isolate the highest-scoring paths in each conversation tree and use these samples, resulting in 7,708 examples.
- ShareGPT (Apache 2.0 listed, no official repo found): We use all 114,046 from our processed ShareGPT dataset, as we found ShareGPT gave strong performance in prior work.
- GPT4-Alpaca (CC By NC 4.0):We sample 20,000 samples from GPT-4 Alpaca to further include distilled GPT-4 data.
- Code-Alpaca (CC By NC 4.0):We use all 20,022 examples from Code Alpaca, following our prior V1 mixture, in order to improve model code abilities.
- LIMA (CC BY-NC-SA): We use 1,030 examples from LIMA as an example of carefully curated data.
- WizardLM Evol Instruct (No license provided): We subsample 30,000 examples from WizardLM, which contains distilled data of increasing diversity and complexity.
- Open-Orca (MIT): We sample 30,000 samples generated by GPT-4 from OpenOrca, a reproduction of Orca Mukherjee et al., 2023, which augments FLAN data with additional model-generated explanations
- Hardcoded: A collection of prompts such as `Tell me about yourself' such that the model generates correct outputs given inquiries about its name or developers. We wrote 14 samples and repeat each sample 10 times in the mixture, resulting in 140 total samples.
- Science: 7,544 examples from a mixture of scientific document understand tasks—including question answering, fact-checking, summarization, and information extraction (under development, standalone release soon).
These are made by taking either just the training set of the subsets or the entire section if no splits are present. Tulu V2 is presented as a singular training split. Tulu V2 DPO 70B, and is a fine-tuned version of Llama 2 that was trained on on a mix of publicly available, synthetic and human datasets using Direct Preference Optimization (DPO).
Model Family: Other models and the dataset are found in the Tulu V2 collection.
The length distribution of the dataset can be seen below:
Tulu V1 Mix can be found here.
Note: Some samples contain empty turns as noted in this github issue. We will not remove these from this release to ensure reproducibility but you may wish to explicitly filter them out when training your own models!
Science data note
The included science data is from the following categories:
Note that some of the examples include an off-by-one error in the sentence indexing that had a small or negligible impact on performance. This was found during testing and will be updated in future versions, with the detailed release of the dataset artifact itself coming in a future release.
License
We are releasing this dataset under the terms of ODC-BY. By using this, you are also bound by the Common Crawl terms of use in respect of the content contained in the dataset.