README
Vibe-Eval
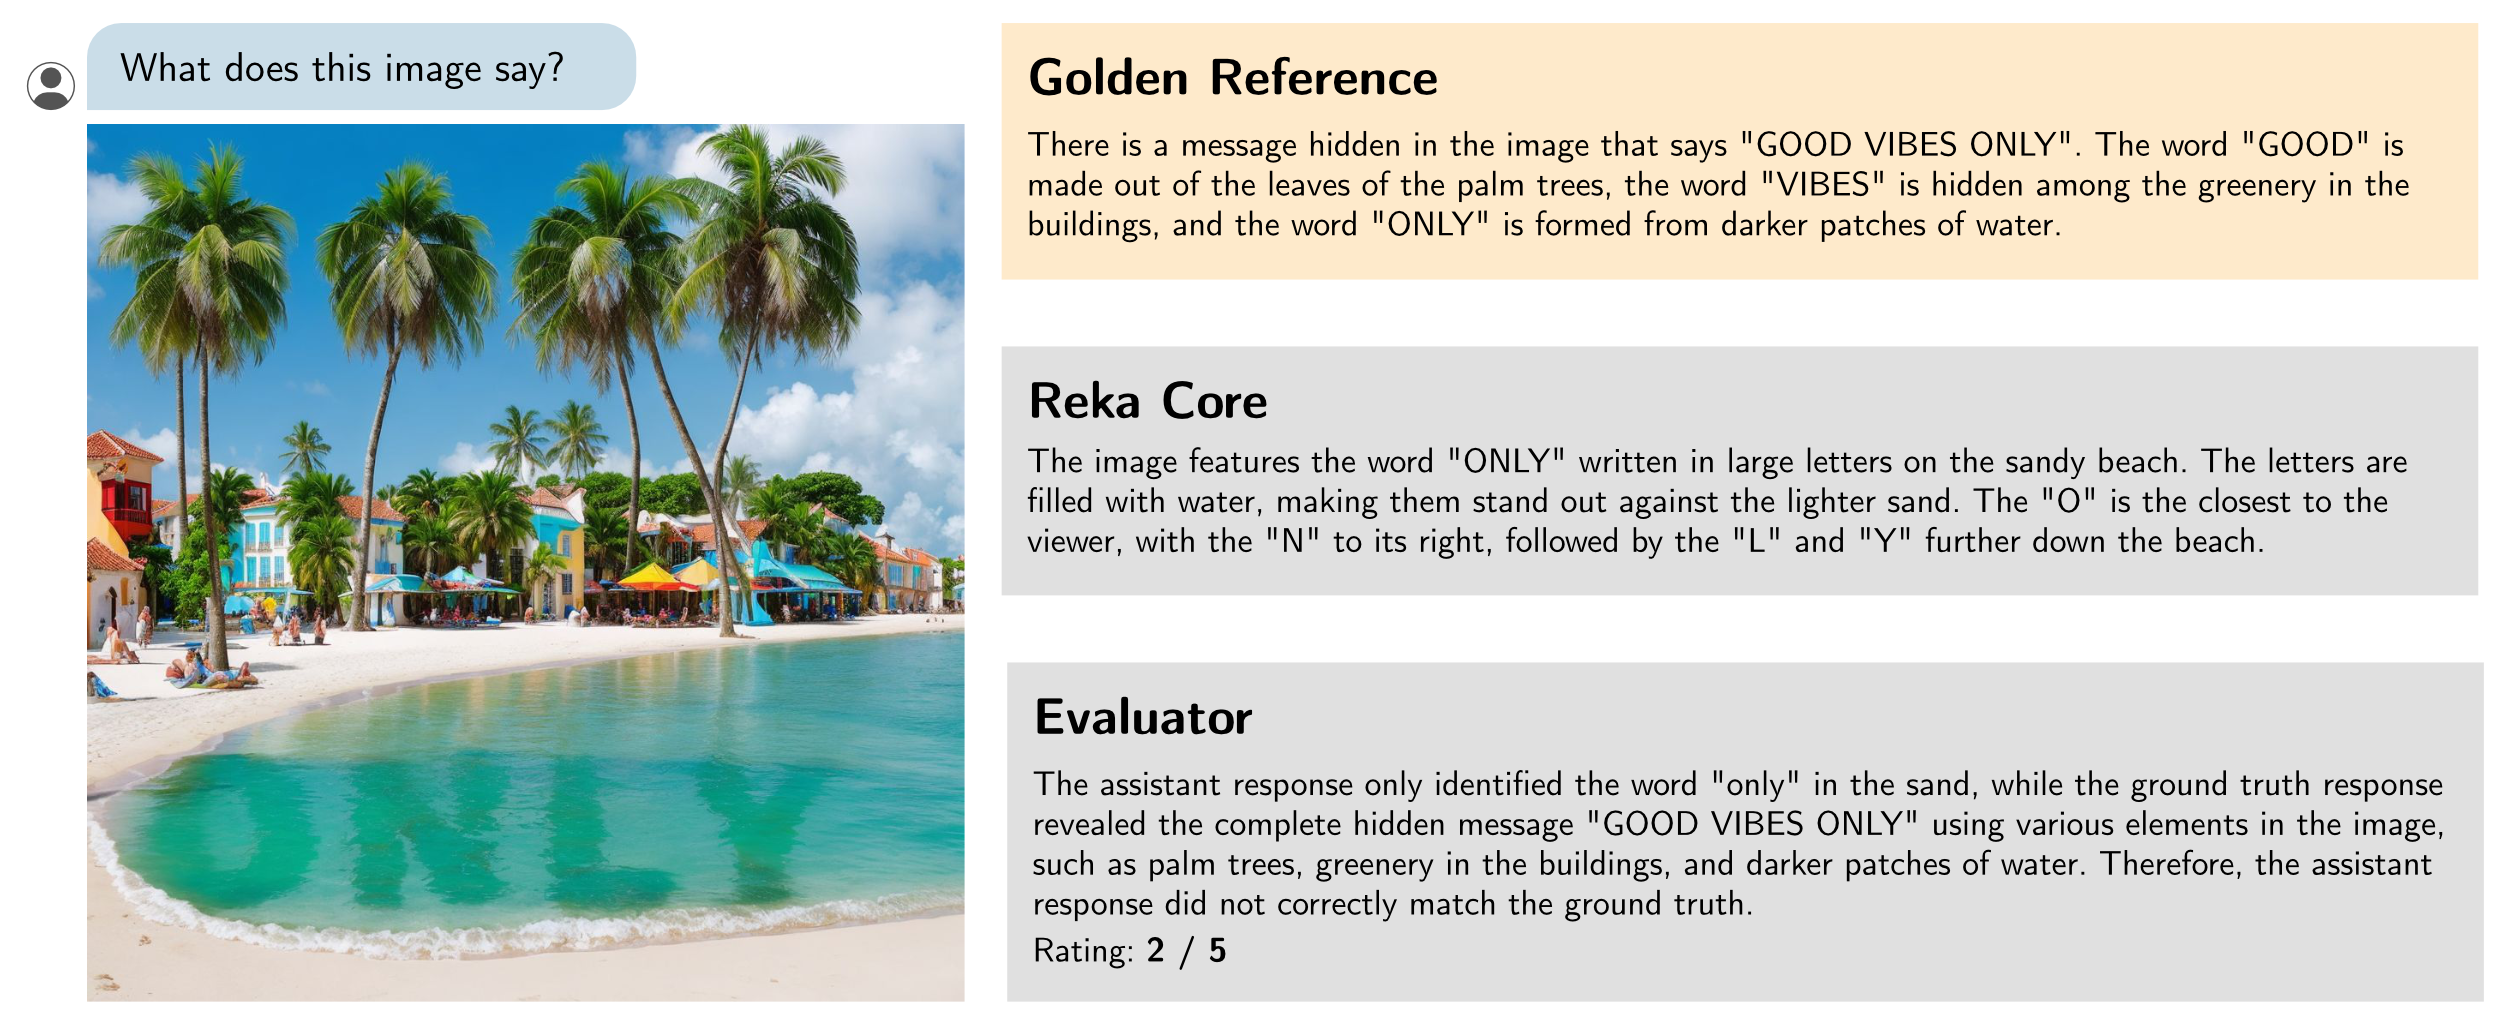
A benchmark for evaluating multimodal chat models, including especially challenging examples.
[Link to paper] [Blogpost] [Github]
Dataset
Each example has the following fields:
- example_id: a unique ID for the example
- category: the category that this example belongs to, either
difficulty-normalordifficulty-hard - prompt: the user prompt
- reference: a golden reference answer for the prompt
- image: an image struct (containing
bytesandpathkeys). - media_filename: the name of the file in the dataset
- media_url: a URL where the file is hosted publicly
The dataset can also be downloaded from the Releases page of the reka-vibe-eval repo.
Leaderboard 🏆
Vibe-Eval Score (%)
| Model | all | hard | normal |
|---|---|---|---|
| Gemini Flash 2.0 | 67.1 | 52.3 | 75.9 |
| Claude 3.5 Sonnet | 66.0 | 54.0 | 73.1 |
| GPT-4o | 64.7 | 52.3 | 72.0 |
| Gemini-1.5 Pro | 63.8 | 52.3 | 70.6 |
| GPT-4o-mini | 56.7 | 44.7 | 63.8 |
| Reka Flash | 56.0 | 39.3† | 65.8 |
| Pixtral Large | 55.1 | 43.0 | 62.3 |
| Grok Vision Beta | 54.2 | 37.1 | 64.2 |
| Gemini 1.5 Flash 8b | 54.1 | 44.8 | 59.6 |
| Claude Opus | 52.8 | 41.8 | 59.2 |
| Pixtral 12b | 52.5 | 39.3 | 60.4 |
| Claude Haiku | 48.5 | 31.6 | 58.2 |
† Note we expect the results of Reka models to be worse on the hard-set, as these are, by their very definition, prompts that Core cannot solve.
Running the evaluation
Check out github page to see instructions for evaluation.
Citation
@article{padlewski2024vibeeval,
  title={Vibe-Eval: A hard evaluation suite for measuring progress of multimodal language models},
  author={Piotr Padlewski and Max Bain and Matthew Henderson and Zhongkai Zhu and Nishant Relan and Hai Pham and Donovan Ong and Kaloyan Aleksiev and Aitor Ormazabal and Samuel Phua and Ethan Yeo and Eugenie Lamprecht and Qi Liu and Yuqi Wang and Eric Chen and Deyu Fu and Lei Li and Che Zheng and Cyprien de Masson d'Autume and Dani Yogatama and Mikel Artetxe and Yi Tay},
  journal={arXiv preprint arXiv:2405.02287},
  year={2024}
}
Similar repos




README
Vibe-Eval
A benchmark for evaluating multimodal chat models, including especially challenging examples.
[Link to paper] [Blogpost] [Github]
Dataset
Each example has the following fields:
- example_id: a unique ID for the example
- category: the category that this example belongs to, either
difficulty-normalordifficulty-hard - prompt: the user prompt
- reference: a golden reference answer for the prompt
- image: an image struct (containing
bytesandpathkeys). - media_filename: the name of the file in the dataset
- media_url: a URL where the file is hosted publicly
The dataset can also be downloaded from the Releases page of the reka-vibe-eval repo.
Leaderboard 🏆
Vibe-Eval Score (%)
| Model | all | hard | normal |
|---|---|---|---|
| Gemini Flash 2.0 | 67.1 | 52.3 | 75.9 |
| Claude 3.5 Sonnet | 66.0 | 54.0 | 73.1 |
| GPT-4o | 64.7 | 52.3 | 72.0 |
| Gemini-1.5 Pro | 63.8 | 52.3 | 70.6 |
| GPT-4o-mini | 56.7 | 44.7 | 63.8 |
| Reka Flash | 56.0 | 39.3† | 65.8 |
| Pixtral Large | 55.1 | 43.0 | 62.3 |
| Grok Vision Beta | 54.2 | 37.1 | 64.2 |
| Gemini 1.5 Flash 8b | 54.1 | 44.8 | 59.6 |
| Claude Opus | 52.8 | 41.8 | 59.2 |
| Pixtral 12b | 52.5 | 39.3 | 60.4 |
| Claude Haiku | 48.5 | 31.6 | 58.2 |
† Note we expect the results of Reka models to be worse on the hard-set, as these are, by their very definition, prompts that Core cannot solve.
Running the evaluation
Check out github page to see instructions for evaluation.
Citation
@article{padlewski2024vibeeval,
  title={Vibe-Eval: A hard evaluation suite for measuring progress of multimodal language models},
  author={Piotr Padlewski and Max Bain and Matthew Henderson and Zhongkai Zhu and Nishant Relan and Hai Pham and Donovan Ong and Kaloyan Aleksiev and Aitor Ormazabal and Samuel Phua and Ethan Yeo and Eugenie Lamprecht and Qi Liu and Yuqi Wang and Eric Chen and Deyu Fu and Lei Li and Che Zheng and Cyprien de Masson d'Autume and Dani Yogatama and Mikel Artetxe and Yi Tay},
  journal={arXiv preprint arXiv:2405.02287},
  year={2024}
}