README
Benchmark.ai Image Benchmark
Built by Rapidata for Benchmark.ai.
This dataset contains 6,123,853 human responses, collected with the Rapidata Python SDK, comparing 43 text-to-image models on 1,514 prompts. Each row is a head-to-head comparison between two models' images for the same prompt, judged by human annotators on up to four questions — Alignment, Preference, Coherence and Text coherence.
Every image is ranked purely by human judgement, no automated metrics. This is the data behind the Benchmark.ai image leaderboard.
If you get value from this dataset and would like to see more in the future, please consider liking it ❤️
To evaluate your own models and create a leaderboard, check out our MRI.
🏆 Live Leaderboard
Explore the full interactive leaderboard on Benchmark.ai — compare models side by side, browse matchups and prompts, and slice the standings by capability, output type, subject and prompt source.

👆 Click to open it on benchmark.ai, or on Rapidata
At a glance
| Head-to-head comparisons (rows) | 680,548 |
| Human votes | 6,123,853 (Alignment 1,730,190 · Preference 1,731,352 · Coherence 1,730,112 · Text coherence 932,199) |
| Models compared | 43 |
| Prompts | 1,514 (616 of them ask for rendered text) |
| Unique generated images | 64,266 |
| Annotator countries | 148 |
The leaderboards
Every model is compared on the same kind of image pairs across four independent questions, run as four leaderboards on one Rapidata benchmark:
| Leaderboard | Question shown to annotators | Prompt shown? | Measures |
|---|---|---|---|
| Alignment | "Which image matches the description better?" | Yes | how faithfully the image depicts the prompt |
| Preference | "Which image looks higher quality and more visually appealing?" | No | overall visual appeal, independent of the prompt |
| Coherence | "Which image has more glitches and is more likely to be AI generated?" | No | visual soundness — the image with fewer artifacts wins |
| Text coherence | "In which image does the text have glitches or is harder to read?" | No | legibility of rendered text — the image with fewer text glitches wins (text prompts only) |
Alignment
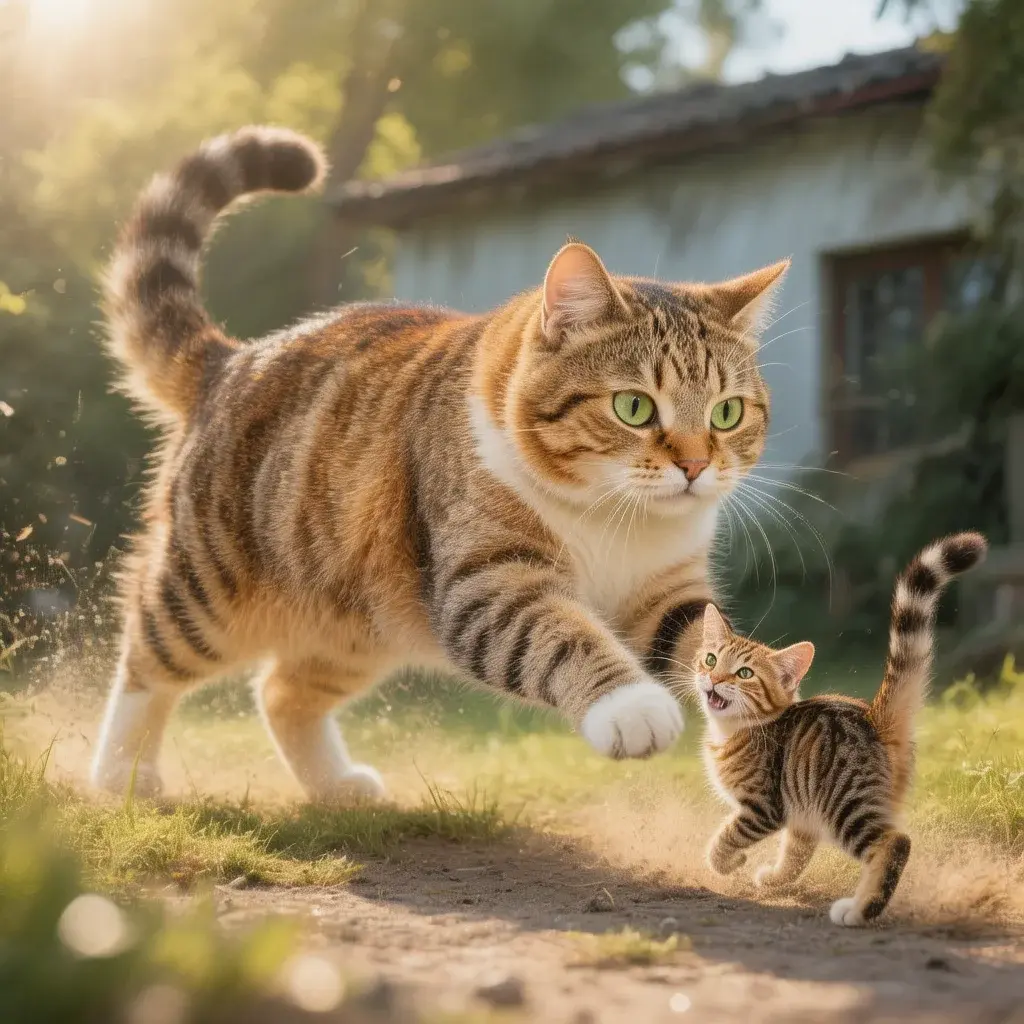
The alignment score measures how well the image matches its prompt. Annotators saw the prompt and were asked: "Which image matches the description better?"
a cat chasing a horse
Reve 2.1
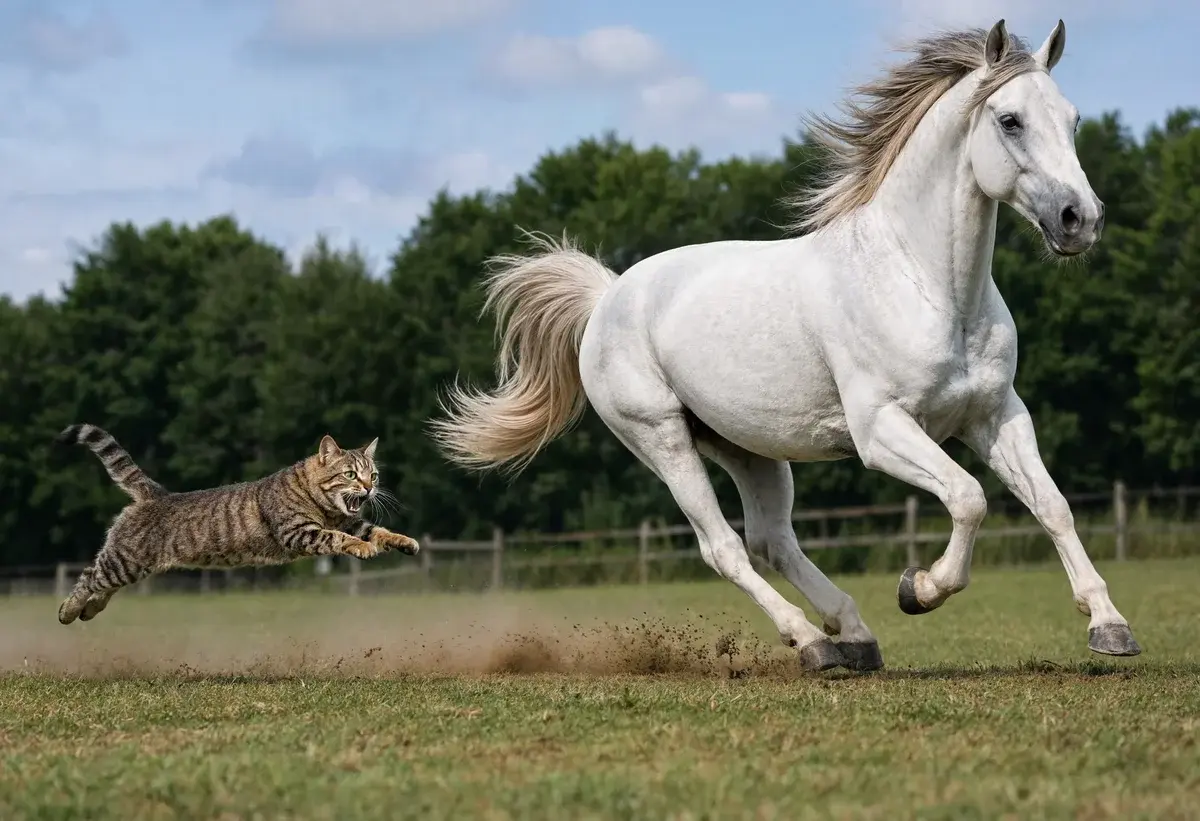
HunyuanImage 3.0
Book cover, deep navy background: a heraldic oval crest with a silver border, pierced by a katana and a crossbow bolt. Title (not touching the edge): "Comandante Vega: Orion".
GPT Image 2.5 (Flare)
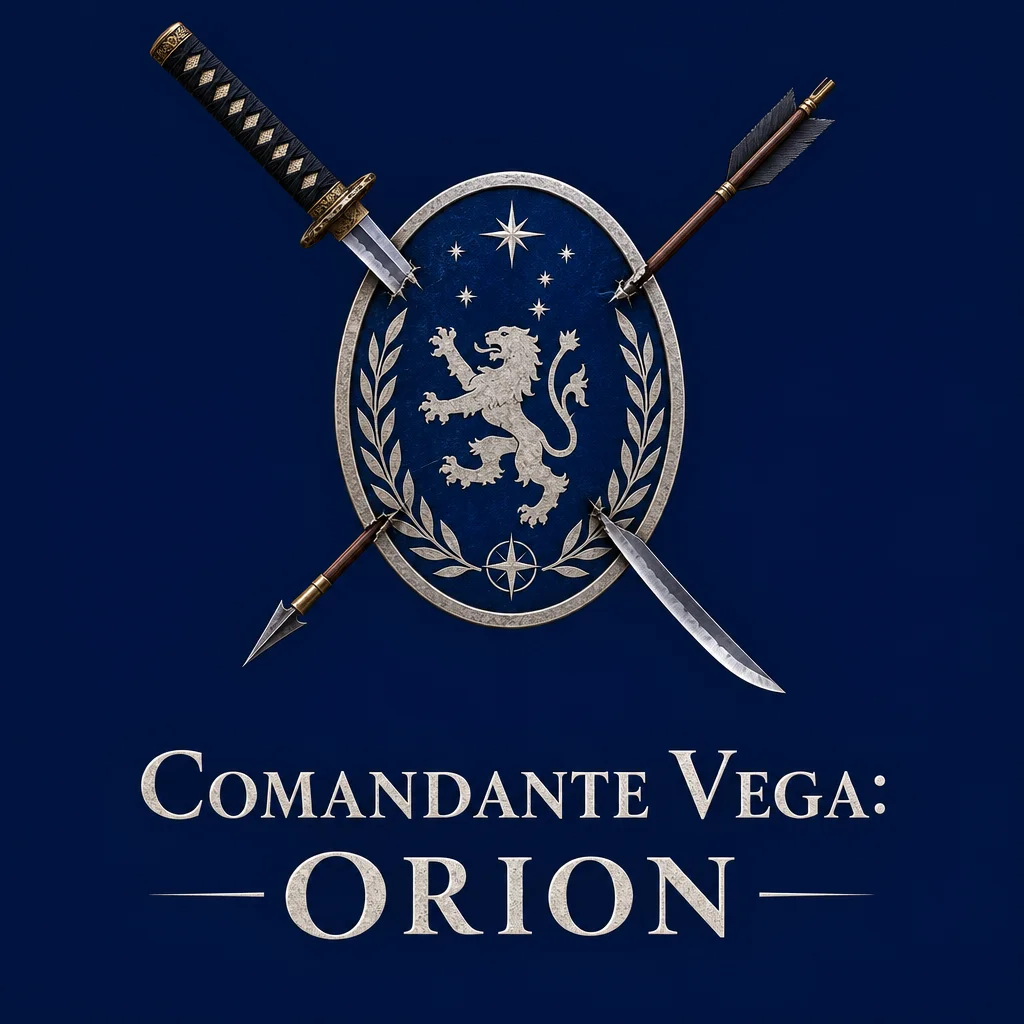
Pruna P-Image
Preference
The preference score reflects how visually appealing annotators found each image. Without seeing the prompt, they were asked: "Which image looks higher quality and more visually appealing?"
GPT Image 2.5 (Flare)
FLUX.2 klein 9B
nano-banana-pro
Ideogram 4.0 Quality
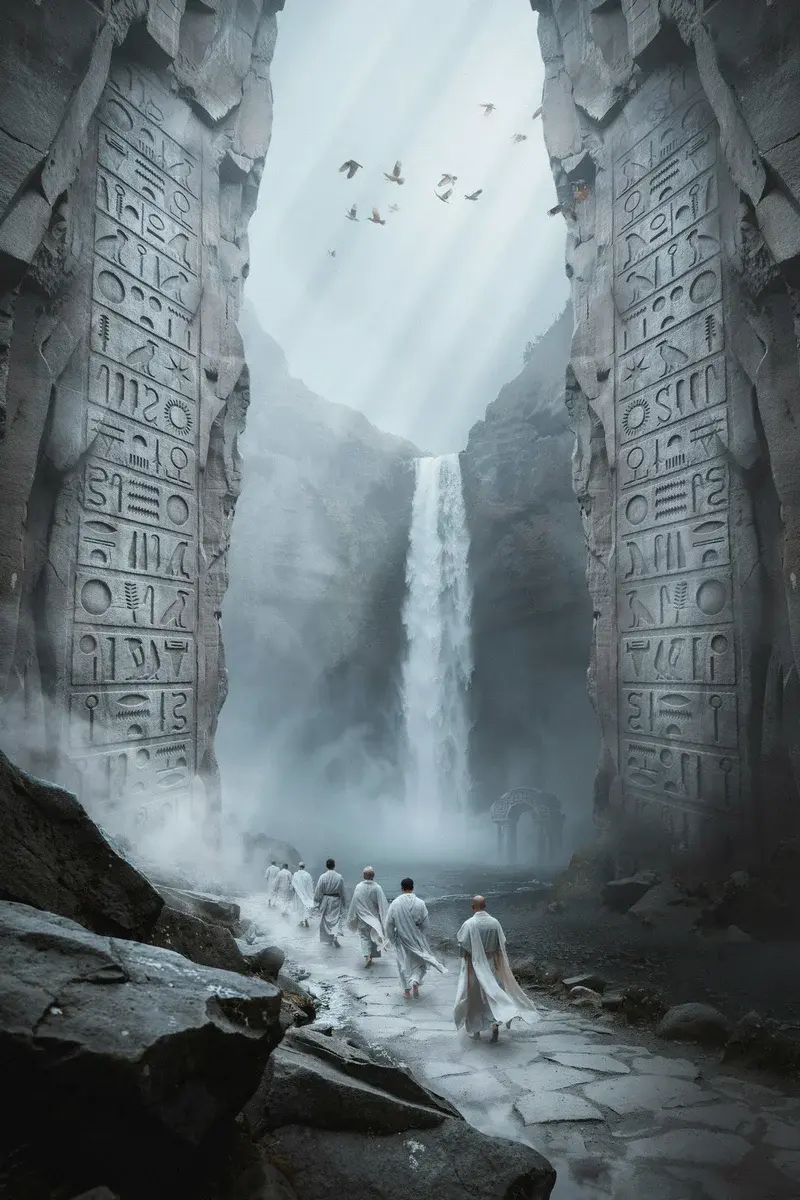
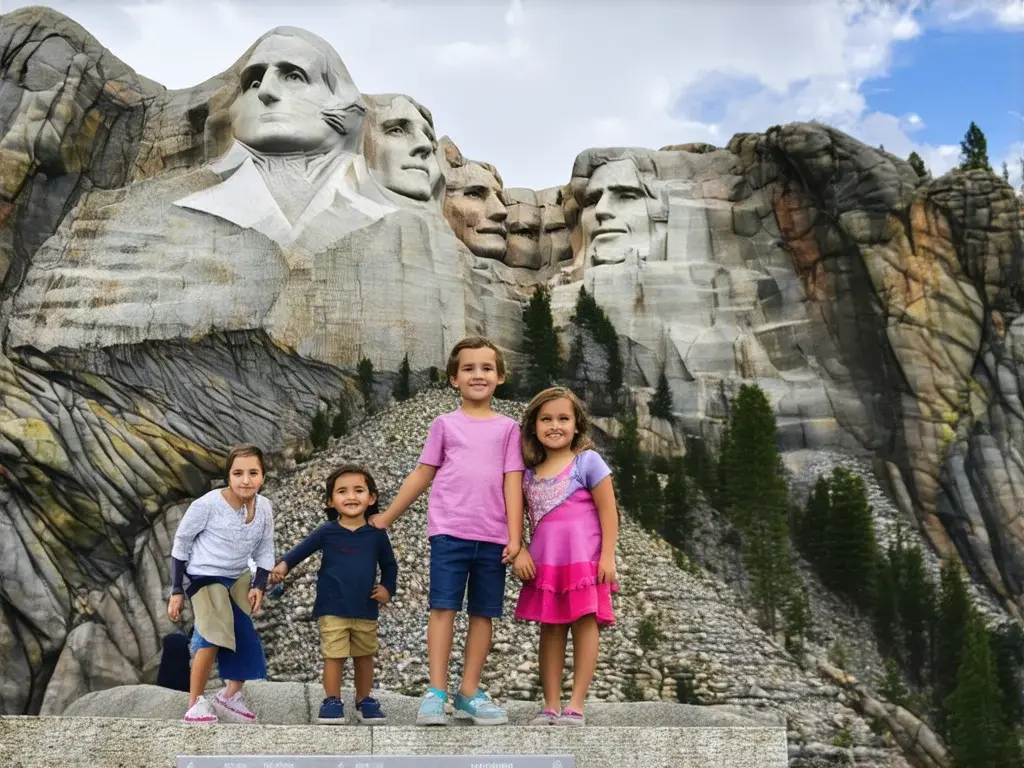
Coherence
The coherence score measures whether the image is free of artifacts and visual glitches. Without seeing the prompt, annotators were asked: "Which image has more glitches and is more likely to be AI generated?" The image picked less often wins.
Pruna P-Image
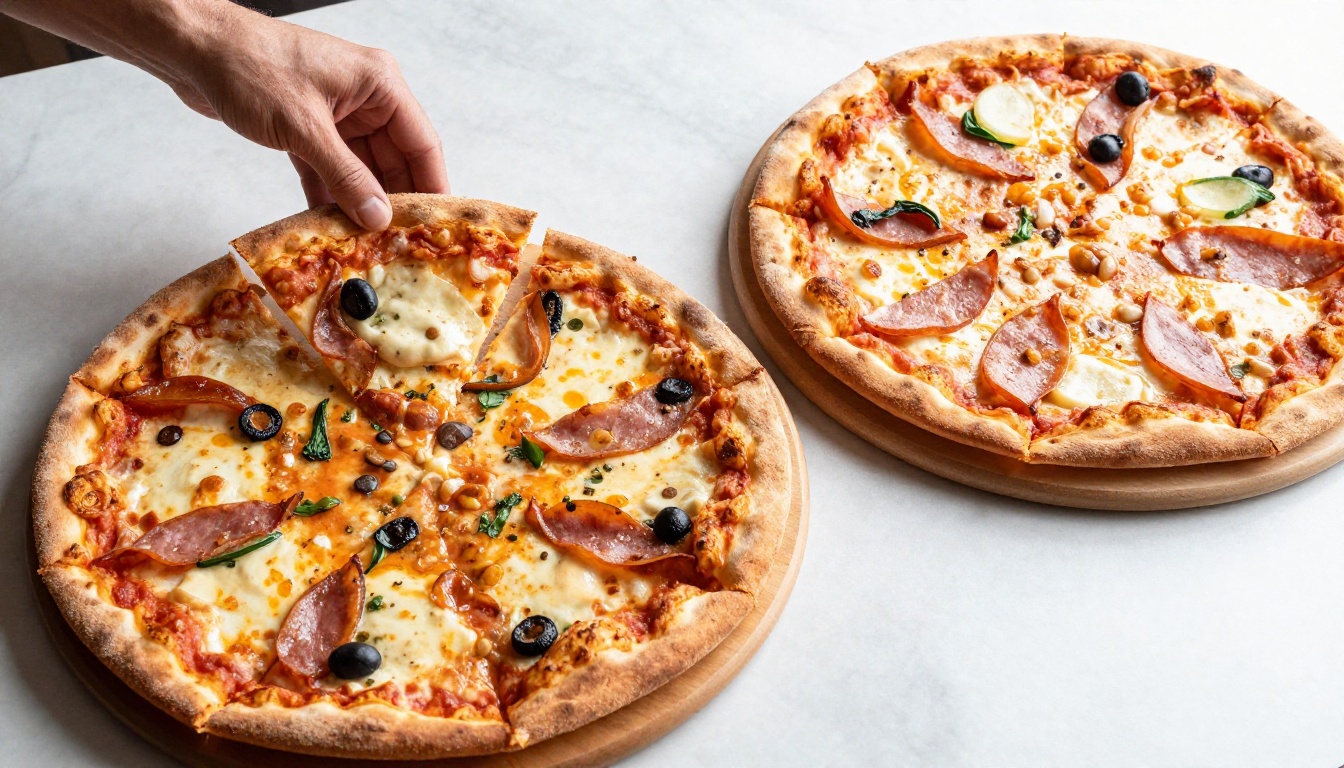
Reve 2.1
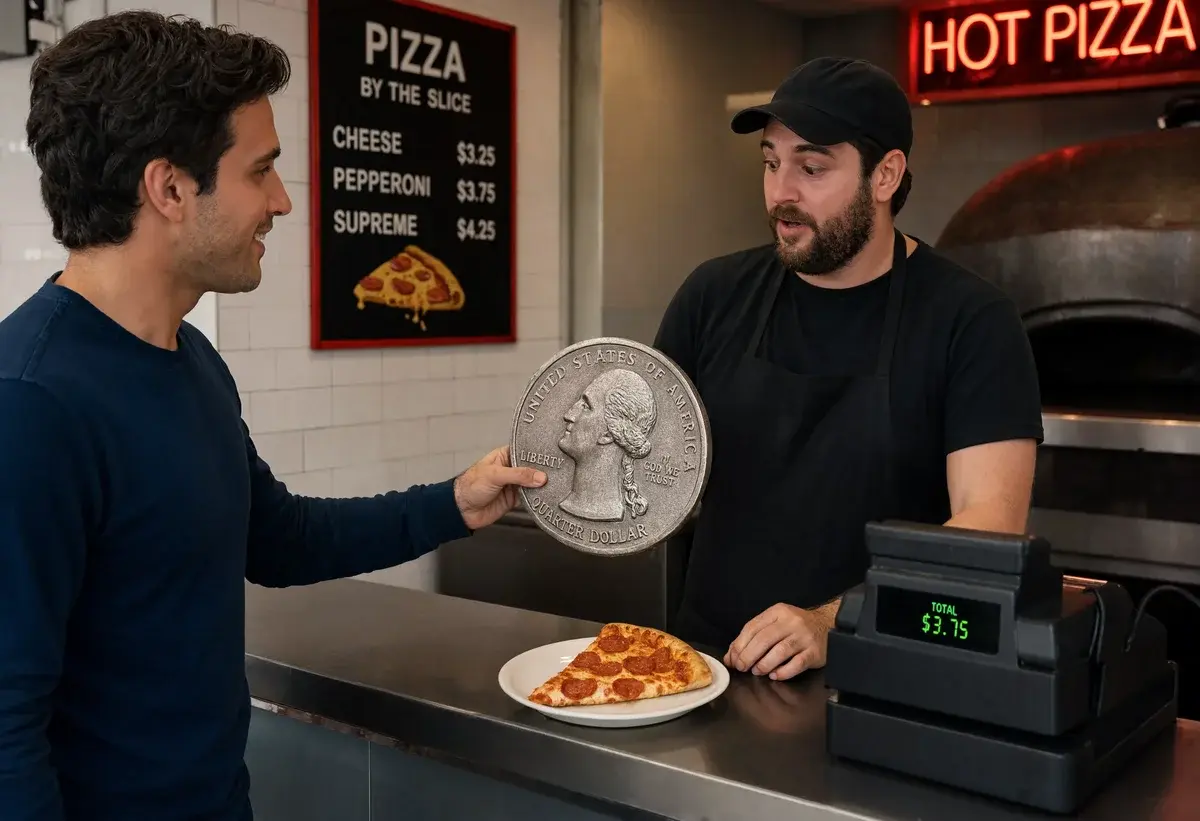
FLUX.2 max
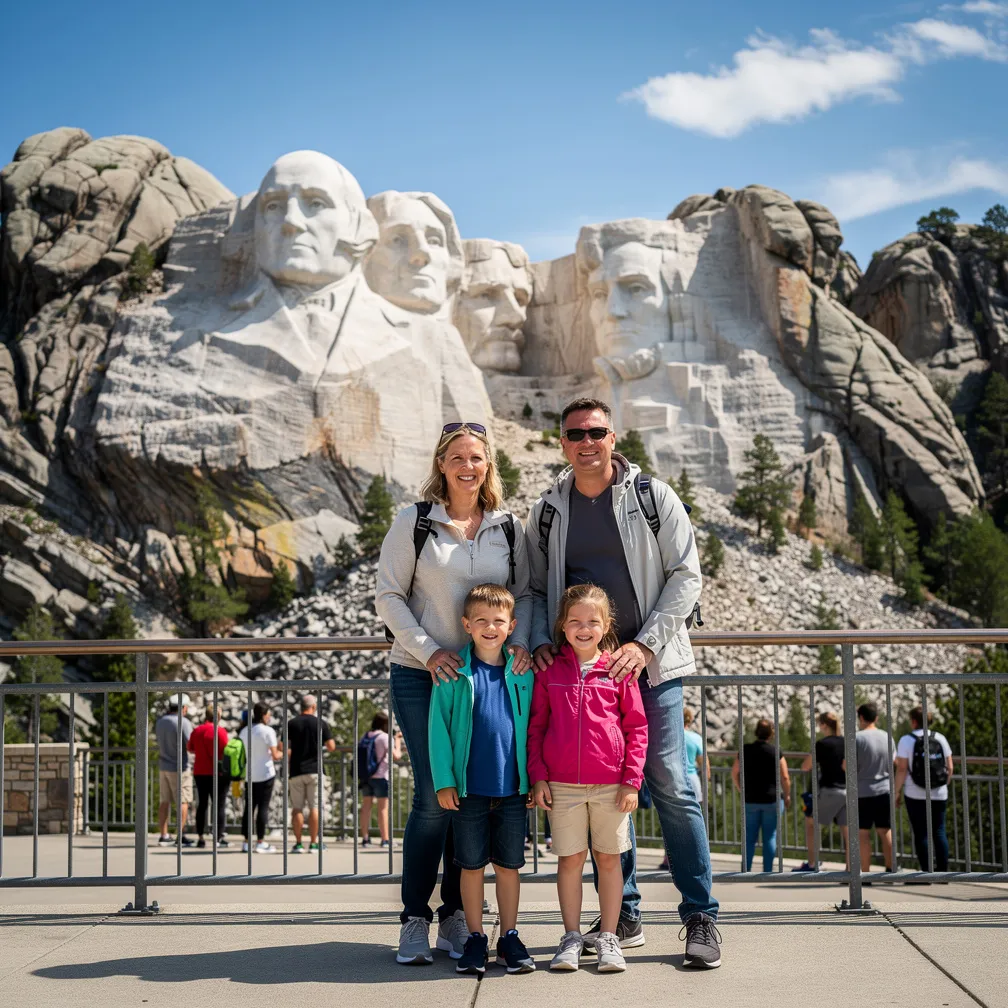
Stable Diffusion 3.5 Large
Text coherence
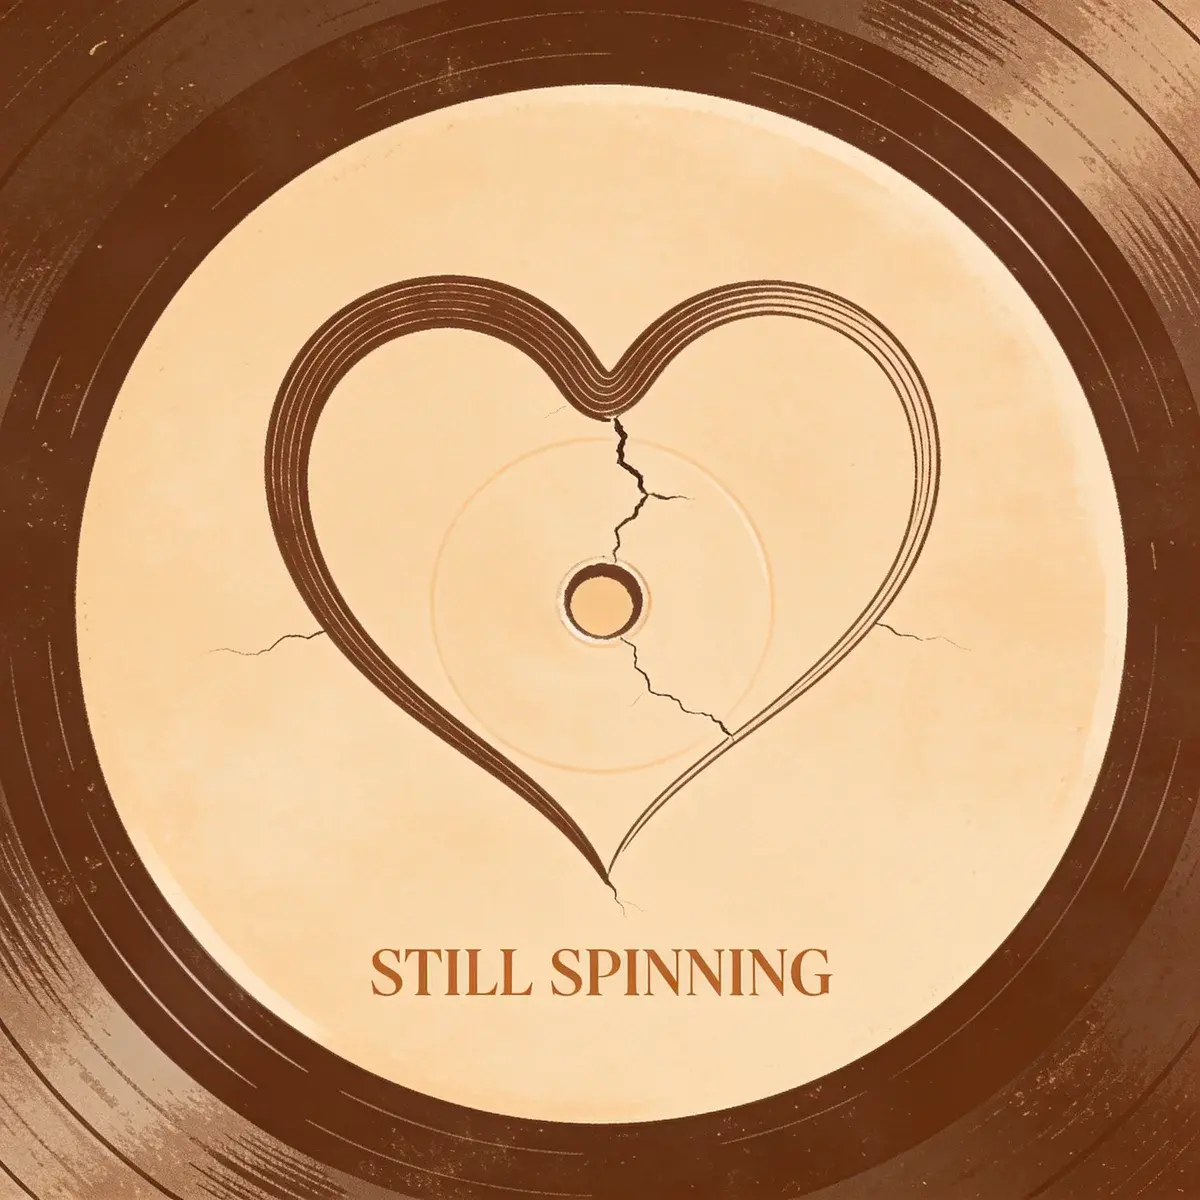
The text coherence score measures how cleanly a model renders text. It runs only on the 616 prompts that ask for text. Without seeing the prompt, annotators were asked: "In which image does the text have glitches or is harder to read?" The image picked less often wins.
Seedream 4.5
Pruna P-Image
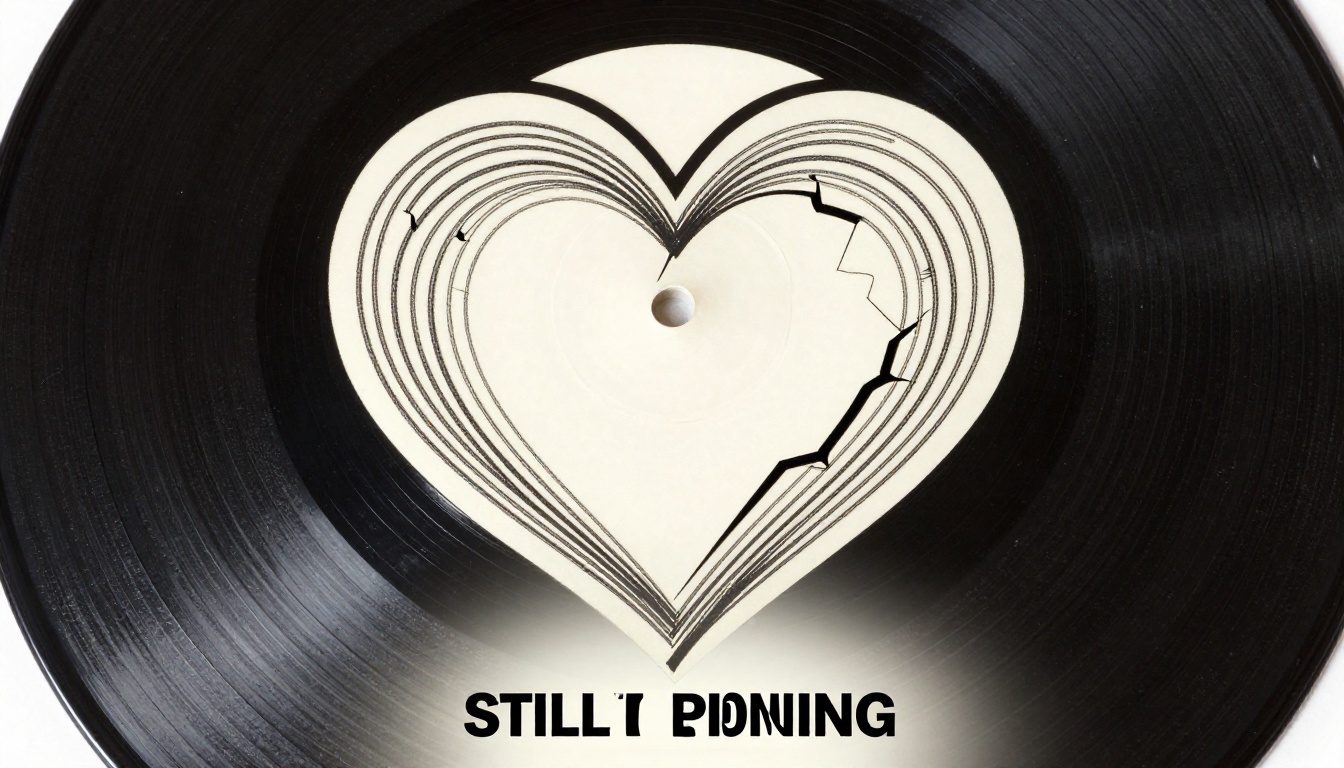
Recraft V4.1 Utility Pro
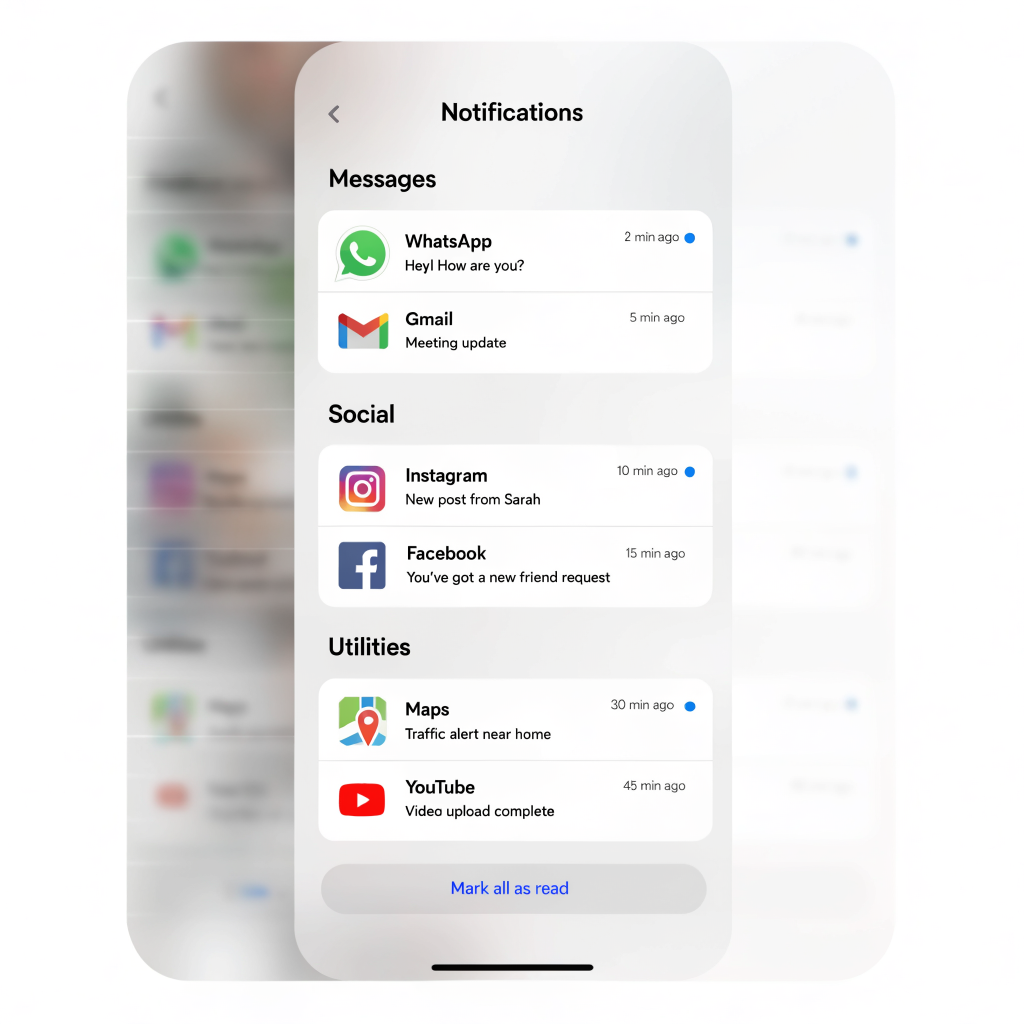
Pruna P-Image
Rankings
Overall ranking (ELO, aggregated across all four leaderboards)
| # | Model | Lab | Overall | Alignment | Preference | Coherence | Text coherence |
|---|---|---|---|---|---|---|---|
| 1 | GPT Image 2.5 (Sunburst) | OpenAI | 1238.3 | 1326 | 1250 | 1246 | 1181 |
| 2 | GPT Image 2.5 (Flare) | OpenAI | 1207.1 | 1341 | 1196 | 1219 | 1136 |
| 3 | GPT Image 2.0 | OpenAI | 1167.3 | 1242 | 1135 | 1113 | 1186 |
| 4 | Reve 2.1 | Reve AI | 1147.5 | 1149 | 1096 | 1157 | 1193 |
| 5 | Grok Image Imagine 2.0 (Medium) | SpaceXAI | 1136.8 | 1192 | 1099 | 1096 | 1165 |
| 6 | GPT Image 1.5 (high) | OpenAI | 1131.9 | 1247 | 1242 | 896 | 1154 |
| 7 | nano-banana-2 | 1128.1 | 1169 | 1242 | 1050 | 1051 | |
| 8 | Grok Imagine Image 2.0 | SpaceXAI | 1107.5 | 1128 | 1086 | 1076 | 1155 |
| 9 | Muse Image | Meta | 1096.3 | 1171 | 1108 | 1062 | 1034 |
| 10 | Qwen-Image-3.0 | Alibaba Cloud | 1083.1 | 1110 | 1205 | 972 | 1031 |
| 11 | nano-banana-pro | 1071.6 | 1070 | 1044 | 1104 | 1049 | |
| 12 | Seedream 4.5 | ByteDance | 1046.7 | 1032 | 999 | 948 | 1220 |
| 13 | Grok Image Imagine 2.0 (Thinking) | SpaceXAI | 1045.6 | 1039 | 1087 | 1012 | 1038 |
| 14 | MAI-Image 2.5 | Microsoft AI | 1042.1 | 1060 | 1114 | 975 | 1015 |
| 15 | Imagen 4 Ultra | 1025.9 | 1057 | 1106 | 869 | 1081 | |
| 16 | Seedream 5.0 Lite | ByteDance | 1013.7 | 1027 | 896 | 957 | 1183 |
| 17 | FLUX.2 flex | Black Forest Labs | 1011.0 | 1034 | 1036 | 872 | 1104 |
| 18 | Grok Imagine Image (quality) | SpaceXAI | 1009.7 | 1139 | 1034 | 880 | 980 |
| 19 | Wan 2.7 Pro | Alibaba Cloud | 1007.6 | 1018 | 1038 | 987 | 981 |
| 20 | FLUX.2 pro | Black Forest Labs | 1003.4 | 1015 | 946 | 990 | 1061 |
| 21 | Seedream 5.0 Pro | ByteDance | 992.9 | 1005 | 1076 | 1016 | 858 |
| 22 | FLUX.2 max | Black Forest Labs | 992.8 | 992 | 932 | 975 | 1071 |
| 23 | Qwen-Image | Alibaba Cloud | 991.7 | 933 | 1129 | 1003 | 888 |
| 24 | Grok Imagine Image | SpaceXAI | 988.6 | 1038 | 1016 | 866 | 1031 |
| 25 | HiDream O1 | HiDream AI | 988.2 | 1043 | 1101 | 871 | 928 |
| 26 | Qwen-Image 2.0 Pro | Alibaba Cloud | 986.3 | 1005 | 920 | 939 | 1087 |
| 27 | Ideogram 4.5 Quality | Ideogram | 967.6 | 851 | 821 | 1136 | 1006 |
| 28 | Recraft V4.1 Utility Pro | Recraft | 953.3 | 983 | 890 | 1004 | 925 |
| 29 | FLUX.2 dev | Black Forest Labs | 945.7 | 1016 | 936 | 911 | 910 |
| 30 | Imagen 3 | 939.3 | 912 | 1014 | 964 | 823 | |
| 31 | Imagen 4 | 934.7 | 879 | 1036 | 901 | 903 | |
| 32 | Imagen 4 Fast | 930.2 | 893 | 946 | 953 | 914 | |
| 33 | FLUX.2 klein 9B | Black Forest Labs | 925.3 | 950 | 905 | 992 | 837 |
| 34 | HunyuanImage 3.0 | Tencent | 924.8 | 989 | 1130 | 767 | 788 |
| 35 | Ideogram 4.0 Quality | Ideogram | 911.9 | 817 | 800 | 1100 | 911 |
| 36 | ERNIE Image | Baidu | 896.9 | 860 | 1145 | 694 | 846 |
| 37 | Pruna-P-Ideogram (High) | Pruna AI | 894.9 | 767 | 789 | 1101 | 891 |
| 38 | Pruna P-Image | Pruna AI | 890.2 | 634 | 874 | 1130 | 884 |
| 39 | Pruna-P-Ideogram (Low) | Pruna AI | 870.7 | 769 | 714 | 1105 | — |
| 40 | Pruna-P-Ideogram (Medium) | Pruna AI | 867.9 | 744 | 695 | 1137 | — |
| 41 | Luma UNI 1.1 Max | Luma Labs | 846.1 | 820 | 619 | 1014 | 872 |
| 42 | Pruna-P-Ideogram (Very Low) | Pruna AI | 844.3 | 753 | 683 | 1076 | — |
| 43 | Stable Diffusion 3.5 Large | Stability AI | 794.4 | 780 | 868 | 862 | 627 |
A model shows "—" where it has no standing on that leaderboard.
By output type and capability
OpenAI's GPT Image 2.5 tops every category the benchmark slices by, so the last column shows the strongest model from any other lab. The full per-category standings, including subject and prompt source, are on Benchmark.ai.
| Output type | Prompts | #1 overall (ELO) | Best non-OpenAI model (ELO) |
|---|---|---|---|
| General Image | 524 | GPT Image 2.5 (Sunburst) (1265) | Reve 2.1 — Reve AI (1151) |
| Photorealism | 243 | GPT Image 2.5 (Flare) (1242) | Reve 2.1 — Reve AI (1141) |
| UI / UX | 182 | GPT Image 2.5 (Sunburst) (1213) | Muse Image — Meta (1174) |
| Illustration & Anime | 147 | GPT Image 2.5 (Sunburst) (1237) | Reve 2.1 — Reve AI (1161) |
| Graphic Design & Marketing | 137 | GPT Image 2.5 (Sunburst) (1249) | Reve 2.1 — Reve AI (1222) |
| Logos & Branding | 134 | GPT Image 2.5 (Flare) (1209) | nano-banana-2 — Google (1151) |
| Infographics | 131 | GPT Image 2.5 (Sunburst) (1235) | nano-banana-2 — Google (1154) |
| 3D Modeling & Rendering | 19 | GPT Image 2.5 (Sunburst) (1270) | Qwen-Image-3.0 — Alibaba Cloud (1176) |
| Capability | Prompts | #1 overall (ELO) | Best non-OpenAI model (ELO) |
|---|---|---|---|
| Attribute Binding | 758 | GPT Image 2.5 (Sunburst) (1214) | Reve 2.1 — Reve AI (1153) |
| Text | 616 | GPT Image 2.5 (Sunburst) (1236) | Reve 2.1 — Reve AI (1159) |
| Scene Composition | 428 | GPT Image 2.5 (Flare) (1230) | Reve 2.1 — Reve AI (1163) |
| Knowledge & Reasoning | 384 | GPT Image 2.5 (Sunburst) (1227) | nano-banana-2 — Google (1141) |
| Spatial & Size | 264 | GPT Image 2.5 (Sunburst) (1228) | Reve 2.1 — Reve AI (1129) |
| Number of Objects | 252 | GPT Image 2.5 (Sunburst) (1265) | Reve 2.1 — Reve AI (1169) |
| Surreal | 244 | GPT Image 2.5 (Flare) (1206) | nano-banana-2 — Google (1142) |
| Emotion & Mood | 130 | GPT Image 2.5 (Sunburst) (1254) | Reve 2.1 — Reve AI (1177) |
| Noisy Input | 20 | GPT Image 2.5 (Sunburst) (1377) | Grok Image Imagine 2.0 (Medium) — SpaceXAI (1238) |
How the dataset was built
1. Prompts (1,514)
The prompts are drawn from established text-to-image evaluation sets, real user prompts and prompts written for this benchmark:
| Source | Prompts |
|---|---|
| Rapidata Original | 328 |
| DiffusionDB | 325 |
| PartiPrompts | 243 |
| Community | 235 |
| MONET | 187 |
| DrawBench | 87 |
| ABC-6K | 40 |
| T2I-CompBench | 31 |
| DALLE3-EVAL | 20 |
| HRS-Bench | 18 |
Every prompt is tagged on three more axes, which the live leaderboard can slice by:
- Capability — attribute binding, text, scene composition, knowledge & reasoning, spatial & size, number of objects, surreal, emotion & mood, noisy input (a prompt can carry several)
- Output type — general image, photorealism, UI / UX, illustration & anime, graphic design & marketing, logos & branding, infographics, 3D modeling & rendering
- Subject — objects & abstract, people & portraits, animals, architecture & spaces, vehicles, sci-fi & fantasy, food & drink, nature & landscapes
2. Image generation (43 models)
Each prompt was sent to every model, and the resulting images were uploaded to a Rapidata MRI benchmark as one participant per model. Every model has images for between 1,410 and 1,514 of the 1,514 prompts.
Alibaba Cloud — Qwen-Image, Qwen-Image 2.0 Pro, Qwen-Image-3.0, Wan 2.7 Pro · Baidu — ERNIE Image · Black Forest Labs — FLUX.2 dev, FLUX.2 flex, FLUX.2 klein 9B, FLUX.2 max, FLUX.2 pro · ByteDance — Seedream 4.5, Seedream 5.0 Lite, Seedream 5.0 Pro · Google — Imagen 3, Imagen 4, Imagen 4 Fast, Imagen 4 Ultra, nano-banana-2, nano-banana-pro · HiDream AI — HiDream O1 · Ideogram — Ideogram 4.0 Quality, Ideogram 4.5 Quality · Luma Labs — Luma UNI 1.1 Max · Meta — Muse Image · Microsoft AI — MAI-Image 2.5 · OpenAI — GPT Image 1.5 (high), GPT Image 2.0, GPT Image 2.5 (Flare), GPT Image 2.5 (Sunburst) · Pruna AI — Pruna P-Image, Pruna-P-Ideogram (High), Pruna-P-Ideogram (Low), Pruna-P-Ideogram (Medium), Pruna-P-Ideogram (Very Low) · Recraft — Recraft V4.1 Utility Pro · Reve AI — Reve 2.1 · SpaceXAI — Grok Image Imagine 2.0 (Medium), Grok Image Imagine 2.0 (Thinking), Grok Imagine Image, Grok Imagine Image (quality), Grok Imagine Image 2.0 · Stability AI — Stable Diffusion 3.5 Large · Tencent — HunyuanImage 3.0
3. Human evaluation
The four leaderboards were run over pairwise matchups between the models' images for the same prompt. Alignment,
Coherence and Text coherence were answered by dedicated, qualified Rapidata audiences; Preference by the open global
pool. Each pair is judged on a subset of the questions, with at least 5 votes per question it was judged on; Text
coherence runs only on the 616 text prompts. Per-annotator detail — chosen side, country, language, gender, age
bucket, occupation and the annotator's userScore — is preserved in the detailed_results_* columns. Votes came from
annotators in 148 countries.
Dataset structure
One row per head-to-head image pair generated from the same prompt.
| Column | Type | Description |
|---|---|---|
prompt | string | the prompt both images were generated from |
image1 | string | public URL of the image from model1 |
image2 | string | public URL of the image from model2 |
model1 | string | name of the model that produced image1 |
model2 | string | name of the model that produced image2 |
weighted_results_image1_<q> | float32 | sum of the userScore weights of the votes for image1 on question <q> |
weighted_results_image2_<q> | float32 | sum of the userScore weights of the votes for image2 on question <q> |
detailed_results_<q> | string | every vote on question <q> as a JSON array (votedFor is A for image1 and B for image2, plus annotator demographics, userScore and votedAt) |
<q> is one of alignment, preference, coherence and text_coherence. A row's columns for a question it was
not judged on are empty.
- The
weighted_results_*values are userScore-weighted vote sums, not probabilities — they do not sum to 1. Divide by their sum for a normalised win share. - Coherence and Text coherence are already flipped. Annotators were asked which image has more glitches, but in
this dataset
votedForandweighted_results_*point to the image with fewer glitches, so a higher value is better on every question.
import json
from datasets import load_dataset

ds = load_dataset("Rapidata/benchmark-ai-image-benchmark", split="train")
row = ds[0]
print(row["prompt"], "|", row["model1"], "vs", row["model2"])

for q in ["alignment", "preference", "coherence", "text_coherence"]:
    w1, w2 = row[f"weighted_results_image1_{q}"], row[f"weighted_results_image2_{q}"]
    if w1 is None or w1 + w2 == 0:
        continue  # this pair was not judged on q
    print(f"{q}: {row['model1']} wins {w1 / (w1 + w2):.0%} of the weighted vote")
Licensing & attribution
This dataset combines material under different terms:
- Prompts. Prompts taken from public evaluation sets (PartiPrompts, DrawBench, DiffusionDB, MONET, T2I-CompBench, HRS-Bench, ABC-6K, DALLE3-EVAL) remain under their original licenses; Rapidata-original and community prompts are released under CC-BY-4.0.
- Generated images. Produced by third-party models. Model outputs are governed by the terms of use of each respective model provider.
- Human annotations. Collected via Rapidata, released under CC-BY-4.0.
About Rapidata
Rapidata's technology makes collecting human feedback at scale faster and more accessible than ever before. Visit rapidata.ai to learn more about how we're revolutionizing human feedback collection for AI development.
Explore all of our live benchmarks on Benchmark.ai.
Related datasets
- Rapidata/svg-benchmark — the same three core questions for SVGs generated by frontier LLMs.
- Rapidata/camera-movement and Rapidata/relative-camera-movement — camera control in image-to-video models.
Similar repos





README
Benchmark.ai Image Benchmark
Built by Rapidata for Benchmark.ai.
This dataset contains 6,123,853 human responses, collected with the Rapidata Python SDK, comparing 43 text-to-image models on 1,514 prompts. Each row is a head-to-head comparison between two models' images for the same prompt, judged by human annotators on up to four questions — Alignment, Preference, Coherence and Text coherence.
Every image is ranked purely by human judgement, no automated metrics. This is the data behind the Benchmark.ai image leaderboard.
If you get value from this dataset and would like to see more in the future, please consider liking it ❤️
To evaluate your own models and create a leaderboard, check out our MRI.
🏆 Live Leaderboard
Explore the full interactive leaderboard on Benchmark.ai — compare models side by side, browse matchups and prompts, and slice the standings by capability, output type, subject and prompt source.
👆 Click to open it on benchmark.ai, or on Rapidata
At a glance
| Head-to-head comparisons (rows) | 680,548 |
| Human votes | 6,123,853 (Alignment 1,730,190 · Preference 1,731,352 · Coherence 1,730,112 · Text coherence 932,199) |
| Models compared | 43 |
| Prompts | 1,514 (616 of them ask for rendered text) |
| Unique generated images | 64,266 |
| Annotator countries | 148 |
The leaderboards
Every model is compared on the same kind of image pairs across four independent questions, run as four leaderboards on one Rapidata benchmark:
| Leaderboard | Question shown to annotators | Prompt shown? | Measures |
|---|---|---|---|
| Alignment | "Which image matches the description better?" | Yes | how faithfully the image depicts the prompt |
| Preference | "Which image looks higher quality and more visually appealing?" | No | overall visual appeal, independent of the prompt |
| Coherence | "Which image has more glitches and is more likely to be AI generated?" | No | visual soundness — the image with fewer artifacts wins |
| Text coherence | "In which image does the text have glitches or is harder to read?" | No | legibility of rendered text — the image with fewer text glitches wins (text prompts only) |
Alignment
The alignment score measures how well the image matches its prompt. Annotators saw the prompt and were asked: "Which image matches the description better?"
a cat chasing a horse
Reve 2.1
HunyuanImage 3.0
Book cover, deep navy background: a heraldic oval crest with a silver border, pierced by a katana and a crossbow bolt. Title (not touching the edge): "Comandante Vega: Orion".
GPT Image 2.5 (Flare)
Pruna P-Image
Preference
The preference score reflects how visually appealing annotators found each image. Without seeing the prompt, they were asked: "Which image looks higher quality and more visually appealing?"
GPT Image 2.5 (Flare)
FLUX.2 klein 9B
nano-banana-pro
Ideogram 4.0 Quality
Coherence
The coherence score measures whether the image is free of artifacts and visual glitches. Without seeing the prompt, annotators were asked: "Which image has more glitches and is more likely to be AI generated?" The image picked less often wins.
Pruna P-Image
Reve 2.1
FLUX.2 max
Stable Diffusion 3.5 Large
Text coherence
The text coherence score measures how cleanly a model renders text. It runs only on the 616 prompts that ask for text. Without seeing the prompt, annotators were asked: "In which image does the text have glitches or is harder to read?" The image picked less often wins.
Seedream 4.5
Pruna P-Image
Recraft V4.1 Utility Pro
Pruna P-Image
Rankings
Overall ranking (ELO, aggregated across all four leaderboards)
| # | Model | Lab | Overall | Alignment | Preference | Coherence | Text coherence |
|---|---|---|---|---|---|---|---|
| 1 | GPT Image 2.5 (Sunburst) | OpenAI | 1238.3 | 1326 | 1250 | 1246 | 1181 |
| 2 | GPT Image 2.5 (Flare) | OpenAI | 1207.1 | 1341 | 1196 | 1219 | 1136 |
| 3 | GPT Image 2.0 | OpenAI | 1167.3 | 1242 | 1135 | 1113 | 1186 |
| 4 | Reve 2.1 | Reve AI | 1147.5 | 1149 | 1096 | 1157 | 1193 |
| 5 | Grok Image Imagine 2.0 (Medium) | SpaceXAI | 1136.8 | 1192 | 1099 | 1096 | 1165 |
| 6 | GPT Image 1.5 (high) | OpenAI | 1131.9 | 1247 | 1242 | 896 | 1154 |
| 7 | nano-banana-2 | 1128.1 | 1169 | 1242 | 1050 | 1051 | |
| 8 | Grok Imagine Image 2.0 | SpaceXAI | 1107.5 | 1128 | 1086 | 1076 | 1155 |
| 9 | Muse Image | Meta | 1096.3 | 1171 | 1108 | 1062 | 1034 |
| 10 | Qwen-Image-3.0 | Alibaba Cloud | 1083.1 | 1110 | 1205 | 972 | 1031 |
| 11 | nano-banana-pro | 1071.6 | 1070 | 1044 | 1104 | 1049 | |
| 12 | Seedream 4.5 | ByteDance | 1046.7 | 1032 | 999 | 948 | 1220 |
| 13 | Grok Image Imagine 2.0 (Thinking) | SpaceXAI | 1045.6 | 1039 | 1087 | 1012 | 1038 |
| 14 | MAI-Image 2.5 | Microsoft AI | 1042.1 | 1060 | 1114 | 975 | 1015 |
| 15 | Imagen 4 Ultra | 1025.9 | 1057 | 1106 | 869 | 1081 | |
| 16 | Seedream 5.0 Lite | ByteDance | 1013.7 | 1027 | 896 | 957 | 1183 |
| 17 | FLUX.2 flex | Black Forest Labs | 1011.0 | 1034 | 1036 | 872 | 1104 |
| 18 | Grok Imagine Image (quality) | SpaceXAI | 1009.7 | 1139 | 1034 | 880 | 980 |
| 19 | Wan 2.7 Pro | Alibaba Cloud | 1007.6 | 1018 | 1038 | 987 | 981 |
| 20 | FLUX.2 pro | Black Forest Labs | 1003.4 | 1015 | 946 | 990 | 1061 |
| 21 | Seedream 5.0 Pro | ByteDance | 992.9 | 1005 | 1076 | 1016 | 858 |
| 22 | FLUX.2 max | Black Forest Labs | 992.8 | 992 | 932 | 975 | 1071 |
| 23 | Qwen-Image | Alibaba Cloud | 991.7 | 933 | 1129 | 1003 | 888 |
| 24 | Grok Imagine Image | SpaceXAI | 988.6 | 1038 | 1016 | 866 | 1031 |
| 25 | HiDream O1 | HiDream AI | 988.2 | 1043 | 1101 | 871 | 928 |
| 26 | Qwen-Image 2.0 Pro | Alibaba Cloud | 986.3 | 1005 | 920 | 939 | 1087 |
| 27 | Ideogram 4.5 Quality | Ideogram | 967.6 | 851 | 821 | 1136 | 1006 |
| 28 | Recraft V4.1 Utility Pro | Recraft | 953.3 | 983 | 890 | 1004 | 925 |
| 29 | FLUX.2 dev | Black Forest Labs | 945.7 | 1016 | 936 | 911 | 910 |
| 30 | Imagen 3 | 939.3 | 912 | 1014 | 964 | 823 | |
| 31 | Imagen 4 | 934.7 | 879 | 1036 | 901 | 903 | |
| 32 | Imagen 4 Fast | 930.2 | 893 | 946 | 953 | 914 | |
| 33 | FLUX.2 klein 9B | Black Forest Labs | 925.3 | 950 | 905 | 992 | 837 |
| 34 | HunyuanImage 3.0 | Tencent | 924.8 | 989 | 1130 | 767 | 788 |
| 35 | Ideogram 4.0 Quality | Ideogram | 911.9 | 817 | 800 | 1100 | 911 |
| 36 | ERNIE Image | Baidu | 896.9 | 860 | 1145 | 694 | 846 |
| 37 | Pruna-P-Ideogram (High) | Pruna AI | 894.9 | 767 | 789 | 1101 | 891 |
| 38 | Pruna P-Image | Pruna AI | 890.2 | 634 | 874 | 1130 | 884 |
| 39 | Pruna-P-Ideogram (Low) | Pruna AI | 870.7 | 769 | 714 | 1105 | — |
| 40 | Pruna-P-Ideogram (Medium) | Pruna AI | 867.9 | 744 | 695 | 1137 | — |
| 41 | Luma UNI 1.1 Max | Luma Labs | 846.1 | 820 | 619 | 1014 | 872 |
| 42 | Pruna-P-Ideogram (Very Low) | Pruna AI | 844.3 | 753 | 683 | 1076 | — |
| 43 | Stable Diffusion 3.5 Large | Stability AI | 794.4 | 780 | 868 | 862 | 627 |
A model shows "—" where it has no standing on that leaderboard.
By output type and capability
OpenAI's GPT Image 2.5 tops every category the benchmark slices by, so the last column shows the strongest model from any other lab. The full per-category standings, including subject and prompt source, are on Benchmark.ai.
| Output type | Prompts | #1 overall (ELO) | Best non-OpenAI model (ELO) |
|---|---|---|---|
| General Image | 524 | GPT Image 2.5 (Sunburst) (1265) | Reve 2.1 — Reve AI (1151) |
| Photorealism | 243 | GPT Image 2.5 (Flare) (1242) | Reve 2.1 — Reve AI (1141) |
| UI / UX | 182 | GPT Image 2.5 (Sunburst) (1213) | Muse Image — Meta (1174) |
| Illustration & Anime | 147 | GPT Image 2.5 (Sunburst) (1237) | Reve 2.1 — Reve AI (1161) |
| Graphic Design & Marketing | 137 | GPT Image 2.5 (Sunburst) (1249) | Reve 2.1 — Reve AI (1222) |
| Logos & Branding | 134 | GPT Image 2.5 (Flare) (1209) | nano-banana-2 — Google (1151) |
| Infographics | 131 | GPT Image 2.5 (Sunburst) (1235) | nano-banana-2 — Google (1154) |
| 3D Modeling & Rendering | 19 | GPT Image 2.5 (Sunburst) (1270) | Qwen-Image-3.0 — Alibaba Cloud (1176) |
| Capability | Prompts | #1 overall (ELO) | Best non-OpenAI model (ELO) |
|---|---|---|---|
| Attribute Binding | 758 | GPT Image 2.5 (Sunburst) (1214) | Reve 2.1 — Reve AI (1153) |
| Text | 616 | GPT Image 2.5 (Sunburst) (1236) | Reve 2.1 — Reve AI (1159) |
| Scene Composition | 428 | GPT Image 2.5 (Flare) (1230) | Reve 2.1 — Reve AI (1163) |
| Knowledge & Reasoning | 384 | GPT Image 2.5 (Sunburst) (1227) | nano-banana-2 — Google (1141) |
| Spatial & Size | 264 | GPT Image 2.5 (Sunburst) (1228) | Reve 2.1 — Reve AI (1129) |
| Number of Objects | 252 | GPT Image 2.5 (Sunburst) (1265) | Reve 2.1 — Reve AI (1169) |
| Surreal | 244 | GPT Image 2.5 (Flare) (1206) | nano-banana-2 — Google (1142) |
| Emotion & Mood | 130 | GPT Image 2.5 (Sunburst) (1254) | Reve 2.1 — Reve AI (1177) |
| Noisy Input | 20 | GPT Image 2.5 (Sunburst) (1377) | Grok Image Imagine 2.0 (Medium) — SpaceXAI (1238) |
How the dataset was built
1. Prompts (1,514)
The prompts are drawn from established text-to-image evaluation sets, real user prompts and prompts written for this benchmark:
| Source | Prompts |
|---|---|
| Rapidata Original | 328 |
| DiffusionDB | 325 |
| PartiPrompts | 243 |
| Community | 235 |
| MONET | 187 |
| DrawBench | 87 |
| ABC-6K | 40 |
| T2I-CompBench | 31 |
| DALLE3-EVAL | 20 |
| HRS-Bench | 18 |
Every prompt is tagged on three more axes, which the live leaderboard can slice by:
- Capability — attribute binding, text, scene composition, knowledge & reasoning, spatial & size, number of objects, surreal, emotion & mood, noisy input (a prompt can carry several)
- Output type — general image, photorealism, UI / UX, illustration & anime, graphic design & marketing, logos & branding, infographics, 3D modeling & rendering
- Subject — objects & abstract, people & portraits, animals, architecture & spaces, vehicles, sci-fi & fantasy, food & drink, nature & landscapes
2. Image generation (43 models)
Each prompt was sent to every model, and the resulting images were uploaded to a Rapidata MRI benchmark as one participant per model. Every model has images for between 1,410 and 1,514 of the 1,514 prompts.
Alibaba Cloud — Qwen-Image, Qwen-Image 2.0 Pro, Qwen-Image-3.0, Wan 2.7 Pro · Baidu — ERNIE Image · Black Forest Labs — FLUX.2 dev, FLUX.2 flex, FLUX.2 klein 9B, FLUX.2 max, FLUX.2 pro · ByteDance — Seedream 4.5, Seedream 5.0 Lite, Seedream 5.0 Pro · Google — Imagen 3, Imagen 4, Imagen 4 Fast, Imagen 4 Ultra, nano-banana-2, nano-banana-pro · HiDream AI — HiDream O1 · Ideogram — Ideogram 4.0 Quality, Ideogram 4.5 Quality · Luma Labs — Luma UNI 1.1 Max · Meta — Muse Image · Microsoft AI — MAI-Image 2.5 · OpenAI — GPT Image 1.5 (high), GPT Image 2.0, GPT Image 2.5 (Flare), GPT Image 2.5 (Sunburst) · Pruna AI — Pruna P-Image, Pruna-P-Ideogram (High), Pruna-P-Ideogram (Low), Pruna-P-Ideogram (Medium), Pruna-P-Ideogram (Very Low) · Recraft — Recraft V4.1 Utility Pro · Reve AI — Reve 2.1 · SpaceXAI — Grok Image Imagine 2.0 (Medium), Grok Image Imagine 2.0 (Thinking), Grok Imagine Image, Grok Imagine Image (quality), Grok Imagine Image 2.0 · Stability AI — Stable Diffusion 3.5 Large · Tencent — HunyuanImage 3.0
3. Human evaluation
The four leaderboards were run over pairwise matchups between the models' images for the same prompt. Alignment,
Coherence and Text coherence were answered by dedicated, qualified Rapidata audiences; Preference by the open global
pool. Each pair is judged on a subset of the questions, with at least 5 votes per question it was judged on; Text
coherence runs only on the 616 text prompts. Per-annotator detail — chosen side, country, language, gender, age
bucket, occupation and the annotator's userScore — is preserved in the detailed_results_* columns. Votes came from
annotators in 148 countries.
Dataset structure
One row per head-to-head image pair generated from the same prompt.
| Column | Type | Description |
|---|---|---|
prompt | string | the prompt both images were generated from |
image1 | string | public URL of the image from model1 |
image2 | string | public URL of the image from model2 |
model1 | string | name of the model that produced image1 |
model2 | string | name of the model that produced image2 |
weighted_results_image1_<q> | float32 | sum of the userScore weights of the votes for image1 on question <q> |
weighted_results_image2_<q> | float32 | sum of the userScore weights of the votes for image2 on question <q> |
detailed_results_<q> | string | every vote on question <q> as a JSON array (votedFor is A for image1 and B for image2, plus annotator demographics, userScore and votedAt) |
<q> is one of alignment, preference, coherence and text_coherence. A row's columns for a question it was
not judged on are empty.
- The
weighted_results_*values are userScore-weighted vote sums, not probabilities — they do not sum to 1. Divide by their sum for a normalised win share. - Coherence and Text coherence are already flipped. Annotators were asked which image has more glitches, but in
this dataset
votedForandweighted_results_*point to the image with fewer glitches, so a higher value is better on every question.
import json
from datasets import load_dataset

ds = load_dataset("Rapidata/benchmark-ai-image-benchmark", split="train")
row = ds[0]
print(row["prompt"], "|", row["model1"], "vs", row["model2"])

for q in ["alignment", "preference", "coherence", "text_coherence"]:
    w1, w2 = row[f"weighted_results_image1_{q}"], row[f"weighted_results_image2_{q}"]
    if w1 is None or w1 + w2 == 0:
        continue  # this pair was not judged on q
    print(f"{q}: {row['model1']} wins {w1 / (w1 + w2):.0%} of the weighted vote")
Licensing & attribution
This dataset combines material under different terms:
- Prompts. Prompts taken from public evaluation sets (PartiPrompts, DrawBench, DiffusionDB, MONET, T2I-CompBench, HRS-Bench, ABC-6K, DALLE3-EVAL) remain under their original licenses; Rapidata-original and community prompts are released under CC-BY-4.0.
- Generated images. Produced by third-party models. Model outputs are governed by the terms of use of each respective model provider.
- Human annotations. Collected via Rapidata, released under CC-BY-4.0.
About Rapidata
Rapidata's technology makes collecting human feedback at scale faster and more accessible than ever before. Visit rapidata.ai to learn more about how we're revolutionizing human feedback collection for AI development.
Explore all of our live benchmarks on Benchmark.ai.
Related datasets
- Rapidata/svg-benchmark — the same three core questions for SVGs generated by frontier LLMs.
- Rapidata/camera-movement and Rapidata/relative-camera-movement — camera control in image-to-video models.