This dataset consists of meta information (including the repository name and file path) of the raw code data from RefineCode. You can collect those files referring to this metadata and reproduce RefineCode!
33
11 commits
1 linked in READMEs
updated Nov 15, 2024
This dataset consists of meta information (including the repository name and file path) of the raw code data from RefineCode. You can collect those files referring to this metadata and reproduce RefineCode!
Note: Currently, we have uploaded the meta data covered by The Stack V2 (About 50% file volume). Due to complex legal considerations, we are unable to provide the complete source code currently. We are working hard to make the remaining part available.
RefineCode is a high-quality, reproducible code pretraining corpus comprising 960 billion tokens across 607 programming languages and 75 billion code-related token recalled from web corpus, incorporating over 130 language-specific rules with customized weight assignments. Our dataset shows better training efficacy and efficiency compared with the training subset of The Stack V2.
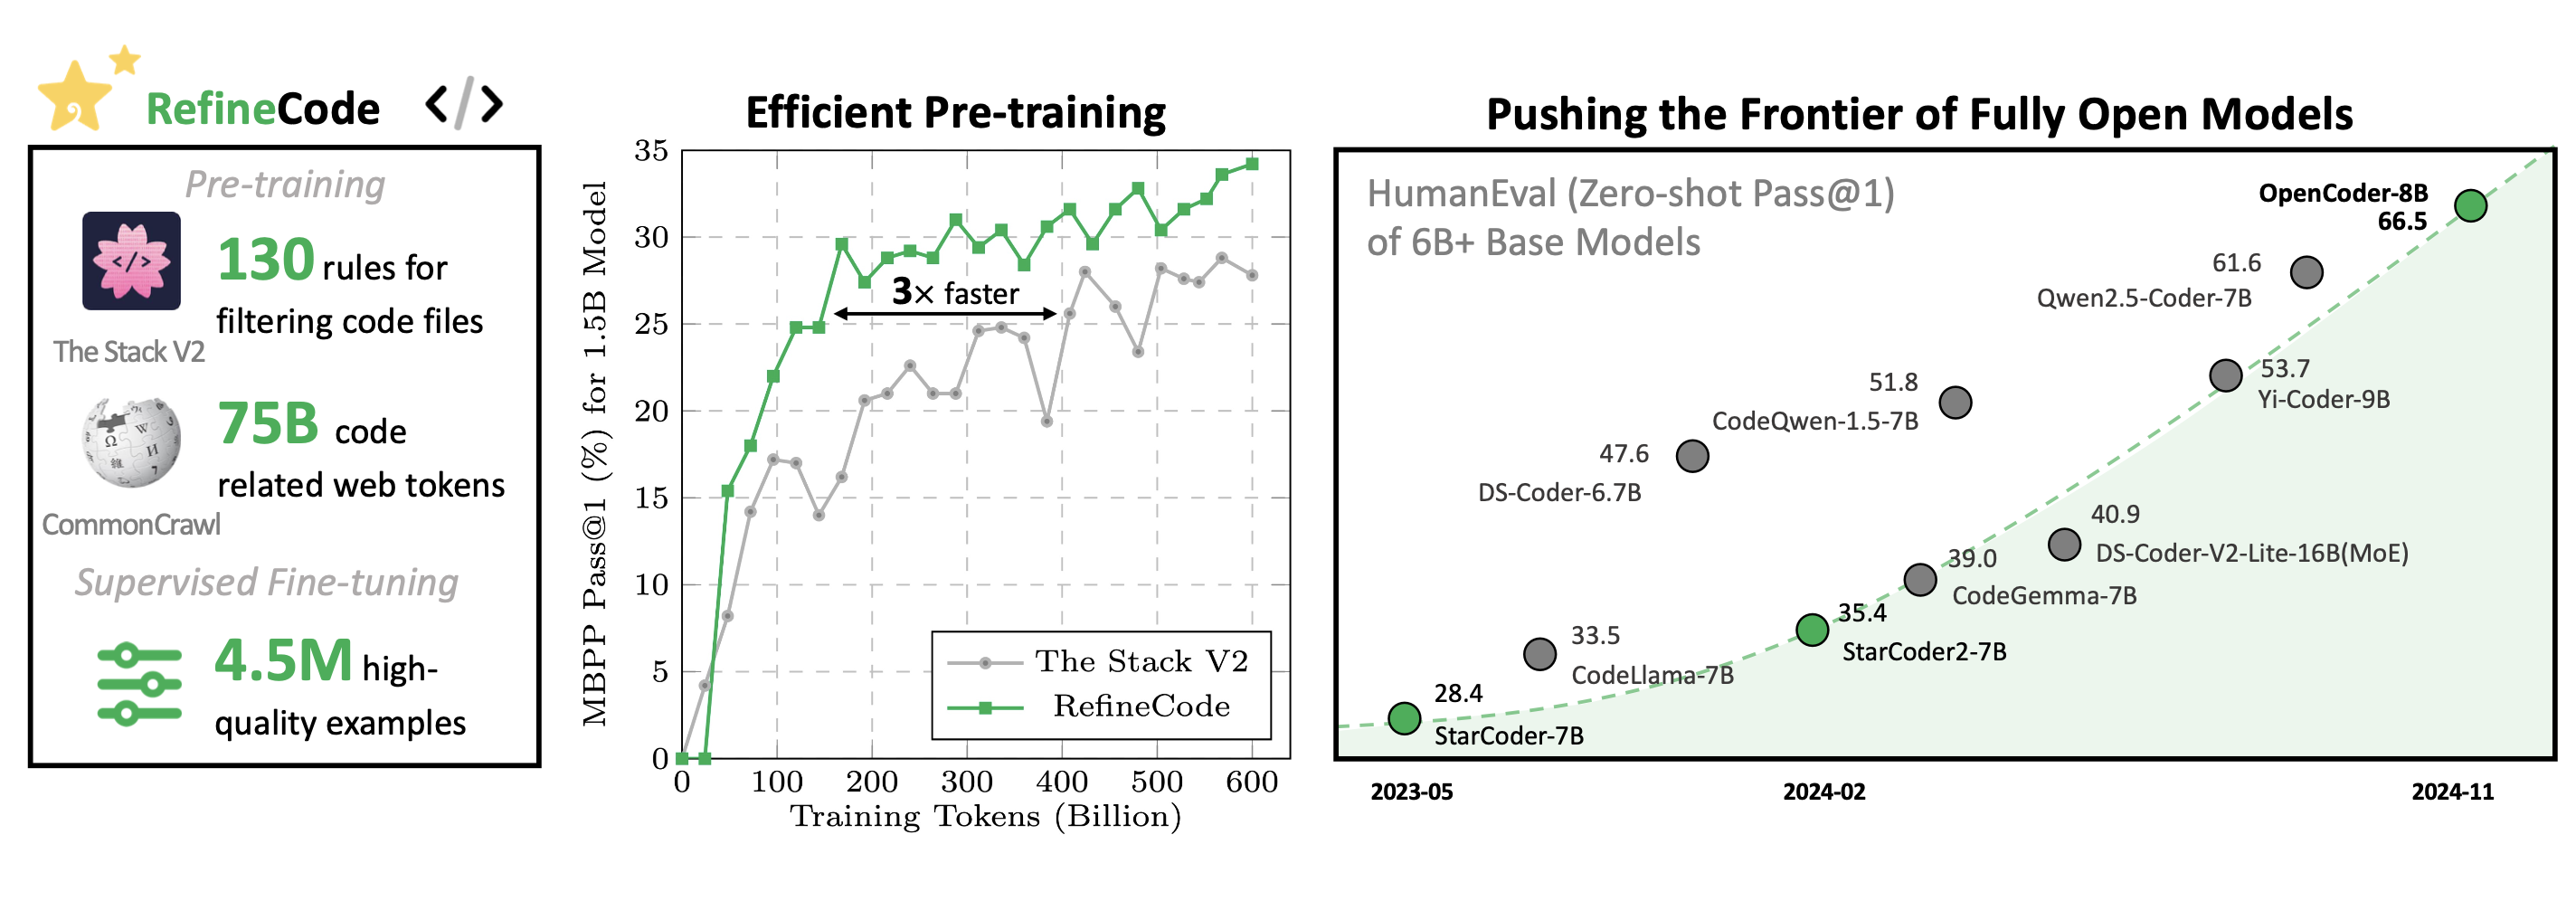
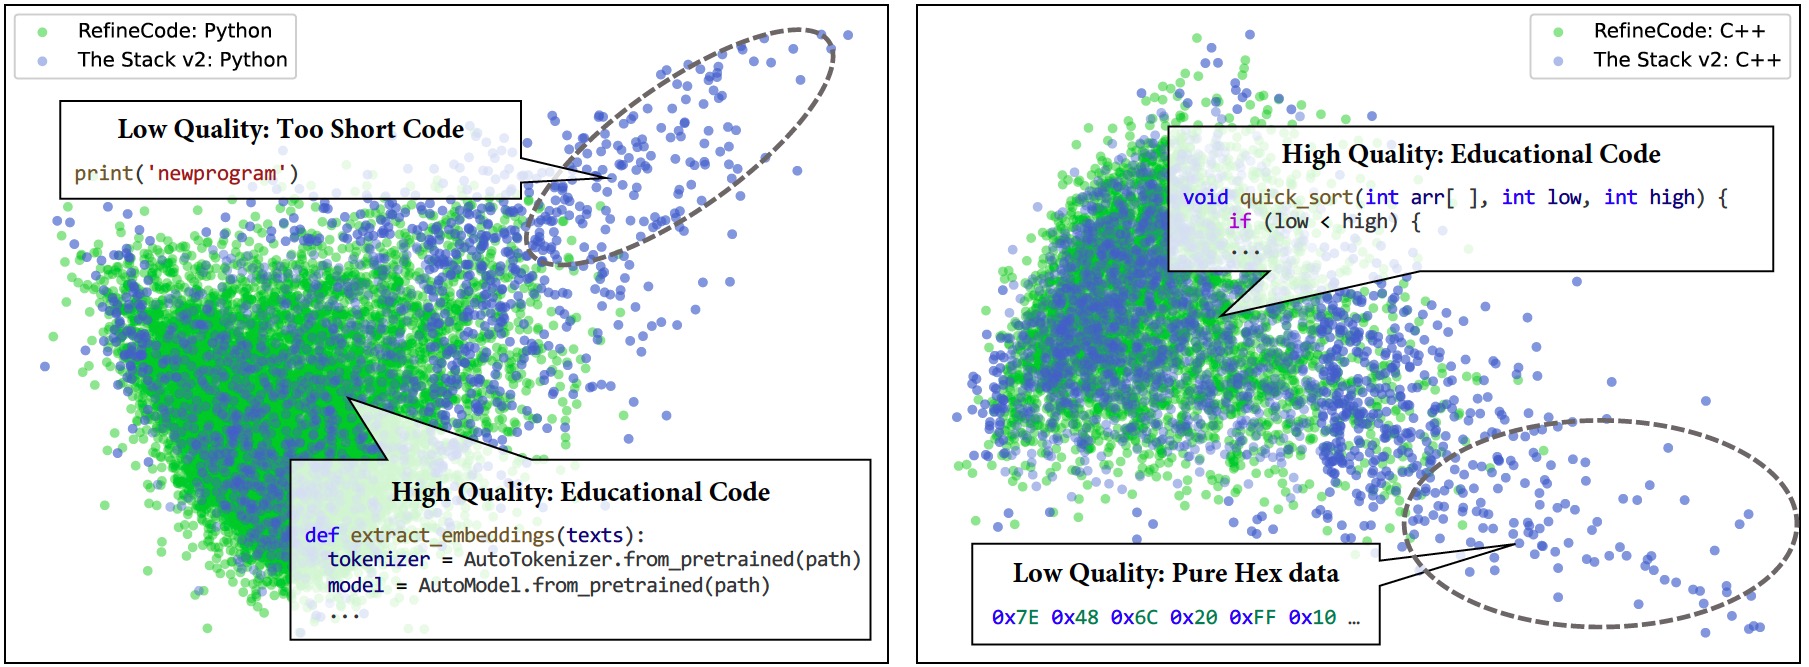
We also use PCA to visualize the embeddings extracted from CodeBERT for The Stack V2 and RefineCode, showing a clear advance of our pretraining dataset.
This dataset consists of meta information (including the repository name and file path) of the raw code data from RefineCode. You can collect those files referring to this metadata and reproduce RefineCode!
33
11 commits
1 linked in READMEs
updated Nov 15, 2024
This dataset consists of meta information (including the repository name and file path) of the raw code data from RefineCode. You can collect those files referring to this metadata and reproduce RefineCode!
Note: Currently, we have uploaded the meta data covered by The Stack V2 (About 50% file volume). Due to complex legal considerations, we are unable to provide the complete source code currently. We are working hard to make the remaining part available.
RefineCode is a high-quality, reproducible code pretraining corpus comprising 960 billion tokens across 607 programming languages and 75 billion code-related token recalled from web corpus, incorporating over 130 language-specific rules with customized weight assignments. Our dataset shows better training efficacy and efficiency compared with the training subset of The Stack V2.
We also use PCA to visualize the embeddings extracted from CodeBERT for The Stack V2 and RefineCode, showing a clear advance of our pretraining dataset.