Long-RL: Scaling RL to Long Sequences (Training, Validation and Test Dataset - for research only)
5
21 commits
6 linked in READMEs
updated Aug 19, 2025
README
Long-RL: Scaling RL to Long Sequences (Training, Validation and Test Dataset - for research only)


Data Distribution
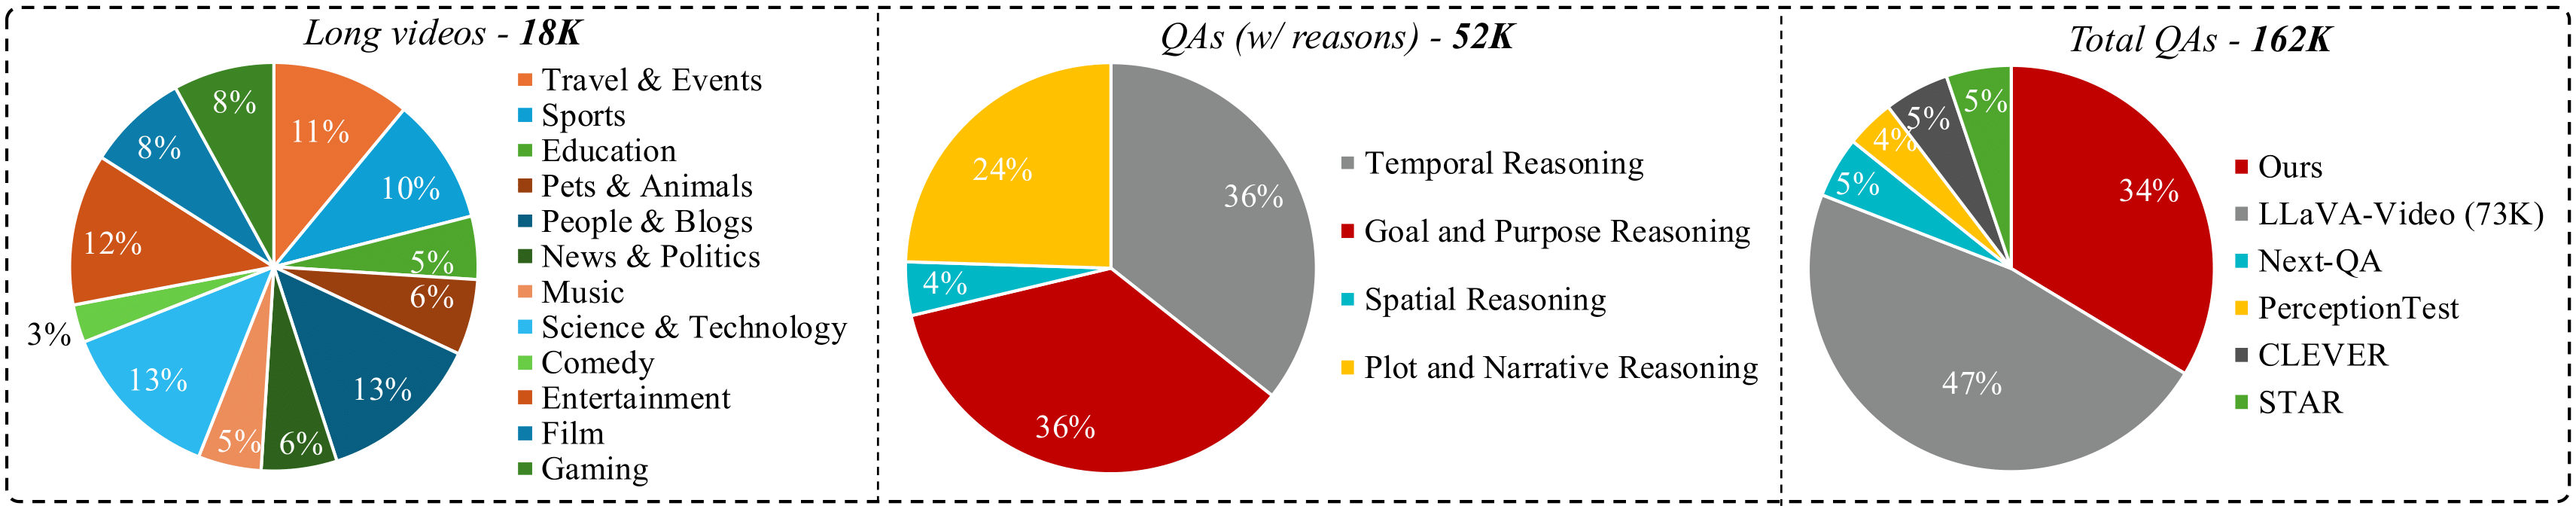
We strategically construct a high-quality dataset with CoT annotations for long video reasoning, named LongVideo-Reason. Leveraging a powerful VLM (NVILA-8B) and a leading open-source reasoning LLM, we develop a dataset comprising 52K high-quality Question-Reasoning-Answer pairs for long videos. We use 18K high-quality samples for Long-CoT-SFT to initialize the model's reasoning and instruction-following abilities, and 33K samples with an additional 110K video data for reinforcement learning. This two-stage training combines high-quality reasoning annotations with reinforcement learning, enabling LongVILA-R1 to achieve superior and generalized video reasoning. We also manually curate a balanced set of 1K long-video samples to build a new benchmark, LongVideo-Reason-eval, that evaluates performance from four perspectives: Temporal, Goal and Purpose, Spatial, and Plot and Narrative, for a comprehensive assessment.
LongVideo-Reason (Train, 52k) [Data Link]
LongVideo-Reason-eval (Test, 1k) [Data Link]
Installation
git clone https://github.com/NVlabs/Long-RL.git
cd Long-RL
pip install -e .
If you want to train Qwen-Omni models, please
bash vllm_replace.sh
Training
Single node
For single node (within 8 GPUs), you can refer to the training scripts in the examples directory. For example,
bash examples/new_supports/qwen2_5_vl_3b_video_grpo.sh $VIDEO_PATH
Multi-nodes
For jobs that requires multi-nodes, you can refer to the ways mentioned in the EasyR1 repo, here.
We provide additional examples for sbatch scripts like, where TRAIN_SCRIPT is the script to train on single node, NNODES is the number of nodes required.
bash scripts/srun_multi_nodes.sh $TRAIN_SCRIPT $NNODES
For example,
bash scripts/srun_multi_nodes.sh examples/new_supports/qwen2_5_vl_3b_video_grpo.sh 2
Merge Checkpoint in Hugging Face Format
This follows the ways in the EasyR1 repo.
python3 scripts/model_merger.py --local_dir checkpoints/easy_r1/exp_name/global_step_1/actor
Evaluation
We provide the instruction on evaluating models on our LongVideo-Reason benchmark in the eval directory.
How to contribute
- Make sure to have git installed.
- Create your own fork of the project.
- Clone the repository on your local machine, using git clone and pasting the url of this project.
- Read both the
Installationsections above. - Commit and push your changes.
- Make a pull request when finished modifying the project.
Core Contributors
Yukang Chen, Wei Huang, Shuai Yang, Qinghao Hu, Baifeng Shi, Hanrong Ye, Ligeng Zhu.
We welcome all possible contributions and will acknowledge all contributors clearly.
Citation
Please consider to cite our paper and this framework, if they are helpful in your research.
@misc{long-rl,
  title = {Long-RL: Scaling RL to Long Sequences},
  author = {Yukang Chen, Wei Huang, Shuai Yang, Qinghao Hu, Baifeng Shi, Hanrong Ye, Ligeng Zhu, Zhijian Liu, Pavlo Molchanov, Jan Kautz, Xiaojuan Qi, Sifei Liu,Hongxu Yin, Yao Lu, Song Han},
  year = {2025},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/NVlabs/Long-RL}},
}
@article{chen2025longvila-r1,
      title={Scaling RL to Long Videos},
      author={Yukang Chen and Wei Huang and Baifeng Shi and Qinghao Hu and Hanrong Ye and Ligeng Zhu and Zhijian Liu and Pavlo Molchanov and Jan Kautz and Xiaojuan Qi and Sifei Liu and Hongxu Yin and Yao Lu and Song Han},
      year={2025},
      eprint={2507.07966},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@inproceedings{chen2024longvila,
      title={LongVILA: Scaling Long-Context Visual Language Models for Long Videos},
      author={Yukang Chen and Fuzhao Xue and Dacheng Li and Qinghao Hu and Ligeng Zhu and Xiuyu Li and Yunhao Fang and Haotian Tang and Shang Yang and Zhijian Liu and Ethan He and Hongxu Yin and Pavlo Molchanov and Jan Kautz and Linxi Fan and Yuke Zhu and Yao Lu and Song Han},
      booktitle={The International Conference on Learning Representations (ICLR)},
      year={2025},
}
Acknowledgement
- EasyR1: the codebase we built upon. Thanks for their wonderful work.
- verl: the RL training framework we built upon.
- vllm: we built upon vllm for the rollout engine.
- Flow-GRPO: we refer to the Flow-GRPO for the image/video generation RL part.
- Shot2story: we curate 18K long videos from the Shot2Story.
Contributors
21 commits
Similar repos



Linked in READMEs


Long-RL: Scaling RL to Long Sequences (Training, Validation and Test Dataset - for research only)
5
21 commits
6 linked in READMEs
updated Aug 19, 2025
README
Long-RL: Scaling RL to Long Sequences (Training, Validation and Test Dataset - for research only)
Data Distribution
We strategically construct a high-quality dataset with CoT annotations for long video reasoning, named LongVideo-Reason. Leveraging a powerful VLM (NVILA-8B) and a leading open-source reasoning LLM, we develop a dataset comprising 52K high-quality Question-Reasoning-Answer pairs for long videos. We use 18K high-quality samples for Long-CoT-SFT to initialize the model's reasoning and instruction-following abilities, and 33K samples with an additional 110K video data for reinforcement learning. This two-stage training combines high-quality reasoning annotations with reinforcement learning, enabling LongVILA-R1 to achieve superior and generalized video reasoning. We also manually curate a balanced set of 1K long-video samples to build a new benchmark, LongVideo-Reason-eval, that evaluates performance from four perspectives: Temporal, Goal and Purpose, Spatial, and Plot and Narrative, for a comprehensive assessment.
LongVideo-Reason (Train, 52k) [Data Link]
LongVideo-Reason-eval (Test, 1k) [Data Link]
Installation
git clone https://github.com/NVlabs/Long-RL.git
cd Long-RL
pip install -e .
If you want to train Qwen-Omni models, please
bash vllm_replace.sh
Training
Single node
For single node (within 8 GPUs), you can refer to the training scripts in the examples directory. For example,
bash examples/new_supports/qwen2_5_vl_3b_video_grpo.sh $VIDEO_PATH
Multi-nodes
For jobs that requires multi-nodes, you can refer to the ways mentioned in the EasyR1 repo, here.
We provide additional examples for sbatch scripts like, where TRAIN_SCRIPT is the script to train on single node, NNODES is the number of nodes required.
bash scripts/srun_multi_nodes.sh $TRAIN_SCRIPT $NNODES
For example,
bash scripts/srun_multi_nodes.sh examples/new_supports/qwen2_5_vl_3b_video_grpo.sh 2
Merge Checkpoint in Hugging Face Format
This follows the ways in the EasyR1 repo.
python3 scripts/model_merger.py --local_dir checkpoints/easy_r1/exp_name/global_step_1/actor
Evaluation
We provide the instruction on evaluating models on our LongVideo-Reason benchmark in the eval directory.
How to contribute
- Make sure to have git installed.
- Create your own fork of the project.
- Clone the repository on your local machine, using git clone and pasting the url of this project.
- Read both the
Installationsections above. - Commit and push your changes.
- Make a pull request when finished modifying the project.
Core Contributors
Yukang Chen, Wei Huang, Shuai Yang, Qinghao Hu, Baifeng Shi, Hanrong Ye, Ligeng Zhu.
We welcome all possible contributions and will acknowledge all contributors clearly.
Citation
Please consider to cite our paper and this framework, if they are helpful in your research.
@misc{long-rl,
  title = {Long-RL: Scaling RL to Long Sequences},
  author = {Yukang Chen, Wei Huang, Shuai Yang, Qinghao Hu, Baifeng Shi, Hanrong Ye, Ligeng Zhu, Zhijian Liu, Pavlo Molchanov, Jan Kautz, Xiaojuan Qi, Sifei Liu,Hongxu Yin, Yao Lu, Song Han},
  year = {2025},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/NVlabs/Long-RL}},
}
@article{chen2025longvila-r1,
      title={Scaling RL to Long Videos},
      author={Yukang Chen and Wei Huang and Baifeng Shi and Qinghao Hu and Hanrong Ye and Ligeng Zhu and Zhijian Liu and Pavlo Molchanov and Jan Kautz and Xiaojuan Qi and Sifei Liu and Hongxu Yin and Yao Lu and Song Han},
      year={2025},
      eprint={2507.07966},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@inproceedings{chen2024longvila,
      title={LongVILA: Scaling Long-Context Visual Language Models for Long Videos},
      author={Yukang Chen and Fuzhao Xue and Dacheng Li and Qinghao Hu and Ligeng Zhu and Xiuyu Li and Yunhao Fang and Haotian Tang and Shang Yang and Zhijian Liu and Ethan He and Hongxu Yin and Pavlo Molchanov and Jan Kautz and Linxi Fan and Yuke Zhu and Yao Lu and Song Han},
      booktitle={The International Conference on Learning Representations (ICLR)},
      year={2025},
}
Acknowledgement
- EasyR1: the codebase we built upon. Thanks for their wonderful work.
- verl: the RL training framework we built upon.
- vllm: we built upon vllm for the rollout engine.
- Flow-GRPO: we refer to the Flow-GRPO for the image/video generation RL part.
- Shot2story: we curate 18K long videos from the Shot2Story.
Similar repos
Linked in READMEs
Contributors
21 commits