Declarative AI pipelines in one YAML file. Tokens, audio chunks, and video frames flow between isolated components. Compose 100+ components for models, agents, speech, vision, and live broadcast. Run local models, cloud APIs, or both. Inspired by docker-compose.
Python
119
2,347 commits
updated Oct 17, 2026
One YAML file. Any model. Any protocol. Any runtime.
Build chat APIs, RAG pipelines, autonomous agents, and MCP servers without writing orchestration code — then run the same definition anywhere, like docker-compose.
AI systems shouldn't be locked into a single provider, runtime, or cloud. model-compose is built on four principles:
Install with uv:
uv pip install model-compose
Or with pip:
pip install model-compose
Create model-compose.yml:
controller:
  adapter:
    type: http-server
    port: 8080
  webui:
    port: 8081

workflow:
  job:
    component: chatgpt
    input:
      prompt: ${input.prompt}
    output: ${output as stream/text}

component:
  id: chatgpt
  type: http-client
  base_url: https://api.openai.com/v1
  action:
    path: /chat/completions
    method: POST
    headers:
      Authorization: Bearer ${env.OPENAI_API_KEY}
      Content-Type: application/json
    body:
      model: gpt-4o
      messages:
        - role: user
          content: ${input.prompt}
      stream: true
    stream_format: json
    output: ${response[].choices[0].delta.content}
Run it:
export OPENAI_API_KEY=your-key
model-compose up
That's it. You're serving GPT-4o at http://localhost:8080 with a web UI at http://localhost:8081. No application code. No framework boilerplate. Same file runs locally, in Docker, or in production.
Every workflow gets a browser UI for free — inputs, outputs, streaming, and file uploads are inferred from the schema. Two lines of YAML, no frontend code.
controller:
  webui:
    driver: gradio
    port: 8081
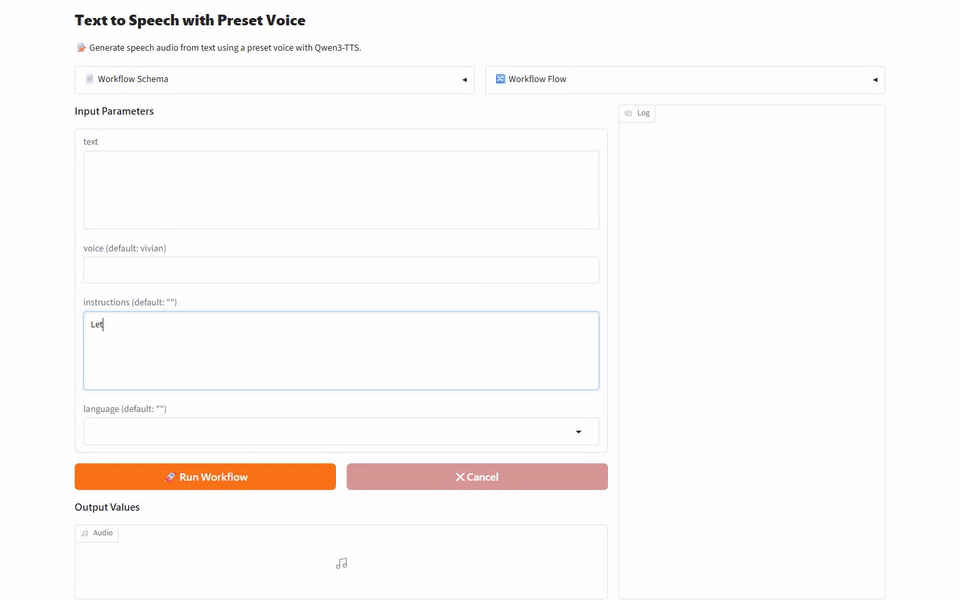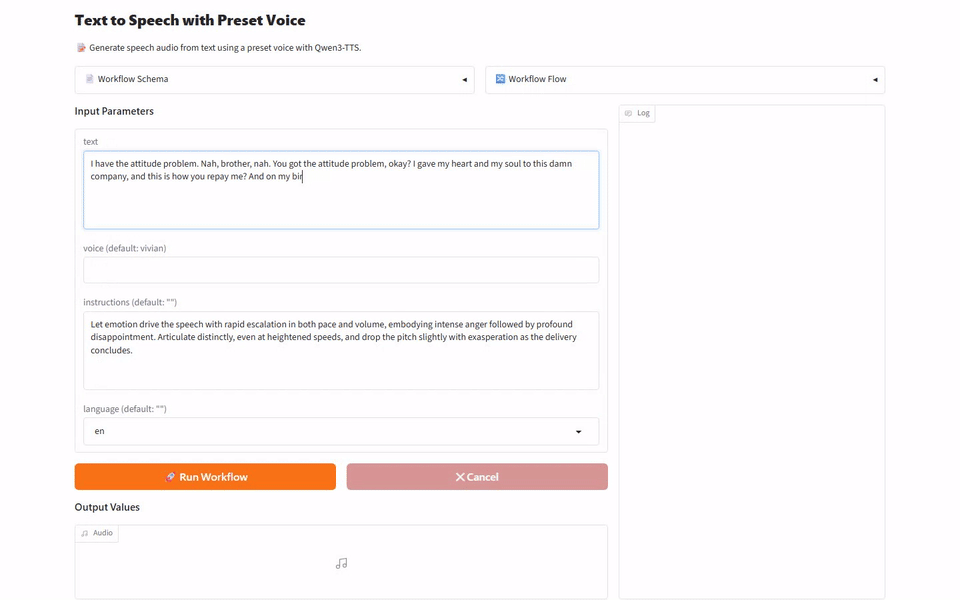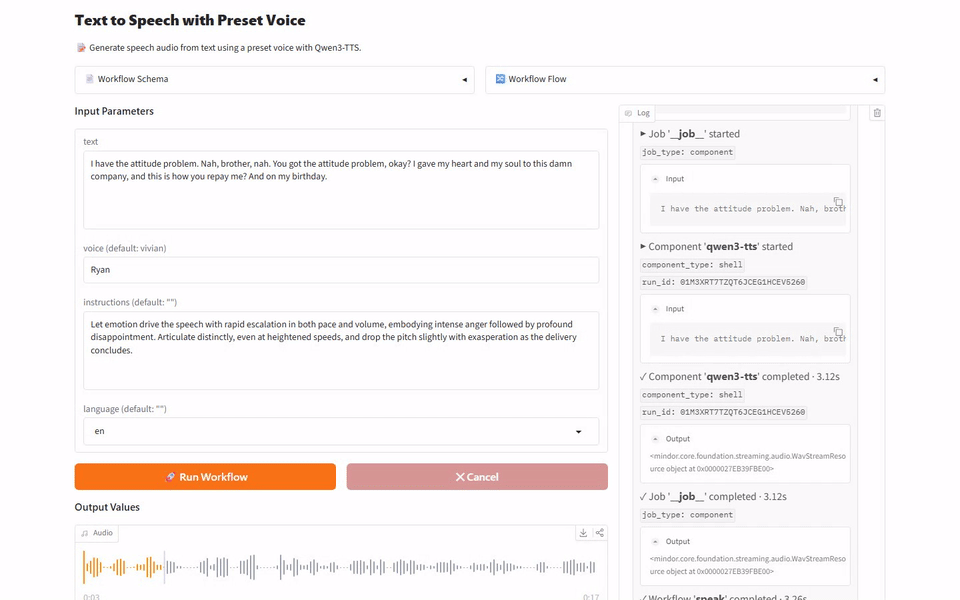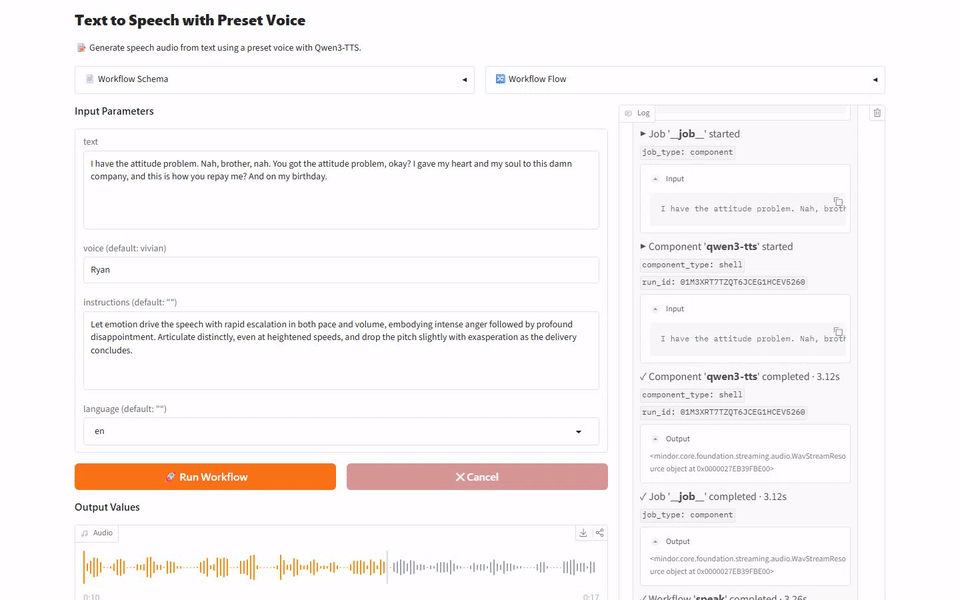
Perfect for iteration, demos, and sharing a workflow with non-engineers before wiring it into production.
Here's what a single YAML file can serve today — just a few examples.
Build a ReAct agent that plans, uses tools, and completes multi-step tasks — declaratively.
component:
  id: research-agent
  type: agent
  tools: [search-web, fetch-page]
  max_iteration_count: 10
  action:
    model:
      component: chatgpt
    system_prompt: You are a web research assistant.
    user_prompt: ${input.question}
See simple agents like a code reviewer, a RAG assistant, and a web researcher in agents/.
Run open-weight models on your own hardware with PyTorch, vLLM, or llama.cpp — same YAML surface as cloud APIs, no SDK code.
component:
  type: model
  task: chat-completion
  model: HuggingFaceTB/SmolLM3-3B
  action:
    messages:
      - role: system
        content: ${input.system_prompt}
      - role: user
        content: ${input.user_prompt}
Point model: at any Hugging Face repo, or a local GGUF file via llama.cpp. Browse local chat, embedding, TTS, VLM, image/audio/video tasks under model-tasks/.
Compose embedding, vector search, and generation into a single workflow — no glue code.
workflow:
  jobs:
    - id: embed
      component: embedder
      input: { text: ${input.query} }

    - id: retrieve
      component: knowledge
      action: search
      input: { vector: ${jobs.embed.output} }

    - id: answer
      component: chatgpt
      input:
        context: ${jobs.retrieve.output}
        question: ${input.query}
Native drivers ship for Chroma, Milvus, Qdrant, FAISS, Neo4j, ArangoDB, and Redis.
Chain audio, video, and image stages across models and native codecs — swap any step without touching the rest.
workflow:
  jobs:
    - id: extract-audio
      component: audio-extractor
      input: { source: ${input.video as video} }

    - id: transcribe
      component: whisper
      input: { audio: ${jobs.extract-audio.output} }

    - id: translate
      component: translator
      input: { text: ${jobs.transcribe.output} }

    - id: dub
      component: tts
      input: { text: ${jobs.translate.output} }

    - id: lip-sync
      component: wav2lip
      input:
        video: ${input.video as video}
        audio: ${jobs.dub.output as audio/wav}
      output: ${output as video/mp4}
See full video dubbing, scene detection, voice cloning, and face mosaic pipelines in media-processing/.
Stream tokens, audio chunks, and video frames end-to-end — first-class across every stage.
workflow:
  job:
    component: chatgpt
    output: ${output as sse-text}

component:
  id: chatgpt
  type: http-client
  action:
    body: { stream: true, ... }
    stream_format: json
    output: ${response[].choices[0].delta.content}
Real-time TTS, video-to-frames, and live chat examples live under data-streaming/ and showcase/.
Turn any workflow into an MCP server that Claude, ChatGPT, or Cursor can use — one line change.
controller:
  adapter:
    type: mcp-server   # ← was: http-server
    port: 8080
Full examples live in mcp-servers/, including a Slack bot MCP.
The same YAML that runs on your laptop scales without a rewrite.
model-compose up
Runs on your machine with a Gradio web UI at :8081 — perfect for iteration.
Add a runtime: block. Same file, same behavior:
controller:
  runtime:
    type: docker
    image: my-ai-service:latest
    ports: [ "8080:8080" ]
Add a queue. Dispatchers accept jobs, subscribers process them across N machines:
controller:
  adapter: { type: http-server, port: 8080 }
  queue:
    driver: redis
    host: redis.internal
    name: my-queue
No shared filesystem. No code changes. Just add more subscribers to scale.
| model-compose | Managed APIs (OpenAI, etc.) | Code Frameworks (LangChain, etc.) | |
|---|---|---|---|
| Time to first API | Minutes (one YAML) | Hours (SDK + server code) | Days (framework + integration) |
| Provider Coupling | Multi-provider via config | Single provider per SDK | Multi-provider via abstractions |
| Code Coupling | Declarative YAML — no application code | Application code required | Framework-specific code required |
| Infrastructure Control | Full Sovereignty | Provider-controlled | Heavy Abstraction |
| Runtime Flexibility | Hybrid-First (Local + Cloud) | Cloud Only | Complex to customize |
| Protocol Support | HTTP / WebSocket / MCP | Provider-specific | Limited |
| Data Streaming | First-class across all stages | Response-only (SSE tokens) | Framework-wrapped generators |
| Deployment | Docker / Native / Virtualenv / Process | Provider-managed | Manual integration |
Browse examples by category:
| Category | What's inside |
|---|---|
agents/ | Code reviewer, RAG assistant, Web researcher, Web page analyzer, ... |
showcase/ | End-to-end pipelines: disk analysis, face-based scene search, real-time TTS |
model-providers/ | OpenAI, Anthropic, xAI, Google, ElevenLabs, vLLM |
model-tasks/ | Local chat, embedding, TTS, VLM, face embedding, ... |
media-processing/ | Audio/video/image processing: extraction, conversion, scene detection |
media-broadcast/ | Live broadcasting pipelines (e.g. YouTube Live over RTMP) |
web-automation/ | Web scraping, headless browser automation, page capture |
text-processing/ | Text chunking and preprocessing |
mcp-servers/ | Build MCP servers exposed to Claude, Cursor, ChatGPT |
workflow-queue/ | Redis-backed distributed dispatch (streaming + non-streaming) |
data-streaming/ | Video-to-frames, YouTube live chat, streaming inputs |
job-flow/ | Workflow control: conditional routing, hooks, interrupts |
integrations/ | Vector/graph/KV stores, search engines, channels, tunnels |
runtime/ | Component execution runtimes: Docker, Apple Container, virtualenv, ... |
Browse the full catalog in examples/README.md.
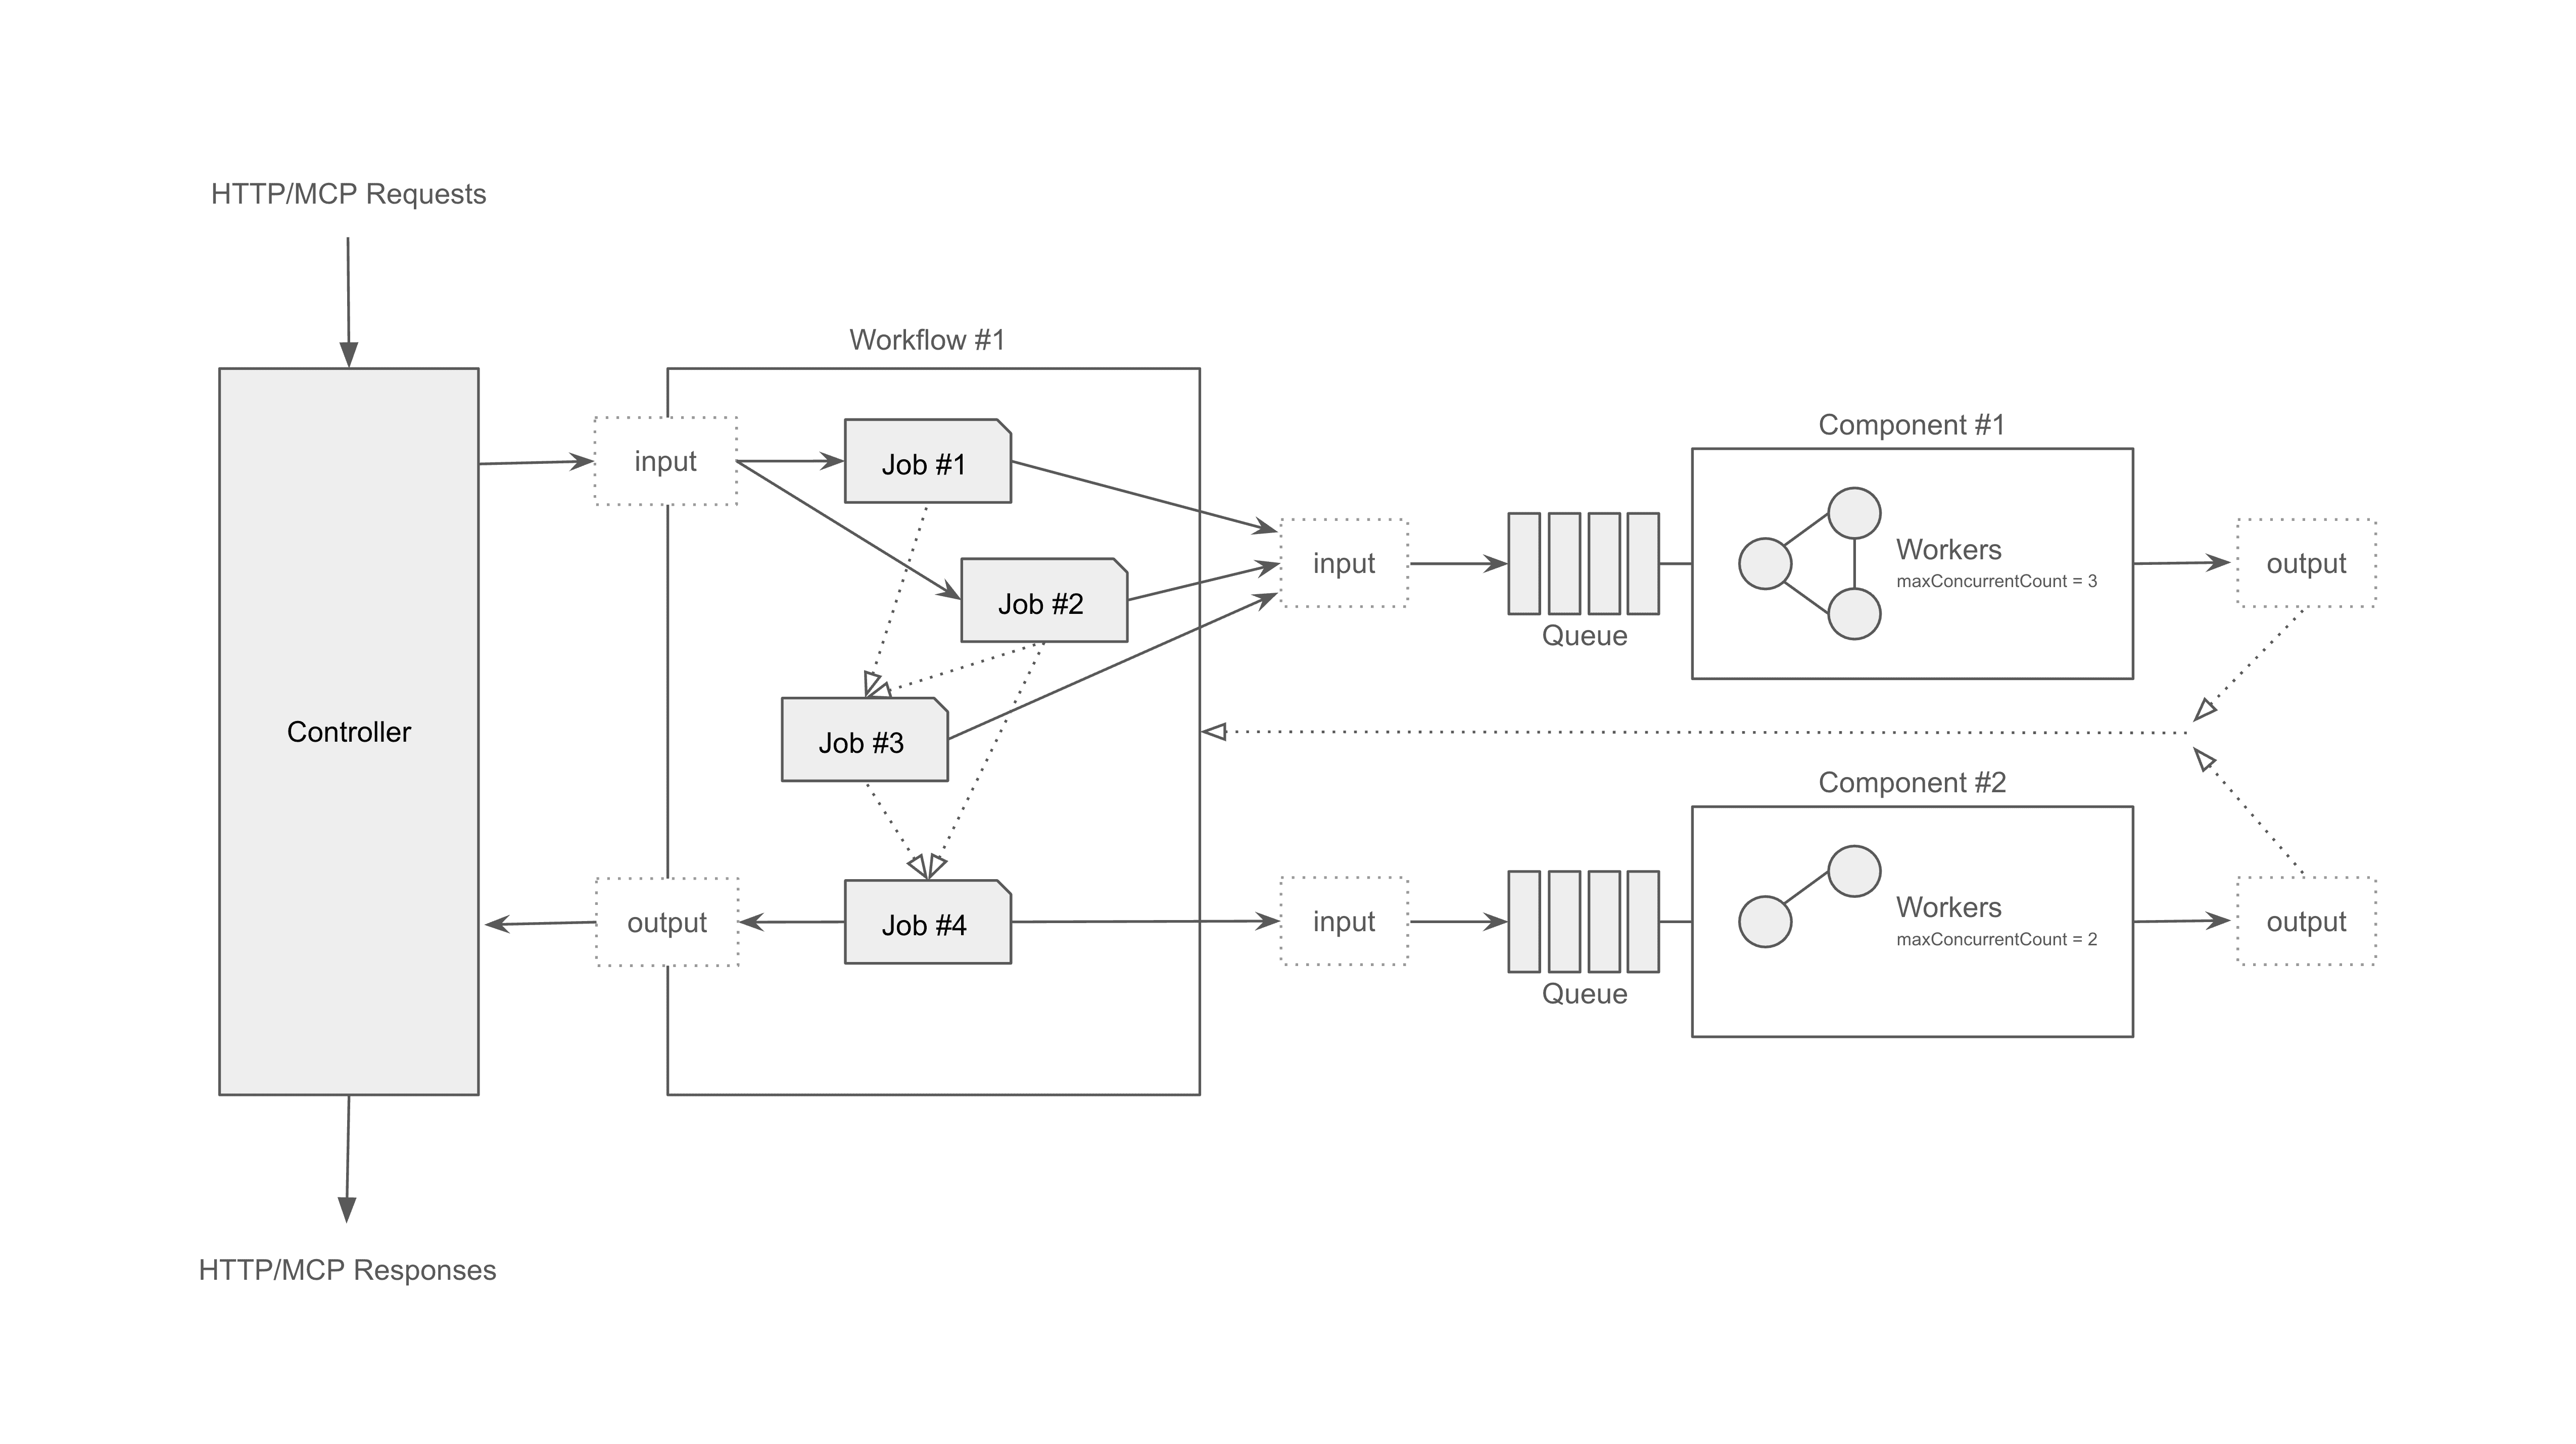
Protocol adapters → Composition engine → Runtime executors
We welcome all contributions — bug fixes, docs improvements, new examples.
git clone https://github.com/hanyeol/model-compose.git
cd model-compose
pip install -e .
See CONTRIBUTING if available, or open a PR directly.
MIT License © 2025-2026 Hanyeol Cho.
Have questions, ideas, or feedback? Open an issue or start a discussion on GitHub Discussions.
Declarative AI pipelines in one YAML file. Tokens, audio chunks, and video frames flow between isolated components. Compose 100+ components for models, agents, speech, vision, and live broadcast. Run local models, cloud APIs, or both. Inspired by docker-compose.
Python
119
2,347 commits
updated Oct 17, 2026
One YAML file. Any model. Any protocol. Any runtime.
Build chat APIs, RAG pipelines, autonomous agents, and MCP servers without writing orchestration code — then run the same definition anywhere, like docker-compose.
AI systems shouldn't be locked into a single provider, runtime, or cloud. model-compose is built on four principles:
Install with uv:
uv pip install model-compose
Or with pip:
pip install model-compose
Create model-compose.yml:
controller:
  adapter:
    type: http-server
    port: 8080
  webui:
    port: 8081

workflow:
  job:
    component: chatgpt
    input:
      prompt: ${input.prompt}
    output: ${output as stream/text}

component:
  id: chatgpt
  type: http-client
  base_url: https://api.openai.com/v1
  action:
    path: /chat/completions
    method: POST
    headers:
      Authorization: Bearer ${env.OPENAI_API_KEY}
      Content-Type: application/json
    body:
      model: gpt-4o
      messages:
        - role: user
          content: ${input.prompt}
      stream: true
    stream_format: json
    output: ${response[].choices[0].delta.content}
Run it:
export OPENAI_API_KEY=your-key
model-compose up
That's it. You're serving GPT-4o at http://localhost:8080 with a web UI at http://localhost:8081. No application code. No framework boilerplate. Same file runs locally, in Docker, or in production.
Every workflow gets a browser UI for free — inputs, outputs, streaming, and file uploads are inferred from the schema. Two lines of YAML, no frontend code.
controller:
  webui:
    driver: gradio
    port: 8081
Perfect for iteration, demos, and sharing a workflow with non-engineers before wiring it into production.
Here's what a single YAML file can serve today — just a few examples.
Build a ReAct agent that plans, uses tools, and completes multi-step tasks — declaratively.
component:
  id: research-agent
  type: agent
  tools: [search-web, fetch-page]
  max_iteration_count: 10
  action:
    model:
      component: chatgpt
    system_prompt: You are a web research assistant.
    user_prompt: ${input.question}
See simple agents like a code reviewer, a RAG assistant, and a web researcher in agents/.
Run open-weight models on your own hardware with PyTorch, vLLM, or llama.cpp — same YAML surface as cloud APIs, no SDK code.
component:
  type: model
  task: chat-completion
  model: HuggingFaceTB/SmolLM3-3B
  action:
    messages:
      - role: system
        content: ${input.system_prompt}
      - role: user
        content: ${input.user_prompt}
Point model: at any Hugging Face repo, or a local GGUF file via llama.cpp. Browse local chat, embedding, TTS, VLM, image/audio/video tasks under model-tasks/.
Compose embedding, vector search, and generation into a single workflow — no glue code.
workflow:
  jobs:
    - id: embed
      component: embedder
      input: { text: ${input.query} }

    - id: retrieve
      component: knowledge
      action: search
      input: { vector: ${jobs.embed.output} }

    - id: answer
      component: chatgpt
      input:
        context: ${jobs.retrieve.output}
        question: ${input.query}
Native drivers ship for Chroma, Milvus, Qdrant, FAISS, Neo4j, ArangoDB, and Redis.
Chain audio, video, and image stages across models and native codecs — swap any step without touching the rest.
workflow:
  jobs:
    - id: extract-audio
      component: audio-extractor
      input: { source: ${input.video as video} }

    - id: transcribe
      component: whisper
      input: { audio: ${jobs.extract-audio.output} }

    - id: translate
      component: translator
      input: { text: ${jobs.transcribe.output} }

    - id: dub
      component: tts
      input: { text: ${jobs.translate.output} }

    - id: lip-sync
      component: wav2lip
      input:
        video: ${input.video as video}
        audio: ${jobs.dub.output as audio/wav}
      output: ${output as video/mp4}
See full video dubbing, scene detection, voice cloning, and face mosaic pipelines in media-processing/.
Stream tokens, audio chunks, and video frames end-to-end — first-class across every stage.
workflow:
  job:
    component: chatgpt
    output: ${output as sse-text}

component:
  id: chatgpt
  type: http-client
  action:
    body: { stream: true, ... }
    stream_format: json
    output: ${response[].choices[0].delta.content}
Real-time TTS, video-to-frames, and live chat examples live under data-streaming/ and showcase/.
Turn any workflow into an MCP server that Claude, ChatGPT, or Cursor can use — one line change.
controller:
  adapter:
    type: mcp-server   # ← was: http-server
    port: 8080
Full examples live in mcp-servers/, including a Slack bot MCP.
The same YAML that runs on your laptop scales without a rewrite.
model-compose up
Runs on your machine with a Gradio web UI at :8081 — perfect for iteration.
Add a runtime: block. Same file, same behavior:
controller:
  runtime:
    type: docker
    image: my-ai-service:latest
    ports: [ "8080:8080" ]
Add a queue. Dispatchers accept jobs, subscribers process them across N machines:
controller:
  adapter: { type: http-server, port: 8080 }
  queue:
    driver: redis
    host: redis.internal
    name: my-queue
No shared filesystem. No code changes. Just add more subscribers to scale.
| model-compose | Managed APIs (OpenAI, etc.) | Code Frameworks (LangChain, etc.) | |
|---|---|---|---|
| Time to first API | Minutes (one YAML) | Hours (SDK + server code) | Days (framework + integration) |
| Provider Coupling | Multi-provider via config | Single provider per SDK | Multi-provider via abstractions |
| Code Coupling | Declarative YAML — no application code | Application code required | Framework-specific code required |
| Infrastructure Control | Full Sovereignty | Provider-controlled | Heavy Abstraction |
| Runtime Flexibility | Hybrid-First (Local + Cloud) | Cloud Only | Complex to customize |
| Protocol Support | HTTP / WebSocket / MCP | Provider-specific | Limited |
| Data Streaming | First-class across all stages | Response-only (SSE tokens) | Framework-wrapped generators |
| Deployment | Docker / Native / Virtualenv / Process | Provider-managed | Manual integration |
Browse examples by category:
| Category | What's inside |
|---|---|
agents/ | Code reviewer, RAG assistant, Web researcher, Web page analyzer, ... |
showcase/ | End-to-end pipelines: disk analysis, face-based scene search, real-time TTS |
model-providers/ | OpenAI, Anthropic, xAI, Google, ElevenLabs, vLLM |
model-tasks/ | Local chat, embedding, TTS, VLM, face embedding, ... |
media-processing/ | Audio/video/image processing: extraction, conversion, scene detection |
media-broadcast/ | Live broadcasting pipelines (e.g. YouTube Live over RTMP) |
web-automation/ | Web scraping, headless browser automation, page capture |
text-processing/ | Text chunking and preprocessing |
mcp-servers/ | Build MCP servers exposed to Claude, Cursor, ChatGPT |
workflow-queue/ | Redis-backed distributed dispatch (streaming + non-streaming) |
data-streaming/ | Video-to-frames, YouTube live chat, streaming inputs |
job-flow/ | Workflow control: conditional routing, hooks, interrupts |
integrations/ | Vector/graph/KV stores, search engines, channels, tunnels |
runtime/ | Component execution runtimes: Docker, Apple Container, virtualenv, ... |
Browse the full catalog in examples/README.md.
Protocol adapters → Composition engine → Runtime executors
We welcome all contributions — bug fixes, docs improvements, new examples.
git clone https://github.com/hanyeol/model-compose.git
cd model-compose
pip install -e .
See CONTRIBUTING if available, or open a PR directly.
MIT License © 2025-2026 Hanyeol Cho.
Have questions, ideas, or feedback? Open an issue or start a discussion on GitHub Discussions.
487 followers · starred Apr 2026