
PyTorch implementation of MeanFlow & iMF (one-step generative modeling).
Python
1,204
81 commits
updated Jul 1, 2026
README
MeanFlow
PyTorch implementation of Mean Flows for One-step Generative Modeling (MeanFlow) and Improved Mean Flows (iMF).
Note: Unofficial implementation, based on the papers above and the official JAX repo imeanflow.
Contributions and feedback are welcome! Feel free to open an issue or pull request.
Updates
2026.06.13
- MeanFlow and iMF training (
meanflow.mode:"meanflow"/"i-meanflow") - Dual-head DiT:
ufor MeanFlow,vfor flow matching - CFG scale as model input with CFG distillation (
cfg_scale;Noneto disable) - JVP under
no_gradfordudtonly; separate grad-enabled forward pass for optimization - Config-based training for MNIST, CIFAR-10, and ImageNet latent
Usage
i-meanflow (meanflow.mode: "i-meanflow") is more stable and recommended for your projects. meanflow mode is kept for reference.
pip install torch accelerate torchvision einops tqdm diffusers
# single GPU
python train.py --config configs/mnist.py

# custom run name
python train.py --config configs/cifar10.py --run_suffix exp1

# multi-GPU
accelerate launch --num_processes 2 train.py --config configs/mnist.py
| Config | Dataset |
|---|---|
configs/mnist.py | MNIST |
configs/cifar10.py | CIFAR-10 |
configs/imagenet_latent.py | ImageNet (latent, VAE) |
Common config fields: n_steps, batch_size, grad_clip, mixed_precision, meanflow.mode, meanflow.cfg_scale.
Training logs are saved to logs/{run_name}/:
logs/{run_name}/
├── config.py
├── train.log      # loss, FM/MF loss, MF_V_MSE, grad norm, LR
├── images/
└── ckpts/
Examples
MNIST — 10k steps, 1-step sample:
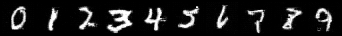
MNIST — 6k steps, 1-step CFG (w=2.0):
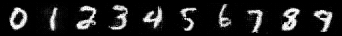
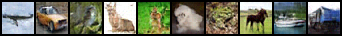
CIFAR-10 — 200k steps, 1-step CFG (w=2.0):
TODO
- Basic training and inference
- Multi-GPU via Accelerate
- Classifier-Free Guidance
- Latent image training
- Improved MeanFlow (iMF)
- Triton JVP + Flash Attention
Known Issues
-
jvpis currently incompatible with PyTorch's native Flash Attention (scaled_dot_product_attention). -
Solution in this repo:
- Run the JVP pass under
no_grad(fordudtonly) without Flash Attention. - Run a separate gradient-enabled forward pass for optimization with Flash Attention.
- Run the JVP pass under
-
Other advanced solutions:
- Triton-based kernels with JVP support (e.g. rcm) will allow Flash Attention within JVP.
- Such kernels may offer additional speed and memory benefits, but are not currently supported in this repository.
Acknowledgement
Building upon Just-a-DiT and EzAudio.
iMF support is based on the official JAX repo imeanflow. Thanks to the authors for releasing their code.
Like This Project?
If you find this repo helpful, consider dropping a ⭐, it really helps!
Citation
If you find this repository useful in your research or projects, please consider citing the original MeanFlow papers as well as this implementation.
MeanFlow
@article{geng2025meanflow,
  title={Mean Flows for One-step Generative Modeling},
  author={Geng, Zhengyang and Shechtman, Eli and Kolter, J. Zico and He, Kaiming},
  journal={arXiv preprint arXiv:2505.13447},
  year={2025}
}
Improved MeanFlow
@article{geng2025improved,
  title={Improved Mean Flows: On the Challenges of Fastforward Generative Models},
  author={Geng, Zhengyang and Lu, Yiyang and Wu, Zongze and Shechtman, Eli and Kolter, J. Zico and He, Kaiming},
  journal={arXiv preprint arXiv:2512.02012},
  year={2025}
}
This Repository
@misc{meanflow_pytorch,
  title={MeanFlow: Unofficial PyTorch Implementation},
  author={haidog-yaqub},
  year={2025},
  howpublished={\url{https://github.com/haidog-yaqub/MeanFlow}},
}
Significant stargazers

154 followers · starred May 2025
Similar repos


Languages
Python
100.0%
PyTorch implementation of MeanFlow & iMF (one-step generative modeling).
Python
1,204
81 commits
updated Jul 1, 2026
README
MeanFlow
PyTorch implementation of Mean Flows for One-step Generative Modeling (MeanFlow) and Improved Mean Flows (iMF).
Note: Unofficial implementation, based on the papers above and the official JAX repo imeanflow.
Contributions and feedback are welcome! Feel free to open an issue or pull request.
Updates
2026.06.13
- MeanFlow and iMF training (
meanflow.mode:"meanflow"/"i-meanflow") - Dual-head DiT:
ufor MeanFlow,vfor flow matching - CFG scale as model input with CFG distillation (
cfg_scale;Noneto disable) - JVP under
no_gradfordudtonly; separate grad-enabled forward pass for optimization - Config-based training for MNIST, CIFAR-10, and ImageNet latent
Usage
i-meanflow (meanflow.mode: "i-meanflow") is more stable and recommended for your projects. meanflow mode is kept for reference.
pip install torch accelerate torchvision einops tqdm diffusers
# single GPU
python train.py --config configs/mnist.py

# custom run name
python train.py --config configs/cifar10.py --run_suffix exp1

# multi-GPU
accelerate launch --num_processes 2 train.py --config configs/mnist.py
| Config | Dataset |
|---|---|
configs/mnist.py | MNIST |
configs/cifar10.py | CIFAR-10 |
configs/imagenet_latent.py | ImageNet (latent, VAE) |
Common config fields: n_steps, batch_size, grad_clip, mixed_precision, meanflow.mode, meanflow.cfg_scale.
Training logs are saved to logs/{run_name}/:
logs/{run_name}/
├── config.py
├── train.log      # loss, FM/MF loss, MF_V_MSE, grad norm, LR
├── images/
└── ckpts/
Examples
MNIST — 10k steps, 1-step sample:
MNIST — 6k steps, 1-step CFG (w=2.0):
CIFAR-10 — 200k steps, 1-step CFG (w=2.0):
TODO
- Basic training and inference
- Multi-GPU via Accelerate
- Classifier-Free Guidance
- Latent image training
- Improved MeanFlow (iMF)
- Triton JVP + Flash Attention
Known Issues
-
jvpis currently incompatible with PyTorch's native Flash Attention (scaled_dot_product_attention). -
Solution in this repo:
- Run the JVP pass under
no_grad(fordudtonly) without Flash Attention. - Run a separate gradient-enabled forward pass for optimization with Flash Attention.
- Run the JVP pass under
-
Other advanced solutions:
- Triton-based kernels with JVP support (e.g. rcm) will allow Flash Attention within JVP.
- Such kernels may offer additional speed and memory benefits, but are not currently supported in this repository.
Acknowledgement
Building upon Just-a-DiT and EzAudio.
iMF support is based on the official JAX repo imeanflow. Thanks to the authors for releasing their code.
Like This Project?
If you find this repo helpful, consider dropping a ⭐, it really helps!
Citation
If you find this repository useful in your research or projects, please consider citing the original MeanFlow papers as well as this implementation.
MeanFlow
@article{geng2025meanflow,
  title={Mean Flows for One-step Generative Modeling},
  author={Geng, Zhengyang and Shechtman, Eli and Kolter, J. Zico and He, Kaiming},
  journal={arXiv preprint arXiv:2505.13447},
  year={2025}
}
Improved MeanFlow
@article{geng2025improved,
  title={Improved Mean Flows: On the Challenges of Fastforward Generative Models},
  author={Geng, Zhengyang and Lu, Yiyang and Wu, Zongze and Shechtman, Eli and Kolter, J. Zico and He, Kaiming},
  journal={arXiv preprint arXiv:2512.02012},
  year={2025}
}
This Repository
@misc{meanflow_pytorch,
  title={MeanFlow: Unofficial PyTorch Implementation},
  author={haidog-yaqub},
  year={2025},
  howpublished={\url{https://github.com/haidog-yaqub/MeanFlow}},
}
Similar repos
Significant stargazers
154 followers · starred May 2025
Languages
Python
100.0%