This repository contains the implementation of "Boosting the Predictive Power of Protein Representations with a Corpus of Text Annotations" (2024).
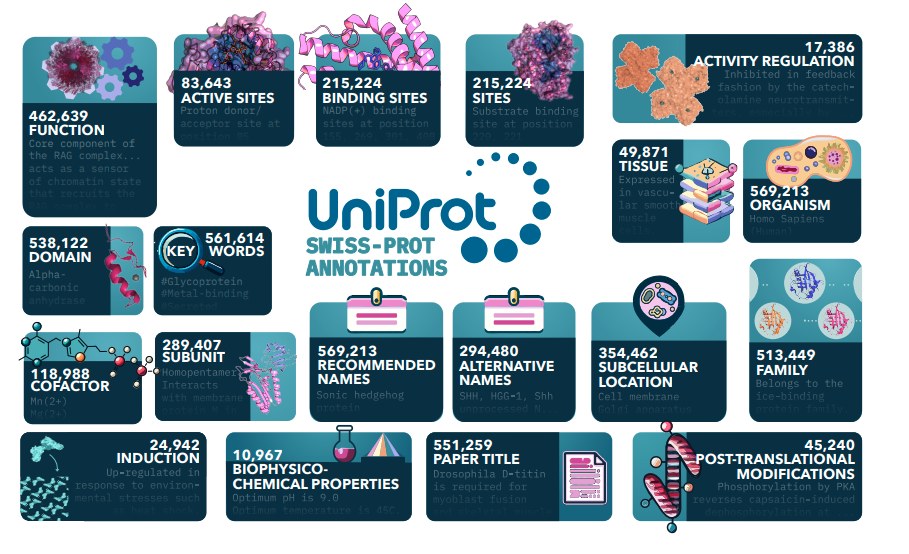
_config/fact_types.yml: Hyperparameters for parsing and loading each fact typepaths.yml: Paths for datasets_evaluation/get_embeddings.py: Generate embeddings for each modelknn_embeddings.py: Perform knn on the precomputing embedding_fact/_/parse.py: parser code for each fact type_/batch.py: Batch operation for each fact type_model/_/model.py: implementations of the seq2seq architecture_/config.py: Hyperparameters of the modeldataloader_ddp.py: General implementations of the data loaderpip install -r requirements.txt
_config/paths.yml._config/fact_types.yml to Truepython parse.py_model/config.py.submit_worker_reference.sh according to your cluster.sbatch submit.sh in slurm.cd _evaluationmodelname, trainset, valset in submit.shsbatch submit.sh in slurm.If you use this work in your research, please cite:
@article{duan2024boosting,
   title={Boosting the Predictive Power of Protein Representations with a Corpus of Text Annotations},
   author={Duan, Haonan and Skreta, Marta and Cotta, Leonardo and Rajaonson, Ella Miray and Dhawan, Nikita and Aspuru-Guzik, Al{\'a}n and Maddison, Chris J.},
   journal={bioRxiv},
   year={2024},
   doi={10.1101/2024.07.22.604688}
}
This repository contains the implementation of "Boosting the Predictive Power of Protein Representations with a Corpus of Text Annotations" (2024).
_config/fact_types.yml: Hyperparameters for parsing and loading each fact typepaths.yml: Paths for datasets_evaluation/get_embeddings.py: Generate embeddings for each modelknn_embeddings.py: Perform knn on the precomputing embedding_fact/_/parse.py: parser code for each fact type_/batch.py: Batch operation for each fact type_model/_/model.py: implementations of the seq2seq architecture_/config.py: Hyperparameters of the modeldataloader_ddp.py: General implementations of the data loaderpip install -r requirements.txt
_config/paths.yml._config/fact_types.yml to Truepython parse.py_model/config.py.submit_worker_reference.sh according to your cluster.sbatch submit.sh in slurm.cd _evaluationmodelname, trainset, valset in submit.shsbatch submit.sh in slurm.If you use this work in your research, please cite:
@article{duan2024boosting,
   title={Boosting the Predictive Power of Protein Representations with a Corpus of Text Annotations},
   author={Duan, Haonan and Skreta, Marta and Cotta, Leonardo and Rajaonson, Ella Miray and Dhawan, Nikita and Aspuru-Guzik, Al{\'a}n and Maddison, Chris J.},
   journal={bioRxiv},
   year={2024},
   doi={10.1101/2024.07.22.604688}
}



