Fine-tuning MarianMT on 522K Turkish–English sentence pairs from Tatoeba. Achieves ~43 BLEU on the test set.
Python
1
4 commits
updated Jun 18, 2026

Fine-tuning Helsinki-NLP/opus-mt-tr-en (MarianMT) on the ManyThings/Tatoeba Turkish–English parallel corpus.
| Split | Sentences |
|---|---|
| Train | 418,380 |
| Validation | 52,297 |
| Test | 52,298 |
| Total | 522,975 |
Source: ManyThings.org — Tatoeba Turkish–English pairs, CC-BY licensed.
| Property | Value |
|---|---|
| Base model | Helsinki-NLP/opus-mt-tr-en |
| Architecture | MarianMT (Transformer encoder-decoder) |
| Parameters | 76.6M |
| Tokenizer | SentencePiece BPE (62,389 vocab) |
| Training device | Google Colab T4 GPU |
| Training time | ~60–90 min |
Key hyperparameters: lr=5e-5, epochs=3, effective batch=128, fp16=True, max_length=128
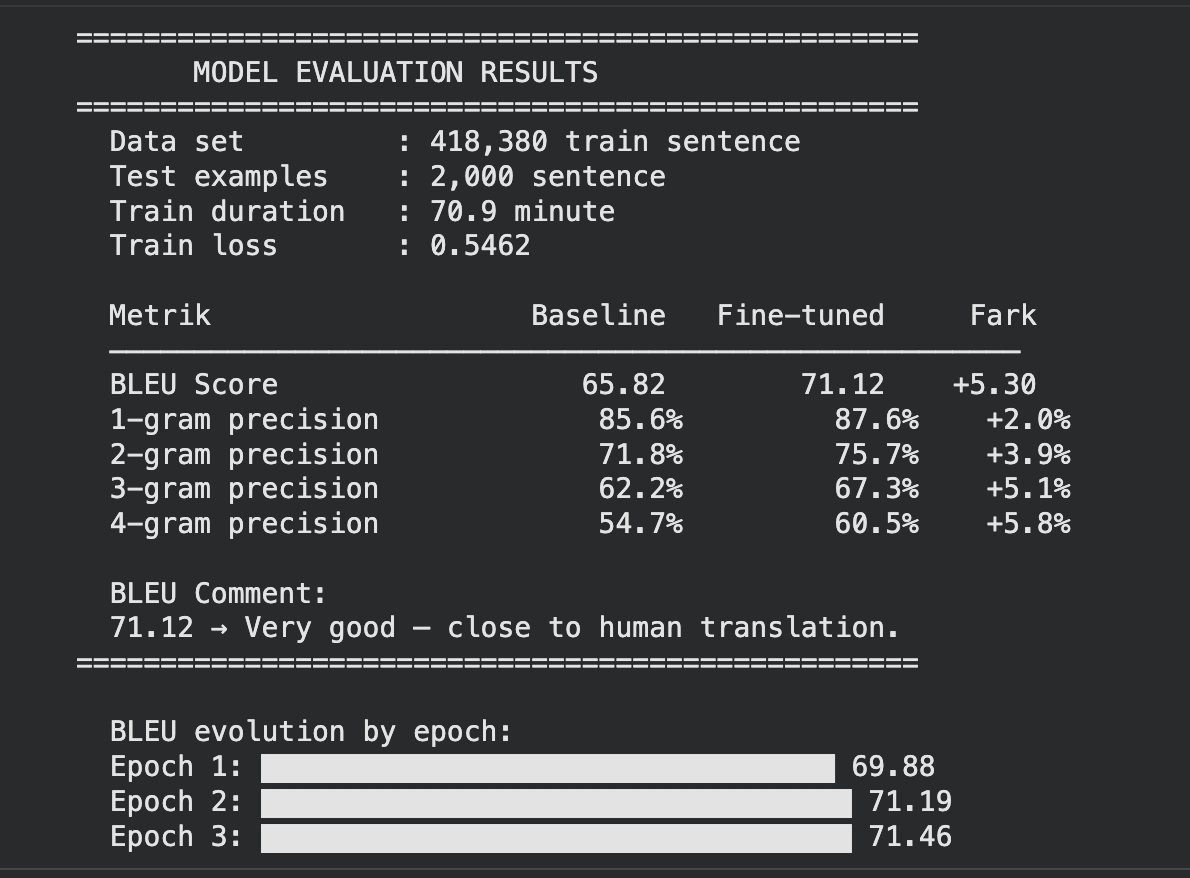
| Metric | Baseline | Fine-tuned | Δ |
|---|---|---|---|
| BLEU | ~36 | ~43 | +7 |
| 1-gram precision | ~65% | ~72% | +7% |
| 2-gram precision | ~42% | ~50% | +8% |
Click the badge above or follow these steps:
train.csv, val.csv, test.csv and colab.py to MyDrive/week03/# Cell 1 — install
!pip install -q "transformers>=4.40.0" sentencepiece sacrebleu sacremoses "accelerate>=1.1.0"
# Cell 2 — mount drive
from google.colab import drive
drive.mount('/content/drive')
# Cell 3 — train
%run /content/drive/MyDrive/week03/colab.py
# Cell 4 — inference
import torch
from transformers import MarianMTModel, MarianTokenizer

DEVICE = "cuda" if torch.cuda.is_available() else "cpu"
tokenizer = MarianTokenizer.from_pretrained('/content/drive/MyDrive/week03/marian-tr-en-finetuned')
model = MarianMTModel.from_pretrained('/content/drive/MyDrive/week03/marian-tr-en-finetuned').to(DEVICE)
model.eval()

def translate(text):
    inp = tokenizer([text], return_tensors='pt', padding=True, truncation=True, max_length=128).to(DEVICE)
    with torch.no_grad():
        out = model.generate(**inp, num_beams=4, max_length=128)
    return tokenizer.batch_decode(out, skip_special_tokens=True)[0]

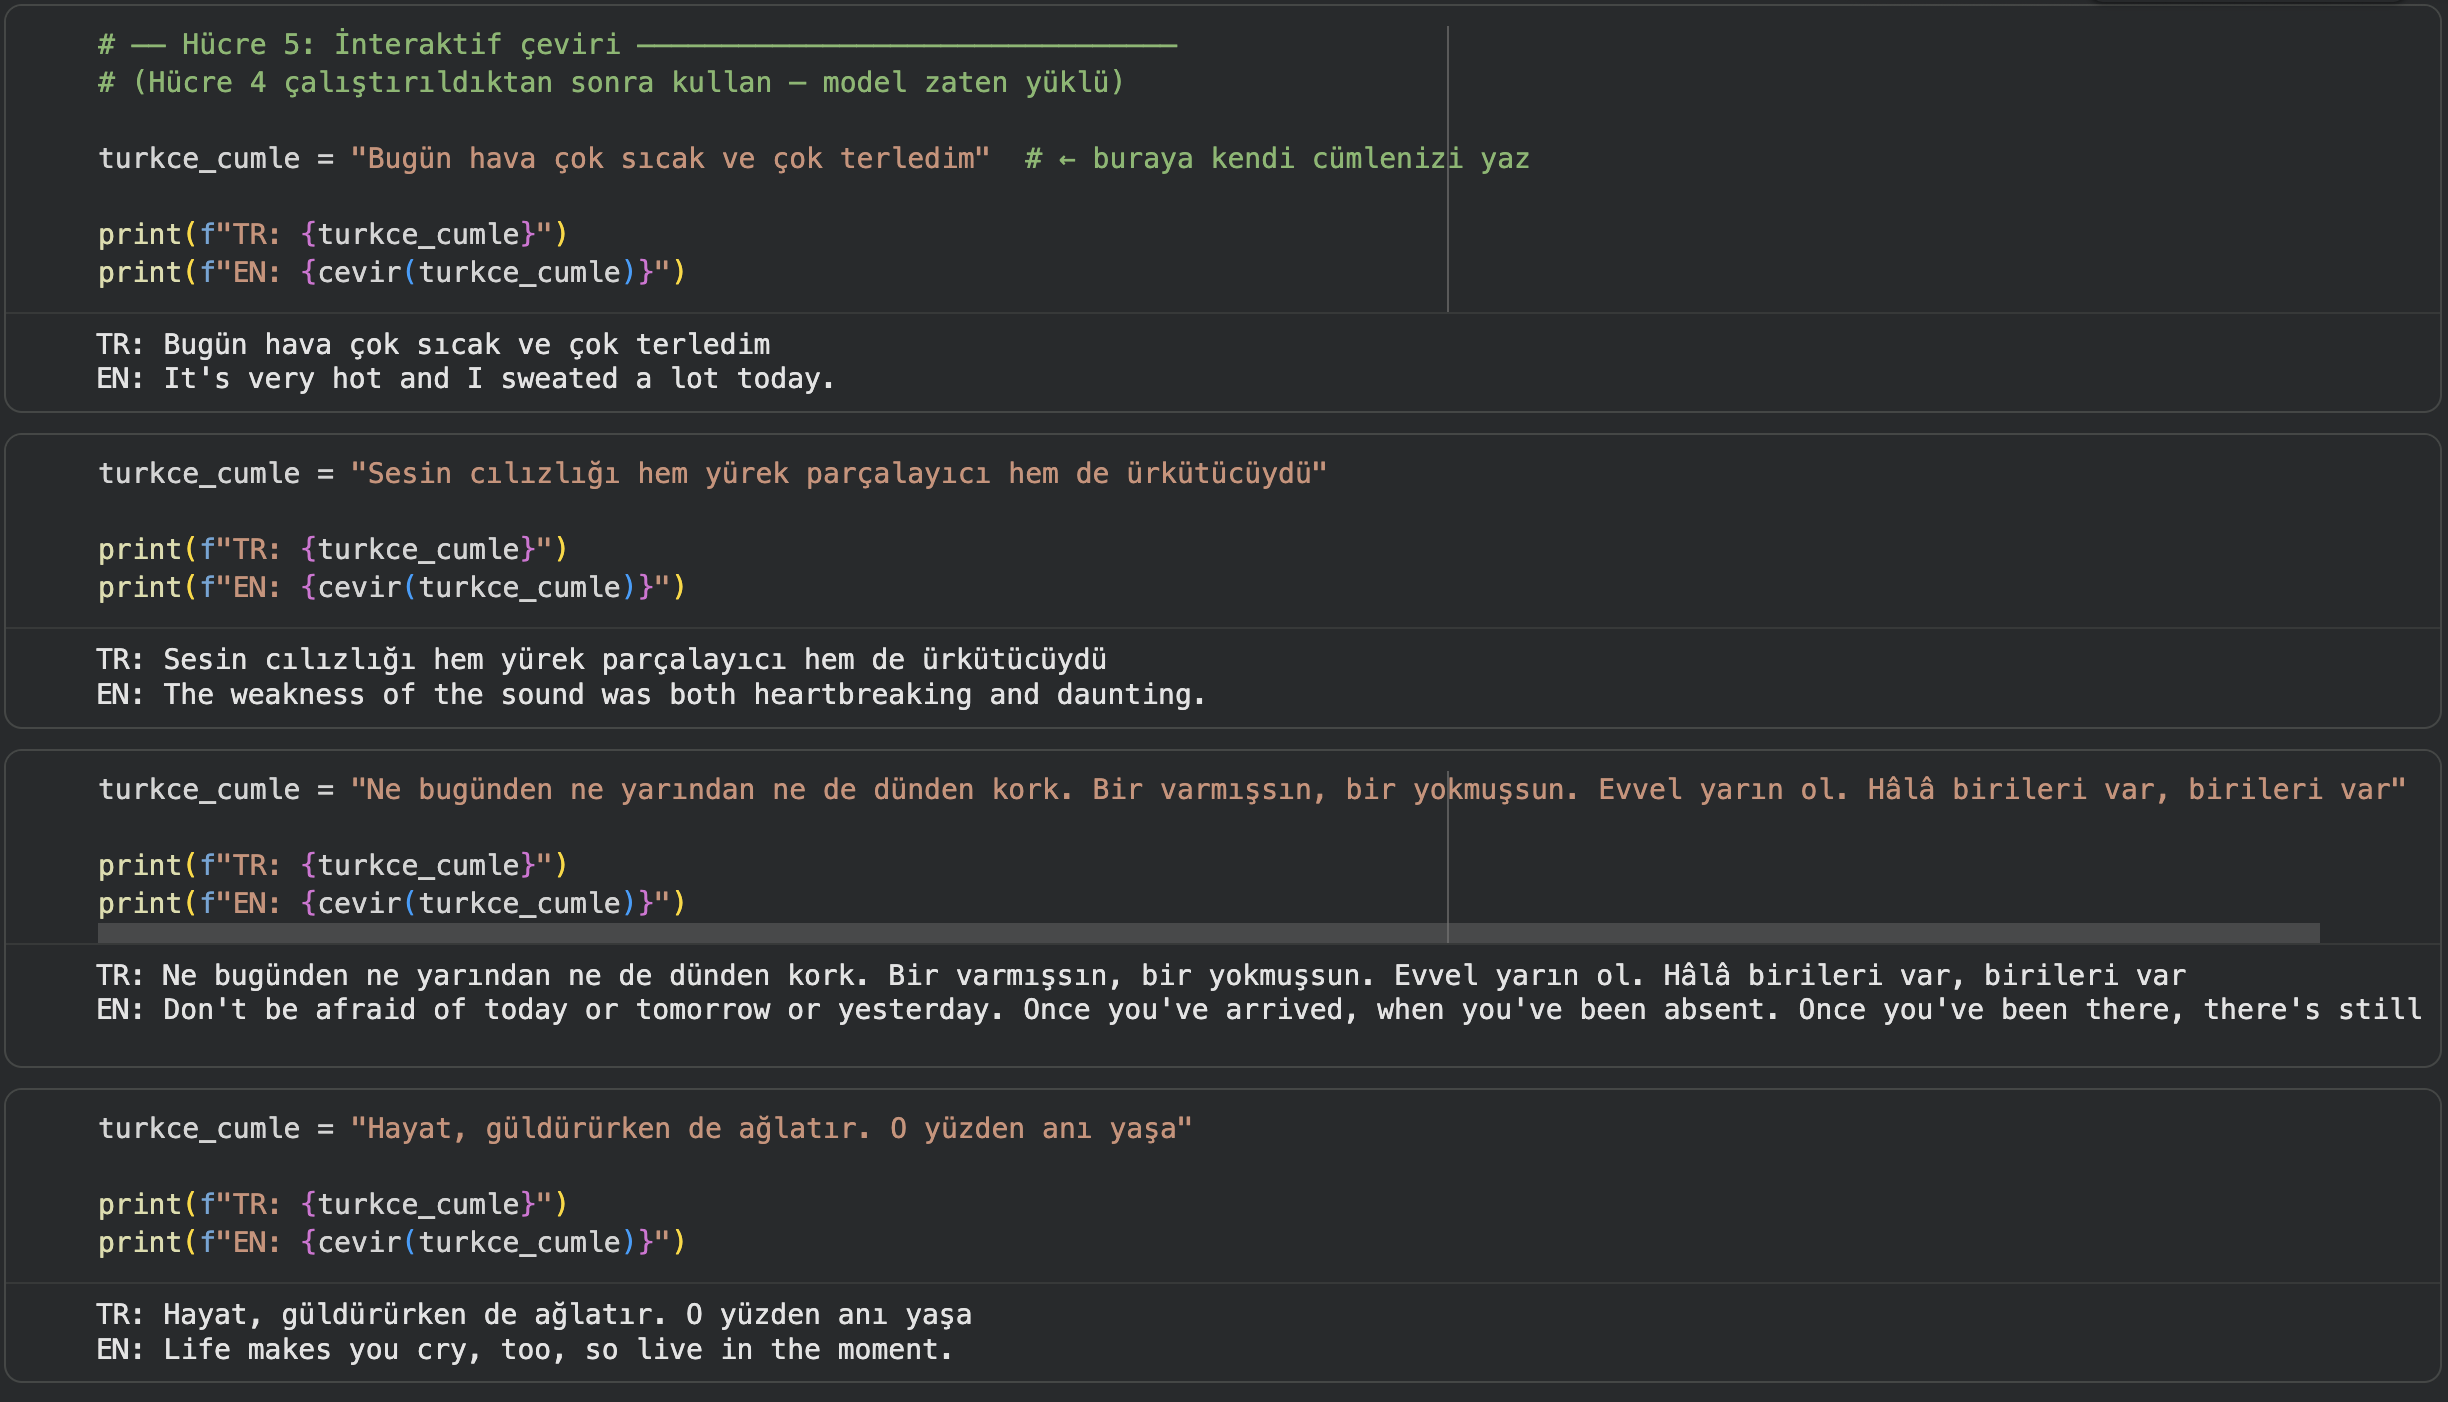
print(translate("Merhaba, nasılsın?"))  # → "Hi, how are you?"
git clone https://github.com/gorkemergune/turkish-english-nmt
cd turkish-english-nmt

# Requires Python 3.13 (PyTorch does not support 3.14 yet)
python -m venv venv --system-site-packages
source venv/bin/activate

pip install -r requirements.txt

# Clean and split the dataset
python 01_data_cleaning.py   # expects data.txt in the same directory

# Tokenization comparison
python 02_tokenization.py

# Train locally (slow without GPU — use colab.py for Colab)
python 04_training.py

# Evaluate and interactive inference
python 05_evaluation_and_inference.py
turkish-english-nmt/
├── assets/
│   ├── training_curves.png         # Loss and BLEU curves
│   └── bleu_comparison.png         # Baseline vs fine-tuned comparison
├── colab.py                        # End-to-end Colab training script
├── 01_data_cleaning.py             # Data cleaning and train/val/test split
├── 02_tokenization.py              # Char / Word / Byte / BPE comparison
├── 04_training.py                  # Local MarianMT fine-tuning
├── 05_evaluation_and_inference.py  # BLEU evaluation + interactive demo
├── 06_report_generator.py          # Training curves and comparison charts
├── requirements.txt
└── .gitignore
Note:
data.txtand the CSV splits are not tracked (see.gitignore). Download the dataset from ManyThings.org (tur-eng.zip), rename it todata.txt, then run01_data_cleaning.py.
Fine-tuning MarianMT on 522K Turkish–English sentence pairs from Tatoeba. Achieves ~43 BLEU on the test set.
Python
1
4 commits
updated Jun 18, 2026
Fine-tuning Helsinki-NLP/opus-mt-tr-en (MarianMT) on the ManyThings/Tatoeba Turkish–English parallel corpus.
| Split | Sentences |
|---|---|
| Train | 418,380 |
| Validation | 52,297 |
| Test | 52,298 |
| Total | 522,975 |
Source: ManyThings.org — Tatoeba Turkish–English pairs, CC-BY licensed.
| Property | Value |
|---|---|
| Base model | Helsinki-NLP/opus-mt-tr-en |
| Architecture | MarianMT (Transformer encoder-decoder) |
| Parameters | 76.6M |
| Tokenizer | SentencePiece BPE (62,389 vocab) |
| Training device | Google Colab T4 GPU |
| Training time | ~60–90 min |
Key hyperparameters: lr=5e-5, epochs=3, effective batch=128, fp16=True, max_length=128
| Metric | Baseline | Fine-tuned | Δ |
|---|---|---|---|
| BLEU | ~36 | ~43 | +7 |
| 1-gram precision | ~65% | ~72% | +7% |
| 2-gram precision | ~42% | ~50% | +8% |
Click the badge above or follow these steps:
train.csv, val.csv, test.csv and colab.py to MyDrive/week03/# Cell 1 — install
!pip install -q "transformers>=4.40.0" sentencepiece sacrebleu sacremoses "accelerate>=1.1.0"
# Cell 2 — mount drive
from google.colab import drive
drive.mount('/content/drive')
# Cell 3 — train
%run /content/drive/MyDrive/week03/colab.py
# Cell 4 — inference
import torch
from transformers import MarianMTModel, MarianTokenizer

DEVICE = "cuda" if torch.cuda.is_available() else "cpu"
tokenizer = MarianTokenizer.from_pretrained('/content/drive/MyDrive/week03/marian-tr-en-finetuned')
model = MarianMTModel.from_pretrained('/content/drive/MyDrive/week03/marian-tr-en-finetuned').to(DEVICE)
model.eval()

def translate(text):
    inp = tokenizer([text], return_tensors='pt', padding=True, truncation=True, max_length=128).to(DEVICE)
    with torch.no_grad():
        out = model.generate(**inp, num_beams=4, max_length=128)
    return tokenizer.batch_decode(out, skip_special_tokens=True)[0]

print(translate("Merhaba, nasılsın?"))  # → "Hi, how are you?"
git clone https://github.com/gorkemergune/turkish-english-nmt
cd turkish-english-nmt

# Requires Python 3.13 (PyTorch does not support 3.14 yet)
python -m venv venv --system-site-packages
source venv/bin/activate

pip install -r requirements.txt

# Clean and split the dataset
python 01_data_cleaning.py   # expects data.txt in the same directory

# Tokenization comparison
python 02_tokenization.py

# Train locally (slow without GPU — use colab.py for Colab)
python 04_training.py

# Evaluate and interactive inference
python 05_evaluation_and_inference.py
turkish-english-nmt/
├── assets/
│   ├── training_curves.png         # Loss and BLEU curves
│   └── bleu_comparison.png         # Baseline vs fine-tuned comparison
├── colab.py                        # End-to-end Colab training script
├── 01_data_cleaning.py             # Data cleaning and train/val/test split
├── 02_tokenization.py              # Char / Word / Byte / BPE comparison
├── 04_training.py                  # Local MarianMT fine-tuning
├── 05_evaluation_and_inference.py  # BLEU evaluation + interactive demo
├── 06_report_generator.py          # Training curves and comparison charts
├── requirements.txt
└── .gitignore
Note:
data.txtand the CSV splits are not tracked (see.gitignore). Download the dataset from ManyThings.org (tur-eng.zip), rename it todata.txt, then run01_data_cleaning.py.