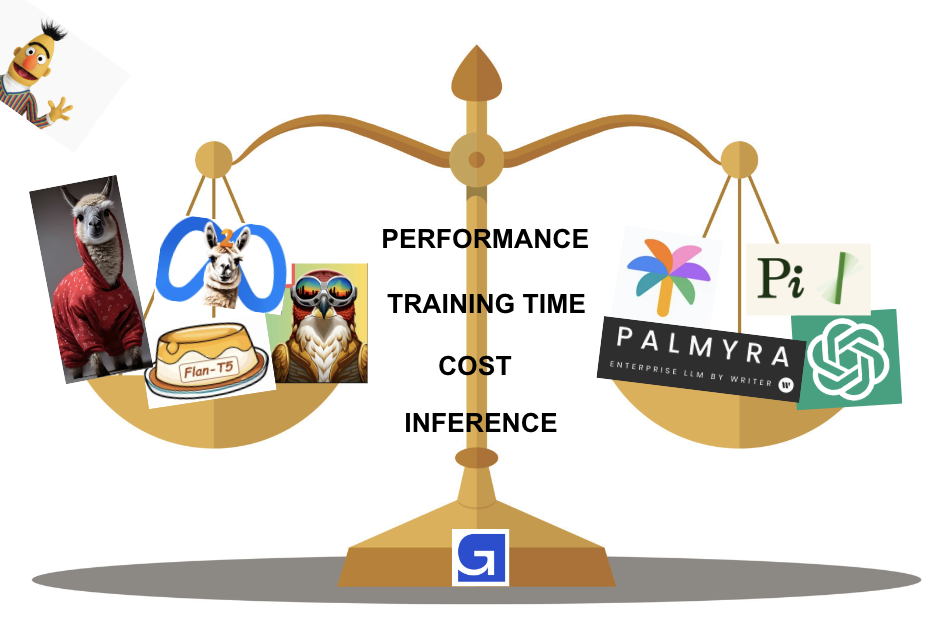
LLM Finetuning Hub contains code and insights to finetune various large language models for your use-case.
We stress-test both open-source and close-source LLMs through our Evaluation Framework to check their applicability for real-life business use-cases. Finetuning LLMs has never been easier.
Evaluation Framework • Getting Started • LLM Roadmap • Benchmarks • Contributing
For a holistic evaluation, we will make use of the Evaluation Framework that contains 4 pillars:
 Performance
 Time to Train
 Cost to Train
 Inferencing
For each of the above four pillars, we are sharing our codebase and insights to:
We are providing scripts that are ready-to-use for:
You can start fine-tuning your choice of LLM in 4 easy steps:
Setup conda environment
wget https://repo.anaconda.com/miniconda/Miniconda3-py38_4.11.0-Linux-x86_64.sh
bash Miniconda3-py38_4.11.0-Linux-x86_64.sh
source ~/.bashrc
conda create --name llm_finetuning python=3.9
conda activate llm_finetuning
Install relevant packages
git clone https://github.com/georgian-io/LLM-Finetuning-Hub.git
cd LLM-Finetuning-Hub/
pip install -r requirements.txt
Finetune your LLM of choice
For instance, to finetune Llama2-7B or Llama2-13B, do the following:
cd llama2/ # navigate to Llama2 folder
python llama2_classification.py --lora_r 8 --epochs 5 --dropout 0.1 --pretrained_ckpt NousResearch/Llama-2-7b-hf # finetune Llama2-7B on newsgroup classification dataset
python llama2_classification_inference.py --experiment <experiment folder> # evaluate finetuned Llama2 7B version
python llama2_summarization.py --lora_r 8 --epochs 1 --dropout 0.1 --pretrained_ckpt NousResearch/Llama-2-13b-hf # finetune Llama2-13B on samsum chat dataset
python llama2_summarization_inference.py --experiment <experiment folder> # evaluate finetuned Llama2 13B version
For instance, to finetune Falcon-7B, do the following:
cd falcon/ # navigate to Falcon folder
python falcon_classification.py --lora_r 8 --epochs 5 --dropout 0.1 # finetune Falcon-7B on newsgroup classification dataset
python falcon_classification_inference.py --experiment <experiment folder> # evaluate finetuned Falcon
python falcon_summarization.py --lora_r 8 --epochs 1 --dropout 0.1 # finetune Falcon-7B on samsum chat dataset
python falcon_summarization_inference.py --experiment <experiment folder> # evaluate finetuned Falcon
For instance, to finetune Flan-T5-Large, do the following:
cd flan-t5/ # navigate to Flan-T5 folder
python flan_classification.py --peft_method prefix --prefix_tokens 20 --epochs 5 # finetune Flan-T5 on newsgroup dataset
python flan_classification_inference.py --experiment <experiment folder> # evaluate finetuned Flan-T5
python flan_summarization.py --peft_method lora --lora_r 8 --epochs 1 # finetune Flan-T5 on samsum chat dataset
python flan_summarization_inference.py --experiment <experiment folder> # evalute finetuned Flan-T5
Zero-shot and Few-shot your LLM of choice
For instance, to use Falcon-7B on newsgroup classification task, do the following:
python falcon_baseline_inference.py --task_type classification --prompt_type zero-shot
python falcon_baseline_inference.py --task_type classification --prompt_type few-shot
To use Falcon-7B on samsum summarization task, do the following:
python falcon_baseline_inference.py --task_type summarization --prompt_type zero-shot
python falcon_baseline_inference.py --task_type summarization --prompt_type few-shot
NOTE: All of our experiments were conducted on the AWS EC2 instance: g5.2xlarge. It has one 24GB Nvidia GPU, and is sufficient to finetune the LLMs in this repository.
Our plan is to perform these experiments on all the LLMs below. To that end, this is a tentative roadmap of the LLMs that we aim to cover, and their corresponding codebase and README links:
| LLM | Benchmarked? | Open-Source? | README | Codebase |
|---|---|---|---|---|
| Flan-T5 | ✅ | ✅ | Link | Folder |
| Falcon | ✅ | ✅ | Link | Folder |
| RedPajama | ✅ | ✅ | Link | Folder |
| Llama-2 | ✅ | ✅ | Link | Folder |
| OpenLlama | ✅ | |||
| SalesForce XGen | ✅ | |||
| Mosaic MPT | ✅ | |||
| Cerebras | ✅ | |||
| Writer Palmyra | ❌ | |||
| OpenAI GPT-3.5 | ❌ | |||
| Google PaLM | ❌ | |||
| Inflection Pi | ❌ |
We benchmark LLMs across the tasks of classification and summarization. More precisely, we finetune LLMs on the following experiments:
Note:
We use the Newsgroup dataset which is a 20-way classification problem. Each document needs to be identified as one of the 20 possible newsgroups. To check how quickly LLMs can learn on small number of samples, we compare them with the likes of BERT and Distilbert. Following table captures how models perform as we increase the number of training samples.
| Training samples (fraction) | Distilbert | Bert | Flan-T5 Large | Falcon-7B | RP-3B | RP-7B | Llama2-7B | Llama2-13B |
|---|---|---|---|---|---|---|---|---|
| 266 (2.5%) | 36.24 | 16.91 | 59.86 | 61.85 | 55.32 | 58.17 | 52.10 | 66.23 |
| 533 (5%) | 46.65 | 30.75 | 68.84 | 64.02 | 57.49 | 60.31 | 54.72 | 67.45 |
| 1066 (10%) | 54.15 | 53.73 | 73.38 | 67.52 | 65.45 | 67.22 | 55.97 | 71.69 |
| 2666 (25%) | 67.07 | 68.41 | 75.45 | 70.32 | 67.18 | 69.53 | 69.20 | 73.50 |
| 5332 (50%) | 72.00 | 72.46 | 75.43 | 72.42 | 70.58 | 70.96 | 69.09 | 77.87 |
| 10664 (100%) | 71.91 | 74.15 | 72.31 | 76.37 | 72.34 | 75.52 | 75.30 | 77.93 |
We use the samsum dataset which contains chat conversations and their summarized versions. The task here is for LLMs to learn how best to summarize conversations by learning from pairs of conversations and corresponding summaries. Following table captures how LLMs perform on this task.
| Model | Flan-T5-Base Full Fine-Tune | Flan-T5-Large | Falcon-7B | RP-3B | RP-7B | Llama2-7B | Llama2-13B |
|---|---|---|---|---|---|---|---|
| ROUGE-1 (in %) | 47.23 | 49.21 | 52.18 | 47.75 | 49.96 | 51.71 | 52.97 |
| ROUGE-2 (in %) | 21.01 | 23.39 | 27.84 | 23.53 | 25.94 | 26.86 | 28.32 |
If you would like to contribute to this project, we recommend following the "fork-and-pull" Git workflow.
NOTE: Be sure to merge the latest from "upstream" before making a pull request!
If you have any questions, please reach out to:
LLM Finetuning Hub contains code and insights to finetune various large language models for your use-case.
We stress-test both open-source and close-source LLMs through our Evaluation Framework to check their applicability for real-life business use-cases. Finetuning LLMs has never been easier.
Evaluation Framework • Getting Started • LLM Roadmap • Benchmarks • Contributing
For a holistic evaluation, we will make use of the Evaluation Framework that contains 4 pillars:
Performance Time to Train Cost to Train Inferencing For each of the above four pillars, we are sharing our codebase and insights to:
We are providing scripts that are ready-to-use for:
You can start fine-tuning your choice of LLM in 4 easy steps:
Setup conda environment
wget https://repo.anaconda.com/miniconda/Miniconda3-py38_4.11.0-Linux-x86_64.sh
bash Miniconda3-py38_4.11.0-Linux-x86_64.sh
source ~/.bashrc
conda create --name llm_finetuning python=3.9
conda activate llm_finetuning
Install relevant packages
git clone https://github.com/georgian-io/LLM-Finetuning-Hub.git
cd LLM-Finetuning-Hub/
pip install -r requirements.txt
Finetune your LLM of choice
For instance, to finetune Llama2-7B or Llama2-13B, do the following:
cd llama2/ # navigate to Llama2 folder
python llama2_classification.py --lora_r 8 --epochs 5 --dropout 0.1 --pretrained_ckpt NousResearch/Llama-2-7b-hf # finetune Llama2-7B on newsgroup classification dataset
python llama2_classification_inference.py --experiment <experiment folder> # evaluate finetuned Llama2 7B version
python llama2_summarization.py --lora_r 8 --epochs 1 --dropout 0.1 --pretrained_ckpt NousResearch/Llama-2-13b-hf # finetune Llama2-13B on samsum chat dataset
python llama2_summarization_inference.py --experiment <experiment folder> # evaluate finetuned Llama2 13B version
For instance, to finetune Falcon-7B, do the following:
cd falcon/ # navigate to Falcon folder
python falcon_classification.py --lora_r 8 --epochs 5 --dropout 0.1 # finetune Falcon-7B on newsgroup classification dataset
python falcon_classification_inference.py --experiment <experiment folder> # evaluate finetuned Falcon
python falcon_summarization.py --lora_r 8 --epochs 1 --dropout 0.1 # finetune Falcon-7B on samsum chat dataset
python falcon_summarization_inference.py --experiment <experiment folder> # evaluate finetuned Falcon
For instance, to finetune Flan-T5-Large, do the following:
cd flan-t5/ # navigate to Flan-T5 folder
python flan_classification.py --peft_method prefix --prefix_tokens 20 --epochs 5 # finetune Flan-T5 on newsgroup dataset
python flan_classification_inference.py --experiment <experiment folder> # evaluate finetuned Flan-T5
python flan_summarization.py --peft_method lora --lora_r 8 --epochs 1 # finetune Flan-T5 on samsum chat dataset
python flan_summarization_inference.py --experiment <experiment folder> # evalute finetuned Flan-T5
Zero-shot and Few-shot your LLM of choice
For instance, to use Falcon-7B on newsgroup classification task, do the following:
python falcon_baseline_inference.py --task_type classification --prompt_type zero-shot
python falcon_baseline_inference.py --task_type classification --prompt_type few-shot
To use Falcon-7B on samsum summarization task, do the following:
python falcon_baseline_inference.py --task_type summarization --prompt_type zero-shot
python falcon_baseline_inference.py --task_type summarization --prompt_type few-shot
NOTE: All of our experiments were conducted on the AWS EC2 instance: g5.2xlarge. It has one 24GB Nvidia GPU, and is sufficient to finetune the LLMs in this repository.
Our plan is to perform these experiments on all the LLMs below. To that end, this is a tentative roadmap of the LLMs that we aim to cover, and their corresponding codebase and README links:
| LLM | Benchmarked? | Open-Source? | README | Codebase |
|---|---|---|---|---|
| Flan-T5 | ✅ | ✅ | Link | Folder |
| Falcon | ✅ | ✅ | Link | Folder |
| RedPajama | ✅ | ✅ | Link | Folder |
| Llama-2 | ✅ | ✅ | Link | Folder |
| OpenLlama | ✅ | |||
| SalesForce XGen | ✅ | |||
| Mosaic MPT | ✅ | |||
| Cerebras | ✅ | |||
| Writer Palmyra | ❌ | |||
| OpenAI GPT-3.5 | ❌ | |||
| Google PaLM | ❌ | |||
| Inflection Pi | ❌ |
We benchmark LLMs across the tasks of classification and summarization. More precisely, we finetune LLMs on the following experiments:
Note:
We use the Newsgroup dataset which is a 20-way classification problem. Each document needs to be identified as one of the 20 possible newsgroups. To check how quickly LLMs can learn on small number of samples, we compare them with the likes of BERT and Distilbert. Following table captures how models perform as we increase the number of training samples.
| Training samples (fraction) | Distilbert | Bert | Flan-T5 Large | Falcon-7B | RP-3B | RP-7B | Llama2-7B | Llama2-13B |
|---|---|---|---|---|---|---|---|---|
| 266 (2.5%) | 36.24 | 16.91 | 59.86 | 61.85 | 55.32 | 58.17 | 52.10 | 66.23 |
| 533 (5%) | 46.65 | 30.75 | 68.84 | 64.02 | 57.49 | 60.31 | 54.72 | 67.45 |
| 1066 (10%) | 54.15 | 53.73 | 73.38 | 67.52 | 65.45 | 67.22 | 55.97 | 71.69 |
| 2666 (25%) | 67.07 | 68.41 | 75.45 | 70.32 | 67.18 | 69.53 | 69.20 | 73.50 |
| 5332 (50%) | 72.00 | 72.46 | 75.43 | 72.42 | 70.58 | 70.96 | 69.09 | 77.87 |
| 10664 (100%) | 71.91 | 74.15 | 72.31 | 76.37 | 72.34 | 75.52 | 75.30 | 77.93 |
We use the samsum dataset which contains chat conversations and their summarized versions. The task here is for LLMs to learn how best to summarize conversations by learning from pairs of conversations and corresponding summaries. Following table captures how LLMs perform on this task.
| Model | Flan-T5-Base Full Fine-Tune | Flan-T5-Large | Falcon-7B | RP-3B | RP-7B | Llama2-7B | Llama2-13B |
|---|---|---|---|---|---|---|---|
| ROUGE-1 (in %) | 47.23 | 49.21 | 52.18 | 47.75 | 49.96 | 51.71 | 52.97 |
| ROUGE-2 (in %) | 21.01 | 23.39 | 27.84 | 23.53 | 25.94 | 26.86 | 28.32 |
If you would like to contribute to this project, we recommend following the "fork-and-pull" Git workflow.
NOTE: Be sure to merge the latest from "upstream" before making a pull request!
If you have any questions, please reach out to:



