
Physics of Language Models: Part 4.2, Canon Layers at Scale where Synthetic Pretraining Resonates in Reality
HTML
361
8 commits
updated Aug 21, 2026
README
Physics of Language Models: Part 4.2, Canon Layers at Scale where Synthetic Pretraining Resonates in Reality


Author: Zeyuan Allen-Zhu
Repository update: I no longer work at FAIR. This repository has moved to github.com/zhuzeyuan/PhysicsLM4, where all future updates will be maintained.
Welcome to this code repository for the Physics of Language Models series. This repository provides all the resources required to reproduce results from the series' Part 4, as well as relevant contributions from Parts 1, 3.1, and 3.3. Below, we describe the key components of this release.
📑Repository Contents
🔴 Data Generators: data-synthetic-pretrain and data-reallife-eval
The synthetic pretraining playground includes the Depo, Brevo, Capo, Mano, and Lano datasets introduced in Physics of Language Models: Part 4.1 — Architecture Design and the Magic of Canon Layers. Three are trivial to reimplement; the remaining two are provided here:
- Lano — also featured in Part 1: Learning Hierarchical Language Structures.
- Capo — includes bioS and bioR generators from Part 3.1: Knowledge Storage and Extraction and Part 3.3: Knowledge Capacity Scaling Laws.
- Depo, Brevo, Mano — includes Depo1, Depo2, Brevo1, Brevo2 and Mano datasets used in Part 4.1: Architecture Design and the Magic of Canon Layers.
The real-life experiments in Part 4.1 also used the following evaluation tasks:
- multi-hop — a birth-year multi-hop in-context retrieval task, arguably the simplest and most natural real-life multi-hop benchmark.
- Babilong — slightly modified few-shot prompts from the original Babilong evaluation setup.
🔴 huggingface and huggingface_linear
Huggingface-style models that add Canon layer supports, as highlighted in Physics of Language Models: Part 4.1:
- Current models:
- LlamaCanon: Includes Canon layers, QK-norm, and partial RoPE support (see
huggingface) - GLA (with GLA5 modifications), GDN (with GDN2 modifications), and Mamba2 models (see
huggingface_linear)
- LlamaCanon: Includes Canon layers, QK-norm, and partial RoPE support (see
🔴 lingua_modified
A modified version of Meta’s Lingua codebase which is optimized for efficient pretraining. Key modifications include:
- For Transformer(Llama) training:
- Added support for Canon-ABCD layers, QK-norm, z-loss, and partial RoPE for Transformer.
- Compatibility with the above Hugging Face
LlamaCanonmodel (bonus: aload_from_lingua_statemethod for seamless loading of Lingua state_dicts).
cd lingua_modified
python -m lingua.stool script=apps.main.train nodes=1 config=apps/main/configs/canon_1B.yaml account=<bla> qos=<bla>
- For Linear model (GLA/GDN/Mamba2) training:
- Added support for Canon-AbCD layers
- Using low-rank gating on GLA / GDN (codenames GLA5 and GDN2)
cd lingua_modified
python -m lingua.stool script=apps.gla.train nodes=1 config=apps/gla/configs/gla5_1B.yaml account=<bla> qos=<bla>
python -m lingua.stool script=apps.gla.train nodes=1 config=apps/gla/configs/gdn2_1B.yaml account=<bla> qos=<bla>
python -m lingua.stool script=apps.gla.train nodes=1 config=apps/gla/configs/mamba2_1B.yaml account=<bla> qos=<bla>
🔴 canon_llama_recipes
Comprehensive training recipes (YAML files) for reproducing our 16 released Llama/LlamaCanon model weights on Hugging Face.


🔴 canon_llama_results
Complete evaluation results for the 16 released Llama models:
-
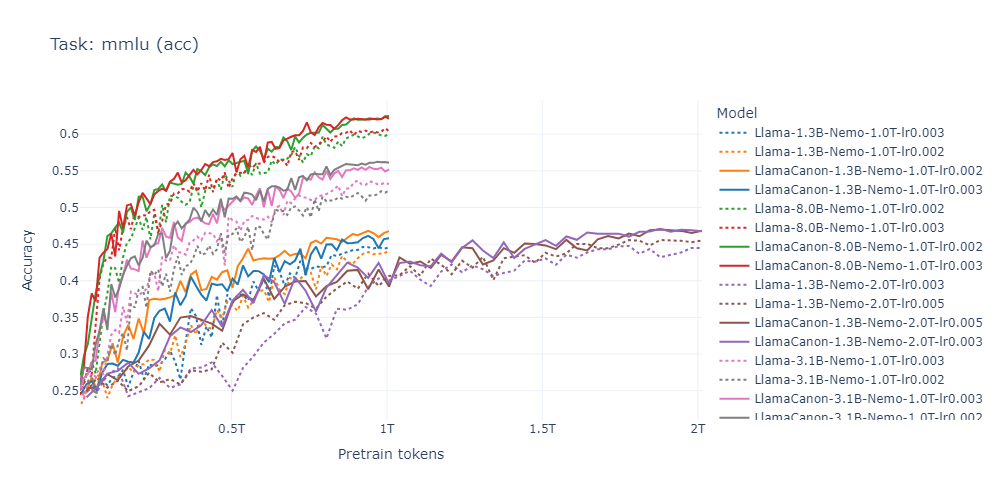
Strong controlled experiments to highlight the benefits of Canon layers by comparing Llama vs. LlamaCanon in real-world pretraining settings.
-
Includes interactive training-time charts for benchmarks like MMLU.
-
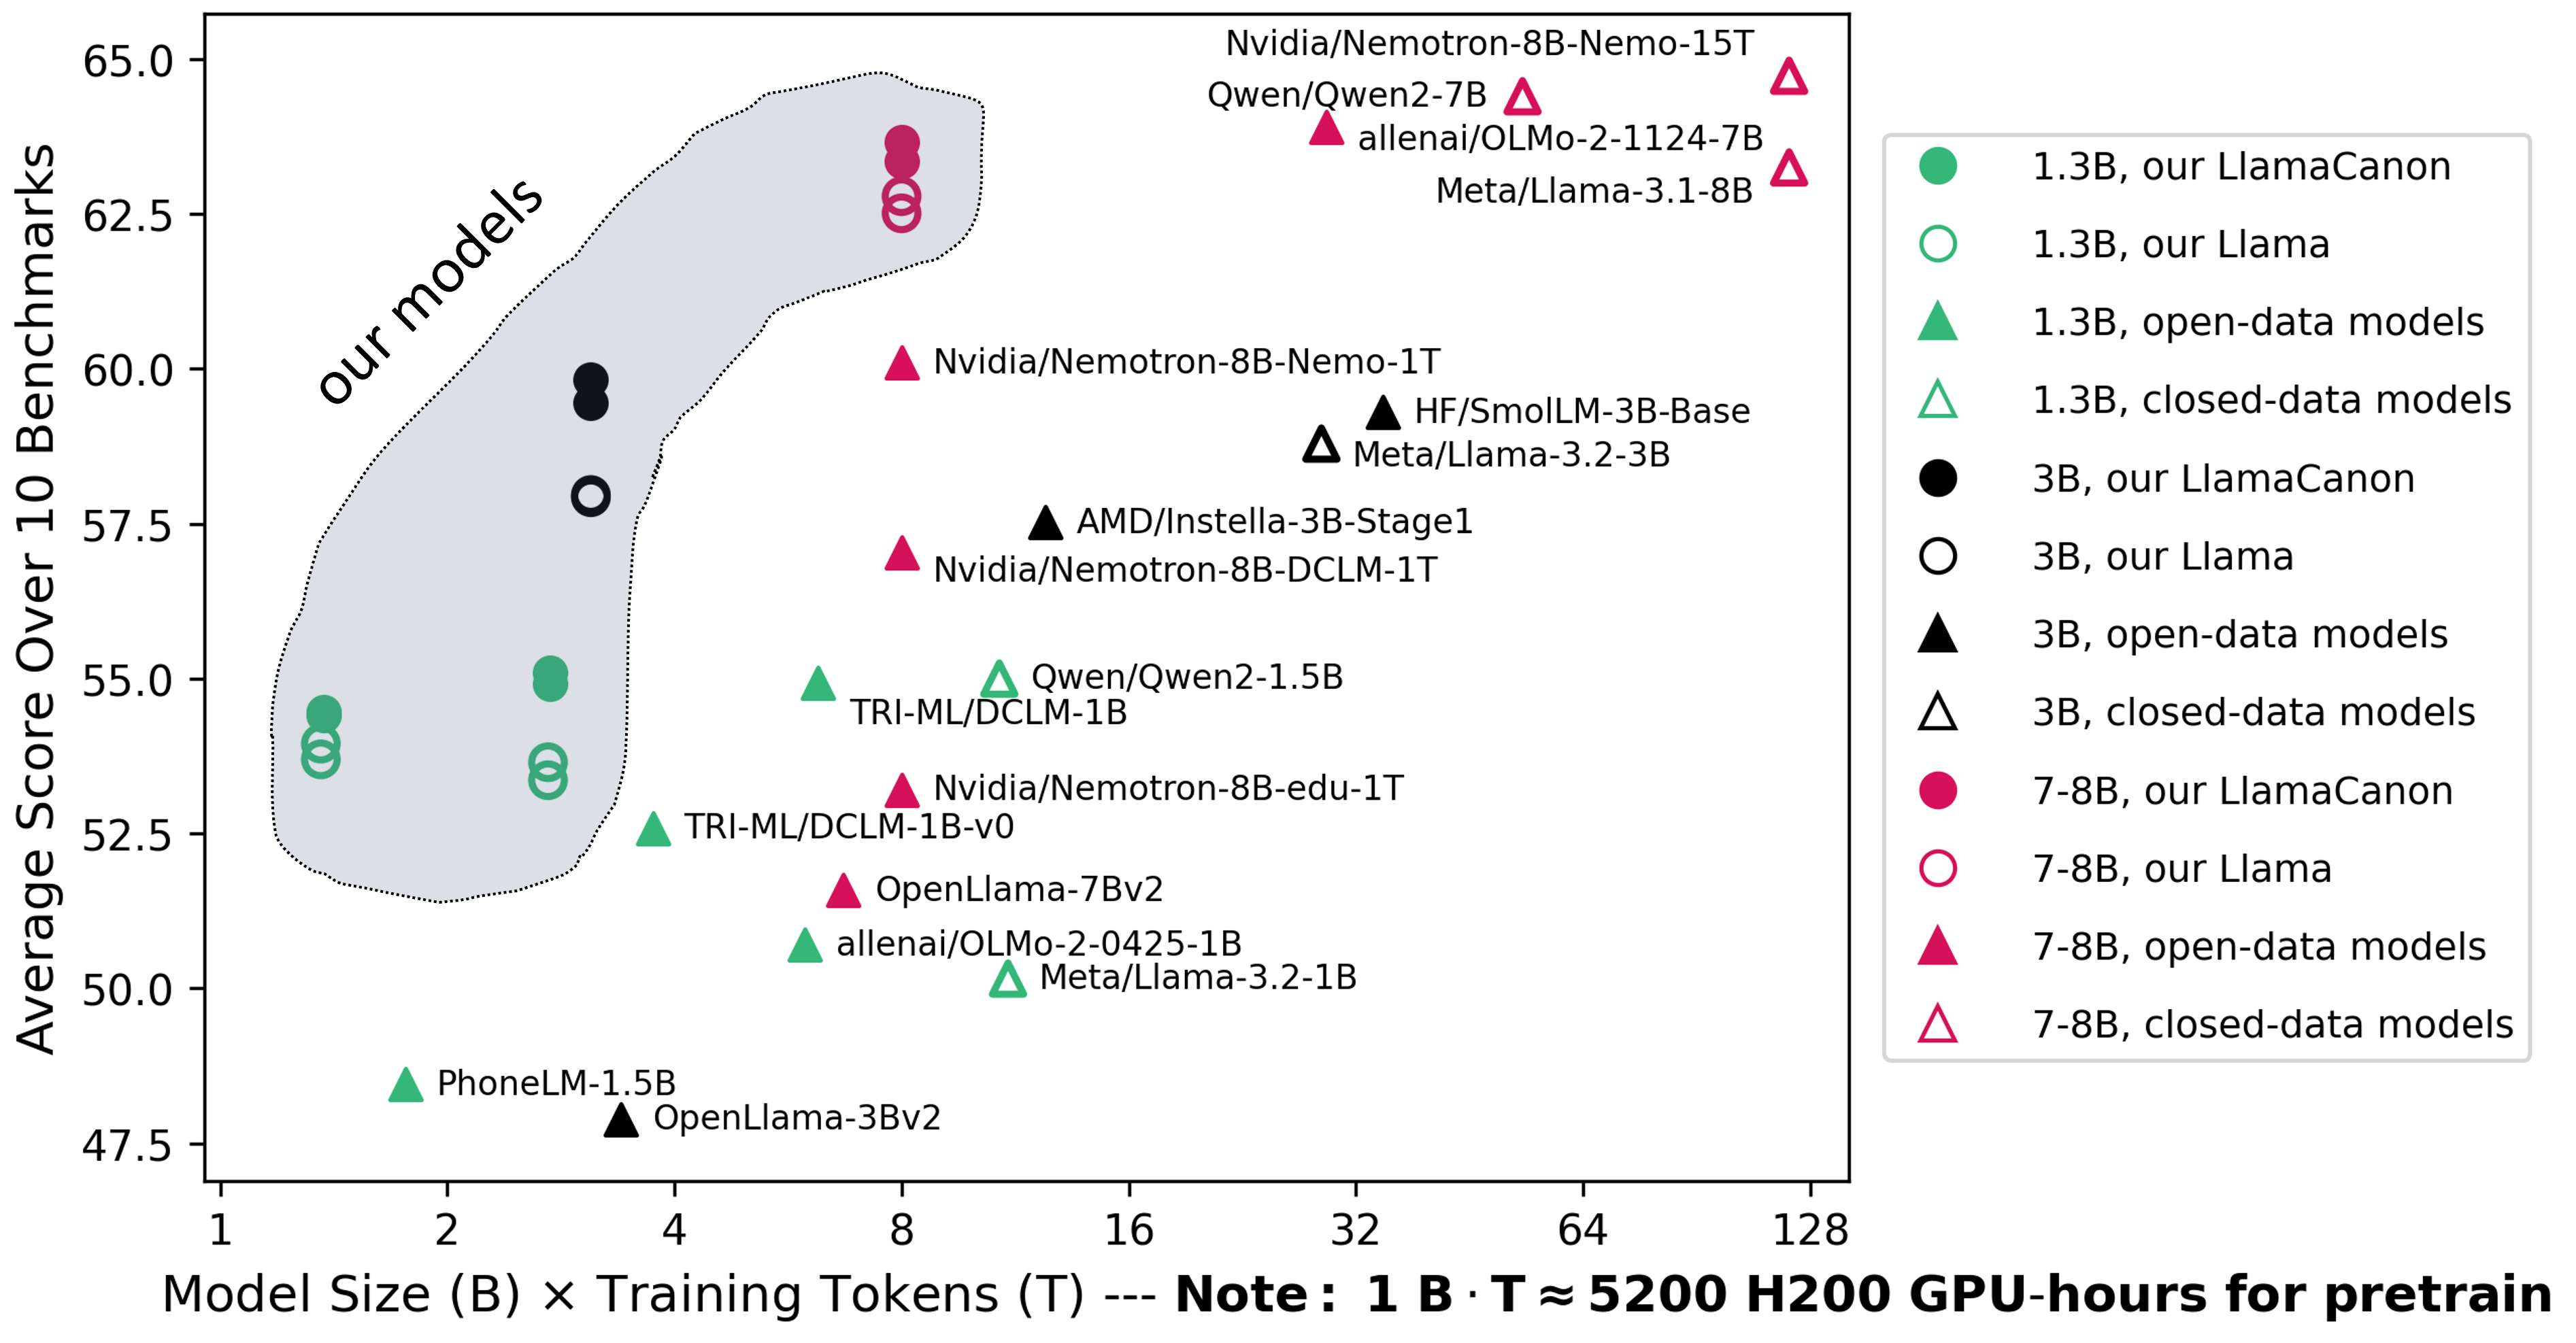
Benchmarks our models against other open-source models, demonstrating that we have conducted evaluations in a realistic pretraining setup rather than relying on artificial scenarios.
🔴 canon_linear_recipes
Comprehensive training recipes (YAML files) for reproducing our 48 linear model weights (GLA5/GDN2/Mamba2 with and without Canon layers).
🔴 canon_linear_results
Complete evaluation results for the 48 linear models vs 18 Llama models.
These results from real-life pretraining may be officially published as part of Physics of Language Models: Part 4.2 if time permits.
📖Citations
If you use this repository in your research, please cite the following:
@inproceedings{Allen2025-canon,
  author = {{Allen-Zhu}, Zeyuan},
  title = {{Physics of Language Models: Part 4.1, Architecture Design and the Magic of Canon Layers}},
  year = {2025},
  booktitle = {Proceedings of the 39th Conference on Neural Information Processing Systems},
  series = {NeurIPS~'25},
  note = {Full version available at \url{https://ssrn.com/abstract=5240330}}
}
@misc{Allen2025-resonate,
    title = {{Physics of Language Models: Part 4.2, Canon Layers at Scale where Synthetic Pretraining Resonates in Reality}},
    author = {{Allen-Zhu}, Zeyuan},
    year = {2025},
    url = {https://physics.allen-zhu.com/part-4-architecture-design/part-4-2},
    note = {Code released at \url{https://github.com/facebookresearch/PhysicsLM4}},
}
License
- Original contributions in this repository are all licensed under Apache 2.0.
- Modifications to the Lingua codebase adhere to its original BSD-3-Clause license (see
lingua_modified/README.mdfor details).
Contributors

7 commits

1 commits
Similar repos

Languages
HTML
84.4%
Python
15.6%
Physics of Language Models: Part 4.2, Canon Layers at Scale where Synthetic Pretraining Resonates in Reality
HTML
361
8 commits
updated Aug 21, 2026
README
Physics of Language Models: Part 4.2, Canon Layers at Scale where Synthetic Pretraining Resonates in Reality
Author: Zeyuan Allen-Zhu
Repository update: I no longer work at FAIR. This repository has moved to github.com/zhuzeyuan/PhysicsLM4, where all future updates will be maintained.
Welcome to this code repository for the Physics of Language Models series. This repository provides all the resources required to reproduce results from the series' Part 4, as well as relevant contributions from Parts 1, 3.1, and 3.3. Below, we describe the key components of this release.
📑Repository Contents
🔴 Data Generators: data-synthetic-pretrain and data-reallife-eval
The synthetic pretraining playground includes the Depo, Brevo, Capo, Mano, and Lano datasets introduced in Physics of Language Models: Part 4.1 — Architecture Design and the Magic of Canon Layers. Three are trivial to reimplement; the remaining two are provided here:
- Lano — also featured in Part 1: Learning Hierarchical Language Structures.
- Capo — includes bioS and bioR generators from Part 3.1: Knowledge Storage and Extraction and Part 3.3: Knowledge Capacity Scaling Laws.
- Depo, Brevo, Mano — includes Depo1, Depo2, Brevo1, Brevo2 and Mano datasets used in Part 4.1: Architecture Design and the Magic of Canon Layers.
The real-life experiments in Part 4.1 also used the following evaluation tasks:
- multi-hop — a birth-year multi-hop in-context retrieval task, arguably the simplest and most natural real-life multi-hop benchmark.
- Babilong — slightly modified few-shot prompts from the original Babilong evaluation setup.
🔴 huggingface and huggingface_linear
Huggingface-style models that add Canon layer supports, as highlighted in Physics of Language Models: Part 4.1:
- Current models:
- LlamaCanon: Includes Canon layers, QK-norm, and partial RoPE support (see
huggingface) - GLA (with GLA5 modifications), GDN (with GDN2 modifications), and Mamba2 models (see
huggingface_linear)
- LlamaCanon: Includes Canon layers, QK-norm, and partial RoPE support (see
🔴 lingua_modified
A modified version of Meta’s Lingua codebase which is optimized for efficient pretraining. Key modifications include:
- For Transformer(Llama) training:
- Added support for Canon-ABCD layers, QK-norm, z-loss, and partial RoPE for Transformer.
- Compatibility with the above Hugging Face
LlamaCanonmodel (bonus: aload_from_lingua_statemethod for seamless loading of Lingua state_dicts).
cd lingua_modified
python -m lingua.stool script=apps.main.train nodes=1 config=apps/main/configs/canon_1B.yaml account=<bla> qos=<bla>
- For Linear model (GLA/GDN/Mamba2) training:
- Added support for Canon-AbCD layers
- Using low-rank gating on GLA / GDN (codenames GLA5 and GDN2)
cd lingua_modified
python -m lingua.stool script=apps.gla.train nodes=1 config=apps/gla/configs/gla5_1B.yaml account=<bla> qos=<bla>
python -m lingua.stool script=apps.gla.train nodes=1 config=apps/gla/configs/gdn2_1B.yaml account=<bla> qos=<bla>
python -m lingua.stool script=apps.gla.train nodes=1 config=apps/gla/configs/mamba2_1B.yaml account=<bla> qos=<bla>
🔴 canon_llama_recipes
Comprehensive training recipes (YAML files) for reproducing our 16 released Llama/LlamaCanon model weights on Hugging Face.
🔴 canon_llama_results
Complete evaluation results for the 16 released Llama models:
-
Strong controlled experiments to highlight the benefits of Canon layers by comparing Llama vs. LlamaCanon in real-world pretraining settings.
-
Includes interactive training-time charts for benchmarks like MMLU.
-
Benchmarks our models against other open-source models, demonstrating that we have conducted evaluations in a realistic pretraining setup rather than relying on artificial scenarios.
🔴 canon_linear_recipes
Comprehensive training recipes (YAML files) for reproducing our 48 linear model weights (GLA5/GDN2/Mamba2 with and without Canon layers).
🔴 canon_linear_results
Complete evaluation results for the 48 linear models vs 18 Llama models.
These results from real-life pretraining may be officially published as part of Physics of Language Models: Part 4.2 if time permits.
📖Citations
If you use this repository in your research, please cite the following:
@inproceedings{Allen2025-canon,
  author = {{Allen-Zhu}, Zeyuan},
  title = {{Physics of Language Models: Part 4.1, Architecture Design and the Magic of Canon Layers}},
  year = {2025},
  booktitle = {Proceedings of the 39th Conference on Neural Information Processing Systems},
  series = {NeurIPS~'25},
  note = {Full version available at \url{https://ssrn.com/abstract=5240330}}
}
@misc{Allen2025-resonate,
    title = {{Physics of Language Models: Part 4.2, Canon Layers at Scale where Synthetic Pretraining Resonates in Reality}},
    author = {{Allen-Zhu}, Zeyuan},
    year = {2025},
    url = {https://physics.allen-zhu.com/part-4-architecture-design/part-4-2},
    note = {Code released at \url{https://github.com/facebookresearch/PhysicsLM4}},
}
License
- Original contributions in this repository are all licensed under Apache 2.0.
- Modifications to the Lingua codebase adhere to its original BSD-3-Clause license (see
lingua_modified/README.mdfor details).
Similar repos
Contributors
7 commits
1 commits
Languages
HTML
84.4%
Python
15.6%