
README
HoneyBee: Data Recipes for Vision-Language Reasoners
This is the official repo for the paper: https://arxiv.org/abs/2510.12225.
Dataset is available on huggingface: https://huggingface.co/datasets/facebook/HoneyBee
Abstract
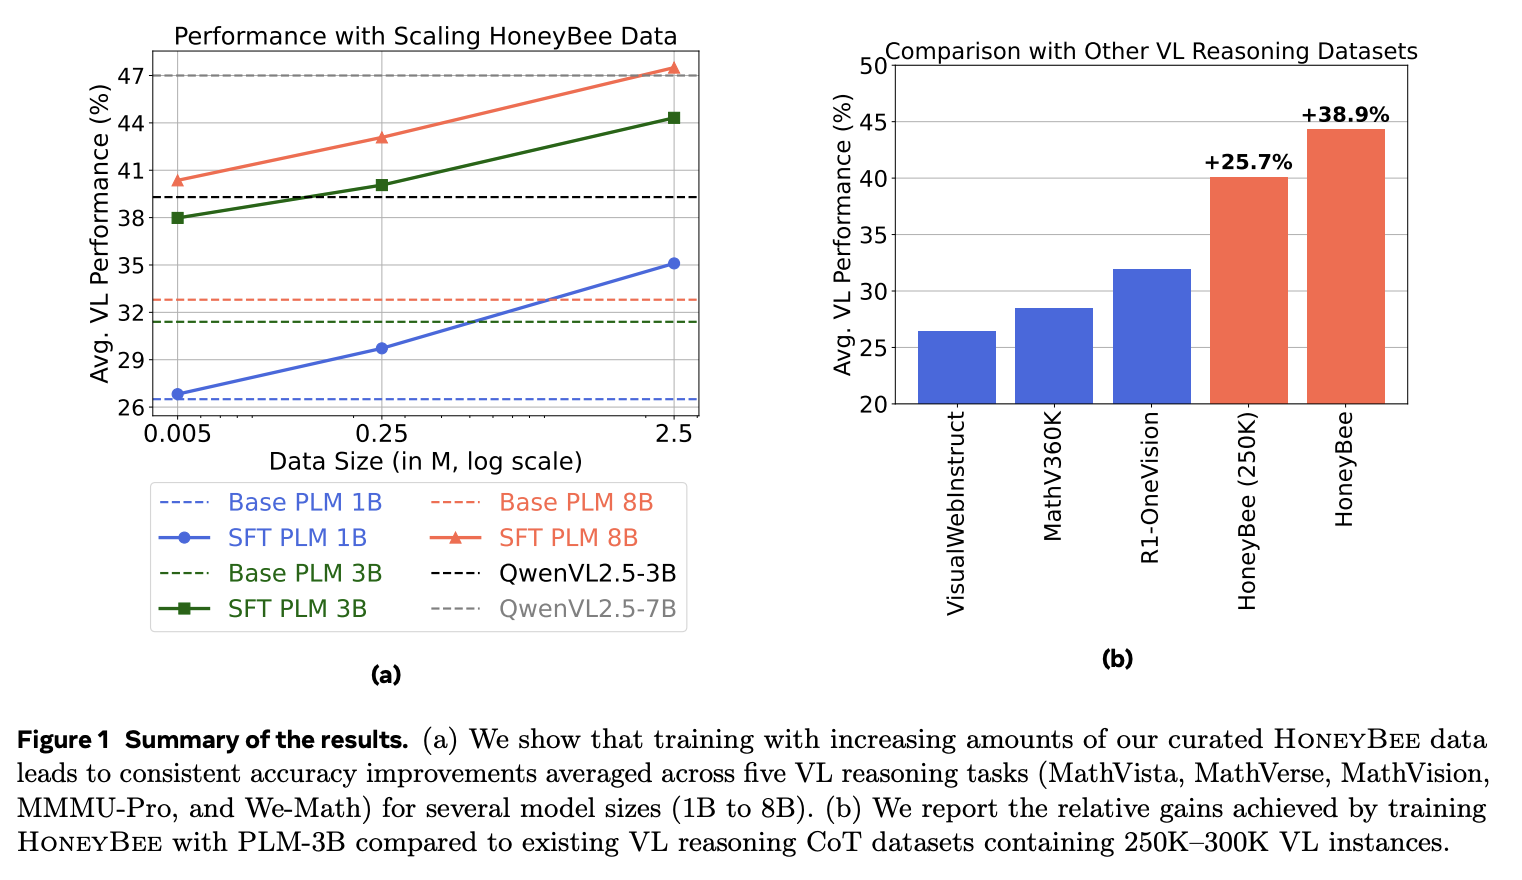
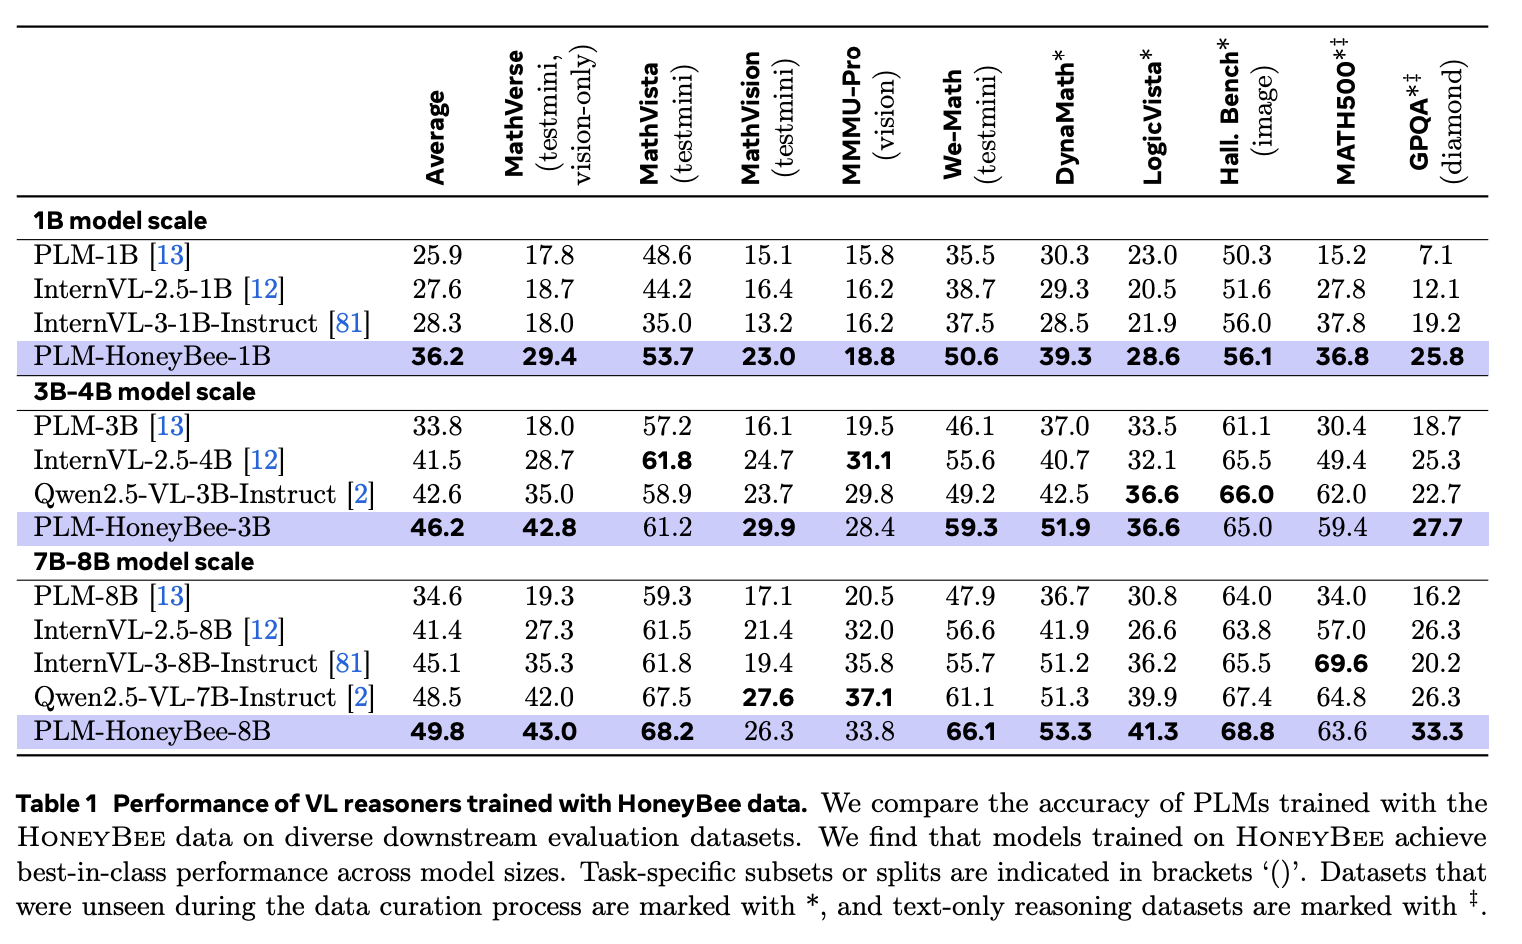
Recent advances in vision-language models (VLMs) have made them highly effective at reasoning tasks. However, the principles underlying the construction of performant VL reasoning training datasets remain poorly understood. In this work, we introduce several data curation approaches and study their impacts on VL reasoning capabilities by carefully controlling training and evaluation setups. We analyze the effects of context (image and question pair) sources, implement targeted data interventions, and explore scaling up images, questions, and chain-of-thought (CoT) solutions. Our findings reveal that (a) context source strategies significantly affect VLM performance, (b) interventions such as auxiliary signals from image captions and the inclusion of text-only reasoning yield substantial gains, and (c) scaling all data dimensions (e.g., unique questions per image and unique CoTs per image-question pair) consistently improves reasoning capability. Motivated by these insights, we introduce HoneyBee, a large-scale, high-quality CoT reasoning dataset with 2.5M examples consisting 350K image-question pairs. VLMs trained with HoneyBee outperform state-of-the-art models across model sizes. For instance, a HoneyBee-trained VLM with 3B parameters outperforms the SOTA model and the base model by 7.8% and 24.8%, respectively, on MathVerse. Furthermore, we propose a test-time scaling strategy that reduces decoding cost by 73% without sacrificing accuracy. Overall, this work presents improved strategies for VL reasoning dataset curation research.
Evaluation
- We provide a self-contained evaluation code for all the 10 eval datasets used in this work.
- Currently, the script works for the base PLM models (in huggingface format) that do not generate chain-of-thoughts (CoTs). But you can easily adapt to any other HF model.
- Installation:
transformersfor model support, andmathrulerfor grading. - Launching generations on multiple GPUs:
torchrun --nproc-per-node 8 eval_plm_multi_hf.py --dataset mathverse --model_path facebook/Perception-LM-1B --name plm1b
- Scoring generations:
python score.py --output_dir outputs/mathverse_plm1b/
Training
- We are not planning to release the trained VLMs. But, you can use the publicly available dataset to train custom VLMs.
- The code for training Perception LMs is already publicly available at: https://github.com/facebookresearch/perception_models
- We provide the training yamls in configs.
Results of Training PLMs with HoneyBee
License
Use of this repository and related resources are governed by CC-By-NC. More details are present in the LICENSE file.
Citation
@article{bansal2025honeybee,
  title={HoneyBee: Data Recipes for Vision-Language Reasoners},
  author={Bansal, Hritik and Sachan, Devandra Singh and Chang, Kai-Wei and Grover, Aditya and Ghosh, Gargi and Yih, Wen-tau and Pasunuru, Ramakanth},
  journal={arXiv preprint arXiv:2510.12225},
  year={2025}
}
Similar repos



Languages
Python
100.0%
README
HoneyBee: Data Recipes for Vision-Language Reasoners
This is the official repo for the paper: https://arxiv.org/abs/2510.12225.
Dataset is available on huggingface: https://huggingface.co/datasets/facebook/HoneyBee
Abstract
Recent advances in vision-language models (VLMs) have made them highly effective at reasoning tasks. However, the principles underlying the construction of performant VL reasoning training datasets remain poorly understood. In this work, we introduce several data curation approaches and study their impacts on VL reasoning capabilities by carefully controlling training and evaluation setups. We analyze the effects of context (image and question pair) sources, implement targeted data interventions, and explore scaling up images, questions, and chain-of-thought (CoT) solutions. Our findings reveal that (a) context source strategies significantly affect VLM performance, (b) interventions such as auxiliary signals from image captions and the inclusion of text-only reasoning yield substantial gains, and (c) scaling all data dimensions (e.g., unique questions per image and unique CoTs per image-question pair) consistently improves reasoning capability. Motivated by these insights, we introduce HoneyBee, a large-scale, high-quality CoT reasoning dataset with 2.5M examples consisting 350K image-question pairs. VLMs trained with HoneyBee outperform state-of-the-art models across model sizes. For instance, a HoneyBee-trained VLM with 3B parameters outperforms the SOTA model and the base model by 7.8% and 24.8%, respectively, on MathVerse. Furthermore, we propose a test-time scaling strategy that reduces decoding cost by 73% without sacrificing accuracy. Overall, this work presents improved strategies for VL reasoning dataset curation research.
Evaluation
- We provide a self-contained evaluation code for all the 10 eval datasets used in this work.
- Currently, the script works for the base PLM models (in huggingface format) that do not generate chain-of-thoughts (CoTs). But you can easily adapt to any other HF model.
- Installation:
transformersfor model support, andmathrulerfor grading. - Launching generations on multiple GPUs:
torchrun --nproc-per-node 8 eval_plm_multi_hf.py --dataset mathverse --model_path facebook/Perception-LM-1B --name plm1b
- Scoring generations:
python score.py --output_dir outputs/mathverse_plm1b/
Training
- We are not planning to release the trained VLMs. But, you can use the publicly available dataset to train custom VLMs.
- The code for training Perception LMs is already publicly available at: https://github.com/facebookresearch/perception_models
- We provide the training yamls in configs.
Results of Training PLMs with HoneyBee
License
Use of this repository and related resources are governed by CC-By-NC. More details are present in the LICENSE file.
Citation
@article{bansal2025honeybee,
  title={HoneyBee: Data Recipes for Vision-Language Reasoners},
  author={Bansal, Hritik and Sachan, Devandra Singh and Chang, Kai-Wei and Grover, Aditya and Ghosh, Gargi and Yih, Wen-tau and Pasunuru, Ramakanth},
  journal={arXiv preprint arXiv:2510.12225},
  year={2025}
}
Similar repos
Languages
Python
100.0%