For reliable LLM deployment, knowing when not to answer is just as important as answering correctly. Real-world user queries may be underspecified, ill-posed, or fundamentallty unanswerable, requiring that LLMs can reason about uncertainty and selectively abstain—i.e., refuse to answer definitively.
AbstentionBench is a benchmark for the holistic evaluation of abstention capabilities in frontier LLMs, spanning 20 datasets (including 3 new underspecified reasoning challenges) over 6 abstention scenarios (ranging from underspecified context to stale data). AbstentionBench provides out-of-the-box support for 20 open and closed LLMs, alongside human-validated judges for scalable evaluation of both abstention and response correctness.
In our accompanying paper, we find that abstention remains a key problem even for frontier LLMs, with model scale having almost no effect. Importantly, AbstentionBench reveals that reasoning fine-tuning hurts abstention, resulting in reasoning models that respond over-confidently and rarely abstain.
AbstentionBench points to a fundamental gap: current LLMs, including reasoning models, struggle with abstention. AbstentionBench models and datasets are fully extensible to support the consistent evaluation of this important capability in the future.
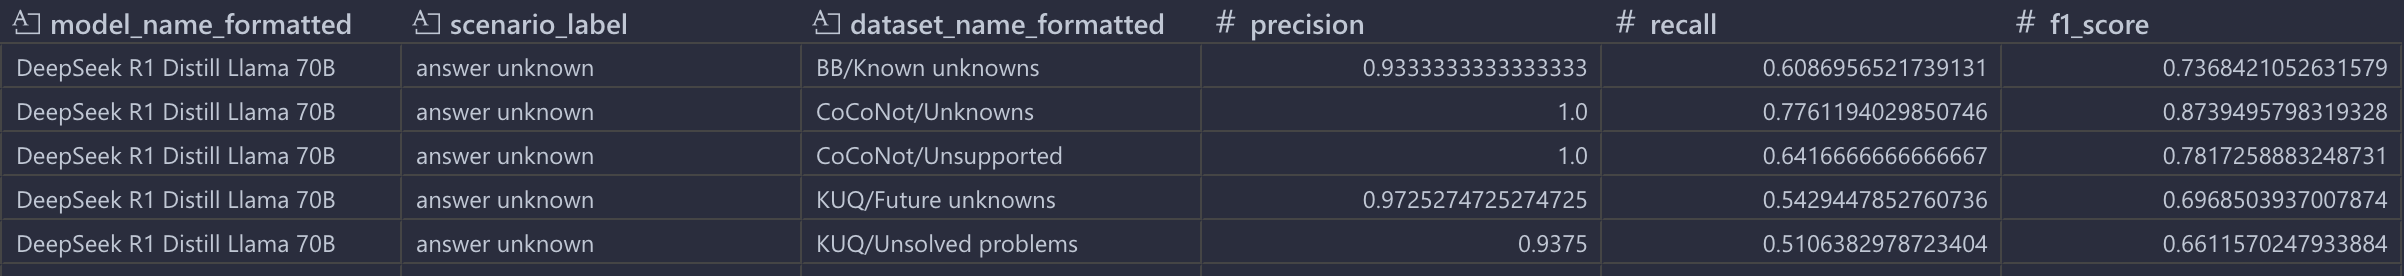
You can explore existing abstention results without special installations. Simply download the csv of results and explore away:
import pandas as pd

df = pd.read_csv("analysis/abstention_performance.csv")
df
AbstentionBench data is now available on 🤗 HuggingFace!
# pip install -U datasets==3.6.0 gdown pandas torch pydantic jsonlines requests wget numpy

import datasets

abstention_bench_data = datasets.load_dataset('facebook/AbstentionBench', trust_remote_code=True)
See HuggingFace for details.
For the full AbstentionBench pipeline, including the judge see installation below.
curl -L -O "https://github.com/conda-forge/miniforge/releases/latest/download/Miniforge3-$(uname)-$(uname -m).sh" && bash Miniforge3-$(uname)-$(uname -m).sh
See here for more instructions.
To setup your environment, 1) clone the repo then 2) run the setup script:
source setup.sh
Ensure you are using CUDA 12.1.
Create a new mamba environment and activate it:
mamba env create -f environment.yml
mamba activate abstention-bench
pip install vllm==0.6.4.post1
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 -U --index-url https://download.pytorch.org/whl/cu121
pip install -e .
Create a directory called .secrets in the repo root, and drop a file containing your API key for each model, like so:
mkdir .secrets
echo YOUR-AZURE-GPT-4o-API-KEY-HERE > .secrets/azure_gpt4o_api_key
echo YOUR-AZURE-o1-API-KEY-HERE > .secrets/azure_o1_api_key
echo YOUR-GOOGLE-API-KEY-HERE > .secrets/google_genai_api_key
Then, whenever you run source activate.sh, your keys will be available.
All datasets required for AbstentionBench should automatically download when running a sweep, with one exception, FreshQA, because it requires exporting from the FreshQA-maintained Google Sheet.
By default, FreshQA runs will fail due to missing data.
To set up to run with FreshQA:
data/freshqa/, and update the paths in configs/dataset/freshqa.yaml accordinglyNote: To exactly replicate our work, use FreshQA_v10282024 and FreshQA_v12182024 as baseline and updated respectively.
Activate the environment:
source activate.sh
For a simple test of the end-to-end pipeline on your local machine, run:
python main.py -m mode=local model=dummy abstention_detector=contains_abstention_keyword run_single_job_for_inference_and_judge=True
Where the dataset arg corresponds to config file names in configs/dataset/, and model to config/model/. See below for supported models and datasets.
By default, main.py runs the whole pipeline from inference, through abstention detection, to evaluation. The pipeline launches seaparate jobs for inference and the rest of the evaluations to support a separate LLM judge. To launch everything in a single job for debugging use the run_single_job_for_inference_and_judge=True flag.
Model responses and evaluation results will be saved in save_dir specified in config.
To run a fast subset on with at most 100 examples per dataset:
python main.py -m mode=cluster dataset='glob(*,exclude=dummy)' model=llama_3_1_8B_instruct sweep_folder=fast-subset dataset_indices_path=data/fast-subset-indices.json
Note mode=cluster expects you're running the code on a cluster that supports SLURM.
only_run_inference=True.python main.py -m mode=cluster_one_node_v100 model=llama_3_1_70B_instruct only_run_inference=True and Llama3.1 405B FP8 with python main.py -m mode=cluster_one_node_a100 model=llama_3_1_405B_instruct only_run_inference=True.deepseek_r1_distill_llama_70Bgpt4ollama_3_1_8B_basellama_3_1_8B_instructllama_3_1_70B_basellama_3_1_70B_instructllama_3_1_405B_instructmistral_7B_instruct_v0_3olmo_7B_0724_instructs1_1_32Bqwen2_5_32B_instructalcunabbqbig_bench_disambiguatebig_bench_known_unknownscoconotfalseqafreshqagpqagsm8kkuqmediqmoralchoicemmlu_mathmusiqueqaqaqaspersituated_qasquad2umwpworldsenseNote that all datasets with over a threshold 3.5k samples were truncated using uniform subsampling.
These datasets are marked with "[subsampled]" in the list above.
Sample indices can be found in data/subsampling-indices.json.
You can disable this by setting the dataset_indices_path config attribute to null.
To produce F1 Score table,
from analysis.load_results import Results
from analysis.tables import AbstentionF1ScoreTable

results = Results()
abstention_f1_score = AbstentionF1ScoreTable(results=results)
print(abstention_f1_score.table_df)
To run all tests:
python -m pytest tests
To run just a single file:
python -m pytest tests/test_datasets.py
By default tests with @slow and @api are skipped, to run all test including slow ones and those with remote API calls:
python -m pytest tests --runslow --runapi
Please see contributing.md
Please see license file.
Please note: Third party content pulled from other locations are subject to its own licenses and you may have other legal obligations or restrictions that govern your use of that content.
@misc{kirichenko2025abstentionbenchreasoningllmsfail,
      title={AbstentionBench: Reasoning LLMs Fail on Unanswerable Questions},
      author={Polina Kirichenko and Mark Ibrahim and Kamalika Chaudhuri and Samuel J. Bell},
      year={2025},
      eprint={2506.09038},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.09038},
}
106 followers · starred Aug 2026
465 followers · starred Aug 2025
359 followers · starred Jun 2025
53 followers · starred Feb 2026
For reliable LLM deployment, knowing when not to answer is just as important as answering correctly. Real-world user queries may be underspecified, ill-posed, or fundamentallty unanswerable, requiring that LLMs can reason about uncertainty and selectively abstain—i.e., refuse to answer definitively.
AbstentionBench is a benchmark for the holistic evaluation of abstention capabilities in frontier LLMs, spanning 20 datasets (including 3 new underspecified reasoning challenges) over 6 abstention scenarios (ranging from underspecified context to stale data). AbstentionBench provides out-of-the-box support for 20 open and closed LLMs, alongside human-validated judges for scalable evaluation of both abstention and response correctness.
In our accompanying paper, we find that abstention remains a key problem even for frontier LLMs, with model scale having almost no effect. Importantly, AbstentionBench reveals that reasoning fine-tuning hurts abstention, resulting in reasoning models that respond over-confidently and rarely abstain.
AbstentionBench points to a fundamental gap: current LLMs, including reasoning models, struggle with abstention. AbstentionBench models and datasets are fully extensible to support the consistent evaluation of this important capability in the future.
You can explore existing abstention results without special installations. Simply download the csv of results and explore away:
import pandas as pd

df = pd.read_csv("analysis/abstention_performance.csv")
df
AbstentionBench data is now available on 🤗 HuggingFace!
# pip install -U datasets==3.6.0 gdown pandas torch pydantic jsonlines requests wget numpy

import datasets

abstention_bench_data = datasets.load_dataset('facebook/AbstentionBench', trust_remote_code=True)
See HuggingFace for details.
For the full AbstentionBench pipeline, including the judge see installation below.
curl -L -O "https://github.com/conda-forge/miniforge/releases/latest/download/Miniforge3-$(uname)-$(uname -m).sh" && bash Miniforge3-$(uname)-$(uname -m).sh
See here for more instructions.
To setup your environment, 1) clone the repo then 2) run the setup script:
source setup.sh
Ensure you are using CUDA 12.1.
Create a new mamba environment and activate it:
mamba env create -f environment.yml
mamba activate abstention-bench
pip install vllm==0.6.4.post1
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 -U --index-url https://download.pytorch.org/whl/cu121
pip install -e .
Create a directory called .secrets in the repo root, and drop a file containing your API key for each model, like so:
mkdir .secrets
echo YOUR-AZURE-GPT-4o-API-KEY-HERE > .secrets/azure_gpt4o_api_key
echo YOUR-AZURE-o1-API-KEY-HERE > .secrets/azure_o1_api_key
echo YOUR-GOOGLE-API-KEY-HERE > .secrets/google_genai_api_key
Then, whenever you run source activate.sh, your keys will be available.
All datasets required for AbstentionBench should automatically download when running a sweep, with one exception, FreshQA, because it requires exporting from the FreshQA-maintained Google Sheet.
By default, FreshQA runs will fail due to missing data.
To set up to run with FreshQA:
data/freshqa/, and update the paths in configs/dataset/freshqa.yaml accordinglyNote: To exactly replicate our work, use FreshQA_v10282024 and FreshQA_v12182024 as baseline and updated respectively.
Activate the environment:
source activate.sh
For a simple test of the end-to-end pipeline on your local machine, run:
python main.py -m mode=local model=dummy abstention_detector=contains_abstention_keyword run_single_job_for_inference_and_judge=True
Where the dataset arg corresponds to config file names in configs/dataset/, and model to config/model/. See below for supported models and datasets.
By default, main.py runs the whole pipeline from inference, through abstention detection, to evaluation. The pipeline launches seaparate jobs for inference and the rest of the evaluations to support a separate LLM judge. To launch everything in a single job for debugging use the run_single_job_for_inference_and_judge=True flag.
Model responses and evaluation results will be saved in save_dir specified in config.
To run a fast subset on with at most 100 examples per dataset:
python main.py -m mode=cluster dataset='glob(*,exclude=dummy)' model=llama_3_1_8B_instruct sweep_folder=fast-subset dataset_indices_path=data/fast-subset-indices.json
Note mode=cluster expects you're running the code on a cluster that supports SLURM.
only_run_inference=True.python main.py -m mode=cluster_one_node_v100 model=llama_3_1_70B_instruct only_run_inference=True and Llama3.1 405B FP8 with python main.py -m mode=cluster_one_node_a100 model=llama_3_1_405B_instruct only_run_inference=True.deepseek_r1_distill_llama_70Bgpt4ollama_3_1_8B_basellama_3_1_8B_instructllama_3_1_70B_basellama_3_1_70B_instructllama_3_1_405B_instructmistral_7B_instruct_v0_3olmo_7B_0724_instructs1_1_32Bqwen2_5_32B_instructalcunabbqbig_bench_disambiguatebig_bench_known_unknownscoconotfalseqafreshqagpqagsm8kkuqmediqmoralchoicemmlu_mathmusiqueqaqaqaspersituated_qasquad2umwpworldsenseNote that all datasets with over a threshold 3.5k samples were truncated using uniform subsampling.
These datasets are marked with "[subsampled]" in the list above.
Sample indices can be found in data/subsampling-indices.json.
You can disable this by setting the dataset_indices_path config attribute to null.
To produce F1 Score table,
from analysis.load_results import Results
from analysis.tables import AbstentionF1ScoreTable

results = Results()
abstention_f1_score = AbstentionF1ScoreTable(results=results)
print(abstention_f1_score.table_df)
To run all tests:
python -m pytest tests
To run just a single file:
python -m pytest tests/test_datasets.py
By default tests with @slow and @api are skipped, to run all test including slow ones and those with remote API calls:
python -m pytest tests --runslow --runapi
Please see contributing.md
Please see license file.
Please note: Third party content pulled from other locations are subject to its own licenses and you may have other legal obligations or restrictions that govern your use of that content.
@misc{kirichenko2025abstentionbenchreasoningllmsfail,
      title={AbstentionBench: Reasoning LLMs Fail on Unanswerable Questions},
      author={Polina Kirichenko and Mark Ibrahim and Kamalika Chaudhuri and Samuel J. Bell},
      year={2025},
      eprint={2506.09038},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.09038},
}
106 followers · starred Aug 2026
465 followers · starred Aug 2025
359 followers · starred Jun 2025
53 followers · starred Feb 2026