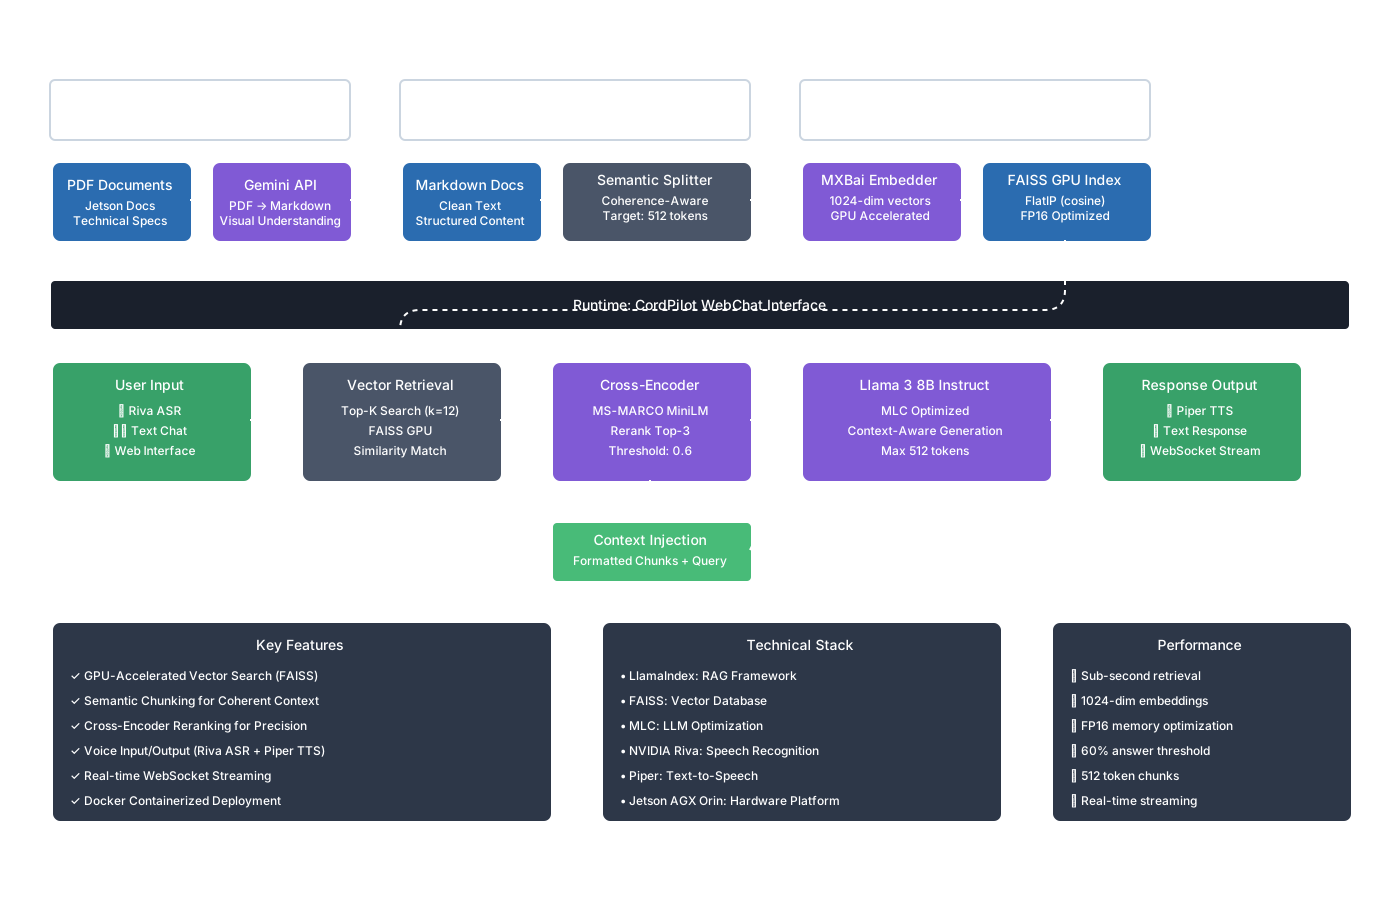
An enterprise-grade Retrieval-Augmented Generation (RAG) system optimized for NVIDIA Jetson platforms
CordPilot is a sophisticated RAG (Retrieval-Augmented Generation) system designed specifically for NVIDIA Jetson embedded computing platforms. It provides intelligent, context-aware responses to technical queries about Jetson hardware, leveraging state-of-the-art language models and vector search capabilities.
Internship Project for OpenZeka - This project was developed as part of an internship for OpenZeka, contributing to their Cordatus software ecosystem. Cordatus is an advanced vocal real-time conversational AI system designed for local edge devices, featuring a working RAG agent that enables natural voice interactions with comprehensive document knowledge.
Built on nanoLLM Framework - This project is developed on top of the nanoLLM framework by Dustin Franklin (dustynv), extending its capabilities with advanced RAG functionality for enterprise-grade document processing and retrieval.
Download the Riva Quick Start from NGC:
riva_quickstart_arm64
Initialize and start Riva:
cd riva_quickstart_arm64_v2.19.0
bash riva_init.sh
bash riva_start.sh
git clone https://github.com/efe-yk/cordpilot.git
cd cordpilot

# Set your API keys
export GEMINI_API_KEY="your_gemini_key"
export HUGGINGFACE_TOKEN="your_hf_token"
CordPilot supports two document processing workflows:
# Place PDFs in jetson_docs/
cp your_pdfs/*.pdf jetson_docs/

# Convert PDFs to clean Markdown using Gemini API
python3 gemini_markdown.py

# Build semantic vector index
python3 semantic_index.py
# Place PDFs in jetson_docs/
cp your_pdfs/*.pdf jetson_docs/

# Process, chunk, clean, and index PDFs locally
python3 index.py

# Use the generated index (jetson_index)
Note: The local processing option (index.py) provides direct PDF parsing and indexing without requiring external API calls, making it suitable for offline or private deployments.
docker run --rm -it \
  --name cordpilot \
  --runtime nvidia \
  --env HUGGINGFACE_TOKEN=$HUGGINGFACE_TOKEN \
  --network host \
  --shm-size=8g \
  -v "$HOME/.cache/huggingface":/root/.cache/huggingface \
  -v "$HOME/.cache/piper":/root/.cache/piper \
  -w /workspace \
  cordpilot:r36.4.0 bash -lc "
    python3 rag_webchat.py \
      --api mlc \
      --model 'meta-llama/Meta-Llama-3-8B-Instruct' \
      --asr riva \
      --tts piper \
      --web-port 8050 \
      --ws-port 49000
  "
Open browser: http://localhost:8050
# RAG Settings
RAG_TOP_K=12              # Retrieval candidates
RAG_RERANK_TOP_N=3        # Final context size
RAG_ANSWER_THRESH=0.6     # Relevance threshold

# GPU Settings
RAG_FAISS_GPU=1           # GPU acceleration
RAG_FAISS_FP16=1          # Memory optimization

# Voice Settings
TTS_VOICE=en_US-nova-low  # Piper voice model
TTS_RATE=1.0              # Speech rate
# Verify Riva is running
docker ps | grep riva
# Restart if needed
bash riva_stop.sh && bash riva_start.sh
# Reduce memory usage
export RAG_TOP_K=8
export RAG_FAISS_FP16=1
# GPU usage
jtop
# Container stats
docker stats cordpilot
MIT License - see LICENSE.md
Built with ❤️ for the NVIDIA Jetson Community



