
🏭 Mega Scale Multimodal DataPipeline for SOTA Foundation Models
Python
379
38 commits
updated May 12, 2026
README
Mega Data Factory
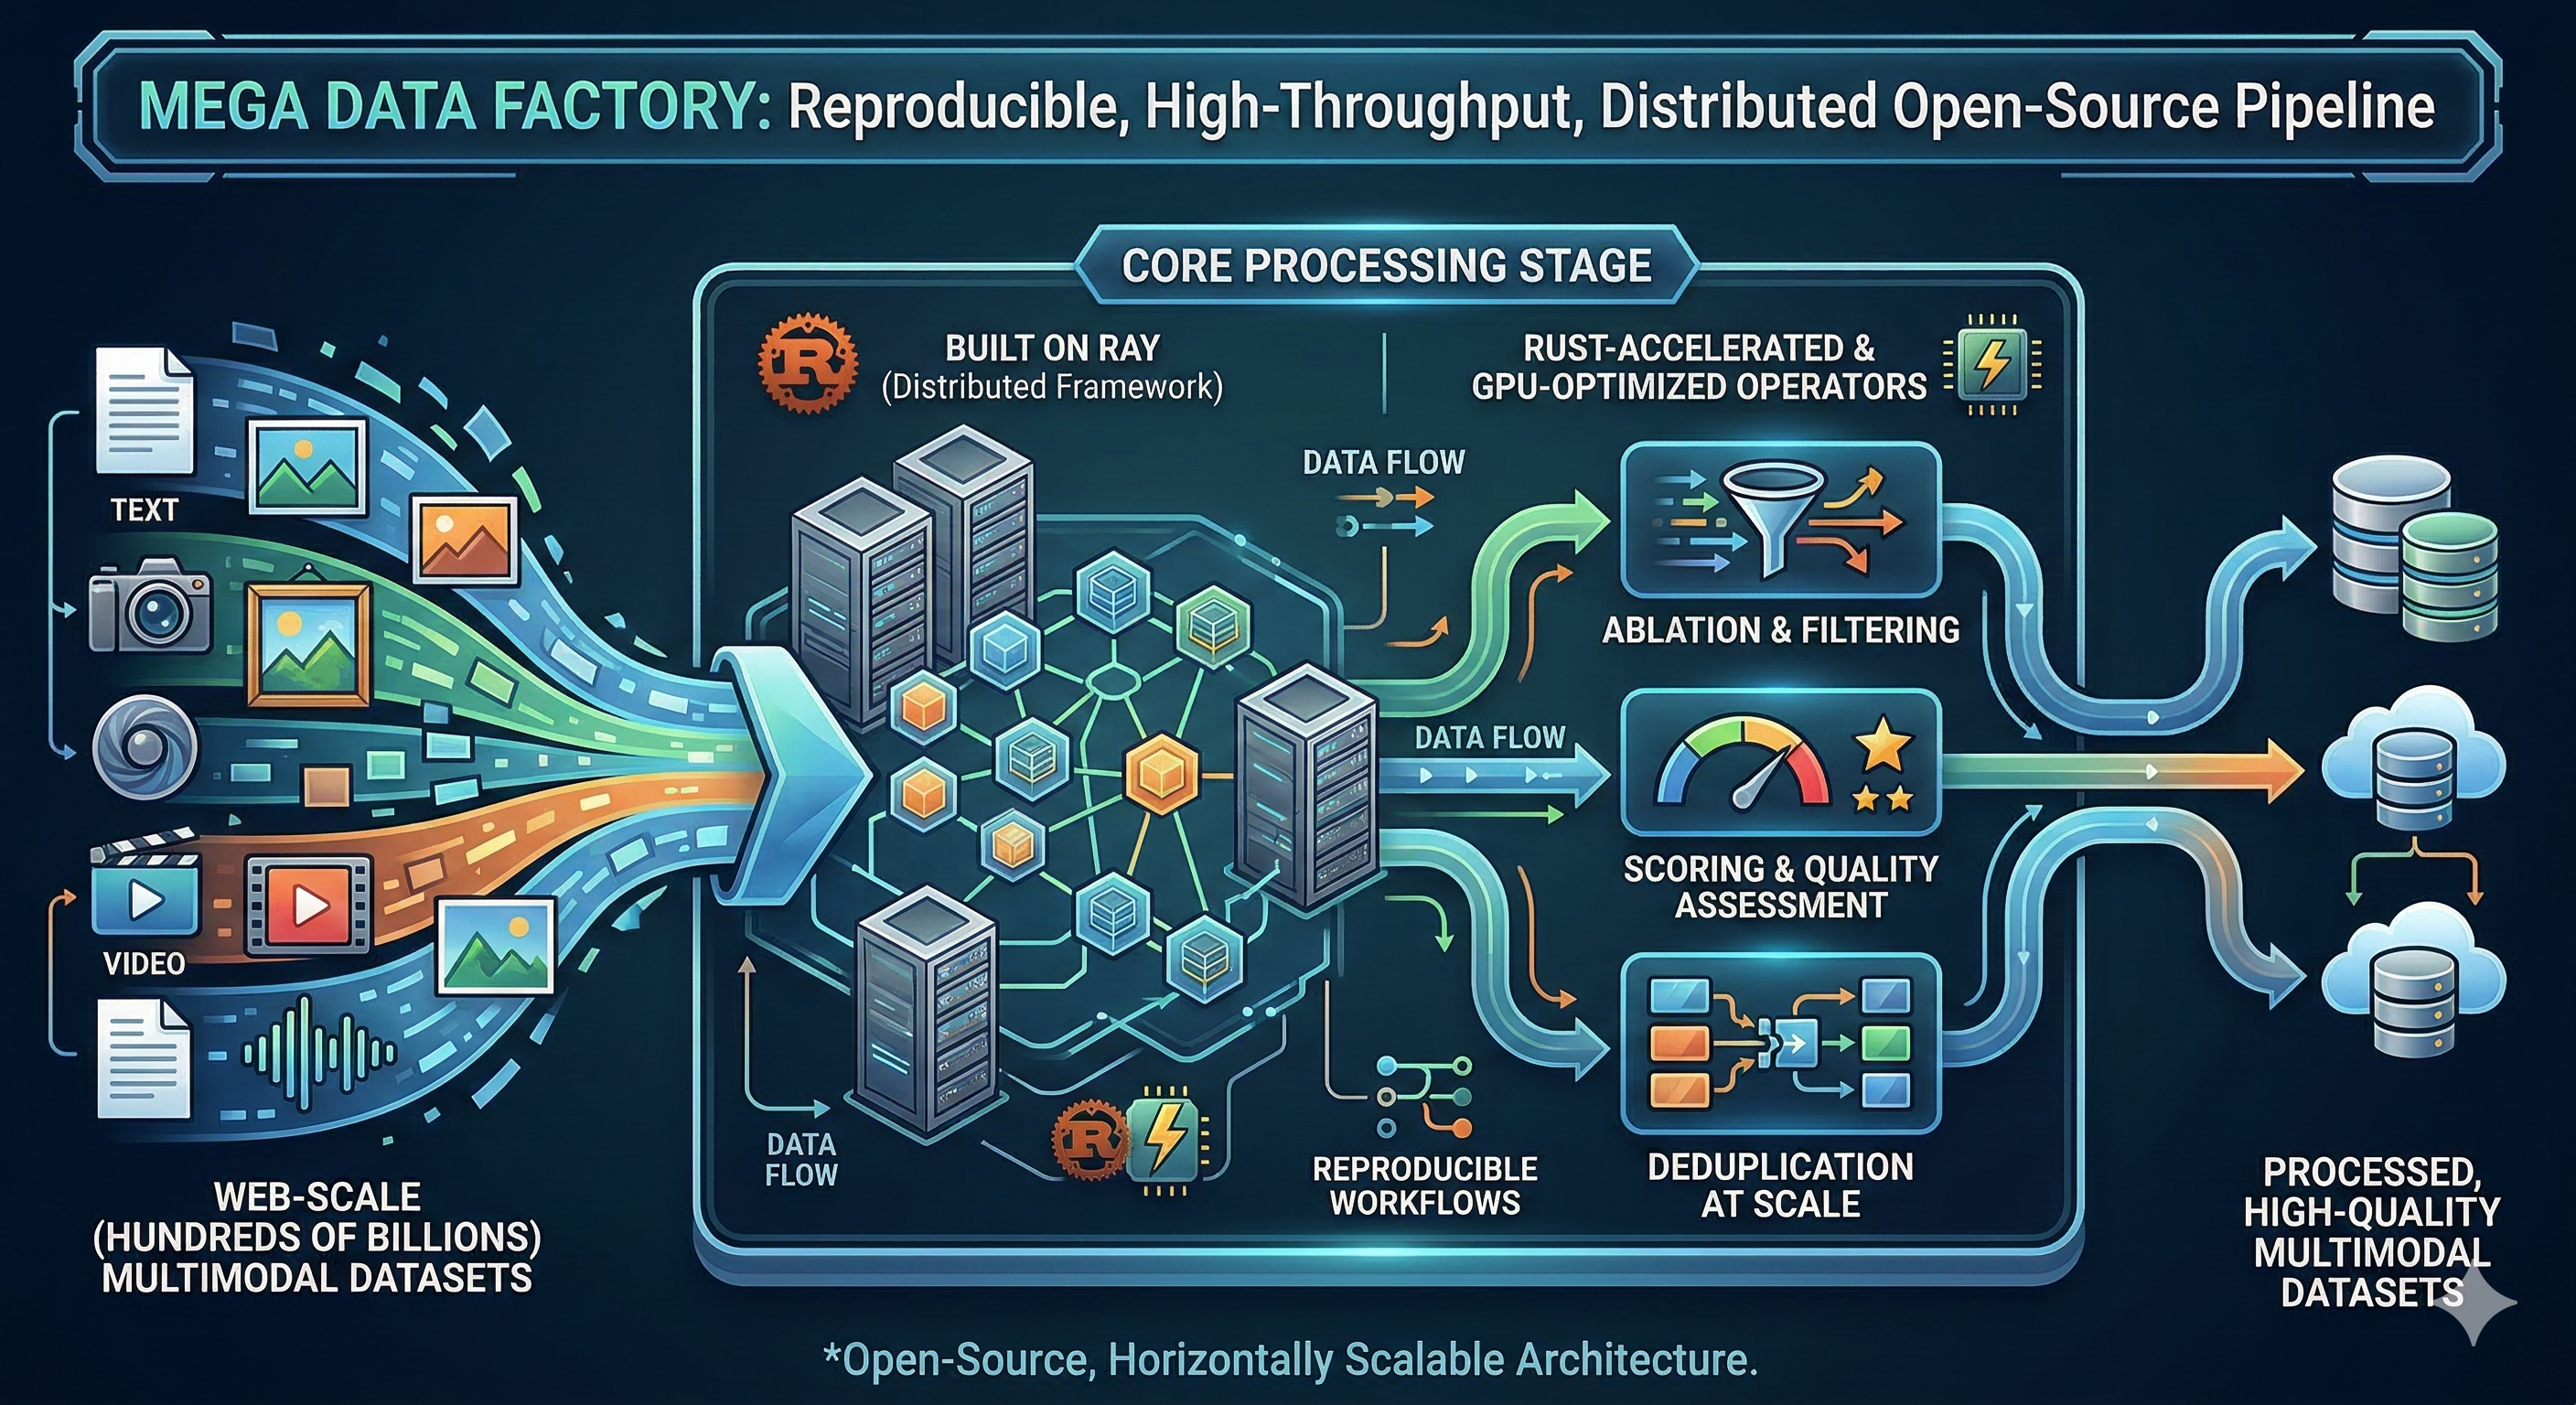
A reproducible, high-throughput, distributed open-source pipeline for processing web-scale (hundreds of billions) multimodal datasets. Built on Ray with Rust-accelerated and GPU-optimized operators for ablation, scoring, and deduplication at scale.
Star History
Vision
Reproduce SOTA foundation model data pipelines — from rule-based to model-based, spanning text, image, and multimodal data.
Text Data Pipelines
| Pipeline | Paper | Status |
|---|---|---|
| FineWeb | 15T tokens, quality filtering | 🚧 In Progress |
| FineWeb-Edu | Educational content classifier | 🚧 In Progress |
| RefinedWeb | URL filtering, trafilatura, dedup | ✅ URL Filter |
| DCLM | Data curation for LLMs | 📋 Planned |
| Dolma | Open corpus toolkit | 📋 Planned |
| RedPajama-V2 | 30T tokens, quality signals | 📋 Planned |
Image & Vision-Language Pipelines
| Pipeline | Paper | Status |
|---|---|---|
| Z-Image | Image generation foundation model | ✅ Implemented |
| Imagen 3 | Image quality & AIGC detection | ✅ Implemented |
| LAION-5B | CLIP filtering, dedup | ✅ Implemented |
| DataComp | CLIP/SigLIP filtering | ✅ Implemented |
| Qwen-VL | Vision-language data | 🚧 In Progress |
| Seed1.5-VL | Vision-language reasoning | 📋 Planned |
| HoneyBee | Data recipes for VL reasoners | 📋 Planned |
| Cosmos | World model platform | 📋 Planned |
Video & Multimodal Pipelines
| Pipeline | Paper | Status |
|---|---|---|
| Panda-70M | Video captioning | 📋 Planned |
| InternVid | Video-language | 📋 Planned |
| OpenVid-1M | Video generation | 📋 Planned |
Pipeline Run Reports
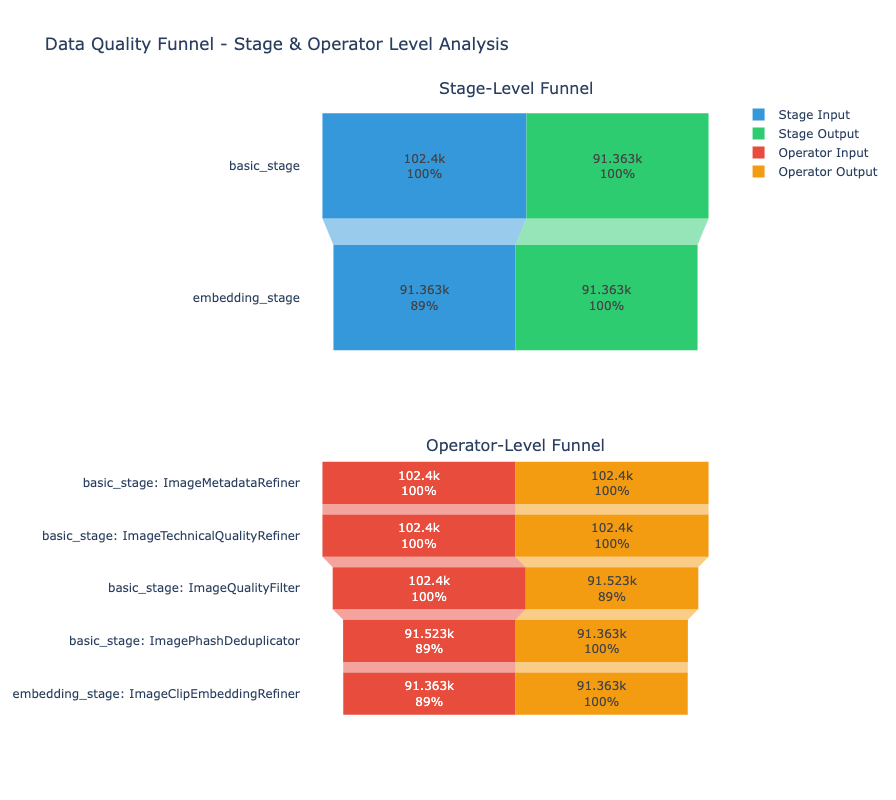
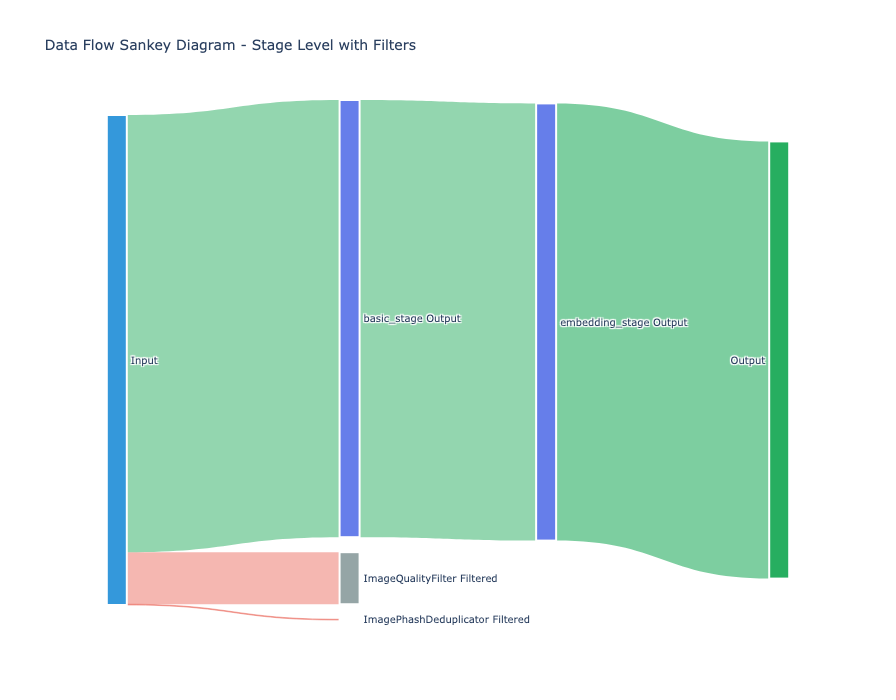
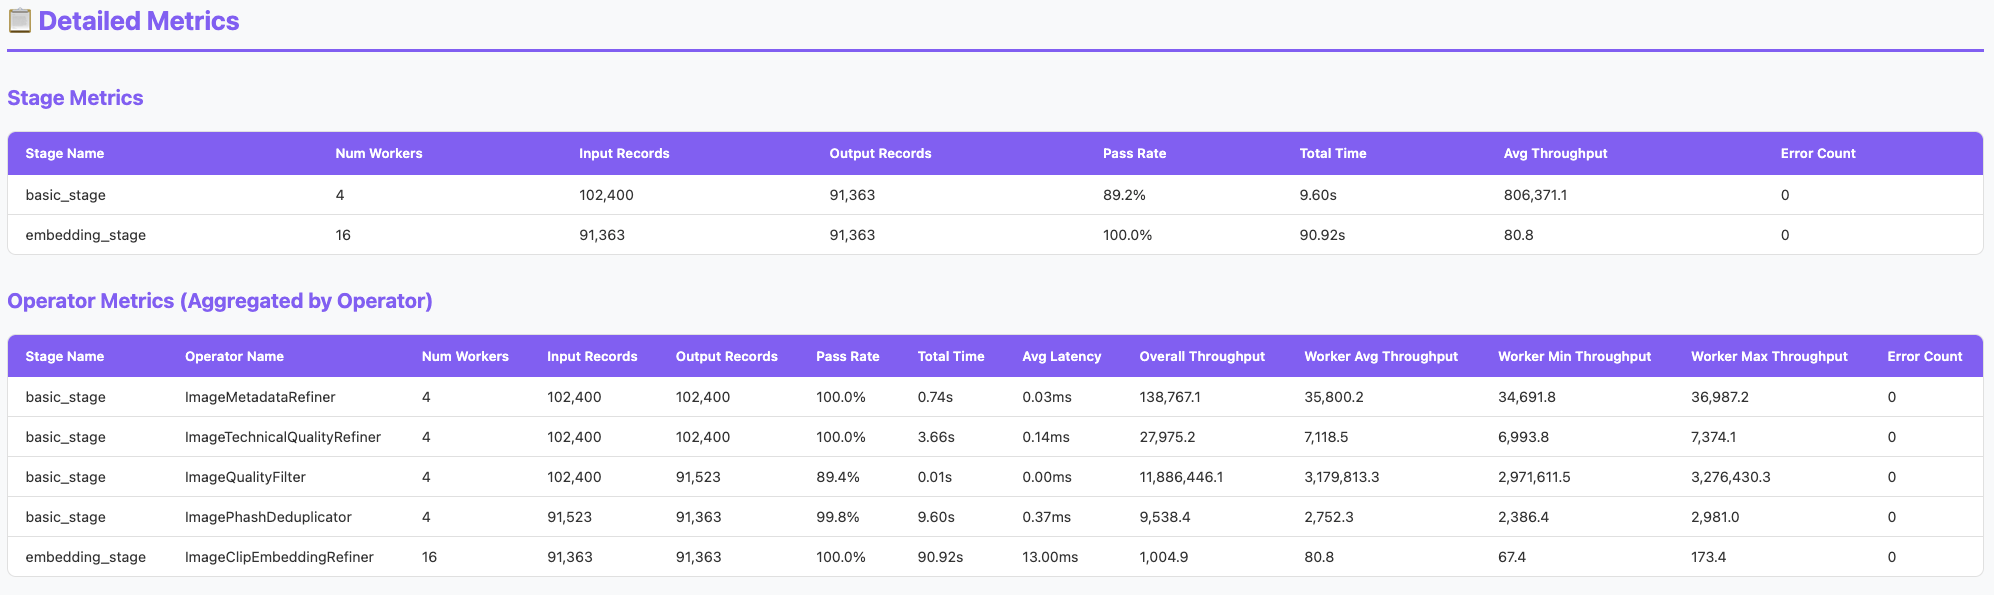
https://huggingface.co/spaces/classtag/mega-data-factory-reports This space contains interactive HTML reports for pipeline runs, showcasing metrics, visualizations, and performance statistics.
Data Quality Funnel
Data Flow Sankey
Data Detail Metrics
Installation
# Clone the repository
git clone https://github.com/duoan/mega-data-factory.git
cd mega-data-factory

# Install with Rust acceleration (recommended)
uv pip install -e .

# Or install without Rust (pure Python fallback)
uv sync
Requires Rust toolchain for building accelerated operators. Install via rustup.
Quick Start
# Run pipeline with config
mdf run --config configs/z_image.yaml

# Or with options
mdf run -c configs/z_image.yaml --max-samples 1000 --batch-size 500
Operators
🦀 = Rust Accelerated | 🖥️ = GPU Optimized
Data Loaders
| Loader | Description | Features |
|---|---|---|
HuggingFaceLoader | Load from HuggingFace datasets | Streaming, sharding |
CommonCrawlLoader | Load from CommonCrawl WARC files | 🦀 Rust text extraction, distributed |
Text Operators
Refiners (normalize/enrich text fields):
| Operator | Description |
|---|---|
TextNewLineRemovalRefiner | Limit maximum consecutive newlines in text |
Filters (rule-based, from RefinedWeb):
| Operator | Description | Reference |
|---|---|---|
URLFilter | Domain blocklist, URL word scoring, quality source exclusion | RefinedWeb §G.1 |
TextLengthFilter | Filter by character/word count | FineWeb, RefinedWeb |
TextAlphabeticWordRationFilter (text_alphabetic_word_ration_filter) | Filter by ratio of words without alphabetic chars | Gopher-style heuristic |
TextAvgWordLengthFilter (text_avg_word_length_filter) | Filter by average word length range | RefinedWeb-style heuristic |
TextBulletFilter (text_bullet_filter) | Filter by bullet-line ratio | RefinedWeb-style heuristic |
TextEllipsisLineRatioFilter (text_ellipsis_line_ratio_filter) | Filter by ellipsis-ending line ratio | RefinedWeb-style heuristic |
TextSymbolRatioFilter (text_symbol_ratio_filter) | Filter by symbol-to-word ratio (#, ..., . . ., …) | RefinedWeb-style heuristic |
TextRepetitionFilter (text_repetition_filter) | Multi-granularity n-gram repetition checks (line/paragraph/word) | Gopher / MassiveText heuristic |
TextTargetLanguageFilter (text_target_language_filter) | FastText language detection with score threshold | CCNet |
Deduplicators:
| Operator | Description |
|---|---|
TextExactDeduplicator | Exact content hash deduplication (xxhash/MD5) |
Coming Soon:
PerplexityFilter- KenLM perplexity scoringQualityClassifierFilter- Model-based quality (FineWeb-Edu style)MinHashDeduplicator- Near-duplicate detection
Image Operators
Refiners (enrich records with new fields):
| Operator | Description | Acceleration |
|---|---|---|
ImageMetadataRefiner | Width, height, format, file size | CPU |
ImageTechnicalQualityRefiner | Compression artifacts, entropy | 🦀 Rust |
ImageVisualDegradationsRefiner | Color cast, blur, watermark, noise | CPU |
ImageClipEmbeddingRefiner | CLIP embeddings (OpenCLIP) | 🖥️ GPU |
ImageSigLIPEmbeddingRefiner | SigLIP2 embeddings | 🖥️ GPU |
ImageAestheticQualityRefiner | Aesthetic score (CLIP-based) | CPU |
ImageAIGCDetectorRefiner | AI-generated image detection | CPU |
Filters:
| Operator | Description |
|---|---|
ImageQualityFilter | Filter by size, quality metrics, aesthetic score |
Deduplicators:
| Operator | Description | Acceleration |
|---|---|---|
ImagePhashDeduplicator | Perceptual hash deduplication | 🦀 Rust |
General Operators
Filters:
| Operator | Description |
|---|---|
RangeFilter | Generic range filter for any numeric field (min/max bounds) |
Video Operators
Refiners:
| Operator | Description | Requirements |
|---|---|---|
VideoMetadataRefiner | Extract video metadata (duration, resolution, fps, codec, bitrate, audio info) | FFprobe |
VideoAestheticsScoreRefiner | Video aesthetic quality scoring via frame sampling | 🖥️ GPU |
VideoClipEmbeddingRefiner | CLIP embeddings for video frames (mean/max pooling) | 🖥️ GPU |
Deduplicators:
| Operator | Description | Requirements |
|---|---|---|
VideoExactByteLevelDeduplicator | Exact file hash deduplication (SHA-256/MD5/SHA-512) | - |
VideoExactStreamLevelDeduplicator | Raw stream hash deduplication (container-agnostic) | FFmpeg |
LLM Synthesis Operators
Refiners (synthesize data via LLM APIs or local models):
| Operator | Description | Mode |
|---|---|---|
LLMOnlineSynthesisRefiner | Call remote LLM APIs (OpenAI, Claude, Gemini, MiniMax, DeepSeek, etc.) with account pool + proxy pool | Online |
LLMOfflineSynthesisRefiner | Run models locally on GPUs via vLLM engine for high-throughput batch inference | Offline |
LLMResponseParserRefiner | Post-process LLM responses: JSON/regex/JMESPath extraction, schema validation, field mapping | Post-processing |
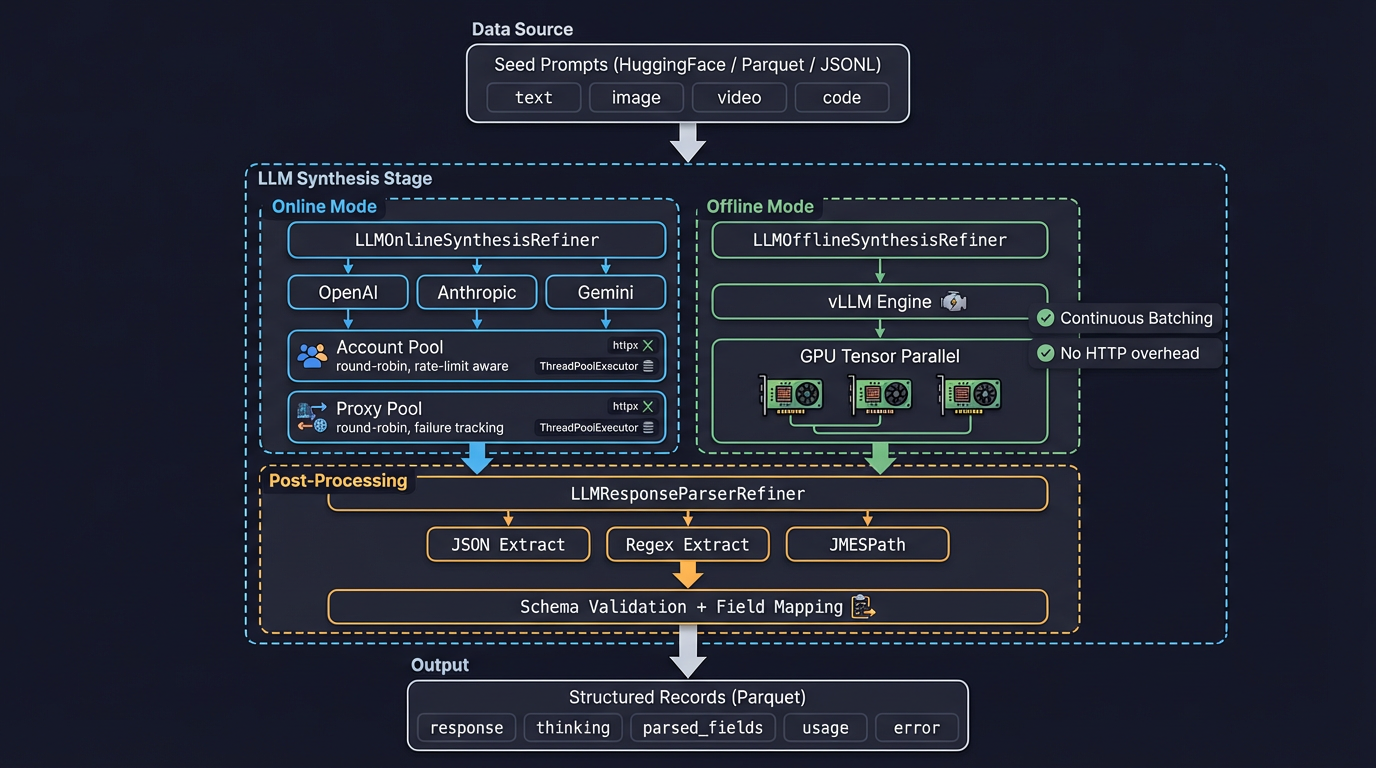
Online mode supports any OpenAI-compatible endpoint (vLLM server, Ollama, Together, Groq) plus native Anthropic, Gemini, and MiniMax APIs. Account pool rotates API keys with rate-limit awareness; proxy pool rotates HTTP/SOCKS proxies with failure tracking.
Offline mode uses vLLM's Python API for zero-HTTP-overhead GPU inference with continuous batching, tensor parallelism, and quantization (AWQ/GPTQ) support.
Install dependencies:
pip install -e ".[llm-online]"    # httpx for online mode
pip install -e ".[llm-offline]"   # vllm for offline mode
Data Writers
| Writer | Description |
|---|---|
ParquetDataWriter | Write to Parquet files |
IcebergDataWriter | Write to Apache Iceberg tables |
Architecture
Deep Dive: See docs/ARCHITECTURE.md for a comprehensive explanation of the distributed pipeline-parallel design, including ObjectRef chaining, backpressure control, bucketed deduplication, and theoretical scalability analysis.
Pipeline Overview
%%{init: {'theme': 'base', 'themeVariables': { 'primaryColor': '#4f46e5', 'primaryTextColor': '#fff', 'primaryBorderColor': '#6366f1', 'lineColor': '#a5b4fc', 'secondaryColor': '#1e1b4b', 'tertiaryColor': '#312e81', 'background': '#0f0f23', 'mainBkg': '#1e1b4b', 'nodeBorder': '#6366f1', 'clusterBkg': '#1e1b4b', 'clusterBorder': '#6366f1', 'titleColor': '#e0e7ff', 'edgeLabelBackground': '#312e81'}}}%%
flowchart TB
    subgraph Driver["Ray Driver"]
        Config[Config]
        Executor[Executor]
        Progress[Stats]
    end

    subgraph ObjectStore["Object Store"]
        Batches["Shared Memory"]
    end

    subgraph Stage0["CPU Pool ×8"]
        direction LR
        W0["W0"]
        W1["W1"]
        W2["W2"]
        Wn["..."]
        W7["W7"]
    end

    subgraph Stage1["GPU Pool ×2"]
        direction LR
        GPU0["GPU0"]
        GPU1["GPU1"]
    end

    subgraph Output["Output"]
        Writer[Parquet]
    end

    HF["HuggingFace"] --> Driver
    Driver --> ObjectStore
    ObjectStore --> Stage0
    Stage0 --> ObjectStore
    ObjectStore --> Stage1
    Stage1 --> Writer
Worker Pool & Load Balancing
%%{init: {'theme': 'base', 'themeVariables': { 'primaryColor': '#059669', 'primaryTextColor': '#fff', 'primaryBorderColor': '#10b981', 'lineColor': '#6ee7b7', 'secondaryColor': '#064e3b', 'tertiaryColor': '#065f46', 'background': '#0f0f23', 'mainBkg': '#064e3b', 'nodeBorder': '#10b981', 'clusterBkg': '#064e3b', 'clusterBorder': '#10b981'}}}%%
flowchart LR
    subgraph Input["Batches"]
        B0["B0"] & B1["B1"] & B2["B2"] & B3["B3"]
        B4["B4"] & B5["B5"] & B6["B6"] & B7["B7"]
    end

    subgraph CPU["CPU Pool ×8 workers"]
        C0["C0 🦀"] & C1["C1 🦀"] & C2["C2 🦀"] & C3["C3 🦀"]
        C4["C4 🦀"] & C5["C5 🦀"] & C6["C6 🦀"] & C7["C7 🦀"]
    end

    subgraph GPU["GPU Pool ×2 workers"]
        G0["G0 CLIP"]
        G1["G1 CLIP"]
    end

    B0 --> C0
    B1 --> C1
    B2 --> C2
    B3 --> C3
    B4 --> C4
    B5 --> C5
    B6 --> C6
    B7 --> C7

    C0 & C1 & C2 & C3 --> G0
    C4 & C5 & C6 & C7 --> G1
Execution Sequence
%%{init: {'theme': 'dark'}}%%
sequenceDiagram
    participant D as Driver
    participant OS as ObjectStore
    participant CPU as CPU ×8
    participant GPU as GPU ×2
    participant W as Writer

    D->>OS: Submit batches

    par CPU Processing
        OS->>CPU: Batch 0-7
    end

    CPU->>OS: Processed

    par GPU Processing
        OS->>GPU: Batch 0-7
    end

    GPU->>W: Write Parquet
    W->>D: Done
Timeline (Parallel Execution)
%%{init: {'theme': 'dark'}}%%
gantt
    title Batch Processing Timeline
    dateFormat X
    axisFormat %s

    section CPU-0
        B0    :c0, 0, 2
        B8    :c0b, 8, 2

    section CPU-1
        B1    :c1, 0, 2
        B9    :c1b, 8, 2

    section CPU-7
        B7    :c7, 0, 2
        B15   :c7b, 8, 2

    section GPU-0
        B0    :g0a, 2, 3
        B2    :g0b, 5, 3

    section GPU-1
        B1    :g1a, 2, 3
        B3    :g1b, 5, 3
Key Points:
- CPU Pool: 8 workers for metadata, quality (🦀 Rust), filtering, dedup
- GPU Pool: 2 workers for CLIP embeddings (limited by VRAM)
- Load Balancing: Ray auto-distributes batches to idle workers
Configuration
Text Pipeline: CommonCrawl Processing
# configs/example_commoncrawl.yaml
# RefinedWeb-style text extraction pipeline

data_loader:
  type: CommonCrawlLoader
  params:
    crawl_id: "CC-MAIN-2024-51"
  num_workers: 1

stages:
  - name: content_filtering
    operators:
      # RefinedWeb §G.1: URL filtering
      - name: url_filter
        params:
          url_field: "url"
      # Length filtering
      - name: text_length_filter
        params:
          min_length: 50
          max_length: 100000
          text_field: "text"
          length_type: "word"
      # Additional text quality filters
      - name: text_alphabetic_word_ration_filter
        params:
          text_field: "text"
          max_ratio: 0.8
      - name: text_avg_word_length_filter
        params:
          text_field: "text"
          lower_bound: 2.0
          upper_bound: 20.0
      - name: text_bullet_filter
        params:
          text_field: "text"
          max_bullet_ratio: 0.9
      - name: text_ellipsis_line_ratio_filter
        params:
          text_field: "text"
          max_ratio: 0.3
      - name: text_symbol_ratio_filter
        params:
          text_field: "text"
          max_symbol_to_word_ratio: 0.5
      - name: text_repetition_filter
        params:
          text_field: "text"
      # Normalize newlines before dedup
      - name: text_new_line_removal_refiner
        params:
          text_field: "text"
          max_consecutive: 2
      # Exact deduplication
      - name: text_exact_deduplicator
        params:
          text_field: "text"
    worker:
      min_replicas: 2
      max_replicas: 2

data_writer:
  type: ParquetDataWriter
  params:
    output_path: "./output/commoncrawl"

executor:
  max_samples: 10000
  batch_size: 200
  dedup_num_buckets: 1
  rejected_samples:
    enabled: true
  metrics:
    enabled: true
    generate_report: true
    debug_samples_per_operator: 20
Image Pipeline: Z-Image Style
# configs/z_image.yaml
# Image quality + aesthetic + AIGC detection pipeline

data_loader:
  type: HuggingFaceLoader
  params:
    dataset_name: "jp1924/Laion400m-1"
    split: "train"
    streaming: true

stages:
  # Stage 1: Basic metadata and quality (CPU, Rust-accelerated)
  - name: basic_stage
    operators:
      - name: image_metadata_refiner
      - name: image_technical_quality_refiner  # 🦀 Rust
      - name: image_quality_filter
        params:
          min_width: 128
          min_height: 128
          max_compression_artifacts: 0.8
      - name: image_phash_deduplicator  # 🦀 Rust
    worker:
      min_replicas: 2
      max_replicas: 8
      resources:
        cpu: 1

  # Stage 2: Embedding extraction (GPU)
  - name: embedding_stage
    operators:
      - name: image_clip_embedding_refiner
        params:
          model_name: "ViT-L-14"
          pretrained: "openai"
          use_fp16: true
      - name: image_siglip_embedding_refiner
        params:
          model_name: "google/siglip2-so400m-patch14-384"
          use_fp16: true
    worker:
      min_replicas: 1
      max_replicas: 2
      resources:
        gpu: 1

  # Stage 3: Quality scoring
  - name: scoring_stage
    operators:
      - name: image_aesthetic_quality_refiner
      - name: image_aigc_detector_refiner
        params:
          threshold: 0.5
    worker:
      min_replicas: 2
      max_replicas: 4
      resources:
        cpu: 1

data_writer:
  type: ParquetDataWriter
  params:
    output_path: "./output/z_image"

executor:
  max_samples: 100000
  batch_size: 256
  dedup_num_buckets: 16
  metrics:
    enabled: true
    generate_report: true
LLM Synthesis Pipeline
# configs/example_llm_synthesis.yaml
# Knowledge synthesis with post-processing

data_loader:
  type: HuggingFaceLoader
  params:
    dataset_name: "your-org/seed-prompts"
    split: "train"
    streaming: true

stages:
  - name: synthesis_stage
    operators:
      # Step 1: Call LLM API
      - name: llm_online_synthesis_refiner
        params:
          provider: anthropic
          model: claude-sonnet-4-20250514
          system_prompt: |
            Analyze the text and return JSON:
            {"category": "...", "confidence": 0.0-1.0, "reasoning": "..."}
          prompt_template: "Classify: {text}"
          enable_thinking: true
          thinking_budget: 10000
          accounts:
            - api_key: "${ANTHROPIC_API_KEY_1}"
            - api_key: "${ANTHROPIC_API_KEY_2}"
          proxies:
            - "http://user:pass@proxy1:8080"
          max_concurrent: 8

      # Step 2: Extract structured output
      - name: llm_response_parser_refiner
        params:
          input_field: llm_response
          parse_mode: json
          field_mapping:
            category: "category"
            confidence: "confidence"
            reasoning: "reasoning"
          required_fields: ["category", "confidence"]
          field_types:
            category: str
            confidence: float
    worker:
      num_replicas: 1
      resources:
        cpu: 2

data_writer:
  type: ParquetDataWriter
  params:
    output_path: "./output/llm_synthesis"

executor:
  max_samples: 10000
  batch_size: 64
Performance
Text Pipeline (CommonCrawl)
============================================================
Pipeline: CommonCrawl text extraction (1M records)
Hardware: 8 CPU cores
============================================================

stage_0:
  [Stage Summary]
    Input: 1,000,000 → Output: 945,866 (94.6% pass)
    Total time: 49.11s
    Throughput: 20,362 records/sec

  URLFilter:           20,362 rec/sec   (98.1% pass)  # RefinedWeb §G.1
  TextLengthFilter:  1,976,454 rec/sec   (96.4% pass)  # Near instant
============================================================

Projections:
  10M records   →  ~8 minutes
  100M records  →  ~1.4 hours
  1B records    →  ~14 hours
Image Pipeline (LAION)
Benchmark on Mac M1 Pro (MPS):
============================================================
Pipeline: Image quality + embedding (1K records)
============================================================

stage_0 (CPU, Rust-accelerated):
  [Stage Summary]
    Input: 1,000 → Output: 898 (89.8% pass)
    Total time: 0.61s
    Throughput: 1,630 records/sec

  ImageMetadataRefiner:        27,000 rec/sec
  ImageTechnicalQualityRefiner: 2,500 rec/sec  🦀 Rust
  ImageQualityFilter:       4,200,000 rec/sec
  ImagePhashDeduplicator:      1,500 rec/sec  🦀 Rust

stage_1 (GPU):
  [Stage Summary]
    Input: 898 → Output: 898
    Total time: 6.80s
    Throughput: 132 records/sec

  ImageClipEmbeddingRefiner:     132 rec/sec  🖥️ GPU
============================================================
Project Structure
mega-data-factory/
├── mega_data_factory/
│   ├── cli.py                          # CLI entry point (mdf command)
│   ├── framework/
│   │   ├── executor.py                 # Pipeline orchestration
│   │   ├── stage_actor.py               # StageActor
│   │   ├── loader_actor.py             # LoaderActor
│   │   ├── dedup_backend.py            # DedupBackend (ABC), ExactDedupBackend, SemanticDedupBackend
│   │   ├── operator.py                 # Operator, Refiner, Filter, Deduplicator
│   │   ├── config.py                   # YAML config parsing
│   │   ├── registry.py                 # Component registries
│   │   └── metrics/                    # Metrics collection & reporting
│   ├── loaders/
│   │   ├── huggingface_loader.py       # HuggingFace datasets
│   │   └── commoncrawl_loader.py       # CommonCrawl WARC files
│   ├── operators/
│   │   ├── refiners/                   # Refiners (text, image, video)
│   │   │   └── llm_synthesis/          # LLM synthesis (online, offline, parser)
│   │   ├── filters/                    # Text + Image filters
│   │   └── dedup/                      # Deduplicators (phash, minhash)
│   ├── writers/
│   │   ├── parquet_writer.py           # Parquet output
│   │   └── iceberg_writer.py           # Apache Iceberg output
│   └── models/                         # Model trainers (aesthetic, AIGC, k-means)
├── src/lib.rs                          # 🦀 Rust operators (quality, phash, HTML extraction)
├── configs/                            # Pipeline configurations
│   ├── z_image.yaml                    # Image pipeline
│   ├── example_commoncrawl.yaml        # Text pipeline
│   └── example_llm_synthesis.yaml      # LLM synthesis pipeline
├── tests/                              # Unit tests
├── Cargo.toml                          # Rust dependencies
└── pyproject.toml                      # Python config (maturin build)
Extending the Pipeline
Custom Text Filter
from mega_data_factory.framework import Filter, OperatorRegistry

class MyTextFilter(Filter):
    def __init__(self, min_words: int = 50):
        super().__init__()
        self.min_words = min_words

    def should_keep_batch(self, records: list[dict]) -> list[bool]:
        return [len(r.get("text", "").split()) >= self.min_words for r in records]

OperatorRegistry.register("MyTextFilter", MyTextFilter)
Custom Image Refiner
from mega_data_factory.framework import Refiner, OperatorRegistry
import pyarrow as pa

class MyImageRefiner(Refiner):
    def refine_batch(self, records: list[dict]) -> None:
        for record in records:
            record["my_score"] = compute_score(record["image"])

    def get_output_schema(self) -> dict[str, pa.DataType]:
        return {"my_score": pa.float32()}

OperatorRegistry.register("MyImageRefiner", MyImageRefiner)
Key Features
- Pipeline Parallelism: Ray ObjectRef chaining enables concurrent stage execution without blocking (details)
- Distributed Data Loading: Sharded file loading with checkpoint support for fault recovery
- Backpressure Control: Bounded in-flight batches prevent OOM on large datasets
- Bucketed Deduplication: Distributed state sharding scales to 100B+ keys (details)
- Rust Acceleration: 10-25x speedup for image quality, hashing, and HTML extraction
- GPU Optimization: CLIP/SigLIP embedding extraction with FP16 and batch inference
- Elastic Scaling: Dynamic worker allocation with min/max replicas per stage
- LLM Synthesis: Online (API) and offline (vLLM) modes with account/proxy pools and response parsing
- Config-Driven: YAML configs define entire pipelines with no code changes
References
Text Data Pipelines
- RefinedWeb (arXiv:2306.01116) - URL filtering, trafilatura, MassiveText dedup
- FineWeb - 15T token dataset, quality filtering
- DCLM (arXiv:2406.11794) - Data curation for language models
- Dolma (arXiv:2402.00159) - Open corpus for LLM pretraining
Image & Vision-Language
- Z-Image (arXiv:2511.22699) - Image generation foundation model data
- DataComp (arXiv:2304.14108) - CLIP filtering benchmark
- LAION-5B (arXiv:2210.08402) - Large-scale image-text dataset
Tools & Models
- OpenCLIP - CLIP implementation
- SigLIP2 - Vision encoder
- dom_smoothie - Rust readability.js port
License
MIT License
Citation
@software{mega_data_factory,
  author       = {Duo An},
  title        = {Mega Data Factory},
  year         = {2025},
  publisher    = {GitHub},
  url          = {https://github.com/duoan/mega-data-factory}
}
Contributors


Similar repos


Languages
Python
95.2%
Jinja
2.7%
Rust
2.1%
🏭 Mega Scale Multimodal DataPipeline for SOTA Foundation Models
Python
379
38 commits
updated May 12, 2026
README
Mega Data Factory
A reproducible, high-throughput, distributed open-source pipeline for processing web-scale (hundreds of billions) multimodal datasets. Built on Ray with Rust-accelerated and GPU-optimized operators for ablation, scoring, and deduplication at scale.
Star History
Vision
Reproduce SOTA foundation model data pipelines — from rule-based to model-based, spanning text, image, and multimodal data.
Text Data Pipelines
| Pipeline | Paper | Status |
|---|---|---|
| FineWeb | 15T tokens, quality filtering | 🚧 In Progress |
| FineWeb-Edu | Educational content classifier | 🚧 In Progress |
| RefinedWeb | URL filtering, trafilatura, dedup | ✅ URL Filter |
| DCLM | Data curation for LLMs | 📋 Planned |
| Dolma | Open corpus toolkit | 📋 Planned |
| RedPajama-V2 | 30T tokens, quality signals | 📋 Planned |
Image & Vision-Language Pipelines
| Pipeline | Paper | Status |
|---|---|---|
| Z-Image | Image generation foundation model | ✅ Implemented |
| Imagen 3 | Image quality & AIGC detection | ✅ Implemented |
| LAION-5B | CLIP filtering, dedup | ✅ Implemented |
| DataComp | CLIP/SigLIP filtering | ✅ Implemented |
| Qwen-VL | Vision-language data | 🚧 In Progress |
| Seed1.5-VL | Vision-language reasoning | 📋 Planned |
| HoneyBee | Data recipes for VL reasoners | 📋 Planned |
| Cosmos | World model platform | 📋 Planned |
Video & Multimodal Pipelines
| Pipeline | Paper | Status |
|---|---|---|
| Panda-70M | Video captioning | 📋 Planned |
| InternVid | Video-language | 📋 Planned |
| OpenVid-1M | Video generation | 📋 Planned |
Pipeline Run Reports
https://huggingface.co/spaces/classtag/mega-data-factory-reports This space contains interactive HTML reports for pipeline runs, showcasing metrics, visualizations, and performance statistics.
Data Quality Funnel
Data Flow Sankey
Data Detail Metrics
Installation
# Clone the repository
git clone https://github.com/duoan/mega-data-factory.git
cd mega-data-factory

# Install with Rust acceleration (recommended)
uv pip install -e .

# Or install without Rust (pure Python fallback)
uv sync
Requires Rust toolchain for building accelerated operators. Install via rustup.
Quick Start
# Run pipeline with config
mdf run --config configs/z_image.yaml

# Or with options
mdf run -c configs/z_image.yaml --max-samples 1000 --batch-size 500
Operators
🦀 = Rust Accelerated | 🖥️ = GPU Optimized
Data Loaders
| Loader | Description | Features |
|---|---|---|
HuggingFaceLoader | Load from HuggingFace datasets | Streaming, sharding |
CommonCrawlLoader | Load from CommonCrawl WARC files | 🦀 Rust text extraction, distributed |
Text Operators
Refiners (normalize/enrich text fields):
| Operator | Description |
|---|---|
TextNewLineRemovalRefiner | Limit maximum consecutive newlines in text |
Filters (rule-based, from RefinedWeb):
| Operator | Description | Reference |
|---|---|---|
URLFilter | Domain blocklist, URL word scoring, quality source exclusion | RefinedWeb §G.1 |
TextLengthFilter | Filter by character/word count | FineWeb, RefinedWeb |
TextAlphabeticWordRationFilter (text_alphabetic_word_ration_filter) | Filter by ratio of words without alphabetic chars | Gopher-style heuristic |
TextAvgWordLengthFilter (text_avg_word_length_filter) | Filter by average word length range | RefinedWeb-style heuristic |
TextBulletFilter (text_bullet_filter) | Filter by bullet-line ratio | RefinedWeb-style heuristic |
TextEllipsisLineRatioFilter (text_ellipsis_line_ratio_filter) | Filter by ellipsis-ending line ratio | RefinedWeb-style heuristic |
TextSymbolRatioFilter (text_symbol_ratio_filter) | Filter by symbol-to-word ratio (#, ..., . . ., …) | RefinedWeb-style heuristic |
TextRepetitionFilter (text_repetition_filter) | Multi-granularity n-gram repetition checks (line/paragraph/word) | Gopher / MassiveText heuristic |
TextTargetLanguageFilter (text_target_language_filter) | FastText language detection with score threshold | CCNet |
Deduplicators:
| Operator | Description |
|---|---|
TextExactDeduplicator | Exact content hash deduplication (xxhash/MD5) |
Coming Soon:
PerplexityFilter- KenLM perplexity scoringQualityClassifierFilter- Model-based quality (FineWeb-Edu style)MinHashDeduplicator- Near-duplicate detection
Image Operators
Refiners (enrich records with new fields):
| Operator | Description | Acceleration |
|---|---|---|
ImageMetadataRefiner | Width, height, format, file size | CPU |
ImageTechnicalQualityRefiner | Compression artifacts, entropy | 🦀 Rust |
ImageVisualDegradationsRefiner | Color cast, blur, watermark, noise | CPU |
ImageClipEmbeddingRefiner | CLIP embeddings (OpenCLIP) | 🖥️ GPU |
ImageSigLIPEmbeddingRefiner | SigLIP2 embeddings | 🖥️ GPU |
ImageAestheticQualityRefiner | Aesthetic score (CLIP-based) | CPU |
ImageAIGCDetectorRefiner | AI-generated image detection | CPU |
Filters:
| Operator | Description |
|---|---|
ImageQualityFilter | Filter by size, quality metrics, aesthetic score |
Deduplicators:
| Operator | Description | Acceleration |
|---|---|---|
ImagePhashDeduplicator | Perceptual hash deduplication | 🦀 Rust |
General Operators
Filters:
| Operator | Description |
|---|---|
RangeFilter | Generic range filter for any numeric field (min/max bounds) |
Video Operators
Refiners:
| Operator | Description | Requirements |
|---|---|---|
VideoMetadataRefiner | Extract video metadata (duration, resolution, fps, codec, bitrate, audio info) | FFprobe |
VideoAestheticsScoreRefiner | Video aesthetic quality scoring via frame sampling | 🖥️ GPU |
VideoClipEmbeddingRefiner | CLIP embeddings for video frames (mean/max pooling) | 🖥️ GPU |
Deduplicators:
| Operator | Description | Requirements |
|---|---|---|
VideoExactByteLevelDeduplicator | Exact file hash deduplication (SHA-256/MD5/SHA-512) | - |
VideoExactStreamLevelDeduplicator | Raw stream hash deduplication (container-agnostic) | FFmpeg |
LLM Synthesis Operators
Refiners (synthesize data via LLM APIs or local models):
| Operator | Description | Mode |
|---|---|---|
LLMOnlineSynthesisRefiner | Call remote LLM APIs (OpenAI, Claude, Gemini, MiniMax, DeepSeek, etc.) with account pool + proxy pool | Online |
LLMOfflineSynthesisRefiner | Run models locally on GPUs via vLLM engine for high-throughput batch inference | Offline |
LLMResponseParserRefiner | Post-process LLM responses: JSON/regex/JMESPath extraction, schema validation, field mapping | Post-processing |
Online mode supports any OpenAI-compatible endpoint (vLLM server, Ollama, Together, Groq) plus native Anthropic, Gemini, and MiniMax APIs. Account pool rotates API keys with rate-limit awareness; proxy pool rotates HTTP/SOCKS proxies with failure tracking.
Offline mode uses vLLM's Python API for zero-HTTP-overhead GPU inference with continuous batching, tensor parallelism, and quantization (AWQ/GPTQ) support.
Install dependencies:
pip install -e ".[llm-online]"    # httpx for online mode
pip install -e ".[llm-offline]"   # vllm for offline mode
Data Writers
| Writer | Description |
|---|---|
ParquetDataWriter | Write to Parquet files |
IcebergDataWriter | Write to Apache Iceberg tables |
Architecture
Deep Dive: See docs/ARCHITECTURE.md for a comprehensive explanation of the distributed pipeline-parallel design, including ObjectRef chaining, backpressure control, bucketed deduplication, and theoretical scalability analysis.
Pipeline Overview
%%{init: {'theme': 'base', 'themeVariables': { 'primaryColor': '#4f46e5', 'primaryTextColor': '#fff', 'primaryBorderColor': '#6366f1', 'lineColor': '#a5b4fc', 'secondaryColor': '#1e1b4b', 'tertiaryColor': '#312e81', 'background': '#0f0f23', 'mainBkg': '#1e1b4b', 'nodeBorder': '#6366f1', 'clusterBkg': '#1e1b4b', 'clusterBorder': '#6366f1', 'titleColor': '#e0e7ff', 'edgeLabelBackground': '#312e81'}}}%%
flowchart TB
    subgraph Driver["Ray Driver"]
        Config[Config]
        Executor[Executor]
        Progress[Stats]
    end

    subgraph ObjectStore["Object Store"]
        Batches["Shared Memory"]
    end

    subgraph Stage0["CPU Pool ×8"]
        direction LR
        W0["W0"]
        W1["W1"]
        W2["W2"]
        Wn["..."]
        W7["W7"]
    end

    subgraph Stage1["GPU Pool ×2"]
        direction LR
        GPU0["GPU0"]
        GPU1["GPU1"]
    end

    subgraph Output["Output"]
        Writer[Parquet]
    end

    HF["HuggingFace"] --> Driver
    Driver --> ObjectStore
    ObjectStore --> Stage0
    Stage0 --> ObjectStore
    ObjectStore --> Stage1
    Stage1 --> Writer
Worker Pool & Load Balancing
%%{init: {'theme': 'base', 'themeVariables': { 'primaryColor': '#059669', 'primaryTextColor': '#fff', 'primaryBorderColor': '#10b981', 'lineColor': '#6ee7b7', 'secondaryColor': '#064e3b', 'tertiaryColor': '#065f46', 'background': '#0f0f23', 'mainBkg': '#064e3b', 'nodeBorder': '#10b981', 'clusterBkg': '#064e3b', 'clusterBorder': '#10b981'}}}%%
flowchart LR
    subgraph Input["Batches"]
        B0["B0"] & B1["B1"] & B2["B2"] & B3["B3"]
        B4["B4"] & B5["B5"] & B6["B6"] & B7["B7"]
    end

    subgraph CPU["CPU Pool ×8 workers"]
        C0["C0 🦀"] & C1["C1 🦀"] & C2["C2 🦀"] & C3["C3 🦀"]
        C4["C4 🦀"] & C5["C5 🦀"] & C6["C6 🦀"] & C7["C7 🦀"]
    end

    subgraph GPU["GPU Pool ×2 workers"]
        G0["G0 CLIP"]
        G1["G1 CLIP"]
    end

    B0 --> C0
    B1 --> C1
    B2 --> C2
    B3 --> C3
    B4 --> C4
    B5 --> C5
    B6 --> C6
    B7 --> C7

    C0 & C1 & C2 & C3 --> G0
    C4 & C5 & C6 & C7 --> G1
Execution Sequence
%%{init: {'theme': 'dark'}}%%
sequenceDiagram
    participant D as Driver
    participant OS as ObjectStore
    participant CPU as CPU ×8
    participant GPU as GPU ×2
    participant W as Writer

    D->>OS: Submit batches

    par CPU Processing
        OS->>CPU: Batch 0-7
    end

    CPU->>OS: Processed

    par GPU Processing
        OS->>GPU: Batch 0-7
    end

    GPU->>W: Write Parquet
    W->>D: Done
Timeline (Parallel Execution)
%%{init: {'theme': 'dark'}}%%
gantt
    title Batch Processing Timeline
    dateFormat X
    axisFormat %s

    section CPU-0
        B0    :c0, 0, 2
        B8    :c0b, 8, 2

    section CPU-1
        B1    :c1, 0, 2
        B9    :c1b, 8, 2

    section CPU-7
        B7    :c7, 0, 2
        B15   :c7b, 8, 2

    section GPU-0
        B0    :g0a, 2, 3
        B2    :g0b, 5, 3

    section GPU-1
        B1    :g1a, 2, 3
        B3    :g1b, 5, 3
Key Points:
- CPU Pool: 8 workers for metadata, quality (🦀 Rust), filtering, dedup
- GPU Pool: 2 workers for CLIP embeddings (limited by VRAM)
- Load Balancing: Ray auto-distributes batches to idle workers
Configuration
Text Pipeline: CommonCrawl Processing
# configs/example_commoncrawl.yaml
# RefinedWeb-style text extraction pipeline

data_loader:
  type: CommonCrawlLoader
  params:
    crawl_id: "CC-MAIN-2024-51"
  num_workers: 1

stages:
  - name: content_filtering
    operators:
      # RefinedWeb §G.1: URL filtering
      - name: url_filter
        params:
          url_field: "url"
      # Length filtering
      - name: text_length_filter
        params:
          min_length: 50
          max_length: 100000
          text_field: "text"
          length_type: "word"
      # Additional text quality filters
      - name: text_alphabetic_word_ration_filter
        params:
          text_field: "text"
          max_ratio: 0.8
      - name: text_avg_word_length_filter
        params:
          text_field: "text"
          lower_bound: 2.0
          upper_bound: 20.0
      - name: text_bullet_filter
        params:
          text_field: "text"
          max_bullet_ratio: 0.9
      - name: text_ellipsis_line_ratio_filter
        params:
          text_field: "text"
          max_ratio: 0.3
      - name: text_symbol_ratio_filter
        params:
          text_field: "text"
          max_symbol_to_word_ratio: 0.5
      - name: text_repetition_filter
        params:
          text_field: "text"
      # Normalize newlines before dedup
      - name: text_new_line_removal_refiner
        params:
          text_field: "text"
          max_consecutive: 2
      # Exact deduplication
      - name: text_exact_deduplicator
        params:
          text_field: "text"
    worker:
      min_replicas: 2
      max_replicas: 2

data_writer:
  type: ParquetDataWriter
  params:
    output_path: "./output/commoncrawl"

executor:
  max_samples: 10000
  batch_size: 200
  dedup_num_buckets: 1
  rejected_samples:
    enabled: true
  metrics:
    enabled: true
    generate_report: true
    debug_samples_per_operator: 20
Image Pipeline: Z-Image Style
# configs/z_image.yaml
# Image quality + aesthetic + AIGC detection pipeline

data_loader:
  type: HuggingFaceLoader
  params:
    dataset_name: "jp1924/Laion400m-1"
    split: "train"
    streaming: true

stages:
  # Stage 1: Basic metadata and quality (CPU, Rust-accelerated)
  - name: basic_stage
    operators:
      - name: image_metadata_refiner
      - name: image_technical_quality_refiner  # 🦀 Rust
      - name: image_quality_filter
        params:
          min_width: 128
          min_height: 128
          max_compression_artifacts: 0.8
      - name: image_phash_deduplicator  # 🦀 Rust
    worker:
      min_replicas: 2
      max_replicas: 8
      resources:
        cpu: 1

  # Stage 2: Embedding extraction (GPU)
  - name: embedding_stage
    operators:
      - name: image_clip_embedding_refiner
        params:
          model_name: "ViT-L-14"
          pretrained: "openai"
          use_fp16: true
      - name: image_siglip_embedding_refiner
        params:
          model_name: "google/siglip2-so400m-patch14-384"
          use_fp16: true
    worker:
      min_replicas: 1
      max_replicas: 2
      resources:
        gpu: 1

  # Stage 3: Quality scoring
  - name: scoring_stage
    operators:
      - name: image_aesthetic_quality_refiner
      - name: image_aigc_detector_refiner
        params:
          threshold: 0.5
    worker:
      min_replicas: 2
      max_replicas: 4
      resources:
        cpu: 1

data_writer:
  type: ParquetDataWriter
  params:
    output_path: "./output/z_image"

executor:
  max_samples: 100000
  batch_size: 256
  dedup_num_buckets: 16
  metrics:
    enabled: true
    generate_report: true
LLM Synthesis Pipeline
# configs/example_llm_synthesis.yaml
# Knowledge synthesis with post-processing

data_loader:
  type: HuggingFaceLoader
  params:
    dataset_name: "your-org/seed-prompts"
    split: "train"
    streaming: true

stages:
  - name: synthesis_stage
    operators:
      # Step 1: Call LLM API
      - name: llm_online_synthesis_refiner
        params:
          provider: anthropic
          model: claude-sonnet-4-20250514
          system_prompt: |
            Analyze the text and return JSON:
            {"category": "...", "confidence": 0.0-1.0, "reasoning": "..."}
          prompt_template: "Classify: {text}"
          enable_thinking: true
          thinking_budget: 10000
          accounts:
            - api_key: "${ANTHROPIC_API_KEY_1}"
            - api_key: "${ANTHROPIC_API_KEY_2}"
          proxies:
            - "http://user:pass@proxy1:8080"
          max_concurrent: 8

      # Step 2: Extract structured output
      - name: llm_response_parser_refiner
        params:
          input_field: llm_response
          parse_mode: json
          field_mapping:
            category: "category"
            confidence: "confidence"
            reasoning: "reasoning"
          required_fields: ["category", "confidence"]
          field_types:
            category: str
            confidence: float
    worker:
      num_replicas: 1
      resources:
        cpu: 2

data_writer:
  type: ParquetDataWriter
  params:
    output_path: "./output/llm_synthesis"

executor:
  max_samples: 10000
  batch_size: 64
Performance
Text Pipeline (CommonCrawl)
============================================================
Pipeline: CommonCrawl text extraction (1M records)
Hardware: 8 CPU cores
============================================================

stage_0:
  [Stage Summary]
    Input: 1,000,000 → Output: 945,866 (94.6% pass)
    Total time: 49.11s
    Throughput: 20,362 records/sec

  URLFilter:           20,362 rec/sec   (98.1% pass)  # RefinedWeb §G.1
  TextLengthFilter:  1,976,454 rec/sec   (96.4% pass)  # Near instant
============================================================

Projections:
  10M records   →  ~8 minutes
  100M records  →  ~1.4 hours
  1B records    →  ~14 hours
Image Pipeline (LAION)
Benchmark on Mac M1 Pro (MPS):
============================================================
Pipeline: Image quality + embedding (1K records)
============================================================

stage_0 (CPU, Rust-accelerated):
  [Stage Summary]
    Input: 1,000 → Output: 898 (89.8% pass)
    Total time: 0.61s
    Throughput: 1,630 records/sec

  ImageMetadataRefiner:        27,000 rec/sec
  ImageTechnicalQualityRefiner: 2,500 rec/sec  🦀 Rust
  ImageQualityFilter:       4,200,000 rec/sec
  ImagePhashDeduplicator:      1,500 rec/sec  🦀 Rust

stage_1 (GPU):
  [Stage Summary]
    Input: 898 → Output: 898
    Total time: 6.80s
    Throughput: 132 records/sec

  ImageClipEmbeddingRefiner:     132 rec/sec  🖥️ GPU
============================================================
Project Structure
mega-data-factory/
├── mega_data_factory/
│   ├── cli.py                          # CLI entry point (mdf command)
│   ├── framework/
│   │   ├── executor.py                 # Pipeline orchestration
│   │   ├── stage_actor.py               # StageActor
│   │   ├── loader_actor.py             # LoaderActor
│   │   ├── dedup_backend.py            # DedupBackend (ABC), ExactDedupBackend, SemanticDedupBackend
│   │   ├── operator.py                 # Operator, Refiner, Filter, Deduplicator
│   │   ├── config.py                   # YAML config parsing
│   │   ├── registry.py                 # Component registries
│   │   └── metrics/                    # Metrics collection & reporting
│   ├── loaders/
│   │   ├── huggingface_loader.py       # HuggingFace datasets
│   │   └── commoncrawl_loader.py       # CommonCrawl WARC files
│   ├── operators/
│   │   ├── refiners/                   # Refiners (text, image, video)
│   │   │   └── llm_synthesis/          # LLM synthesis (online, offline, parser)
│   │   ├── filters/                    # Text + Image filters
│   │   └── dedup/                      # Deduplicators (phash, minhash)
│   ├── writers/
│   │   ├── parquet_writer.py           # Parquet output
│   │   └── iceberg_writer.py           # Apache Iceberg output
│   └── models/                         # Model trainers (aesthetic, AIGC, k-means)
├── src/lib.rs                          # 🦀 Rust operators (quality, phash, HTML extraction)
├── configs/                            # Pipeline configurations
│   ├── z_image.yaml                    # Image pipeline
│   ├── example_commoncrawl.yaml        # Text pipeline
│   └── example_llm_synthesis.yaml      # LLM synthesis pipeline
├── tests/                              # Unit tests
├── Cargo.toml                          # Rust dependencies
└── pyproject.toml                      # Python config (maturin build)
Extending the Pipeline
Custom Text Filter
from mega_data_factory.framework import Filter, OperatorRegistry

class MyTextFilter(Filter):
    def __init__(self, min_words: int = 50):
        super().__init__()
        self.min_words = min_words

    def should_keep_batch(self, records: list[dict]) -> list[bool]:
        return [len(r.get("text", "").split()) >= self.min_words for r in records]

OperatorRegistry.register("MyTextFilter", MyTextFilter)
Custom Image Refiner
from mega_data_factory.framework import Refiner, OperatorRegistry
import pyarrow as pa

class MyImageRefiner(Refiner):
    def refine_batch(self, records: list[dict]) -> None:
        for record in records:
            record["my_score"] = compute_score(record["image"])

    def get_output_schema(self) -> dict[str, pa.DataType]:
        return {"my_score": pa.float32()}

OperatorRegistry.register("MyImageRefiner", MyImageRefiner)
Key Features
- Pipeline Parallelism: Ray ObjectRef chaining enables concurrent stage execution without blocking (details)
- Distributed Data Loading: Sharded file loading with checkpoint support for fault recovery
- Backpressure Control: Bounded in-flight batches prevent OOM on large datasets
- Bucketed Deduplication: Distributed state sharding scales to 100B+ keys (details)
- Rust Acceleration: 10-25x speedup for image quality, hashing, and HTML extraction
- GPU Optimization: CLIP/SigLIP embedding extraction with FP16 and batch inference
- Elastic Scaling: Dynamic worker allocation with min/max replicas per stage
- LLM Synthesis: Online (API) and offline (vLLM) modes with account/proxy pools and response parsing
- Config-Driven: YAML configs define entire pipelines with no code changes
References
Text Data Pipelines
- RefinedWeb (arXiv:2306.01116) - URL filtering, trafilatura, MassiveText dedup
- FineWeb - 15T token dataset, quality filtering
- DCLM (arXiv:2406.11794) - Data curation for language models
- Dolma (arXiv:2402.00159) - Open corpus for LLM pretraining
Image & Vision-Language
- Z-Image (arXiv:2511.22699) - Image generation foundation model data
- DataComp (arXiv:2304.14108) - CLIP filtering benchmark
- LAION-5B (arXiv:2210.08402) - Large-scale image-text dataset
Tools & Models
- OpenCLIP - CLIP implementation
- SigLIP2 - Vision encoder
- dom_smoothie - Rust readability.js port
License
MIT License
Citation
@software{mega_data_factory,
  author       = {Duo An},
  title        = {Mega Data Factory},
  year         = {2025},
  publisher    = {GitHub},
  url          = {https://github.com/duoan/mega-data-factory}
}
Similar repos
Contributors
Languages
Python
95.2%
Jinja
2.7%
Rust
2.1%