
README
Awesome-Knowledge-Fusion

If you have any questions about the library, please feel free to contact us. Email: duguodong7@gmail.com
A comprehensive list of papers about '[Knowledge Fusion: A Comprehensive Survey.]'.
Abstract
As the comprehensive capabilities of foundational large models rapidly improve, similar general abilities have emerged across different models, making capability transfer and fusion between them more feasible. Knowledge fusion aims to integrate existing LLMs of diverse architectures and capabilities into a more powerful model through efficient methods such as knowledge distillation, model merging, mixture of experts, and PEFT, thereby reducing the need for costly LLM development and adaptation. We provide a comprehensive overview of model merging methods and theories, covering their applications across various fields and scenarios, including LLMs, MLLMs, image generation, model compression, continual learning, and more. Finally, we highlight the challenges of knowledge fusion and explore future research directions.
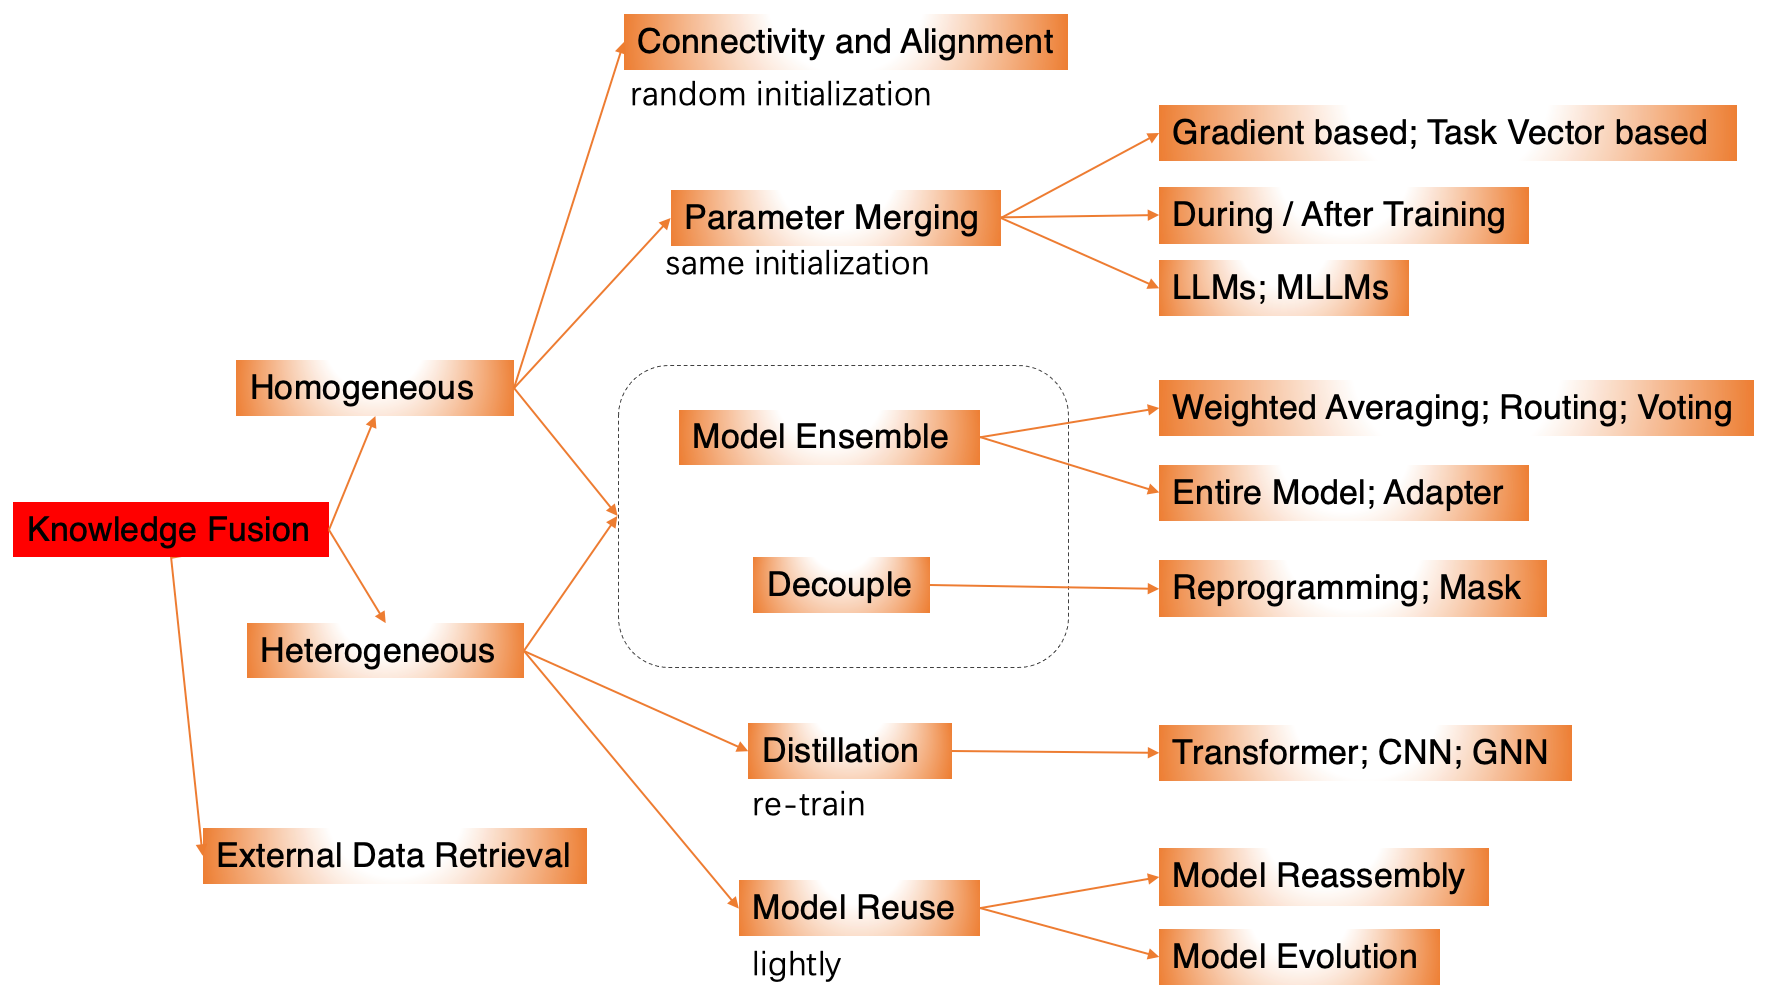
Framework
1. Connectivity and Alignment
1.1 Model Connectivity
1.2 Weight Alignment
2. Parameter Merging
2.1 Merging Methods
Optimization based
Task Vector based
2.2 During or After Training
During Training
After Training
2.3 For LLMs and MLLMs
For LLMs
For Multimodal Language Models
3. Model Ensemble
3.1 Ensemble Methods
Weighted Averaging
Routing
| Paper Title | Code | Publication & Date |
|---|---|---|
| Soft merging of experts with adaptive routing | TMLR 2024 | |
| DeepSeekMoE: Towards Ultimate Expert Specialization in Mixture-of-Experts Language Models | DeepSeekMoE | ArXiv 24.01 |
| Multiple Expert Brainstorming for Domain Adaptive Person Re-identification | MEB-Net | ECCV 2020 |
| Merging Vision Transformers from Different Tasks and Domains | ArXiv 23.12 |
3.2 Ensemble Object
Entire Model
Adapter
4. Decouple
4.1 Reprogramming
4.2 Mask
| Paper Title | Code | Publication & Date |
|---|---|---|
| EMR-Merging: Tuning-Free High-Performance Model Merging | EMR_Merging | NeurIPS 2024 spolight |
| Model Composition for Multimodal Large Language Models | THUNLP | ACL 2024 |
| Localizing Task Information for Improved Model Merging and Compression | tall_masks | ICML 2024 |
| Adapting a Single Network to Multiple Tasks by Learning to Mask Weights | Piggyback | ECCV 2018 |
5. Distillation
5.1 Transformer
5.2 CNN
5.3 GNN
| Paper Title | Code | Publication & Date |
|---|---|---|
| Amalgamating Knowledge From Heterogeneous Graph Neural Networks | ycjing | CVPR 2021 |
6. Model Reuse
6.1 Model Reassembly
| Paper Title | Code | Publication & Date |
|---|---|---|
| Advances in Robust Federated Learning: Heterogeneity Considerations | ArXiv 24.05 | |
| Towards Personalized Federated Learning via Heterogeneous Model Reassembly | pFedHR | NeurIPS 2023 |
| Stitchable Neural Networks | snnet | CVPR 2023 Highlight |
| Instant Soup Cheap Pruning Ensembles in A Single Pass Can Draw Lottery Tickets from Large Models | instant_soup | ICML 2023 |
| Deep Incubation: Training Large Models by Divide-and-Conquering | Deep-Incubation | ArXiv 22.12 |
| Deep Model Reassembly | DeRy | NeurIPS 2022 |
| GAN Cocktail: Mixing GANs without Dataset Access | GAN-cocktail | ECCV 2022 |
6.2 Model Evolution
| Paper Title | Code | Publication & Date |
|---|---|---|
| It’s Morphing Time: Unleashing the Potential of Multiple LLMs via Multi-objective Optimization | - | ArXiv 24.07 |
| Evolutionary Optimization of Model Merging Recipes | EvoLLM | ArXiv 24.03 |
| Knowledge Fusion By Evolving Weights of Language Models | Model_Evolver | ACL 2024 |
| Population-based evolutionary gaming for unsupervised person re-identification | - | IJCV 2023 |
7. Others
7.1 External Data Retrieval
| Paper Title | Code | Publication & Date |
|---|---|---|
| Evaluating the External and Parametric Knowledge Fusion of Large Language Models | ArXiv 24.05 | |
| Knowledge Fusion and Semantic Knowledge Ranking for Open Domain Question Answering | ArXiv 20.04 |
7.2 Multi-Objective Optimization
| Paper Title | Code | Publication & Date |
|---|---|---|
| You Only Merge Once: Learning the Pareto Set of Preference-Aware Model Merging | ArXiv 24.08 | |
| Towards Efficient Pareto Set Approximation via Mixture of Experts Based Model Fusion | ArXiv 24.06 | |
| MAP: Low-compute Model Merging with Amortized Pareto Fronts via Quadratic Approximation | ArXiv 24.06 |
7.3 Others
| Paper Title | Code | Publication & Date |
|---|---|---|
| Adaptive Discovering and Merging for Incremental Novel Class Discovery | AAAI 2024 | |
| Knowledge Fusion and Semantic Knowledge Ranking for Open Domain Question Answering | ArXiv 20.04 |
7.4 Other Surveys
| Paper Title | Code | Publication & Date |
|---|---|---|
| A Survey on Model MoErging: Recycling and Routing Among Specialized Experts for Collaborative Learning | ArXiv 24.08 | |
| Model Merging in LLMs, MLLMs, and Beyond: Methods, Theories, Applications and Opportunities | Yang | ArXiv 24.08 |
| Merge, Ensemble, and Cooperate! A Survey on Collaborative Strategies in the Era of Large Language Models | ArXiv 24.07 | |
| Arcee's MergeKit: A Toolkit for Merging Large Language Models | MergeKit | ArXiv 24.03 |
| Learn From Model Beyond Fine-Tuning: A Survey | LFM | ArXiv 23.10 |
| Deep Model Fusion: A Survey | ArXiv 23.09 | |
| A curated paper list of Model Merging methods | ycjing | GitHub |
Contributors
Junlin Lee; Qi Tang; Runhua Jiang.
Star History
Contact
We invite all researchers to contribute to this repository, 'Knowledge Fusion: The Integration of Model Capabilities'. If you have any questions about the library, please feel free to contact us.
Email: duguodong7@gmail.com
Contributors

62 commits
Similar repos


README
Awesome-Knowledge-Fusion
If you have any questions about the library, please feel free to contact us. Email: duguodong7@gmail.com
A comprehensive list of papers about '[Knowledge Fusion: A Comprehensive Survey.]'.
Abstract
As the comprehensive capabilities of foundational large models rapidly improve, similar general abilities have emerged across different models, making capability transfer and fusion between them more feasible. Knowledge fusion aims to integrate existing LLMs of diverse architectures and capabilities into a more powerful model through efficient methods such as knowledge distillation, model merging, mixture of experts, and PEFT, thereby reducing the need for costly LLM development and adaptation. We provide a comprehensive overview of model merging methods and theories, covering their applications across various fields and scenarios, including LLMs, MLLMs, image generation, model compression, continual learning, and more. Finally, we highlight the challenges of knowledge fusion and explore future research directions.
Framework
1. Connectivity and Alignment
1.1 Model Connectivity
1.2 Weight Alignment
2. Parameter Merging
2.1 Merging Methods
Optimization based
Task Vector based
2.2 During or After Training
During Training
After Training
2.3 For LLMs and MLLMs
For LLMs
For Multimodal Language Models
3. Model Ensemble
3.1 Ensemble Methods
Weighted Averaging
Routing
| Paper Title | Code | Publication & Date |
|---|---|---|
| Soft merging of experts with adaptive routing | TMLR 2024 | |
| DeepSeekMoE: Towards Ultimate Expert Specialization in Mixture-of-Experts Language Models | DeepSeekMoE | ArXiv 24.01 |
| Multiple Expert Brainstorming for Domain Adaptive Person Re-identification | MEB-Net | ECCV 2020 |
| Merging Vision Transformers from Different Tasks and Domains | ArXiv 23.12 |
3.2 Ensemble Object
Entire Model
Adapter
4. Decouple
4.1 Reprogramming
4.2 Mask
| Paper Title | Code | Publication & Date |
|---|---|---|
| EMR-Merging: Tuning-Free High-Performance Model Merging | EMR_Merging | NeurIPS 2024 spolight |
| Model Composition for Multimodal Large Language Models | THUNLP | ACL 2024 |
| Localizing Task Information for Improved Model Merging and Compression | tall_masks | ICML 2024 |
| Adapting a Single Network to Multiple Tasks by Learning to Mask Weights | Piggyback | ECCV 2018 |
5. Distillation
5.1 Transformer
5.2 CNN
5.3 GNN
| Paper Title | Code | Publication & Date |
|---|---|---|
| Amalgamating Knowledge From Heterogeneous Graph Neural Networks | ycjing | CVPR 2021 |
6. Model Reuse
6.1 Model Reassembly
| Paper Title | Code | Publication & Date |
|---|---|---|
| Advances in Robust Federated Learning: Heterogeneity Considerations | ArXiv 24.05 | |
| Towards Personalized Federated Learning via Heterogeneous Model Reassembly | pFedHR | NeurIPS 2023 |
| Stitchable Neural Networks | snnet | CVPR 2023 Highlight |
| Instant Soup Cheap Pruning Ensembles in A Single Pass Can Draw Lottery Tickets from Large Models | instant_soup | ICML 2023 |
| Deep Incubation: Training Large Models by Divide-and-Conquering | Deep-Incubation | ArXiv 22.12 |
| Deep Model Reassembly | DeRy | NeurIPS 2022 |
| GAN Cocktail: Mixing GANs without Dataset Access | GAN-cocktail | ECCV 2022 |
6.2 Model Evolution
| Paper Title | Code | Publication & Date |
|---|---|---|
| It’s Morphing Time: Unleashing the Potential of Multiple LLMs via Multi-objective Optimization | - | ArXiv 24.07 |
| Evolutionary Optimization of Model Merging Recipes | EvoLLM | ArXiv 24.03 |
| Knowledge Fusion By Evolving Weights of Language Models | Model_Evolver | ACL 2024 |
| Population-based evolutionary gaming for unsupervised person re-identification | - | IJCV 2023 |
7. Others
7.1 External Data Retrieval
| Paper Title | Code | Publication & Date |
|---|---|---|
| Evaluating the External and Parametric Knowledge Fusion of Large Language Models | ArXiv 24.05 | |
| Knowledge Fusion and Semantic Knowledge Ranking for Open Domain Question Answering | ArXiv 20.04 |
7.2 Multi-Objective Optimization
| Paper Title | Code | Publication & Date |
|---|---|---|
| You Only Merge Once: Learning the Pareto Set of Preference-Aware Model Merging | ArXiv 24.08 | |
| Towards Efficient Pareto Set Approximation via Mixture of Experts Based Model Fusion | ArXiv 24.06 | |
| MAP: Low-compute Model Merging with Amortized Pareto Fronts via Quadratic Approximation | ArXiv 24.06 |
7.3 Others
| Paper Title | Code | Publication & Date |
|---|---|---|
| Adaptive Discovering and Merging for Incremental Novel Class Discovery | AAAI 2024 | |
| Knowledge Fusion and Semantic Knowledge Ranking for Open Domain Question Answering | ArXiv 20.04 |
7.4 Other Surveys
| Paper Title | Code | Publication & Date |
|---|---|---|
| A Survey on Model MoErging: Recycling and Routing Among Specialized Experts for Collaborative Learning | ArXiv 24.08 | |
| Model Merging in LLMs, MLLMs, and Beyond: Methods, Theories, Applications and Opportunities | Yang | ArXiv 24.08 |
| Merge, Ensemble, and Cooperate! A Survey on Collaborative Strategies in the Era of Large Language Models | ArXiv 24.07 | |
| Arcee's MergeKit: A Toolkit for Merging Large Language Models | MergeKit | ArXiv 24.03 |
| Learn From Model Beyond Fine-Tuning: A Survey | LFM | ArXiv 23.10 |
| Deep Model Fusion: A Survey | ArXiv 23.09 | |
| A curated paper list of Model Merging methods | ycjing | GitHub |
Contributors
Junlin Lee; Qi Tang; Runhua Jiang.
Star History
Contact
We invite all researchers to contribute to this repository, 'Knowledge Fusion: The Integration of Model Capabilities'. If you have any questions about the library, please feel free to contact us.
Email: duguodong7@gmail.com
Similar repos
Contributors
62 commits