Elegant PyTorch implementation of paper Model-Agnostic Meta-Learning (MAML)
Python
2,482
39 commits
updated May 16, 2019
PyTorch implementation of the supervised learning experiments from the paper: Model-Agnostic Meta-Learning (MAML).
Version 1.0: Both
MiniImagenetandOmniglotDatasets are supported! Have Fun~
Version 2.0: Re-write meta learner and basic learner. Solved some serious bugs in version 1.0.
For Tensorflow Implementation, please visit official HERE and simplier version HERE.
For First-Order Approximation Implementation, Reptile namely, please visit HERE.

For 5-way 1-shot exp., it allocates nearly 6GB GPU memory.
miniimagenet/
├── images
	├── n0210891500001298.jpg
	├── n0287152500001298.jpg
	...
├── test.csv
├── val.csv
└── train.csv
path in miniimagenet_train.py: mini = MiniImagenet('miniimagenet/', mode='train', n_way=args.n_way, k_shot=args.k_spt,
k_query=args.k_qry,
batchsz=10000, resize=args.imgsz)
...
mini_test = MiniImagenet('miniimagenet/', mode='test', n_way=args.n_way, k_shot=args.k_spt,
k_query=args.k_qry,
batchsz=100, resize=args.imgsz)
to your actual data path.
python miniimagenet_train.py and the running screenshot is as follows:
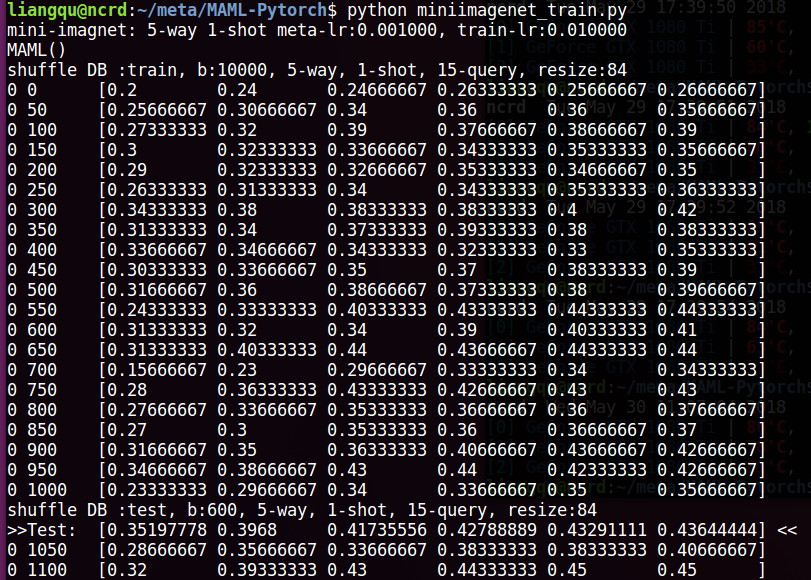
If your reproducation perf. is not so good, maybe you can enlarge your training epoch to get longer training. And MAML is notorious for its hard training. Therefore, this implementation only provide you a basic start point to begin your research.
and the performance below is true and achieved on my machine.
| Model | Fine Tune | 5-way Acc. | 20-way Acc. | ||
|---|---|---|---|---|---|
| 1-shot | 5-shot | 1-shot | 5-shot | ||
| Matching Nets | N | 43.56% | 55.31% | 17.31% | 22.69% |
| Meta-LSTM | 43.44% | 60.60% | 16.70% | 26.06% | |
| MAML | Y | 48.7% | 63.11% | 16.49% | 19.29% |
| Ours | Y | 46.2% | 60.3% | - | - |
run python omniglot_train.py, the program will download omniglot dataset automatically.
decrease the value of args.task_num to fit your GPU memory capacity.
For 5-way 1-shot exp., it allocates nearly 3GB GPU memory.
@misc{MAML_Pytorch,
  author = {Liangqu Long},
  title = {MAML-Pytorch Implementation},
  year = {2018},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/dragen1860/MAML-Pytorch}},
  commit = {master}
}
5,711 followers · starred Jan 2020
242 followers · starred May 2021
267 followers · starred Feb 2019
112 followers · starred May 2018
Elegant PyTorch implementation of paper Model-Agnostic Meta-Learning (MAML)
Python
2,482
39 commits
updated May 16, 2019
PyTorch implementation of the supervised learning experiments from the paper: Model-Agnostic Meta-Learning (MAML).
Version 1.0: Both
MiniImagenetandOmniglotDatasets are supported! Have Fun~
Version 2.0: Re-write meta learner and basic learner. Solved some serious bugs in version 1.0.
For Tensorflow Implementation, please visit official HERE and simplier version HERE.
For First-Order Approximation Implementation, Reptile namely, please visit HERE.
For 5-way 1-shot exp., it allocates nearly 6GB GPU memory.
miniimagenet/
├── images
	├── n0210891500001298.jpg
	├── n0287152500001298.jpg
	...
├── test.csv
├── val.csv
└── train.csv
path in miniimagenet_train.py: mini = MiniImagenet('miniimagenet/', mode='train', n_way=args.n_way, k_shot=args.k_spt,
k_query=args.k_qry,
batchsz=10000, resize=args.imgsz)
...
mini_test = MiniImagenet('miniimagenet/', mode='test', n_way=args.n_way, k_shot=args.k_spt,
k_query=args.k_qry,
batchsz=100, resize=args.imgsz)
to your actual data path.
python miniimagenet_train.py and the running screenshot is as follows:
If your reproducation perf. is not so good, maybe you can enlarge your training epoch to get longer training. And MAML is notorious for its hard training. Therefore, this implementation only provide you a basic start point to begin your research.
and the performance below is true and achieved on my machine.
| Model | Fine Tune | 5-way Acc. | 20-way Acc. | ||
|---|---|---|---|---|---|
| 1-shot | 5-shot | 1-shot | 5-shot | ||
| Matching Nets | N | 43.56% | 55.31% | 17.31% | 22.69% |
| Meta-LSTM | 43.44% | 60.60% | 16.70% | 26.06% | |
| MAML | Y | 48.7% | 63.11% | 16.49% | 19.29% |
| Ours | Y | 46.2% | 60.3% | - | - |
run python omniglot_train.py, the program will download omniglot dataset automatically.
decrease the value of args.task_num to fit your GPU memory capacity.
For 5-way 1-shot exp., it allocates nearly 3GB GPU memory.
@misc{MAML_Pytorch,
  author = {Liangqu Long},
  title = {MAML-Pytorch Implementation},
  year = {2018},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/dragen1860/MAML-Pytorch}},
  commit = {master}
}
5,711 followers · starred Jan 2020
242 followers · starred May 2021
267 followers · starred Feb 2019
112 followers · starred May 2018