This repository contains a vision-language pipeline for converting handwritten mathematical formulas into LaTeX. The project was developed as a technical assignment solution and includes training code, evaluation code, command-line inference, and a Streamlit demo application.
The final successful solution is based on Qwen/Qwen2-VL-2B-Instruct fine-tuned with LoRA on linxy/LaTeX_OCR.
The full technical report for the assignment is available in TECHNICAL_REPORT.md.
The project solves handwritten formula recognition as an image-to-text task. An input image containing a handwritten mathematical formula is processed by a vision-language model and converted into LaTeX. In addition to the training and evaluation pipeline, the repository includes a Streamlit application for interactive inference and visual rendering of the generated formula.
The final best-performing setup uses Qwen/Qwen2-VL-2B-Instruct fine-tuned on linxy/LaTeX_OCR. The resulting model significantly outperformed zero-shot and one-shot baselines and also outperformed the combined-dataset SFT variant.
Final results on linxy/LaTeX_OCR:test:
| Setup | BLEU | Exact Match | Edit Distance | Token F1 |
|---|---|---|---|---|
| zero_shot | 0.5210 | 0.1429 | 0.5390 | 0.7507 |
| one_shot | 0.2082 | 0.1000 | 0.3735 | 0.4234 |
| sft_latex_ocr | 0.8989 | 0.6857 | 0.9115 | 0.9685 |
| sft_combined | 0.8492 | 0.6000 | 0.8722 | 0.9527 |
Published checkpoints:
.
|-- Dockerfile
|-- docker-compose.yml
|-- README.md
|-- TECHNICAL_REPORT.md
|-- requirements.txt
|-- configs/
|   `-- train_config.qwen2vl_2b.yaml
|-- src/
|   |-- data_utils.py
|   |-- evaluate.py
|   |-- inference.py
|   |-- metrics.py
|   |-- model_utils.py
|   `-- train.py
|-- app/
|   `-- streamlit_app.py
|-- scripts/
|   `-- upload_to_hub.py
`-- demo/
    |-- streamlit_demo.mp4
    |-- streamlit_input_photo.jpg
    |-- streamlit_prediction_text.tex
    `-- streamlit_rendered_output.png
git clone https://github.com/dmitryz1024/Multimodal_Reasoning_for_STEM.git
cd Multimodal_Reasoning_for_STEM
python3 -m venv venv
source venv/bin/activate
python -m pip install --upgrade pip
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu128
pip install -r requirements.txt
If Hugging Face authentication is required:
huggingface-cli login
Best single-dataset run:
python -m src.train --config configs/train_config.qwen2vl_2b.yaml --run_name qwen2vl_latex_only
Combined run:
python -m src.train --config configs/train_config.qwen2vl_2b.yaml --use_secondary --run_name qwen2vl_combined
python -m src.evaluate --model_name "Qwen/Qwen2-VL-2B-Instruct" --checkpoint_latex_ocr ./checkpoints/qwen2vl_latex_only/final --checkpoint_combined ./checkpoints/qwen2vl_combined/final --dataset "linxy/LaTeX_OCR" --subset "human_handwrite" --eval_mode all --output evaluation_results_qwen2vl_all.json
python -m src.inference path/to/image.png
With a fine-tuned checkpoint:
python -m src.inference path/to/image.png --checkpoint ./checkpoints/qwen2vl_latex_only/final
streamlit run app/streamlit_app.py
Build image:
docker build -t latex-ocr .
Run the app:
docker compose up latex-ocr
Run training:
docker compose run --rm train
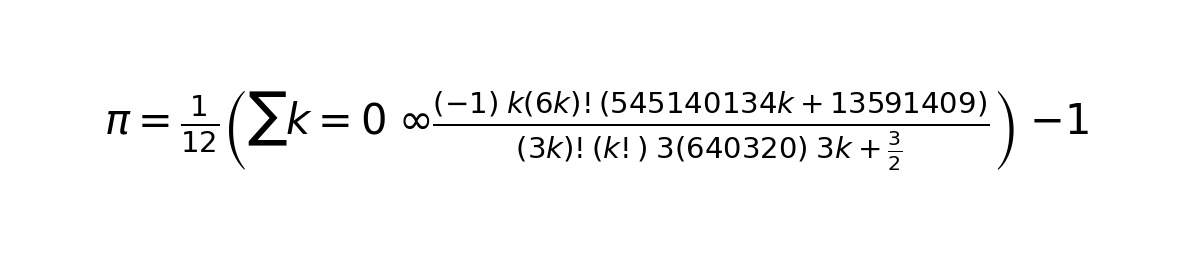
The repository includes demo artifacts generated with the final model:
Preview:
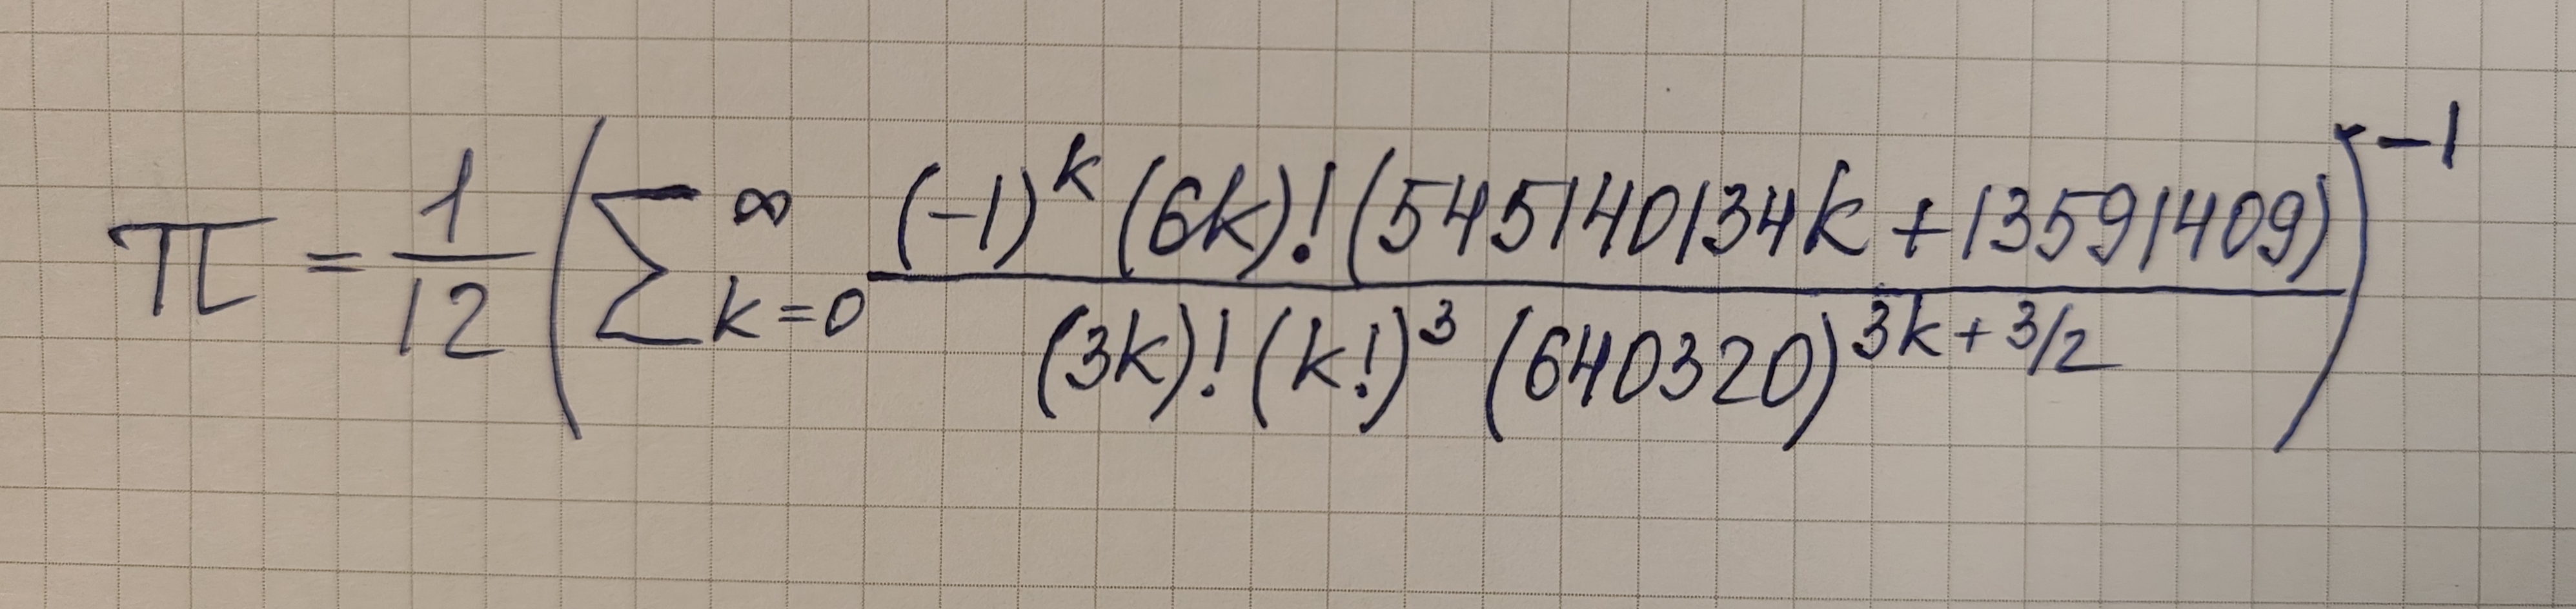
Qwen/Qwen2-VL-2B-Instruct.This repository contains a vision-language pipeline for converting handwritten mathematical formulas into LaTeX. The project was developed as a technical assignment solution and includes training code, evaluation code, command-line inference, and a Streamlit demo application.
The final successful solution is based on Qwen/Qwen2-VL-2B-Instruct fine-tuned with LoRA on linxy/LaTeX_OCR.
The full technical report for the assignment is available in TECHNICAL_REPORT.md.
The project solves handwritten formula recognition as an image-to-text task. An input image containing a handwritten mathematical formula is processed by a vision-language model and converted into LaTeX. In addition to the training and evaluation pipeline, the repository includes a Streamlit application for interactive inference and visual rendering of the generated formula.
The final best-performing setup uses Qwen/Qwen2-VL-2B-Instruct fine-tuned on linxy/LaTeX_OCR. The resulting model significantly outperformed zero-shot and one-shot baselines and also outperformed the combined-dataset SFT variant.
Final results on linxy/LaTeX_OCR:test:
| Setup | BLEU | Exact Match | Edit Distance | Token F1 |
|---|---|---|---|---|
| zero_shot | 0.5210 | 0.1429 | 0.5390 | 0.7507 |
| one_shot | 0.2082 | 0.1000 | 0.3735 | 0.4234 |
| sft_latex_ocr | 0.8989 | 0.6857 | 0.9115 | 0.9685 |
| sft_combined | 0.8492 | 0.6000 | 0.8722 | 0.9527 |
Published checkpoints:
.
|-- Dockerfile
|-- docker-compose.yml
|-- README.md
|-- TECHNICAL_REPORT.md
|-- requirements.txt
|-- configs/
|   `-- train_config.qwen2vl_2b.yaml
|-- src/
|   |-- data_utils.py
|   |-- evaluate.py
|   |-- inference.py
|   |-- metrics.py
|   |-- model_utils.py
|   `-- train.py
|-- app/
|   `-- streamlit_app.py
|-- scripts/
|   `-- upload_to_hub.py
`-- demo/
    |-- streamlit_demo.mp4
    |-- streamlit_input_photo.jpg
    |-- streamlit_prediction_text.tex
    `-- streamlit_rendered_output.png
git clone https://github.com/dmitryz1024/Multimodal_Reasoning_for_STEM.git
cd Multimodal_Reasoning_for_STEM
python3 -m venv venv
source venv/bin/activate
python -m pip install --upgrade pip
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu128
pip install -r requirements.txt
If Hugging Face authentication is required:
huggingface-cli login
Best single-dataset run:
python -m src.train --config configs/train_config.qwen2vl_2b.yaml --run_name qwen2vl_latex_only
Combined run:
python -m src.train --config configs/train_config.qwen2vl_2b.yaml --use_secondary --run_name qwen2vl_combined
python -m src.evaluate --model_name "Qwen/Qwen2-VL-2B-Instruct" --checkpoint_latex_ocr ./checkpoints/qwen2vl_latex_only/final --checkpoint_combined ./checkpoints/qwen2vl_combined/final --dataset "linxy/LaTeX_OCR" --subset "human_handwrite" --eval_mode all --output evaluation_results_qwen2vl_all.json
python -m src.inference path/to/image.png
With a fine-tuned checkpoint:
python -m src.inference path/to/image.png --checkpoint ./checkpoints/qwen2vl_latex_only/final
streamlit run app/streamlit_app.py
Build image:
docker build -t latex-ocr .
Run the app:
docker compose up latex-ocr
Run training:
docker compose run --rm train
The repository includes demo artifacts generated with the final model:
Preview:
Qwen/Qwen2-VL-2B-Instruct.