
README
Enhancing Temporal Consistency in Video Editing by Reconstructing Videos with 3D Gaussian Splatting [TMLR 2025]
Project page | Paper
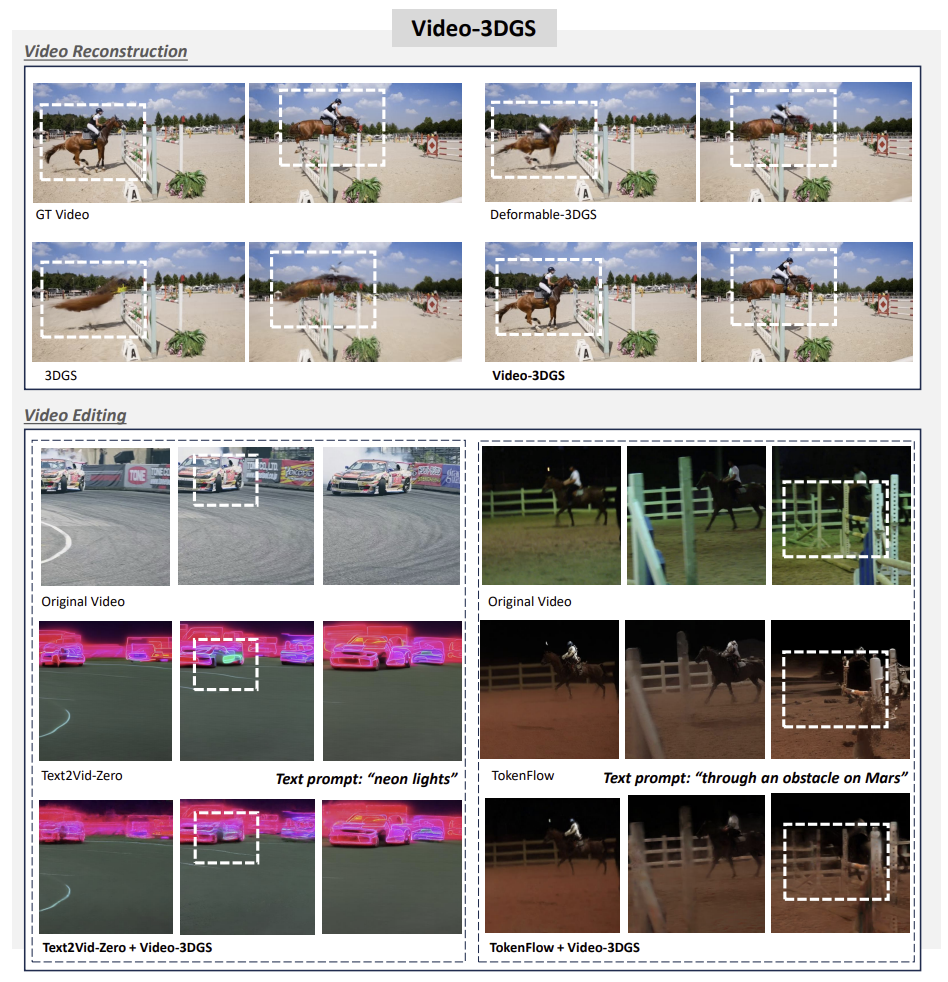
This repository contains the official Pytorch implementation of the paper "Enhancing Temporal Consistency in Video Editing by Reconstructing Videos with 3D Gaussian Splatting".
Dataset
According to our paper, we conducted two tasks with the following datasets.
- Video reconstruction: DAVIS dataset (480x854)
- Video editing: LOVEU-TGVE-2023 dataset (480x480)
There are two options for pre-processing the datasets.
- You can download the datasets with above link for original dataset and run MC-COLMAP.
- You directly download MC-COLMAP processed dataset from here
We organize the datasets as follows:
├── datasets
│   | recon
│     ├── DAVIS
│       ├── JPEGImages
│         ├── 480p
│           ├── blackswan
│           ├── blackswan_pts_camera_from_deva
│           ├── ...
│   | edit
│     ├── DAVIS
│       ├── 480p_frames
│         ├── bmx-rider
│         ├── bmx-rider_pts_camera_from_deva
Pipeline
Environments
Setting up environments for training contains three parts:
- Download COLMAP and put it under "submodules".
- Download Tiny-cuda-nn and put it under "submodules".
git clone https://github.com/dlsrbgg33/Video-3DGS.git --recursive
cd Video-3DGS

conda create -n video_3dgs python=3.8
conda activate video_3dgs

# install pytorch
pip install torch==1.12.1+cu113 torchvision==0.13.1+cu113 torchaudio==0.12.1 --extra-index-url https://download.pytorch.org/whl/cu113

# install packages & dependencies
bash requirement.sh
Setting up environments for evaluation contains two parts:
- download the pre-trained optical flow models (WarpSSIM)
cd models/optical_flow/RAFT
bash download_models.sh
- download CLIP pre-trained models (CLIPScore, Qedit)
cd models/clipscore
git lfs install
git clone https://huggingface.co/openai/clip-vit-large-patch14
git clone https://huggingface.co/laion/CLIP-ViT-H-14-laion2B-s32B-b79K
Video-3DGS (1st stage): Video Reconstruction
bash sh_recon/davis.sh
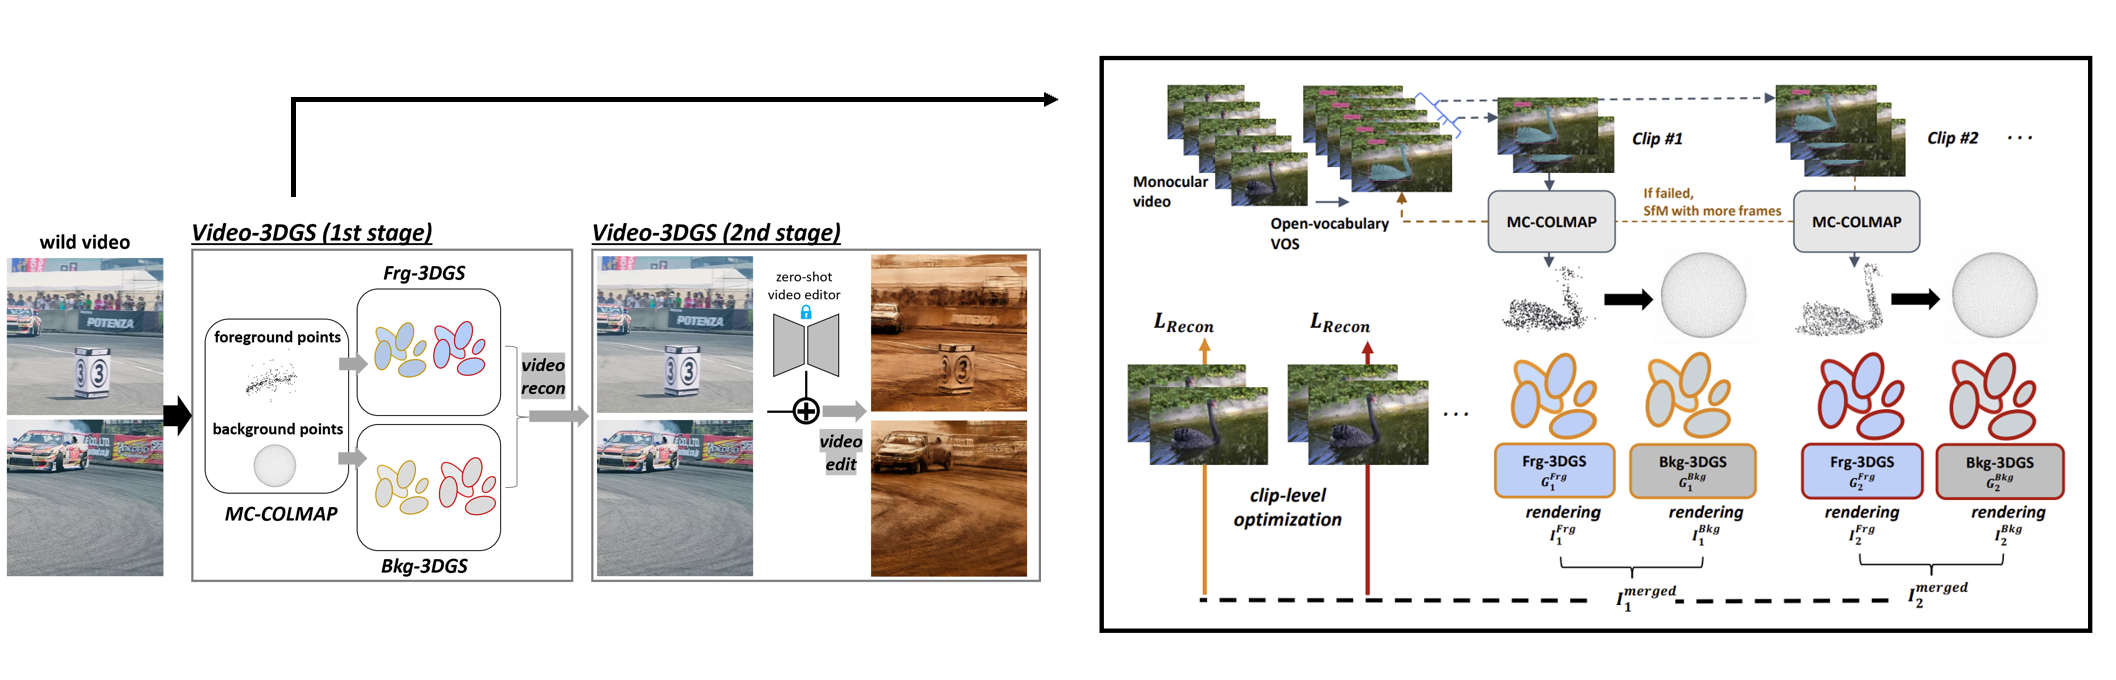
To effectively obtain reprentation for video editing, we utilize all the training images for each video scene in this stage.
Arguments:
- iteration num
- group size
- number of random points
https://github.com/user-attachments/assets/8eb8e201-ef3b-461c-985b-72d3fa19cd54?width=100&height=100
- Video reconstruction for "drift-turn" in DAVIS dataset
Video-3DGS (2nd stage): Video Editing
bash sh_edit/{initial_editor}/{dataset}.sh
We currently support three "initial editors": Text2Video-Zero / TokenFlow / RAVE
We recommend user to install related packages and modules of above initial editors in Video-3DGS framework to conduct initial video editing.
For running TokenFlow efficiently (e.g., edit long video), we borrowed the some strategies from here.
https://github.com/user-attachments/assets/923dec4a-fb23-4c02-a187-a51cb57501a8?width=100&height=100
- Singe-phase refiner for "Text2Video-Zero" editor
Video-3DGS (2nd stage) + Recursive and Ensembled refinement
bash sh_edit/{initial_editor}/davis_re.sh
https://github.com/user-attachments/assets/866d241c-8d63-4d49-9657-9b02737e9c40?width=100&height=100
- Recursive and ensembled refiner for "Text2Video-Zero" editor
📖BibTeX
If you find this code helpful in your research or wish to refer to the baseline results, please use the following BibTeX entry.
@article{shin2024enhancing,
  title={Enhancing Temporal Consistency in Video Editing by Reconstructing Videos with 3D Gaussian Splatting},
  author={Shin, Inkyu and Yu, Qihang and Shen, Xiaohui and Kweon, In So and Yoon, Kuk-Jin and Chen, Liang-Chieh},
  journal={arXiv preprint arXiv:2406.02541},
  year={2024}
}
🤗Acknowledgements
- Thanks to 3DGS for providing codebase of 3D Gaussian Splatting.
- Thanks to Deformable-3DGS for providing codebase of deformable model.
- Thanks to Text2Video-Zero, TokenFlow and RAVE for providing codebase of zero-shot video editors.
- Thanks to RAFT and CLIP for providing evaluation metric codebase.
Similar repos




Languages
Python
96.2%
Cuda
2.2%
C++
1.1%
README
Enhancing Temporal Consistency in Video Editing by Reconstructing Videos with 3D Gaussian Splatting [TMLR 2025]
Project page | Paper
This repository contains the official Pytorch implementation of the paper "Enhancing Temporal Consistency in Video Editing by Reconstructing Videos with 3D Gaussian Splatting".
Dataset
According to our paper, we conducted two tasks with the following datasets.
- Video reconstruction: DAVIS dataset (480x854)
- Video editing: LOVEU-TGVE-2023 dataset (480x480)
There are two options for pre-processing the datasets.
- You can download the datasets with above link for original dataset and run MC-COLMAP.
- You directly download MC-COLMAP processed dataset from here
We organize the datasets as follows:
├── datasets
│   | recon
│     ├── DAVIS
│       ├── JPEGImages
│         ├── 480p
│           ├── blackswan
│           ├── blackswan_pts_camera_from_deva
│           ├── ...
│   | edit
│     ├── DAVIS
│       ├── 480p_frames
│         ├── bmx-rider
│         ├── bmx-rider_pts_camera_from_deva
Pipeline
Environments
Setting up environments for training contains three parts:
- Download COLMAP and put it under "submodules".
- Download Tiny-cuda-nn and put it under "submodules".
git clone https://github.com/dlsrbgg33/Video-3DGS.git --recursive
cd Video-3DGS

conda create -n video_3dgs python=3.8
conda activate video_3dgs

# install pytorch
pip install torch==1.12.1+cu113 torchvision==0.13.1+cu113 torchaudio==0.12.1 --extra-index-url https://download.pytorch.org/whl/cu113

# install packages & dependencies
bash requirement.sh
Setting up environments for evaluation contains two parts:
- download the pre-trained optical flow models (WarpSSIM)
cd models/optical_flow/RAFT
bash download_models.sh
- download CLIP pre-trained models (CLIPScore, Qedit)
cd models/clipscore
git lfs install
git clone https://huggingface.co/openai/clip-vit-large-patch14
git clone https://huggingface.co/laion/CLIP-ViT-H-14-laion2B-s32B-b79K
Video-3DGS (1st stage): Video Reconstruction
bash sh_recon/davis.sh
To effectively obtain reprentation for video editing, we utilize all the training images for each video scene in this stage.
Arguments:
- iteration num
- group size
- number of random points
https://github.com/user-attachments/assets/8eb8e201-ef3b-461c-985b-72d3fa19cd54?width=100&height=100
- Video reconstruction for "drift-turn" in DAVIS dataset
Video-3DGS (2nd stage): Video Editing
bash sh_edit/{initial_editor}/{dataset}.sh
We currently support three "initial editors": Text2Video-Zero / TokenFlow / RAVE
We recommend user to install related packages and modules of above initial editors in Video-3DGS framework to conduct initial video editing.
For running TokenFlow efficiently (e.g., edit long video), we borrowed the some strategies from here.
https://github.com/user-attachments/assets/923dec4a-fb23-4c02-a187-a51cb57501a8?width=100&height=100
- Singe-phase refiner for "Text2Video-Zero" editor
Video-3DGS (2nd stage) + Recursive and Ensembled refinement
bash sh_edit/{initial_editor}/davis_re.sh
https://github.com/user-attachments/assets/866d241c-8d63-4d49-9657-9b02737e9c40?width=100&height=100
- Recursive and ensembled refiner for "Text2Video-Zero" editor
📖BibTeX
If you find this code helpful in your research or wish to refer to the baseline results, please use the following BibTeX entry.
@article{shin2024enhancing,
  title={Enhancing Temporal Consistency in Video Editing by Reconstructing Videos with 3D Gaussian Splatting},
  author={Shin, Inkyu and Yu, Qihang and Shen, Xiaohui and Kweon, In So and Yoon, Kuk-Jin and Chen, Liang-Chieh},
  journal={arXiv preprint arXiv:2406.02541},
  year={2024}
}
🤗Acknowledgements
- Thanks to 3DGS for providing codebase of 3D Gaussian Splatting.
- Thanks to Deformable-3DGS for providing codebase of deformable model.
- Thanks to Text2Video-Zero, TokenFlow and RAVE for providing codebase of zero-shot video editors.
- Thanks to RAFT and CLIP for providing evaluation metric codebase.
Similar repos
Languages
Python
96.2%
Cuda
2.2%
C++
1.1%