
[ECCV 2022]Code for paper "DaViT: Dual Attention Vision Transformer"
Python
379
6 commits
updated Feb 13, 2024
README
DaViT: Dual Attention Vision Transformer (ECCV 2022)

This repo contains the official detection and segmentation implementation of paper "DaViT: Dual Attention Vision Transformer (ECCV 2022)", by Mingyu Ding, Bin Xiao, Noel Codella, Ping Luo, Jingdong Wang, and Lu Yuan. See Introduction.md for an introduction.
The large models for image classification will be released in https://github.com/microsoft/DaViT.
Introduction
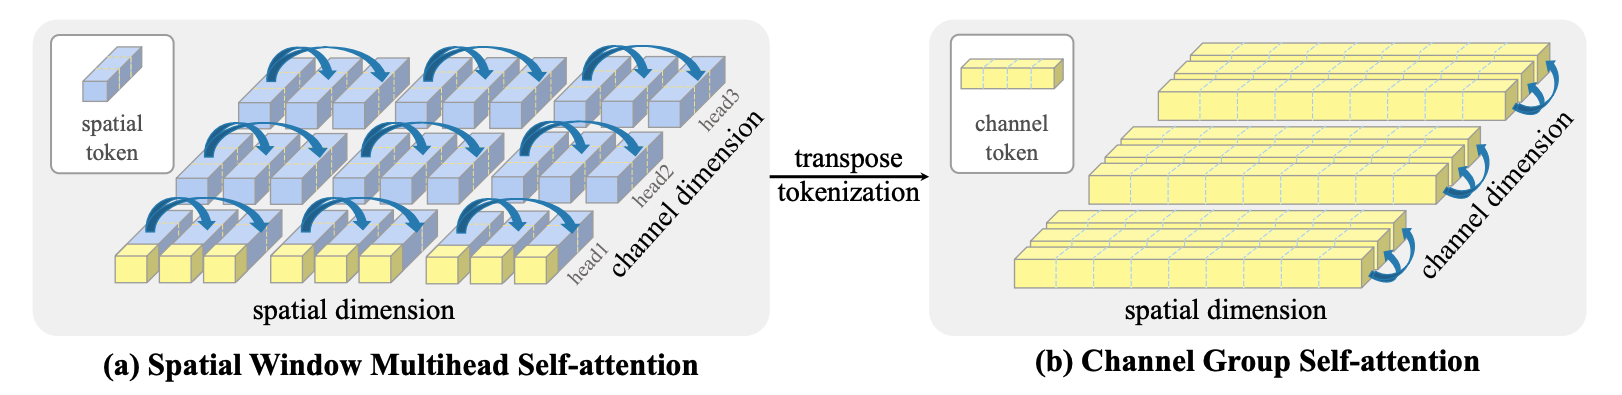
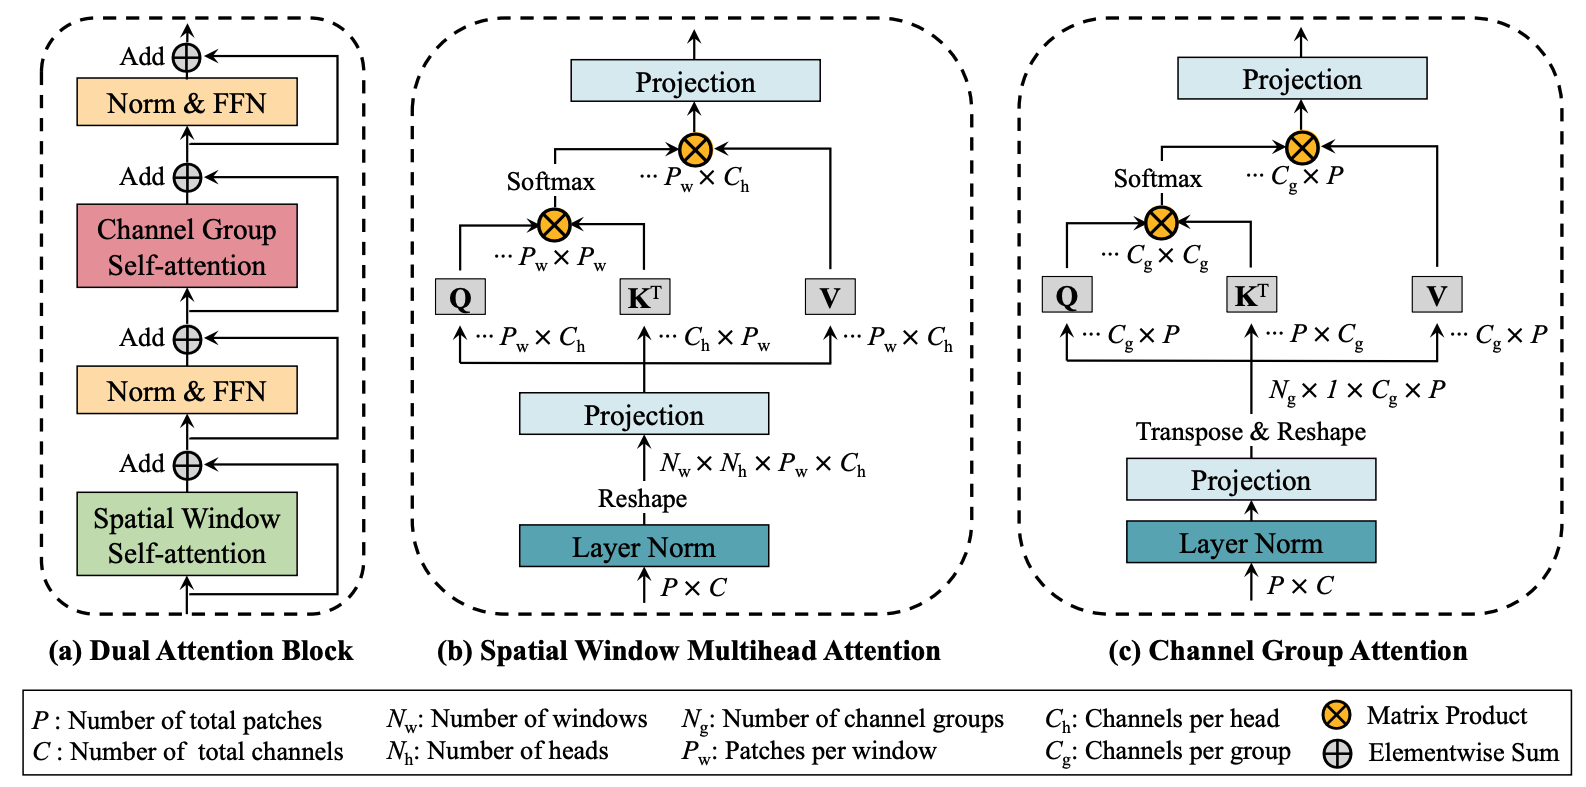
In this work, we introduce Dual Attention Vision Transformers (DaViT), a simple yet effective vision transformer architecture that is able to capture global context while maintaining computational efficiency. We propose approaching the problem from an orthogonal angle: exploiting self-attention mechanisms with both "spatial tokens" and "channel tokens". (i) Since each channel token contains an abstract representation of the entire image, the channel attention naturally captures global interactions and representations by taking all spatial positions into account when computing attention scores between channels. (ii) The spatial attention refines the local representations by performing fine-grained interactions across spatial locations, which in turn helps the global information modeling in channel attention.
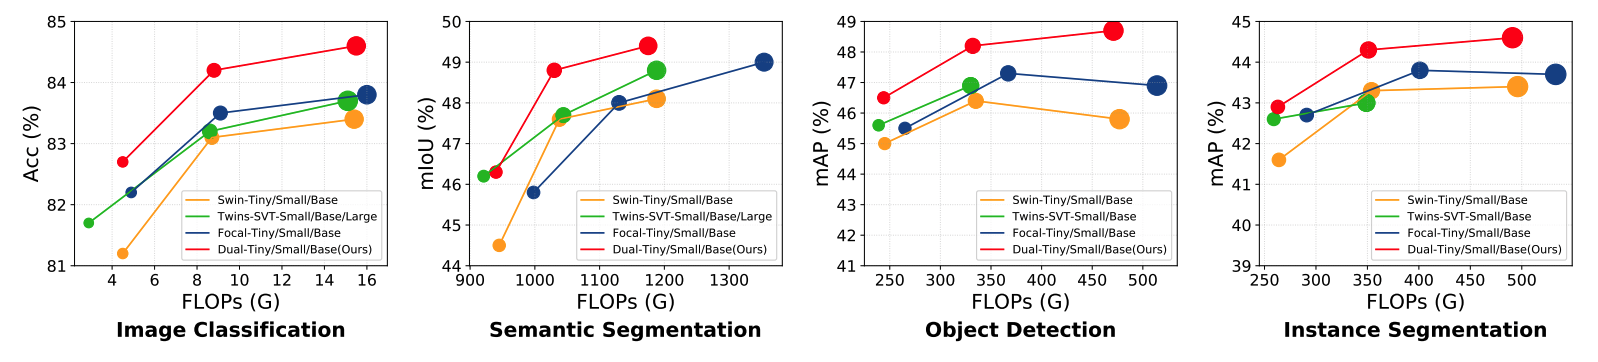
Experiments show our DaViT achieves state-of-the-art performance on four different tasks with efficient computations. Without extra data, DaViT-Tiny, DaViT-Small, and DaViT-Base achieve 82.8%, 84.2%, and 84.6% top-1 accuracy on ImageNet-1K with 28.3M, 49.7M, and 87.9M parameters, respectively. When we further scale up DaViT with 1.5B weakly supervised image and text pairs, DaViT-Gaint reaches 90.4% top-1 accuracy on ImageNet-1K.
Getting Started
Python3, PyTorch>=1.8.0, torchvision>=0.7.0 are required for the current codebase.
# An example on CUDA 10.2
pip install torch===1.9.0+cu102 torchvision===0.10.0+cu102 torchaudio===0.9.0 -f https://download.pytorch.org/whl/torch_stable.html
pip install thop pyyaml fvcore pillow==8.3.2
Image Classification
-
Prepare the ImageNet dataset in the timm format (DATASET_DIR/train/ DATASET_DIR/val/).
-
Set the following ENV variable:
$MASTER_ADDR: IP address of the node 0 (Not required if you have only one node (machine)) $MASTER_PORT: Port used for initializing distributed environment $NODE_RANK: Index of the node $N_NODES: Number of nodes $NPROC_PER_NODE: Number of GPUs (NOTE: should exactly match local GPU numbers with `CUDA_VISIBLE_DEVICES`) -
Training:
- Example1 (One machine with 8 GPUs):
python -u -m torch.distributed.launch --nproc_per_node=8 \ --nnodes=1 --node_rank=0 --master_port=12345 \ train.py DATASET_DIR --model DaViT_tiny --batch-size 128 --lr 1e-3 \ --native-amp --clip-grad 1.0 --output OUTPUT_DIR- Example2 (Two machines, each has 8 GPUs):
# Node 1: (IP: 192.168.1.1, and has a free port: 12345) python -u -m torch.distributed.launch --nproc_per_node=8 --nnodes=2 --node_rank=0 --master_addr="192.168.1.1" --master_port=12345 train.py DATASET_DIR --model DaViT_tiny --batch-size 128 --lr 2e-3 \ --native-amp --clip-grad 1.0 --output OUTPUT_DIR # Node 2: python -u -m torch.distributed.launch --nproc_per_node=8 --nnodes=2 --node_rank=1 --master_addr="192.168.1.1" --master_port=12345 train.py DATASET_DIR --model DaViT_tiny --batch-size 128 --lr 2e-3 \ --native-amp --clip-grad 1.0 --output OUTPUT_DIR -
Validation:
CUDA_VISIBLE_DEVICES=0 python -u validate.py DATASET_DIR --model DaViT_tiny --batch-size 128  \
--native-amp  --checkpoint TRAINED_MODEL_PATH  # --img-size 224 --no-test-pool
Object Detection and Instance Segmentation
-
cd mmdet& install mmcv/mmdet# An example on CUDA 10.2 and pytorch 1.9 pip install mmcv-full==1.3.0 -f https://download.openmmlab.com/mmcv/dist/cu102/torch1.9.0/index.html pip install -r requirements/build.txt pip install -v -e . # or "python setup.py develop" -
mkdir data& Prepare the dataset in data/coco/ (Format: ROOT/mmdet/data/coco/annotations, train2017, val2017) -
Finetune on COCO
bash tools/dist_train.sh configs/davit_retinanet_1x_coco.py 8 \
--cfg-options model.pretrained=PRETRAINED_MODEL_PATH
Semantic Segmentation
-
cd mmseg& install mmcv/mmseg# An example on CUDA 10.2 and pytorch 1.9 pip install mmcv-full==1.3.0 -f https://download.openmmlab.com/mmcv/dist/cu102/torch1.9.0/index.html pip install -e . -
mkdir data& Prepare the dataset in data/ade/ (Format: ROOT/mmseg/data/ADEChallengeData2016) -
Finetune on ADE
bash tools/dist_train.sh configs/upernet_davit_512x512_160k_ade20k.py 8 \ --options model.pretrained=PRETRAINED_MODEL_PATH -
Multi-scale Testing
bash tools/dist_test.sh configs/upernet_davit_512x512_160k_ade20k.py \
TRAINED_MODEL_PATH 8 --aug-test --eval mIoU
Benchmarking
Image Classification on ImageNet-1K
| Model | Pretrain | Resolution | acc@1 | acc@5 | #params | FLOPs | Checkpoint | Log |
|---|---|---|---|---|---|---|---|---|
| DaViT-T | IN-1K | 224 | 82.8 | 96.2 | 28.3M | 4.5G | download | log |
| DaViT-S | IN-1K | 224 | 84.2 | 96.9 | 49.7M | 8.8G | download | log |
| DaViT-B | IN-1K | 224 | 84.6 | 96.9 | 87.9M | 15.5G | download | log |
Object Detection and Instance Segmentation on COCO
Mask R-CNN
| Backbone | Pretrain | Lr Schd | #params | FLOPs | box mAP | mask mAP | Checkpoint | Log |
|---|---|---|---|---|---|---|---|---|
| DaViT-T | ImageNet-1K | 1x | 47.8M | 263G | 45.0 | 41.1 | download | log |
| DaViT-T | ImageNet-1K | 3x | 47.8M | 263G | 47.4 | 42.9 | download | log |
| DaViT-S | ImageNet-1K | 1x | 69.2M | 351G | 47.7 | 42.9 | download | log |
| DaViT-S | ImageNet-1K | 3x | 69.2M | 351G | 49.5 | 44.3 | download | log |
| DaViT-B | ImageNet-1K | 1x | 107.3M | 491G | 48.2 | 43.3 | download | log |
| DaViT-B | ImageNet-1K | 3x | 107.3M | 491G | 49.9 | 44.6 | download | log |
RetinaNet
| Backbone | Pretrain | Lr Schd | #params | FLOPs | box mAP | Checkpoint | Log |
|---|---|---|---|---|---|---|---|
| DaViT-T | ImageNet-1K | 1x | 38.5M | 244G | 44.0 | download | log |
| DaViT-T | ImageNet-1K | 3x | 38.5M | 244G | 46.5 | download | log |
| DaViT-S | ImageNet-1K | 1x | 59.9M | 332G | 46.0 | download | log |
| DaViT-S | ImageNet-1K | 3x | 59.9M | 332G | 48.2 | download | log |
| DaViT-B | ImageNet-1K | 1x | 98.5M | 471G | 46.7 | download | log |
| DaViT-B | ImageNet-1K | 3x | 98.5M | 471G | 48.7 | download | log |
Semantic Segmentation on ADE20K
| Backbone | Pretrain | Method | Resolution | Iters | #params | FLOPs | mIoU | Checkpoint | Log |
|---|---|---|---|---|---|---|---|---|---|
| DaViT-T | ImageNet-1K | UPerNet | 512x512 | 160k | 60M | 940G | 46.3 | download | log |
| DaViT-S | ImageNet-1K | UPerNet | 512x512 | 160k | 81M | 1030G | 48.8 | download | log |
| DaViT-B | ImageNet-1K | UPerNet | 512x512 | 160k | 121M | 1175G | 49.4 | download | log |
Citation
If you find this repo useful to your project, please consider citing it with the following bib:
@inproceedings{ding2022davit,
  title={Davit: Dual attention vision transformers},
  author={Ding, Mingyu and Xiao, Bin and Codella, Noel and Luo, Ping and Wang, Jingdong and Yuan, Lu},
  booktitle={Computer Vision--ECCV 2022: 17th European Conference, Tel Aviv, Israel, October 23--27, 2022, Proceedings, Part XXIV},
  pages={74--92},
  year={2022},
  organization={Springer}
}
Acknowledgement
Our codebase is built based on timm, MMDetection, MMSegmentation. We thank the authors for the nicely organized code!
Contributors

6 commits
Similar repos


Languages
Python
77.7%
Jupyter Notebook
22.2%
[ECCV 2022]Code for paper "DaViT: Dual Attention Vision Transformer"
Python
379
6 commits
updated Feb 13, 2024
README
DaViT: Dual Attention Vision Transformer (ECCV 2022)
This repo contains the official detection and segmentation implementation of paper "DaViT: Dual Attention Vision Transformer (ECCV 2022)", by Mingyu Ding, Bin Xiao, Noel Codella, Ping Luo, Jingdong Wang, and Lu Yuan. See Introduction.md for an introduction.
The large models for image classification will be released in https://github.com/microsoft/DaViT.
Introduction
In this work, we introduce Dual Attention Vision Transformers (DaViT), a simple yet effective vision transformer architecture that is able to capture global context while maintaining computational efficiency. We propose approaching the problem from an orthogonal angle: exploiting self-attention mechanisms with both "spatial tokens" and "channel tokens". (i) Since each channel token contains an abstract representation of the entire image, the channel attention naturally captures global interactions and representations by taking all spatial positions into account when computing attention scores between channels. (ii) The spatial attention refines the local representations by performing fine-grained interactions across spatial locations, which in turn helps the global information modeling in channel attention.
Experiments show our DaViT achieves state-of-the-art performance on four different tasks with efficient computations. Without extra data, DaViT-Tiny, DaViT-Small, and DaViT-Base achieve 82.8%, 84.2%, and 84.6% top-1 accuracy on ImageNet-1K with 28.3M, 49.7M, and 87.9M parameters, respectively. When we further scale up DaViT with 1.5B weakly supervised image and text pairs, DaViT-Gaint reaches 90.4% top-1 accuracy on ImageNet-1K.
Getting Started
Python3, PyTorch>=1.8.0, torchvision>=0.7.0 are required for the current codebase.
# An example on CUDA 10.2
pip install torch===1.9.0+cu102 torchvision===0.10.0+cu102 torchaudio===0.9.0 -f https://download.pytorch.org/whl/torch_stable.html
pip install thop pyyaml fvcore pillow==8.3.2
Image Classification
-
Prepare the ImageNet dataset in the timm format (DATASET_DIR/train/ DATASET_DIR/val/).
-
Set the following ENV variable:
$MASTER_ADDR: IP address of the node 0 (Not required if you have only one node (machine)) $MASTER_PORT: Port used for initializing distributed environment $NODE_RANK: Index of the node $N_NODES: Number of nodes $NPROC_PER_NODE: Number of GPUs (NOTE: should exactly match local GPU numbers with `CUDA_VISIBLE_DEVICES`) -
Training:
- Example1 (One machine with 8 GPUs):
python -u -m torch.distributed.launch --nproc_per_node=8 \ --nnodes=1 --node_rank=0 --master_port=12345 \ train.py DATASET_DIR --model DaViT_tiny --batch-size 128 --lr 1e-3 \ --native-amp --clip-grad 1.0 --output OUTPUT_DIR- Example2 (Two machines, each has 8 GPUs):
# Node 1: (IP: 192.168.1.1, and has a free port: 12345) python -u -m torch.distributed.launch --nproc_per_node=8 --nnodes=2 --node_rank=0 --master_addr="192.168.1.1" --master_port=12345 train.py DATASET_DIR --model DaViT_tiny --batch-size 128 --lr 2e-3 \ --native-amp --clip-grad 1.0 --output OUTPUT_DIR # Node 2: python -u -m torch.distributed.launch --nproc_per_node=8 --nnodes=2 --node_rank=1 --master_addr="192.168.1.1" --master_port=12345 train.py DATASET_DIR --model DaViT_tiny --batch-size 128 --lr 2e-3 \ --native-amp --clip-grad 1.0 --output OUTPUT_DIR -
Validation:
CUDA_VISIBLE_DEVICES=0 python -u validate.py DATASET_DIR --model DaViT_tiny --batch-size 128  \
--native-amp  --checkpoint TRAINED_MODEL_PATH  # --img-size 224 --no-test-pool
Object Detection and Instance Segmentation
-
cd mmdet& install mmcv/mmdet# An example on CUDA 10.2 and pytorch 1.9 pip install mmcv-full==1.3.0 -f https://download.openmmlab.com/mmcv/dist/cu102/torch1.9.0/index.html pip install -r requirements/build.txt pip install -v -e . # or "python setup.py develop" -
mkdir data& Prepare the dataset in data/coco/ (Format: ROOT/mmdet/data/coco/annotations, train2017, val2017) -
Finetune on COCO
bash tools/dist_train.sh configs/davit_retinanet_1x_coco.py 8 \
--cfg-options model.pretrained=PRETRAINED_MODEL_PATH
Semantic Segmentation
-
cd mmseg& install mmcv/mmseg# An example on CUDA 10.2 and pytorch 1.9 pip install mmcv-full==1.3.0 -f https://download.openmmlab.com/mmcv/dist/cu102/torch1.9.0/index.html pip install -e . -
mkdir data& Prepare the dataset in data/ade/ (Format: ROOT/mmseg/data/ADEChallengeData2016) -
Finetune on ADE
bash tools/dist_train.sh configs/upernet_davit_512x512_160k_ade20k.py 8 \ --options model.pretrained=PRETRAINED_MODEL_PATH -
Multi-scale Testing
bash tools/dist_test.sh configs/upernet_davit_512x512_160k_ade20k.py \
TRAINED_MODEL_PATH 8 --aug-test --eval mIoU
Benchmarking
Image Classification on ImageNet-1K
| Model | Pretrain | Resolution | acc@1 | acc@5 | #params | FLOPs | Checkpoint | Log |
|---|---|---|---|---|---|---|---|---|
| DaViT-T | IN-1K | 224 | 82.8 | 96.2 | 28.3M | 4.5G | download | log |
| DaViT-S | IN-1K | 224 | 84.2 | 96.9 | 49.7M | 8.8G | download | log |
| DaViT-B | IN-1K | 224 | 84.6 | 96.9 | 87.9M | 15.5G | download | log |
Object Detection and Instance Segmentation on COCO
Mask R-CNN
| Backbone | Pretrain | Lr Schd | #params | FLOPs | box mAP | mask mAP | Checkpoint | Log |
|---|---|---|---|---|---|---|---|---|
| DaViT-T | ImageNet-1K | 1x | 47.8M | 263G | 45.0 | 41.1 | download | log |
| DaViT-T | ImageNet-1K | 3x | 47.8M | 263G | 47.4 | 42.9 | download | log |
| DaViT-S | ImageNet-1K | 1x | 69.2M | 351G | 47.7 | 42.9 | download | log |
| DaViT-S | ImageNet-1K | 3x | 69.2M | 351G | 49.5 | 44.3 | download | log |
| DaViT-B | ImageNet-1K | 1x | 107.3M | 491G | 48.2 | 43.3 | download | log |
| DaViT-B | ImageNet-1K | 3x | 107.3M | 491G | 49.9 | 44.6 | download | log |
RetinaNet
| Backbone | Pretrain | Lr Schd | #params | FLOPs | box mAP | Checkpoint | Log |
|---|---|---|---|---|---|---|---|
| DaViT-T | ImageNet-1K | 1x | 38.5M | 244G | 44.0 | download | log |
| DaViT-T | ImageNet-1K | 3x | 38.5M | 244G | 46.5 | download | log |
| DaViT-S | ImageNet-1K | 1x | 59.9M | 332G | 46.0 | download | log |
| DaViT-S | ImageNet-1K | 3x | 59.9M | 332G | 48.2 | download | log |
| DaViT-B | ImageNet-1K | 1x | 98.5M | 471G | 46.7 | download | log |
| DaViT-B | ImageNet-1K | 3x | 98.5M | 471G | 48.7 | download | log |
Semantic Segmentation on ADE20K
| Backbone | Pretrain | Method | Resolution | Iters | #params | FLOPs | mIoU | Checkpoint | Log |
|---|---|---|---|---|---|---|---|---|---|
| DaViT-T | ImageNet-1K | UPerNet | 512x512 | 160k | 60M | 940G | 46.3 | download | log |
| DaViT-S | ImageNet-1K | UPerNet | 512x512 | 160k | 81M | 1030G | 48.8 | download | log |
| DaViT-B | ImageNet-1K | UPerNet | 512x512 | 160k | 121M | 1175G | 49.4 | download | log |
Citation
If you find this repo useful to your project, please consider citing it with the following bib:
@inproceedings{ding2022davit,
  title={Davit: Dual attention vision transformers},
  author={Ding, Mingyu and Xiao, Bin and Codella, Noel and Luo, Ping and Wang, Jingdong and Yuan, Lu},
  booktitle={Computer Vision--ECCV 2022: 17th European Conference, Tel Aviv, Israel, October 23--27, 2022, Proceedings, Part XXIV},
  pages={74--92},
  year={2022},
  organization={Springer}
}
Acknowledgement
Our codebase is built based on timm, MMDetection, MMSegmentation. We thank the authors for the nicely organized code!
Similar repos
Contributors
6 commits
Languages
Python
77.7%
Jupyter Notebook
22.2%