
[ICCV 2025] Streaming VideoLLMs for Real-time Procedural Video Understanding
Python
23
15 commits
updated Oct 26, 2025
README
ProVideLLM: Streaming VideoLLMs for Real-time Procedural Video Understanding
This repository provides official implementation of:
Streaming VideoLLMs for Real-time Procedural Video Understanding (ICCV 2025)
Dibyadip Chatterjee, Edoardo Remelli, Yale Song, Bugra Tekin, Abhay Mittal, Bharat Bhatnagar, Necati Cihan Camgöz, Shreyas Hampali, Eric Sauser, Shugao Ma, Angela Yao, and Fadime Sener.

[!NOTE] Release (Oct 2025):
This release upgrades the visual encoder to SigLIP 2 which provides stronger language alignment while preserving patch-level objectness through dense supervision during training. We also pretrain DETR-QFormer on the larger EgoClip dataset instead of EPIC-KITCHENS, further improving accuracy and advancing SOTA on EgoExo4D and COIN.
To-Do
- Release verbalize & interleave code for streaming per-frame inference
- Release online step detection training and evaluation for Ego4D-Goalstep
- Release DETR-QFormer Stage-1 pretrained checkpoint
- Released training and evaluation for EgoExo4D and COIN
- Released DETR-QFormer Stage-1 pretraining code on EgoClip
Overview
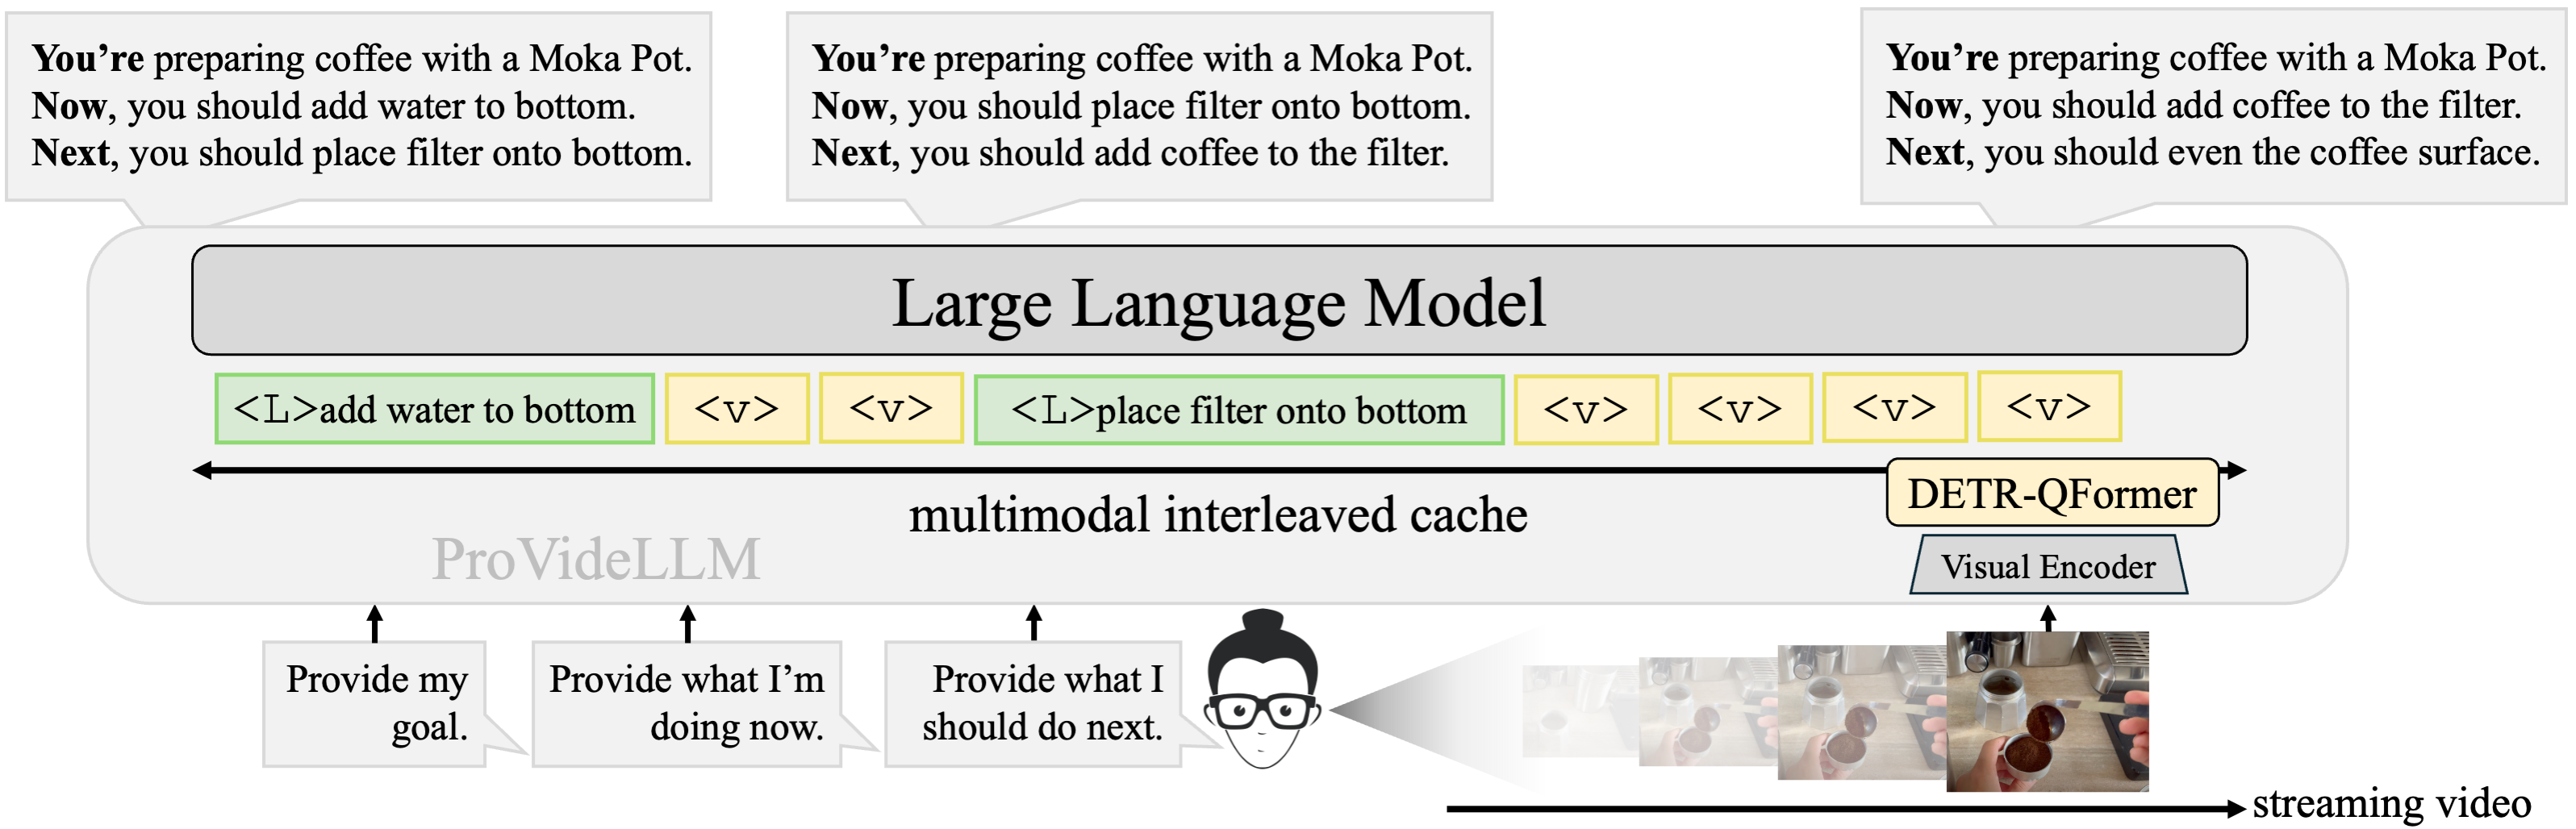
ProVideLLM is a streaming VideoLLM for real-time procedural video understanding. It interleaves verbalized long-term text tokens and DETR-QFormer encoded short-term visual tokens within a multimodal cache, enabling:
- sub-linear memory and compute scaling with video length
- 22× fewer tokens compared to existing streaming/online VideoLLMs for representing an hour long video
- 🏆 state-of-the-art on EgoExo4D Keystep Recognition (#1 in Leaderboard)
- 🏆 state-of-the-art on COIN dataset across 5 tasks
Model Variants
-
ProVideLLM-1B/5 — A lightweight streaming model optimized for real-time tasks. Achieves >10 FPS per-frame inference and >25 FPS streaming narration, running on a single GPU with ~2 GB memory.
-
ProVideLLM-8B/11 — A high-performing streaming model designed for fine-grained online video understanding. Delivers state-of-the-art accuracy on procedural video benchmarks.
State-of-the-art results
Enhanced release with siglip2-so400m as the vision encoder and Stage-1 pretraining on EgoClip, improving fine-grained recognition across benchmarks.
EgoExo4D — Fine-grained Keystep Recognition
| Model | Val. Acc. (%) | Test Acc. (%) |
|---|---|---|
| ProVideLLM-8B/11 | 55.20 | 61.98 |
COIN — Procedural Understanding (Top-1 Acc %)
| Model | Step | Task | Next | Proc. | Proc.+ |
|---|---|---|---|---|---|
| ProVideLLM-8B/11 | 73.0 | 95.0 | 54.2 | 52.8 | 56.1 |
Requirements
The following setup has been tested on Python 3.12 with CUDA 12.4.
conda create -n providellm python=3.12
conda activate providellm

pip install numpy pandas tqdm matplotlib scipy prettytable datetime

pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 xformers --index-url https://download.pytorch.org/whl/cu124
pip install transformers==4.48.0 deepspeed==0.14.4 ninja accelerate peft editdistance Levenshtein wandb moviepy submitit timm opencv-python
pip install flash-attn --no-build-isolation
We use torchcodec for consistent video decoding across datasets:
conda install ffmpeg==7.1.1 -c conda-forge
pip install torchcodec==0.1 --index-url=https://download.pytorch.org/whl/cu124
Citation
If you find our work useful, please cite:
@article{chatterjee2025memory,
  title={Memory-efficient Streaming VideoLLMs for Real-time Procedural Video Understanding},
  author={Chatterjee, Dibyadip and Remelli, Edoardo and Song, Yale and Tekin, Bugra and Mittal, Abhay and Bhatnagar, Bharat and Camg{\~A}{\c{k}}z, Necati Cihan and Hampali, Shreyas and Sauser, Eric and Ma, Shugao and others},
  journal={arXiv preprint arXiv:2504.13915},
  year={2025}
}
Acknowledgements
Our work builds upon the excellent open-source efforts of VideoLLM-Online and LLaVA. We also thank Helping-Hands for providing pre-extracted hand–object bounding boxes for EgoClip.
Contributors

15 commits
Similar repos


Languages
Python
95.5%
Shell
4.5%
[ICCV 2025] Streaming VideoLLMs for Real-time Procedural Video Understanding
Python
23
15 commits
updated Oct 26, 2025
README
ProVideLLM: Streaming VideoLLMs for Real-time Procedural Video Understanding
This repository provides official implementation of:
Streaming VideoLLMs for Real-time Procedural Video Understanding (ICCV 2025)
Dibyadip Chatterjee, Edoardo Remelli, Yale Song, Bugra Tekin, Abhay Mittal, Bharat Bhatnagar, Necati Cihan Camgöz, Shreyas Hampali, Eric Sauser, Shugao Ma, Angela Yao, and Fadime Sener.
[!NOTE] Release (Oct 2025):
This release upgrades the visual encoder to SigLIP 2 which provides stronger language alignment while preserving patch-level objectness through dense supervision during training. We also pretrain DETR-QFormer on the larger EgoClip dataset instead of EPIC-KITCHENS, further improving accuracy and advancing SOTA on EgoExo4D and COIN.
To-Do
- Release verbalize & interleave code for streaming per-frame inference
- Release online step detection training and evaluation for Ego4D-Goalstep
- Release DETR-QFormer Stage-1 pretrained checkpoint
- Released training and evaluation for EgoExo4D and COIN
- Released DETR-QFormer Stage-1 pretraining code on EgoClip
Overview
ProVideLLM is a streaming VideoLLM for real-time procedural video understanding. It interleaves verbalized long-term text tokens and DETR-QFormer encoded short-term visual tokens within a multimodal cache, enabling:
- sub-linear memory and compute scaling with video length
- 22× fewer tokens compared to existing streaming/online VideoLLMs for representing an hour long video
- 🏆 state-of-the-art on EgoExo4D Keystep Recognition (#1 in Leaderboard)
- 🏆 state-of-the-art on COIN dataset across 5 tasks
Model Variants
-
ProVideLLM-1B/5 — A lightweight streaming model optimized for real-time tasks. Achieves >10 FPS per-frame inference and >25 FPS streaming narration, running on a single GPU with ~2 GB memory.
-
ProVideLLM-8B/11 — A high-performing streaming model designed for fine-grained online video understanding. Delivers state-of-the-art accuracy on procedural video benchmarks.
State-of-the-art results
Enhanced release with siglip2-so400m as the vision encoder and Stage-1 pretraining on EgoClip, improving fine-grained recognition across benchmarks.
EgoExo4D — Fine-grained Keystep Recognition
| Model | Val. Acc. (%) | Test Acc. (%) |
|---|---|---|
| ProVideLLM-8B/11 | 55.20 | 61.98 |
COIN — Procedural Understanding (Top-1 Acc %)
| Model | Step | Task | Next | Proc. | Proc.+ |
|---|---|---|---|---|---|
| ProVideLLM-8B/11 | 73.0 | 95.0 | 54.2 | 52.8 | 56.1 |
Requirements
The following setup has been tested on Python 3.12 with CUDA 12.4.
conda create -n providellm python=3.12
conda activate providellm

pip install numpy pandas tqdm matplotlib scipy prettytable datetime

pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 xformers --index-url https://download.pytorch.org/whl/cu124
pip install transformers==4.48.0 deepspeed==0.14.4 ninja accelerate peft editdistance Levenshtein wandb moviepy submitit timm opencv-python
pip install flash-attn --no-build-isolation
We use torchcodec for consistent video decoding across datasets:
conda install ffmpeg==7.1.1 -c conda-forge
pip install torchcodec==0.1 --index-url=https://download.pytorch.org/whl/cu124
Citation
If you find our work useful, please cite:
@article{chatterjee2025memory,
  title={Memory-efficient Streaming VideoLLMs for Real-time Procedural Video Understanding},
  author={Chatterjee, Dibyadip and Remelli, Edoardo and Song, Yale and Tekin, Bugra and Mittal, Abhay and Bhatnagar, Bharat and Camg{\~A}{\c{k}}z, Necati Cihan and Hampali, Shreyas and Sauser, Eric and Ma, Shugao and others},
  journal={arXiv preprint arXiv:2504.13915},
  year={2025}
}
Acknowledgements
Our work builds upon the excellent open-source efforts of VideoLLM-Online and LLaVA. We also thank Helping-Hands for providing pre-extracted hand–object bounding boxes for EgoClip.
Similar repos
Contributors
15 commits
Languages
Python
95.5%
Shell
4.5%