

🚀 Official implementation of DrugCMF, accepted at AAAI 2026 🎉
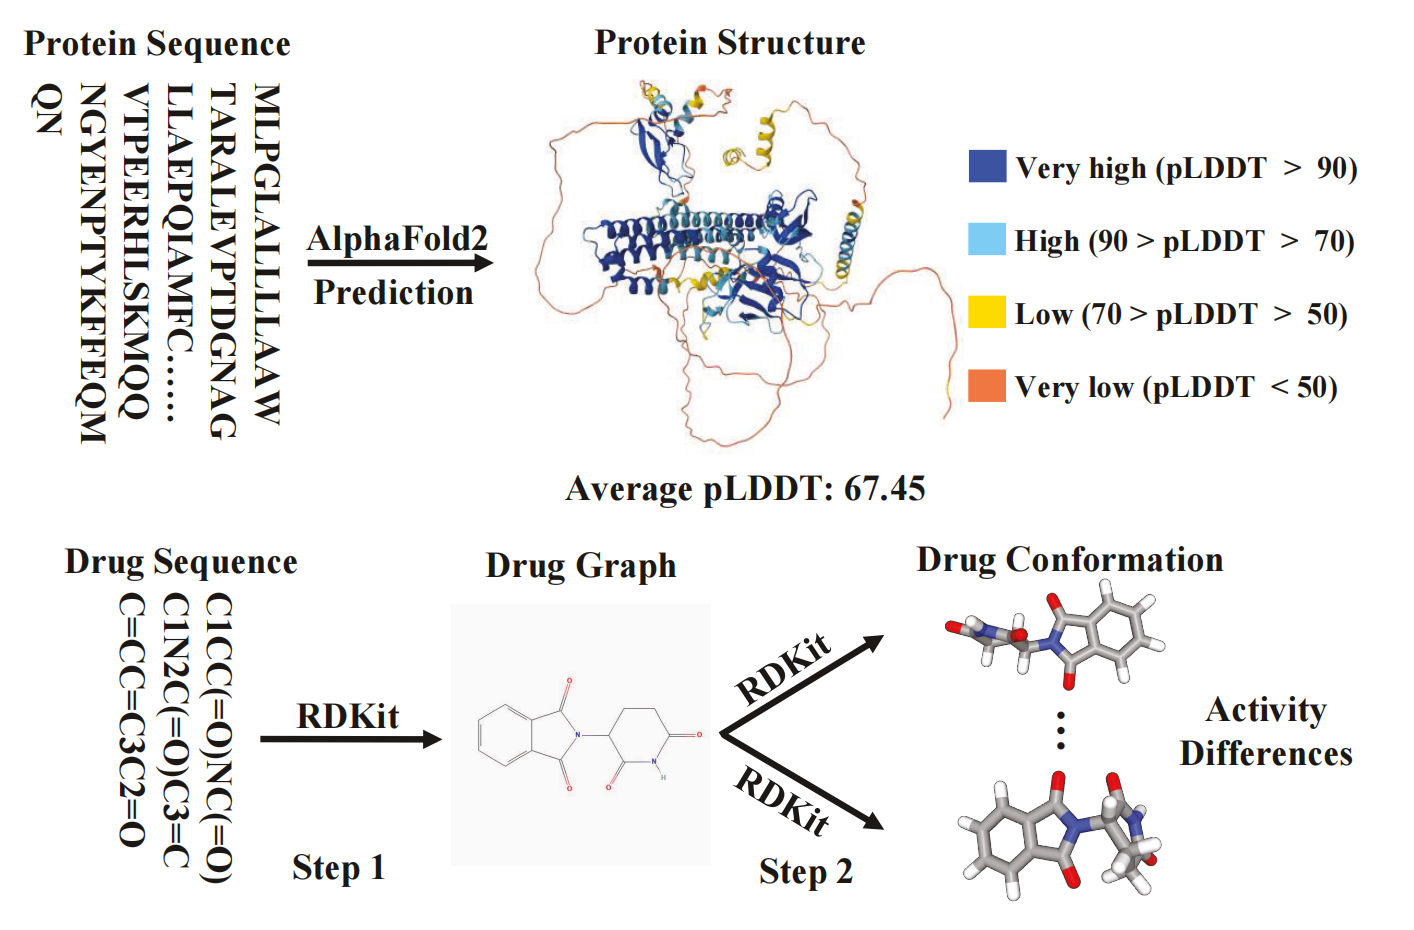
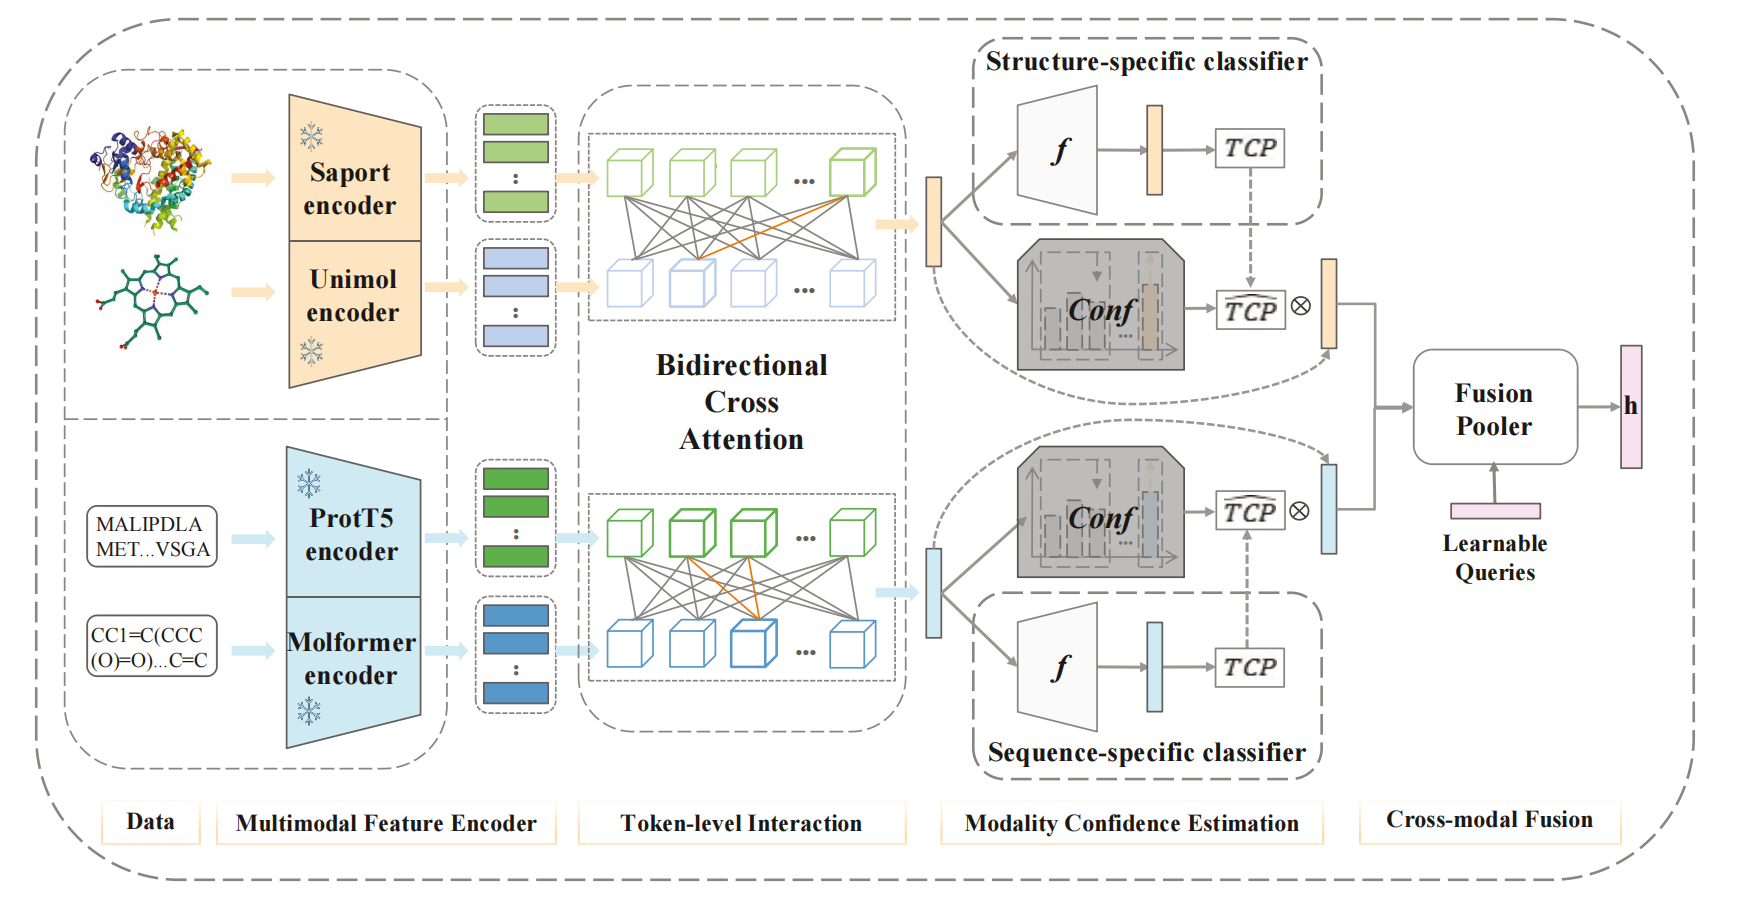
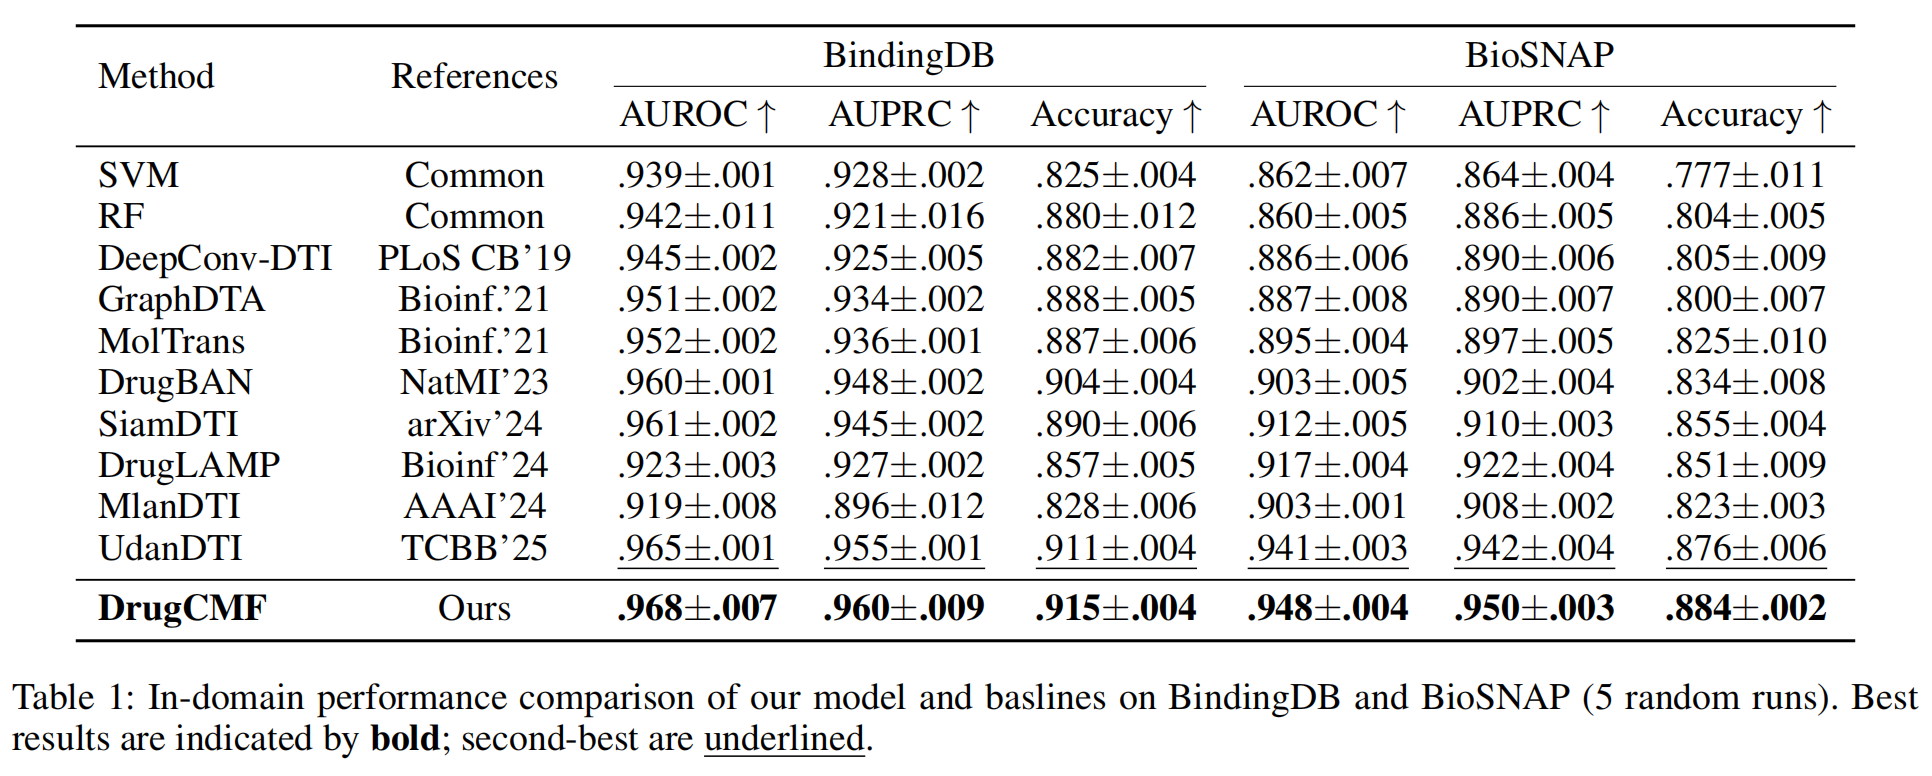
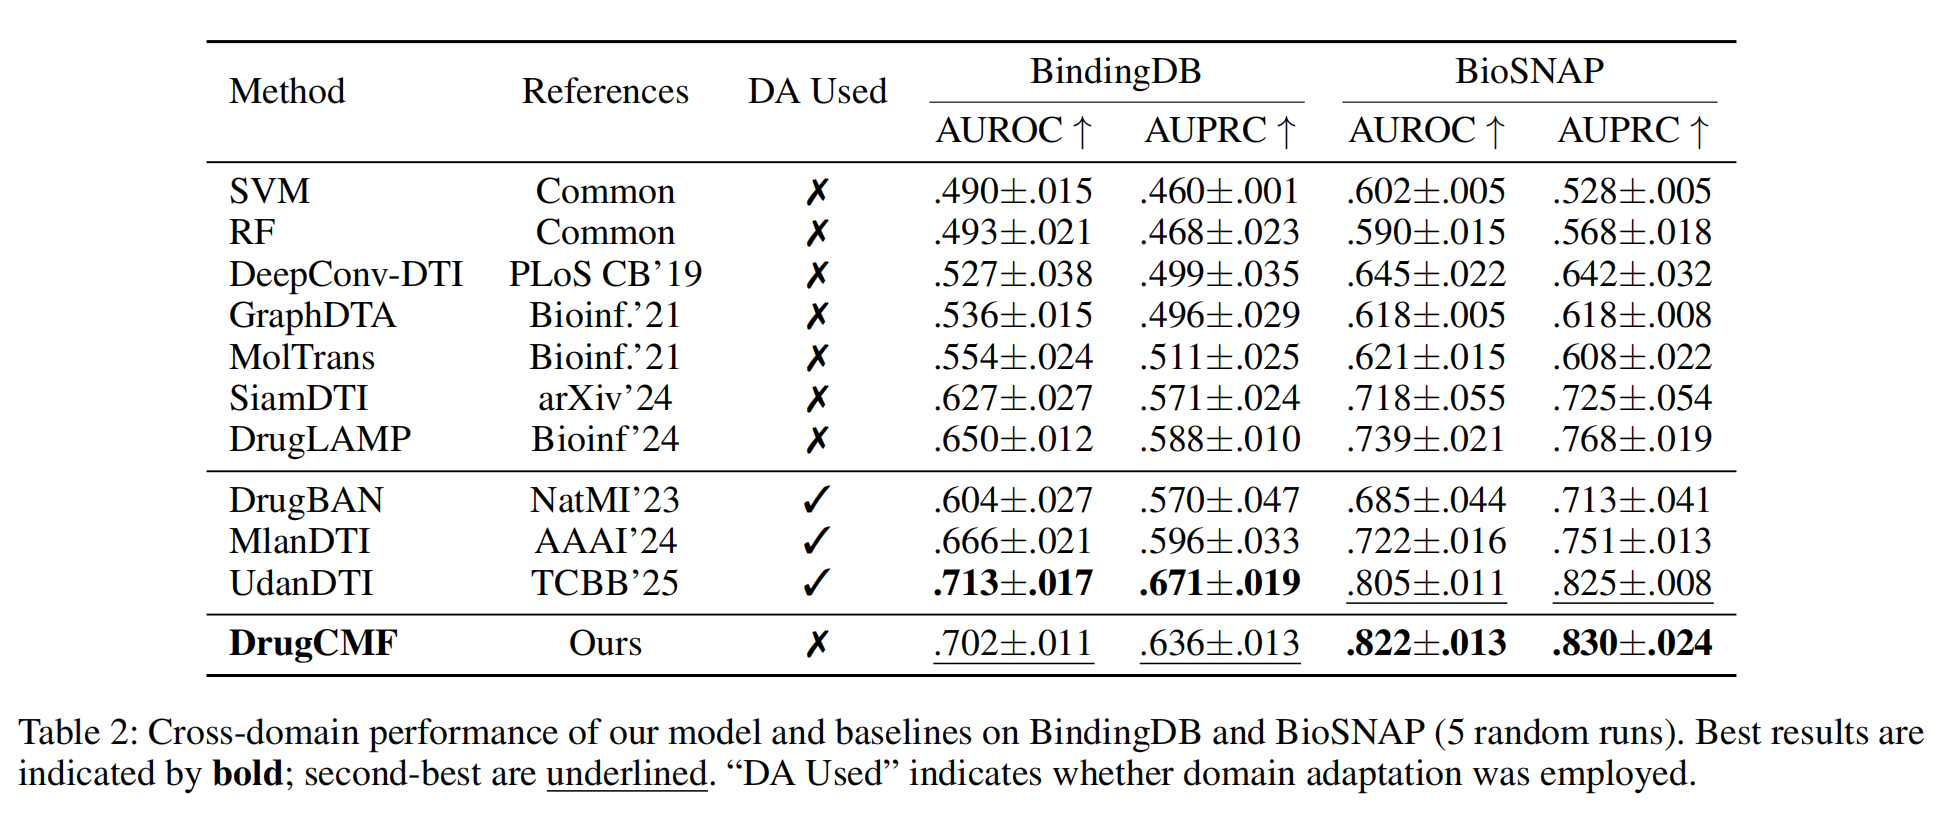
💊 Drug-target interaction (DTI) prediction is a fundamental task in drug discovery. 1D sequences 🧬 and 3D structures 🏗️ capture complementary information but vary in reliability across different drug–protein pairs 🧑🔬. DrugCMF addresses this modality reliability gap through a confidence-aware multimodal fusion 🔗 framework.
Datasets can be downloaded from:
| Dataset | #Pairs | Description |
|---|---|---|
| 🧑 Human | ~6.7K | Curated human drug-target interactions |
| 🔬 BindingDB | ~49.2K | Large-scale binding affinity database (49,189 pairs) |
| 🌐 BioSNAP | ~27.4K | Biomedical network interactions (27,380 pairs) |
✂️ Splits:
Each split CSV contains 6 columns (SMILES, Protein, Y, Structure, SMILES_id, Protein_id). Cluster splits additionally include drug_cluster and target_cluster columns.
Model weights are downloaded automatically from HuggingFace 🤗:
| Model | HuggingFace ID | Dim |
|---|---|---|
| 🧬 ProtT5 | Rostlab/prot_t5_xl_half_uniref50-enc | 1024 |
| 🔬 SaProt | Westlake-R/SaProt_650M_AF2 | 1280 |
| 💊 MolFormer | ibm/MoLFormer-XL-both-10p1024 | 768 |
| 🧪 UniMol | dptech/Uni-Mol-Models | 512 |
Generate all four embeddings offline before training 🏗️:
python preprocess/get_embedding.py \
    --dataset bindingdb \
    --data_path datasets/bindingdb/processed_full.csv \
    --save_path embeddings/bindingdb \
    --device cuda:0 \
    --seed 42
Or generate for all three datasets at once ⚡:
bash preprocess/run_embedding.sh
This produces .pt files in embeddings/{dataset}/{type}_embeddings/ containing seq_emb and mask tensors 📁.
All dependencies are listed in requirements.txt 📄. Key packages:
| Package | Version |
|---|---|
| 🐍 Python | 3.10+ |
| 🔥 PyTorch | 2.6.0 |
| 🤗 Transformers | 4.47.0 |
| 🧪 RDKit | 2024.3.2 |
| 📈 scikit-learn | 1.5.2 |
| 🐼 pandas | 2.2.3 |
| ⚙️ yacs | 0.1.8 |
Train on the Human dataset with a cold-start split:
python main.py --dataset human --split cold --device cuda:0
Run with multiple random seeds 🌱:
bash train.sh
├── main.py                  # Training & evaluation entry point
├── model.py                 # DrugCMF model architecture
├── modules.py               # Building blocks (ModalityInteractionLearner, Classifier, MultiModalAttentionalPooler)
├── attention.py             # BidirectionalCrossAttention, AttentionalPooler
├── dataloader.py            # DTIDataset & DataLoader (loads pre-computed embeddings)
├── train_util.py            # Training & evaluation loops (AdamW, ReduceLROnPlateau, early stopping)
├── utils.py                 # Reproducibility seed, collate function, checkpoint I/O, logger
├── requirements.txt         # Full Python dependencies
├── train.sh                 # Multi-seed training script (11 seeds)
│
├── preprocess/              # Offline embedding generation
│   ├── get_embedding.py     # Generate all 4 embeddings for a dataset
│   └── run_embedding.sh     # SLURM batch script for all datasets
│
├── unimol/                  # UniMol implementation (based on DP Technology)
│   ├── unimol.py
│   ├── unimol_utils.py
│   └── transformers.py
│
└── datasets/                # Preprocessed CSV splits
    ├── README.md
    ├── human/
    │   ├── processed_full.csv
    │   ├── cold/   {train,val,test}.csv
    │   └── random/ {train,val,test}.csv
    ├── bindingdb/
    │   ├── processed_full.csv
    │   ├── random/ ...csv
    │   └── cluster/ {source_train,target_test}.csv
    └── biosnap/
        ├── processed_full.csv
        ├── random/ ...csv
        └── cluster/ {source_train,target_test}.csv
If you find DrugCMF useful, please cite our paper 🙏:
@inproceedings{yang2026bridging,
  title={Bridging the Modality Reliability Gap in Drug-Target Interaction Prediction via a Confidence-aware Multimodal Fusion Framework},
  author={Yang, Jie and Zhang, Junxiong and Qian, Kun and Yang, Qingyu and Li, Weikai and Cheng, Zhen},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={40},
  number={32},
  pages={27529--27537},
  year={2026}
}
unimol/: CC BY-NC 4.0 — Creative Commons Attribution-NonCommercial 4.0 International. Sharing and adaptation for non-commercial purposes only, with attribution.unimol/ (from DP Technology / Uni-Core): MIT License, as originally licensed.
🚀 Official implementation of DrugCMF, accepted at AAAI 2026 🎉
💊 Drug-target interaction (DTI) prediction is a fundamental task in drug discovery. 1D sequences 🧬 and 3D structures 🏗️ capture complementary information but vary in reliability across different drug–protein pairs 🧑🔬. DrugCMF addresses this modality reliability gap through a confidence-aware multimodal fusion 🔗 framework.
Datasets can be downloaded from:
| Dataset | #Pairs | Description |
|---|---|---|
| 🧑 Human | ~6.7K | Curated human drug-target interactions |
| 🔬 BindingDB | ~49.2K | Large-scale binding affinity database (49,189 pairs) |
| 🌐 BioSNAP | ~27.4K | Biomedical network interactions (27,380 pairs) |
✂️ Splits:
Each split CSV contains 6 columns (SMILES, Protein, Y, Structure, SMILES_id, Protein_id). Cluster splits additionally include drug_cluster and target_cluster columns.
Model weights are downloaded automatically from HuggingFace 🤗:
| Model | HuggingFace ID | Dim |
|---|---|---|
| 🧬 ProtT5 | Rostlab/prot_t5_xl_half_uniref50-enc | 1024 |
| 🔬 SaProt | Westlake-R/SaProt_650M_AF2 | 1280 |
| 💊 MolFormer | ibm/MoLFormer-XL-both-10p1024 | 768 |
| 🧪 UniMol | dptech/Uni-Mol-Models | 512 |
Generate all four embeddings offline before training 🏗️:
python preprocess/get_embedding.py \
    --dataset bindingdb \
    --data_path datasets/bindingdb/processed_full.csv \
    --save_path embeddings/bindingdb \
    --device cuda:0 \
    --seed 42
Or generate for all three datasets at once ⚡:
bash preprocess/run_embedding.sh
This produces .pt files in embeddings/{dataset}/{type}_embeddings/ containing seq_emb and mask tensors 📁.
All dependencies are listed in requirements.txt 📄. Key packages:
| Package | Version |
|---|---|
| 🐍 Python | 3.10+ |
| 🔥 PyTorch | 2.6.0 |
| 🤗 Transformers | 4.47.0 |
| 🧪 RDKit | 2024.3.2 |
| 📈 scikit-learn | 1.5.2 |
| 🐼 pandas | 2.2.3 |
| ⚙️ yacs | 0.1.8 |
Train on the Human dataset with a cold-start split:
python main.py --dataset human --split cold --device cuda:0
Run with multiple random seeds 🌱:
bash train.sh
├── main.py                  # Training & evaluation entry point
├── model.py                 # DrugCMF model architecture
├── modules.py               # Building blocks (ModalityInteractionLearner, Classifier, MultiModalAttentionalPooler)
├── attention.py             # BidirectionalCrossAttention, AttentionalPooler
├── dataloader.py            # DTIDataset & DataLoader (loads pre-computed embeddings)
├── train_util.py            # Training & evaluation loops (AdamW, ReduceLROnPlateau, early stopping)
├── utils.py                 # Reproducibility seed, collate function, checkpoint I/O, logger
├── requirements.txt         # Full Python dependencies
├── train.sh                 # Multi-seed training script (11 seeds)
│
├── preprocess/              # Offline embedding generation
│   ├── get_embedding.py     # Generate all 4 embeddings for a dataset
│   └── run_embedding.sh     # SLURM batch script for all datasets
│
├── unimol/                  # UniMol implementation (based on DP Technology)
│   ├── unimol.py
│   ├── unimol_utils.py
│   └── transformers.py
│
└── datasets/                # Preprocessed CSV splits
    ├── README.md
    ├── human/
    │   ├── processed_full.csv
    │   ├── cold/   {train,val,test}.csv
    │   └── random/ {train,val,test}.csv
    ├── bindingdb/
    │   ├── processed_full.csv
    │   ├── random/ ...csv
    │   └── cluster/ {source_train,target_test}.csv
    └── biosnap/
        ├── processed_full.csv
        ├── random/ ...csv
        └── cluster/ {source_train,target_test}.csv
If you find DrugCMF useful, please cite our paper 🙏:
@inproceedings{yang2026bridging,
  title={Bridging the Modality Reliability Gap in Drug-Target Interaction Prediction via a Confidence-aware Multimodal Fusion Framework},
  author={Yang, Jie and Zhang, Junxiong and Qian, Kun and Yang, Qingyu and Li, Weikai and Cheng, Zhen},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={40},
  number={32},
  pages={27529--27537},
  year={2026}
}
unimol/: CC BY-NC 4.0 — Creative Commons Attribution-NonCommercial 4.0 International. Sharing and adaptation for non-commercial purposes only, with attribution.unimol/ (from DP Technology / Uni-Core): MIT License, as originally licensed.


