A Lighting Pytorch Framework for Recommendation Models, Easy-to-use and Easy-to-extend.
See the code


English | 简体中文

Online Documentation: https://datawhalechina.github.io/torch-rechub/
Torch-RecHub —— Build production-grade recommender systems in 10 lines of code. 30+ mainstream models out-of-the-box, one-click ONNX deployment, letting you focus on business instead of engineering.
PyTorch builds are tightly coupled with your hardware, driver, and runtime versions. Before installing, check the official compatibility references for NVIDIA CUDA / PyTorch versions, Huawei Ascend NPU / PyTorch versions, and AMD ROCm / PyTorch versions.
Stable Version (Recommended):
# Install one PyTorch build matching your device
pip install torch                                                     # CPU
pip install torch --index-url https://download.pytorch.org/whl/cu121  # NVIDIA GPU (CUDA 12.1)
pip install torch torch-npu                                           # Huawei Ascend NPU (requires torch-npu >= 2.5.1)
pip install --index-url https://repo.amd.com/rocm/whl/gfx1151/ "rocm[libraries,devel]" torch torchvision torchaudio  # AMD GPU (ROCm, gfx1151 = Ryzen AI Max+ 395/390/385)

pip install torch-rechub
Latest Version:
# Install uv first (if not already installed)
pip install uv

# Clone and install
git clone https://github.com/datawhalechina/torch-rechub.git
cd torch-rechub

# Install one PyTorch build matching your device
uv pip install torch                                                     # CPU
uv pip install torch --index-url https://download.pytorch.org/whl/cu121  # NVIDIA GPU (CUDA 12.1)
uv pip install torch torch-npu                                           # Huawei Ascend NPU (requires torch-npu >= 2.5.1)
uv pip install --index-url https://repo.amd.com/rocm/whl/gfx1151/ "rocm[libraries,devel]" torch torchvision torchaudio  # AMD GPU (ROCm, gfx1151 = Ryzen AI Max+ 395/390/385)

uv sync
Install an extra group with uv sync --extra <name> or pip install "torch-rechub[<name>]".
annoy: Adds Annoy-based approximate nearest neighbor indexing for retrieval serving.faiss: Adds FAISS-based vector indexing for high-performance retrieval experiments.milvus: Adds Milvus client support for external vector database serving workflows.bigdata: Adds PyArrow support for Parquet-based data loading and big-data preprocessing.onnx: Adds ONNX export, runtime inference, and model conversion dependencies.visualization: Adds model graph visualization support with TorchView and Graphviz.tracking: Adds WandB, SwanLab, and TensorBoardX integrations for experiment tracking.dev: Adds testing, linting, typing, and local development tooling.Here's a simple example of training a model (e.g., DSSM) on the MovieLens dataset:
# Clone the repository (if using latest version)
git clone https://github.com/datawhalechina/torch-rechub.git
cd torch-rechub
uv sync

# Run matching example (cd into the script directory first, as scripts use relative data paths)
cd examples/matching
python run_ml_dssm.py

# Or with custom parameters:
python run_ml_dssm.py --model_name dssm --device 'cuda:0' --learning_rate 0.001 --epoch 50 --batch_size 4096 --weight_decay 0.0001 --save_dir 'saved/dssm_ml-100k'

# Run ranking example
cd ../ranking
python run_criteo.py
After training, model files will be saved in the saved/dssm_ml-100k directory (or your configured directory).
torch-rechub/             # Root directory
├── README.md             # Project documentation
├── pyproject.toml        # Project configuration and dependencies
├── torch_rechub/         # Core library
│   ├── basic/            # Basic components
│   │   ├── activation.py # Activation functions
│   │   ├── features.py   # Feature engineering
│   │   ├── layers.py     # Neural network layers
│   │   ├── loss_func.py  # Loss functions
│   │   └── metric.py     # Evaluation metrics
│   ├── models/           # Recommendation model implementations
│   │   ├── matching/     # Matching models (DSSM/MIND/GRU4Rec etc.)
│   │   ├── ranking/      # Ranking models (WideDeep/DeepFM/DIN etc.)
│   │   └── multi_task/   # Multi-task models (MMoE/ESMM etc.)
│   ├── trainers/         # Training frameworks
│   │   ├── ctr_trainer.py    # CTR prediction trainer
│   │   ├── match_trainer.py  # Matching model trainer
│   │   └── mtl_trainer.py    # Multi-task learning trainer
│   └── utils/            # Utility functions
│       ├── data.py       # Data processing utilities
│       ├── match.py      # Matching utilities
│       ├── mtl.py        # Multi-task utilities
│       └── onnx_export.py # ONNX export utilities
├── examples/             # Example scripts
│   ├── matching/         # Matching task examples
│   ├── ranking/          # Ranking task examples
│   └── generative/       # Generative recommendation examples (HSTU, HLLM, etc.)
├── docs/                 # Documentation (VitePress, multi-language)
├── tutorials/            # Jupyter tutorials
├── tests/                # Unit tests
├── config/               # Configuration files
└── scripts/              # Utility scripts
The framework currently supports 30+ mainstream recommendation models:
| Model | Paper | Description |
|---|---|---|
| DeepFM | IJCAI 2017 | FM + Deep joint training |
| Wide&Deep | DLRS 2016 | Memorization + Generalization |
| DCN | KDD 2017 | Explicit feature crossing |
| DCN-v2 | WWW 2021 | Enhanced cross network |
| DIN | KDD 2018 | Attention for user interest |
| DIEN | AAAI 2019 | Interest evolution modeling |
| BST | DLP-KDD 2019 | Transformer for sequences |
| AFM | IJCAI 2017 | Attentional FM |
| AutoInt | CIKM 2019 | Auto feature interaction learning |
| FiBiNET | RecSys 2019 | Feature importance + Bilinear |
| DeepFFM | RecSys 2019 | Field-aware FM |
| EDCN | KDD 2021 | Enhanced DCN |
| Model | Paper | Description |
|---|---|---|
| DSSM | CIKM 2013 | Classic two-tower model |
| YoutubeDNN | RecSys 2016 | YouTube deep retrieval |
| YoutubeSBC | RecSys 2019 | Sampling bias correction |
| MIND | CIKM 2019 | Multi-interest dynamic routing |
| SINE | WSDM 2021 | Sparse interest network |
| GRU4Rec | ICLR 2016 | GRU for sequences |
| SASRec | ICDM 2018 | Self-attentive sequential |
| NARM | CIKM 2017 | Neural attentive session |
| STAMP | KDD 2018 | Short-term attention memory priority |
| ComiRec | KDD 2020 | Controllable multi-interest |
| Model | Paper | Description |
|---|---|---|
| ESMM | SIGIR 2018 | Entire space multi-task |
| MMoE | KDD 2018 | Multi-gate Mixture-of-Experts |
| PLE | RecSys 2020 | Progressive Layered Extraction |
| AITM | KDD 2021 | Adaptive Information Transfer |
| SharedBottom | - | Classic shared bottom |
| Model | Paper | Description |
|---|---|---|
| HSTU | Meta 2024 | Hierarchical Sequential Transduction Units, powering Meta's trillion-parameter RecSys |
| HLLM | 2024 | Hierarchical LLM for recommendation, combining LLM semantic understanding |
| TIGER | NeurIPS 2023 | T5-based generative retrieval for recommendation with semantic ID generation |
The framework provides built-in support or preprocessing scripts for the following common datasets:
The expected data format is typically an interaction file containing:
For specific format requirements, please refer to the example code in the tutorials directory. The examples/ directory already includes sample datasets in each scenario subdirectory, which you can use directly for quick experimentation and debugging.
You can easily integrate your own datasets by ensuring they conform to the framework's data format requirements or by writing custom data loaders.
All model usage examples can be found in /examples
from torch_rechub.models.ranking import DeepFM
from torch_rechub.trainers import CTRTrainer
from torch_rechub.utils.data import DataGenerator

dg = DataGenerator(x, y)
train_dataloader, val_dataloader, test_dataloader = dg.generate_dataloader(split_ratio=[0.7, 0.1], batch_size=256)

model = DeepFM(deep_features=deep_features, fm_features=fm_features, mlp_params={"dims": [256, 128], "dropout": 0.2, "activation": "relu"})

ctr_trainer = CTRTrainer(model)
ctr_trainer.fit(train_dataloader, val_dataloader)
auc = ctr_trainer.evaluate(ctr_trainer.model, test_dataloader)
ctr_trainer.export_onnx("deepfm.onnx")
from torch_rechub.models.multi_task import SharedBottom, ESMM, MMOE, PLE, AITM
from torch_rechub.trainers import MTLTrainer

task_types = ["classification", "classification"]
model = MMOE(features, task_types, 8, expert_params={"dims": [32,16]}, tower_params_list=[{"dims": [32, 16]}, {"dims": [32, 16]}])

mtl_trainer = MTLTrainer(model)
mtl_trainer.fit(train_dataloader, val_dataloader)
auc = ctr_trainer.evaluate(ctr_trainer.model, test_dataloader)
mtl_trainer.export_onnx("mmoe.onnx")
from torch_rechub.models.matching import DSSM
from torch_rechub.trainers import MatchTrainer
from torch_rechub.utils.data import MatchDataGenerator

dg = MatchDataGenerator(x, y)
train_dl, test_dl, item_dl = dg.generate_dataloader(test_user, all_item, batch_size=256)

model = DSSM(user_features, item_features, temperature=0.02,
             user_params={
                 "dims": [256, 128, 64],
                 "activation": 'prelu',
             },
             item_params={
                 "dims": [256, 128, 64],
                 "activation": 'prelu',
             })

match_trainer = MatchTrainer(model)
match_trainer.fit(train_dl)
match_trainer.export_onnx("dssm.onnx")
# For two-tower models, you can export user and item towers separately:
# match_trainer.export_onnx("user_tower.onnx", mode="user")
# match_trainer.export_onnx("item_tower.onnx", mode="item")
# Visualize model architecture (Requires: pip install torch-rechub[visualization])
graph = ctr_trainer.visualization(depth=4)  # Generate computation graph
ctr_trainer.visualization(save_path="model.pdf", dpi=300)  # Save as high-resolution PDF
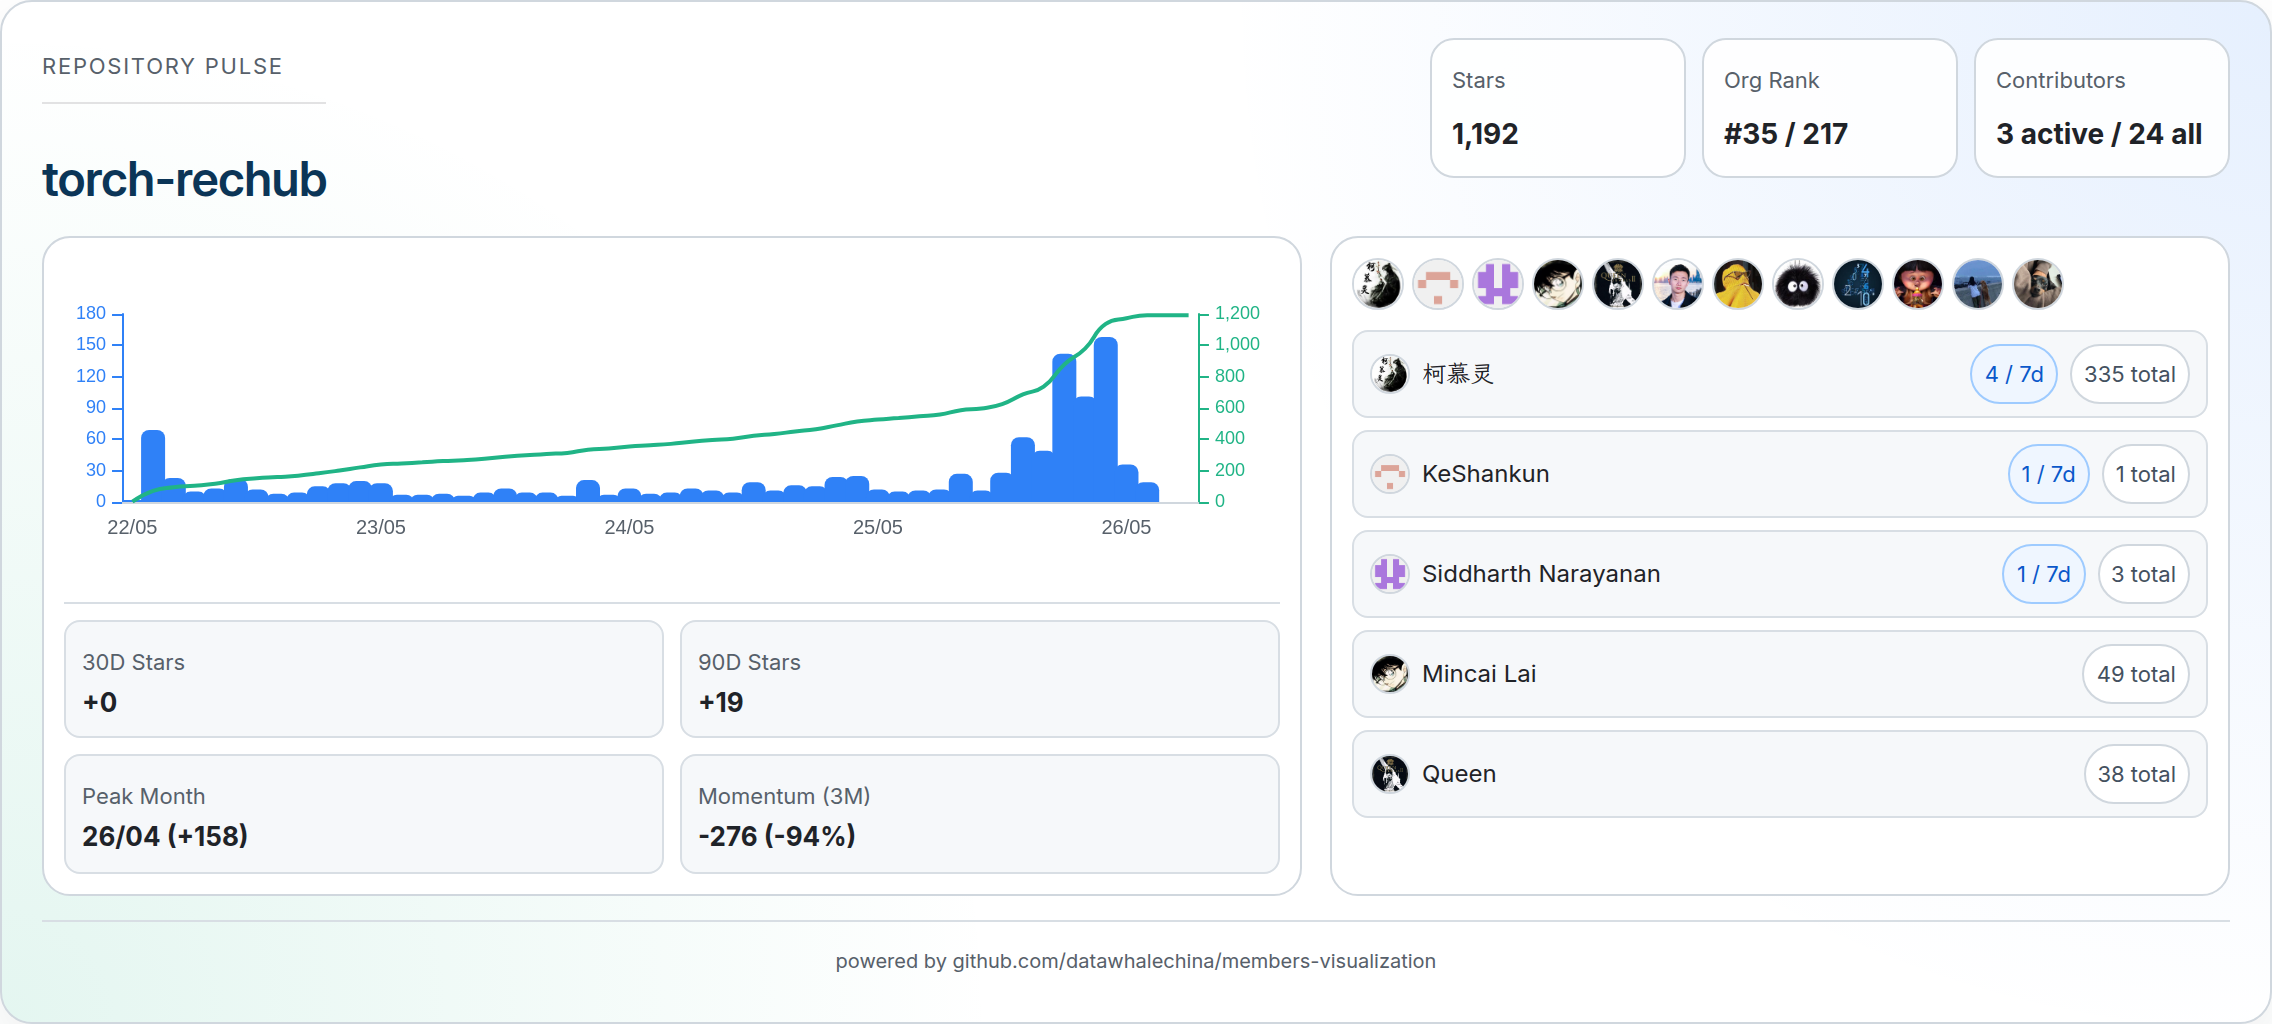
Thanks to all contributors!
We welcome contributions in all forms! Please refer to CONTRIBUTING.md for detailed contribution guidelines.
We also welcome bug reports and feature suggestions through Issues.
This project is licensed under the MIT License.
If you use this framework in your research or work, please consider citing:
@misc{torch_rechub,
    title = {Torch-RecHub},
    author = {Datawhale},
    year = {2022},
    publisher = {GitHub},
    journal = {GitHub repository},
    howpublished = {\url{https://github.com/datawhalechina/torch-rechub}},
    note = {A PyTorch-based recommender system framework providing easy-to-use and extensible solutions}
}
Last updated: [2026-08-03]
13 followers · starred Feb 2026
4 followers · starred Dec 2025
3 followers · starred Jun 2024
A Lighting Pytorch Framework for Recommendation Models, Easy-to-use and Easy-to-extend.
See the code
English | 简体中文
Online Documentation: https://datawhalechina.github.io/torch-rechub/
Torch-RecHub —— Build production-grade recommender systems in 10 lines of code. 30+ mainstream models out-of-the-box, one-click ONNX deployment, letting you focus on business instead of engineering.
PyTorch builds are tightly coupled with your hardware, driver, and runtime versions. Before installing, check the official compatibility references for NVIDIA CUDA / PyTorch versions, Huawei Ascend NPU / PyTorch versions, and AMD ROCm / PyTorch versions.
Stable Version (Recommended):
# Install one PyTorch build matching your device
pip install torch                                                     # CPU
pip install torch --index-url https://download.pytorch.org/whl/cu121  # NVIDIA GPU (CUDA 12.1)
pip install torch torch-npu                                           # Huawei Ascend NPU (requires torch-npu >= 2.5.1)
pip install --index-url https://repo.amd.com/rocm/whl/gfx1151/ "rocm[libraries,devel]" torch torchvision torchaudio  # AMD GPU (ROCm, gfx1151 = Ryzen AI Max+ 395/390/385)

pip install torch-rechub
Latest Version:
# Install uv first (if not already installed)
pip install uv

# Clone and install
git clone https://github.com/datawhalechina/torch-rechub.git
cd torch-rechub

# Install one PyTorch build matching your device
uv pip install torch                                                     # CPU
uv pip install torch --index-url https://download.pytorch.org/whl/cu121  # NVIDIA GPU (CUDA 12.1)
uv pip install torch torch-npu                                           # Huawei Ascend NPU (requires torch-npu >= 2.5.1)
uv pip install --index-url https://repo.amd.com/rocm/whl/gfx1151/ "rocm[libraries,devel]" torch torchvision torchaudio  # AMD GPU (ROCm, gfx1151 = Ryzen AI Max+ 395/390/385)

uv sync
Install an extra group with uv sync --extra <name> or pip install "torch-rechub[<name>]".
annoy: Adds Annoy-based approximate nearest neighbor indexing for retrieval serving.faiss: Adds FAISS-based vector indexing for high-performance retrieval experiments.milvus: Adds Milvus client support for external vector database serving workflows.bigdata: Adds PyArrow support for Parquet-based data loading and big-data preprocessing.onnx: Adds ONNX export, runtime inference, and model conversion dependencies.visualization: Adds model graph visualization support with TorchView and Graphviz.tracking: Adds WandB, SwanLab, and TensorBoardX integrations for experiment tracking.dev: Adds testing, linting, typing, and local development tooling.Here's a simple example of training a model (e.g., DSSM) on the MovieLens dataset:
# Clone the repository (if using latest version)
git clone https://github.com/datawhalechina/torch-rechub.git
cd torch-rechub
uv sync

# Run matching example (cd into the script directory first, as scripts use relative data paths)
cd examples/matching
python run_ml_dssm.py

# Or with custom parameters:
python run_ml_dssm.py --model_name dssm --device 'cuda:0' --learning_rate 0.001 --epoch 50 --batch_size 4096 --weight_decay 0.0001 --save_dir 'saved/dssm_ml-100k'

# Run ranking example
cd ../ranking
python run_criteo.py
After training, model files will be saved in the saved/dssm_ml-100k directory (or your configured directory).
torch-rechub/             # Root directory
├── README.md             # Project documentation
├── pyproject.toml        # Project configuration and dependencies
├── torch_rechub/         # Core library
│   ├── basic/            # Basic components
│   │   ├── activation.py # Activation functions
│   │   ├── features.py   # Feature engineering
│   │   ├── layers.py     # Neural network layers
│   │   ├── loss_func.py  # Loss functions
│   │   └── metric.py     # Evaluation metrics
│   ├── models/           # Recommendation model implementations
│   │   ├── matching/     # Matching models (DSSM/MIND/GRU4Rec etc.)
│   │   ├── ranking/      # Ranking models (WideDeep/DeepFM/DIN etc.)
│   │   └── multi_task/   # Multi-task models (MMoE/ESMM etc.)
│   ├── trainers/         # Training frameworks
│   │   ├── ctr_trainer.py    # CTR prediction trainer
│   │   ├── match_trainer.py  # Matching model trainer
│   │   └── mtl_trainer.py    # Multi-task learning trainer
│   └── utils/            # Utility functions
│       ├── data.py       # Data processing utilities
│       ├── match.py      # Matching utilities
│       ├── mtl.py        # Multi-task utilities
│       └── onnx_export.py # ONNX export utilities
├── examples/             # Example scripts
│   ├── matching/         # Matching task examples
│   ├── ranking/          # Ranking task examples
│   └── generative/       # Generative recommendation examples (HSTU, HLLM, etc.)
├── docs/                 # Documentation (VitePress, multi-language)
├── tutorials/            # Jupyter tutorials
├── tests/                # Unit tests
├── config/               # Configuration files
└── scripts/              # Utility scripts
The framework currently supports 30+ mainstream recommendation models:
| Model | Paper | Description |
|---|---|---|
| DeepFM | IJCAI 2017 | FM + Deep joint training |
| Wide&Deep | DLRS 2016 | Memorization + Generalization |
| DCN | KDD 2017 | Explicit feature crossing |
| DCN-v2 | WWW 2021 | Enhanced cross network |
| DIN | KDD 2018 | Attention for user interest |
| DIEN | AAAI 2019 | Interest evolution modeling |
| BST | DLP-KDD 2019 | Transformer for sequences |
| AFM | IJCAI 2017 | Attentional FM |
| AutoInt | CIKM 2019 | Auto feature interaction learning |
| FiBiNET | RecSys 2019 | Feature importance + Bilinear |
| DeepFFM | RecSys 2019 | Field-aware FM |
| EDCN | KDD 2021 | Enhanced DCN |
| Model | Paper | Description |
|---|---|---|
| DSSM | CIKM 2013 | Classic two-tower model |
| YoutubeDNN | RecSys 2016 | YouTube deep retrieval |
| YoutubeSBC | RecSys 2019 | Sampling bias correction |
| MIND | CIKM 2019 | Multi-interest dynamic routing |
| SINE | WSDM 2021 | Sparse interest network |
| GRU4Rec | ICLR 2016 | GRU for sequences |
| SASRec | ICDM 2018 | Self-attentive sequential |
| NARM | CIKM 2017 | Neural attentive session |
| STAMP | KDD 2018 | Short-term attention memory priority |
| ComiRec | KDD 2020 | Controllable multi-interest |
| Model | Paper | Description |
|---|---|---|
| ESMM | SIGIR 2018 | Entire space multi-task |
| MMoE | KDD 2018 | Multi-gate Mixture-of-Experts |
| PLE | RecSys 2020 | Progressive Layered Extraction |
| AITM | KDD 2021 | Adaptive Information Transfer |
| SharedBottom | - | Classic shared bottom |
| Model | Paper | Description |
|---|---|---|
| HSTU | Meta 2024 | Hierarchical Sequential Transduction Units, powering Meta's trillion-parameter RecSys |
| HLLM | 2024 | Hierarchical LLM for recommendation, combining LLM semantic understanding |
| TIGER | NeurIPS 2023 | T5-based generative retrieval for recommendation with semantic ID generation |
The framework provides built-in support or preprocessing scripts for the following common datasets:
The expected data format is typically an interaction file containing:
For specific format requirements, please refer to the example code in the tutorials directory. The examples/ directory already includes sample datasets in each scenario subdirectory, which you can use directly for quick experimentation and debugging.
You can easily integrate your own datasets by ensuring they conform to the framework's data format requirements or by writing custom data loaders.
All model usage examples can be found in /examples
from torch_rechub.models.ranking import DeepFM
from torch_rechub.trainers import CTRTrainer
from torch_rechub.utils.data import DataGenerator

dg = DataGenerator(x, y)
train_dataloader, val_dataloader, test_dataloader = dg.generate_dataloader(split_ratio=[0.7, 0.1], batch_size=256)

model = DeepFM(deep_features=deep_features, fm_features=fm_features, mlp_params={"dims": [256, 128], "dropout": 0.2, "activation": "relu"})

ctr_trainer = CTRTrainer(model)
ctr_trainer.fit(train_dataloader, val_dataloader)
auc = ctr_trainer.evaluate(ctr_trainer.model, test_dataloader)
ctr_trainer.export_onnx("deepfm.onnx")
from torch_rechub.models.multi_task import SharedBottom, ESMM, MMOE, PLE, AITM
from torch_rechub.trainers import MTLTrainer

task_types = ["classification", "classification"]
model = MMOE(features, task_types, 8, expert_params={"dims": [32,16]}, tower_params_list=[{"dims": [32, 16]}, {"dims": [32, 16]}])

mtl_trainer = MTLTrainer(model)
mtl_trainer.fit(train_dataloader, val_dataloader)
auc = ctr_trainer.evaluate(ctr_trainer.model, test_dataloader)
mtl_trainer.export_onnx("mmoe.onnx")
from torch_rechub.models.matching import DSSM
from torch_rechub.trainers import MatchTrainer
from torch_rechub.utils.data import MatchDataGenerator

dg = MatchDataGenerator(x, y)
train_dl, test_dl, item_dl = dg.generate_dataloader(test_user, all_item, batch_size=256)

model = DSSM(user_features, item_features, temperature=0.02,
             user_params={
                 "dims": [256, 128, 64],
                 "activation": 'prelu',
             },
             item_params={
                 "dims": [256, 128, 64],
                 "activation": 'prelu',
             })

match_trainer = MatchTrainer(model)
match_trainer.fit(train_dl)
match_trainer.export_onnx("dssm.onnx")
# For two-tower models, you can export user and item towers separately:
# match_trainer.export_onnx("user_tower.onnx", mode="user")
# match_trainer.export_onnx("item_tower.onnx", mode="item")
# Visualize model architecture (Requires: pip install torch-rechub[visualization])
graph = ctr_trainer.visualization(depth=4)  # Generate computation graph
ctr_trainer.visualization(save_path="model.pdf", dpi=300)  # Save as high-resolution PDF
Thanks to all contributors!
We welcome contributions in all forms! Please refer to CONTRIBUTING.md for detailed contribution guidelines.
We also welcome bug reports and feature suggestions through Issues.
This project is licensed under the MIT License.
If you use this framework in your research or work, please consider citing:
@misc{torch_rechub,
    title = {Torch-RecHub},
    author = {Datawhale},
    year = {2022},
    publisher = {GitHub},
    journal = {GitHub repository},
    howpublished = {\url{https://github.com/datawhalechina/torch-rechub}},
    note = {A PyTorch-based recommender system framework providing easy-to-use and extensible solutions}
}
Last updated: [2026-08-03]
13 followers · starred Feb 2026
4 followers · starred Dec 2025
3 followers · starred Jun 2024



