

Vietnamese F5-TTS (Vi-F5-TTS) is a fine-tuned text-to-speech model for Vietnamese, based on F5-TTS. Using the vin100h-preprocessed-v2 dataset, it generates natural Vietnamese audio 🎙️ for applications like voice assistants 🤖 and audiobooks 📚, powered by PyTorch, Transformers, and Gradio 🚀.
Vietnamese Speech 🎤: Produces natural Vietnamese audio from text.
Fine-Tuned 🔧: Optimized for better pronunciation and intonation.
Customizable Inference 🎛️: Uses reference audio/text for tailored output.
Gradio GUI 🖥️: Interactive interface for easy testing.
Open-Source 🌐: MIT-licensed with accessible code and checkpoints.
Multi-Platform ☁️: Supports Colab, Kaggle, SageMaker, and local use.
Flexible Training ⚙️: Configurable with accelerate support.




You can explore more in this HuggingFace Dataset available at the given link for further details: 
This repository is built upon the F5-TTS model, originally developed by 
Experience the magic of Vietnames Text to Speech from:
HuggingFace Space:
Demo GUI:
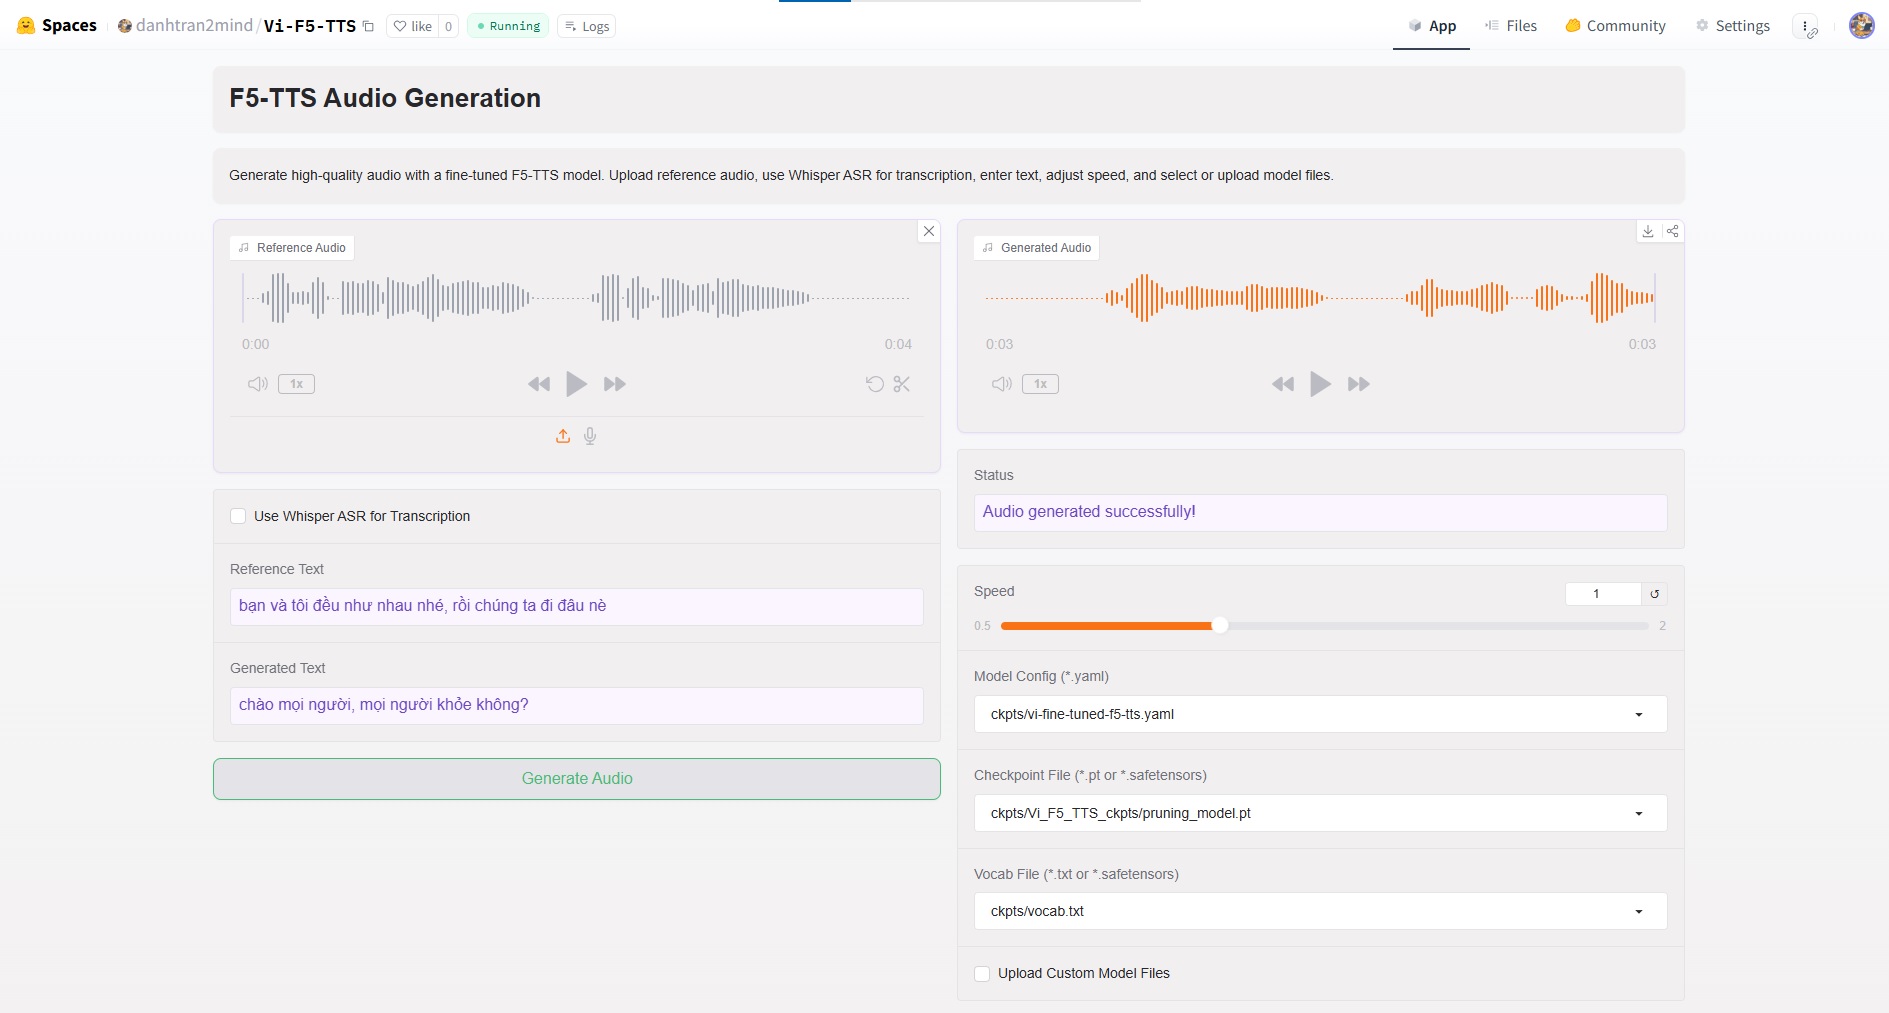
To run the Gradio app locally (localhost:7860):
python apps/gradio_app.py
Clone the project repository and navigate to the project directory:
git clone https://github.com/danhtran2mind/Vi-F5-TTS.git
cd Vi-F5-TTS
Install the required Python packages:
pip install -e .
Or Install Dependencies using requirements.txt
pip install -r requirements/requirements.txt
Run the following scripts to set up the project:
Install Third-Party Dependencies
python scripts/setup_third_party.py
Download Model Checkpoints
SWivid/F5-TTS:python scripts/download_ckpts.py \
--repo_id "SWivid/F5-TTS" --local_dir "./ckpts" \
--folder_name "F5TTS_v1_Base_no_zero_init"
danhtran2mind/Vi-F5-TTS:python scripts/download_ckpts.py \
--repo_id "danhtran2mind/Vi-F5-TTS" \
--local_dir "./ckpts" --pruning_model
Prepare Dataset (Optional, for Training)
python scripts/process_dataset.py
Configuration of the accelerate
accelerate config default
To train the model:
accelerate launch ./src/f5_tts/train/finetune_cli.py \
    --exp_name F5TTS_Base \
    --dataset_name vin100h-preprocessed-v2 \
    --finetune \
    --tokenizer pinyin \
    --learning_rate 1e-05 \
    --batch_size_type frame \
    --batch_size_per_gpu 3200 \
    --max_samples 64 \
    --grad_accumulation_steps 2 \
    --max_grad_norm 1 \
    --epochs 80 \
    --num_warmup_updates 2761 \
    --save_per_updates 4000 \
    --keep_last_n_checkpoints 1 \
    --last_per_updates 4000 \
    --log_samples \
    --pretrain "<your_pretrain_model>"# such as "./ckpts/F5TTS_v1_Base_no_zero_init/model_1250000.safetensors"
Refer to the Training Documents for detailed arguments used in fine-tuning the model. ⚙️
To generate videos using the trained model:
python src/f5_tts/infer/infer_cli.py \
    --model_cfg "vi-fine-tuned-f5-tts.yaml" \
    --ckpt_file "model_last.pt" \
    --vocab_file "vocab.txt" \
    --ref_audio "<path_to_your_reference_audio>" \
    --ref_text "<text_of_your_reference_audio>" \
    --gen_text "<your_generative_text>" \
    --output_dir "<output_folder>" \
    --output_file "<output_file_name>"
Refer to the Inference Documents for detailed arguments used in Inference. ⚙️
https://github.com/user-attachments/assets/f3a8d772-8a2f-461d-afdb-01d43cf3248f
https://github.com/user-attachments/assets/8d83f2a0-2124-4903-9bc6-fc9154041884
https://github.com/user-attachments/assets/79a703b5-a160-4c70-85e0-6cb22f2bf71b
https://github.com/user-attachments/assets/2e0566ad-d97a-441e-89fd-ef0c9729ac48
https://github.com/user-attachments/assets/416ebae3-6d10-4746-a92f-4abdff2a6444
https://github.com/user-attachments/assets/ac8a47b2-cadf-44ca-8fcb-a4acd8040c96
https://github.com/user-attachments/assets/e71ca5e1-1bde-4c96-a5c7-96f869f5537e
https://github.com/user-attachments/assets/44ef4bf4-1649-4df6-86d5-317819b2dd83
vin100h-preprocessed-v2 dataset, which, while useful, is limited in size and diversity. This can result in suboptimal audio quality, particularly in capturing varied intonations, accents, and emotional nuances specific to Vietnamese speech.This repository is trained from 
SWivid/F5-TTS Model Hub from the 
Vietnamese F5-TTS (Vi-F5-TTS) is a fine-tuned text-to-speech model for Vietnamese, based on F5-TTS. Using the vin100h-preprocessed-v2 dataset, it generates natural Vietnamese audio 🎙️ for applications like voice assistants 🤖 and audiobooks 📚, powered by PyTorch, Transformers, and Gradio 🚀.
Vietnamese Speech 🎤: Produces natural Vietnamese audio from text.
Fine-Tuned 🔧: Optimized for better pronunciation and intonation.
Customizable Inference 🎛️: Uses reference audio/text for tailored output.
Gradio GUI 🖥️: Interactive interface for easy testing.
Open-Source 🌐: MIT-licensed with accessible code and checkpoints.
Multi-Platform ☁️: Supports Colab, Kaggle, SageMaker, and local use.
Flexible Training ⚙️: Configurable with accelerate support.
You can explore more in this HuggingFace Dataset available at the given link for further details:
This repository is built upon the F5-TTS model, originally developed by
Experience the magic of Vietnames Text to Speech from:
HuggingFace Space:
Demo GUI:
To run the Gradio app locally (localhost:7860):
python apps/gradio_app.py
Clone the project repository and navigate to the project directory:
git clone https://github.com/danhtran2mind/Vi-F5-TTS.git
cd Vi-F5-TTS
Install the required Python packages:
pip install -e .
Or Install Dependencies using requirements.txt
pip install -r requirements/requirements.txt
Run the following scripts to set up the project:
Install Third-Party Dependencies
python scripts/setup_third_party.py
Download Model Checkpoints
SWivid/F5-TTS:python scripts/download_ckpts.py \
--repo_id "SWivid/F5-TTS" --local_dir "./ckpts" \
--folder_name "F5TTS_v1_Base_no_zero_init"
danhtran2mind/Vi-F5-TTS:python scripts/download_ckpts.py \
--repo_id "danhtran2mind/Vi-F5-TTS" \
--local_dir "./ckpts" --pruning_model
Prepare Dataset (Optional, for Training)
python scripts/process_dataset.py
Configuration of the accelerate
accelerate config default
To train the model:
accelerate launch ./src/f5_tts/train/finetune_cli.py \
    --exp_name F5TTS_Base \
    --dataset_name vin100h-preprocessed-v2 \
    --finetune \
    --tokenizer pinyin \
    --learning_rate 1e-05 \
    --batch_size_type frame \
    --batch_size_per_gpu 3200 \
    --max_samples 64 \
    --grad_accumulation_steps 2 \
    --max_grad_norm 1 \
    --epochs 80 \
    --num_warmup_updates 2761 \
    --save_per_updates 4000 \
    --keep_last_n_checkpoints 1 \
    --last_per_updates 4000 \
    --log_samples \
    --pretrain "<your_pretrain_model>"# such as "./ckpts/F5TTS_v1_Base_no_zero_init/model_1250000.safetensors"
Refer to the Training Documents for detailed arguments used in fine-tuning the model. ⚙️
To generate videos using the trained model:
python src/f5_tts/infer/infer_cli.py \
    --model_cfg "vi-fine-tuned-f5-tts.yaml" \
    --ckpt_file "model_last.pt" \
    --vocab_file "vocab.txt" \
    --ref_audio "<path_to_your_reference_audio>" \
    --ref_text "<text_of_your_reference_audio>" \
    --gen_text "<your_generative_text>" \
    --output_dir "<output_folder>" \
    --output_file "<output_file_name>"
Refer to the Inference Documents for detailed arguments used in Inference. ⚙️
https://github.com/user-attachments/assets/f3a8d772-8a2f-461d-afdb-01d43cf3248f
https://github.com/user-attachments/assets/8d83f2a0-2124-4903-9bc6-fc9154041884
https://github.com/user-attachments/assets/79a703b5-a160-4c70-85e0-6cb22f2bf71b
https://github.com/user-attachments/assets/2e0566ad-d97a-441e-89fd-ef0c9729ac48
https://github.com/user-attachments/assets/416ebae3-6d10-4746-a92f-4abdff2a6444
https://github.com/user-attachments/assets/ac8a47b2-cadf-44ca-8fcb-a4acd8040c96
https://github.com/user-attachments/assets/e71ca5e1-1bde-4c96-a5c7-96f869f5537e
https://github.com/user-attachments/assets/44ef4bf4-1649-4df6-86d5-317819b2dd83
vin100h-preprocessed-v2 dataset, which, while useful, is limited in size and diversity. This can result in suboptimal audio quality, particularly in capturing varied intonations, accents, and emotional nuances specific to Vietnamese speech.This repository is trained from SWivid/F5-TTS Model Hub from the