[ICLR'26] Official implementation of "3D Scene Prompting for Scene-Consistent Camera-Controllable Video Generation"
See the code
This is the official implementation of the paper
"3D Scene Prompting for Scene-Consistent Camera-Controllable Video Generation"
by Joungbin Lee1* · Jaewoo Jung1* · Jisang Han1* · Takuya Narihira2 · Kazumi Fukuda2 · Junyoung Seo1 · Sunghwan Hong3 · Yuki Mitsufuji2,4† · Seungryong Kim1†
1KAIST AI 2Sony AI 3ETH Zürich 4Sony Group Corporation
*: Co-First Author
†: Co-Corresponding Author
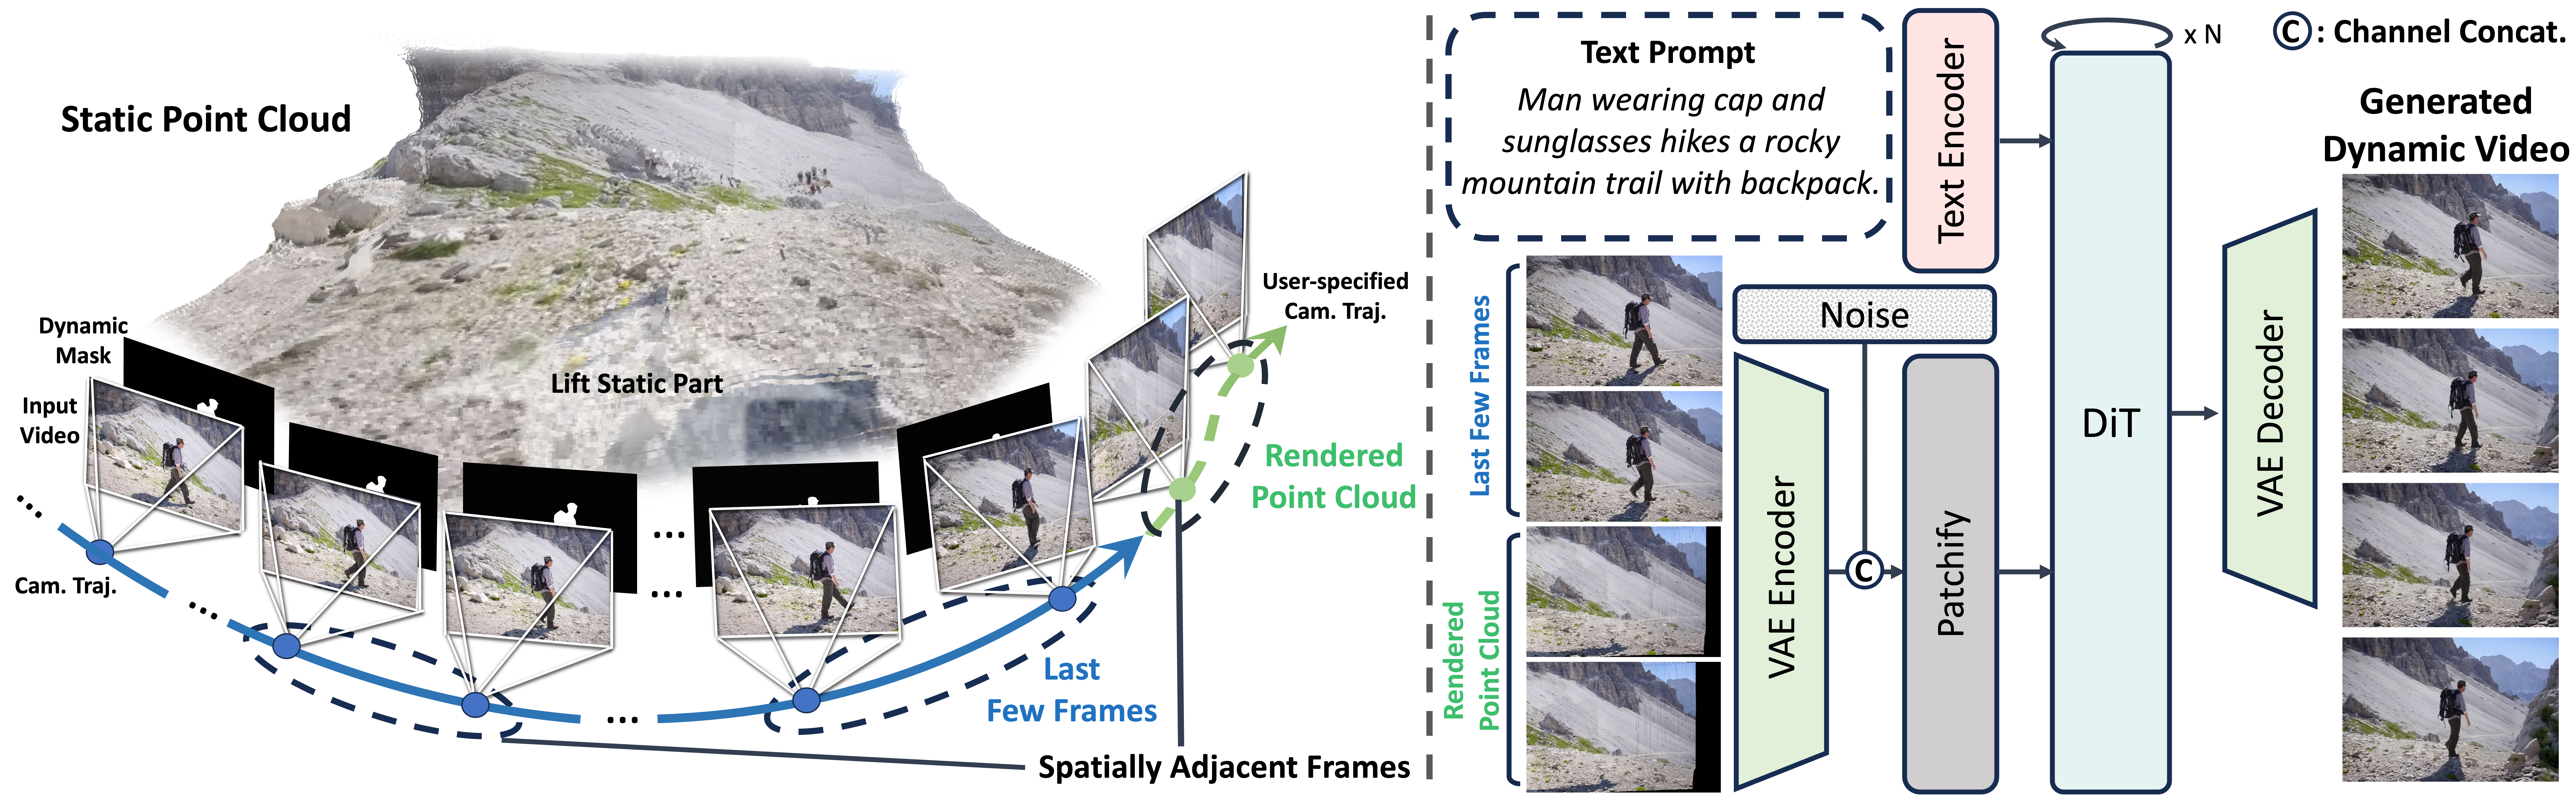
3DScenePrompt is a framework to generate a next chunk video from any arbitrary-length in-the-wild input video while allowing precise camera control and maintaining scene-consistency with the input video.
Our code is developed based on pytorch 2.5.1, CUDA 12.1 and python 3.10.
git clone --recursive https://github.com/cvlab-kaist/3DScenePrompt.git
cd 3DScenePrompt

conda create -n 3DScenePrompt python=3.10
conda activate 3DScenePrompt

pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 xformers --index-url https://download.pytorch.org/whl/cu121
pip install --extra-index-url https://miropsota.github.io/torch_packages_builder pytorch3d==0.7.8+pt2.5.1cu121

cd Depth-Anything-3
pip install -e .

cd third_party/sam2
pip install -e .
cd ../../../

pip install -r requirements.txt


# SEA-raft, Sam2 model weight download
bash download_weight.sh
This project provides a preprocessing pipeline that converts input videos into depth maps, normal maps, conditioning videos, and additional metadata required for training and inference. Run the following script to generate the dataset:
cd Depth-Anything-3
bash data_preprocesisng.sh
cd ../
After running the preprocessing script, the dataset will be structured as follows:
dataset
├── images
│   ├── {scene_name}
│   │   ├── color
│   │   │   ├── 000000.png
│   │   │   ├── 000001.png
│   │   │   ├── ...
│   │   │   ├── 000100.png
│   │   ├── dynamic_mask
│   │   │   ├── 000000.png
│   │   │   ├── 000001.png
│   │   │   ├── ...
│   │   │   ├── 000100.png
│   │   │
│   │   └── DA3.npz              # Depth-Anything-3 depth + camera extrinsic, intrinsic
│   │
│   └── ...
│
├── cond_video
│   ├── {scene_name}.mp4         # conditioning video
│   └── ...
│
├── captions.txt                 # caption per scene
├── cond_video.txt               # path list of cond videos
├── video.txt                    # (optional) path list of videos for training
To run inference with our pretrained model:
cd Spatio-CogVideo/inference
bash inference.sh
This script performs video generation using the provided configuration and checkpoints.
To fine-tune the model on OpenVid or RealEstate10K:
cd Spatio-CogVideo/finetune
bash train_sft_v2v_openvid_re10k.sh
The training script includes dataset loading, optimization setup, and checkpoint saving.
Modify the script as needed to adjust hyperparameters or dataset paths.
If you find this research useful, please consider citing:
@misc{lee20253dscenepromptingsceneconsistent,
      title={3D Scene Prompting for Scene-Consistent Camera-Controllable Video Generation},
      author={JoungBin Lee and Jaewoo Jung and Jisang Han and Takuya Narihira and Kazumi Fukuda and Junyoung Seo and Sunghwan Hong and Yuki Mitsufuji and Seungryong Kim},
      year={2025},
      eprint={2510.14945},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2510.14945},
}
Our work builds upon several excellent open-source projects. We gratefully acknowledge the following repositories:
We sincerely thank the authors and contributors of these projects for making their code publicly available.
[ICLR'26] Official implementation of "3D Scene Prompting for Scene-Consistent Camera-Controllable Video Generation"
See the code
This is the official implementation of the paper
"3D Scene Prompting for Scene-Consistent Camera-Controllable Video Generation"
by Joungbin Lee1* · Jaewoo Jung1* · Jisang Han1* · Takuya Narihira2 · Kazumi Fukuda2 · Junyoung Seo1 · Sunghwan Hong3 · Yuki Mitsufuji2,4† · Seungryong Kim1†
1KAIST AI 2Sony AI 3ETH Zürich 4Sony Group Corporation
*: Co-First Author
†: Co-Corresponding Author
3DScenePrompt is a framework to generate a next chunk video from any arbitrary-length in-the-wild input video while allowing precise camera control and maintaining scene-consistency with the input video.
Our code is developed based on pytorch 2.5.1, CUDA 12.1 and python 3.10.
git clone --recursive https://github.com/cvlab-kaist/3DScenePrompt.git
cd 3DScenePrompt

conda create -n 3DScenePrompt python=3.10
conda activate 3DScenePrompt

pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 xformers --index-url https://download.pytorch.org/whl/cu121
pip install --extra-index-url https://miropsota.github.io/torch_packages_builder pytorch3d==0.7.8+pt2.5.1cu121

cd Depth-Anything-3
pip install -e .

cd third_party/sam2
pip install -e .
cd ../../../

pip install -r requirements.txt


# SEA-raft, Sam2 model weight download
bash download_weight.sh
This project provides a preprocessing pipeline that converts input videos into depth maps, normal maps, conditioning videos, and additional metadata required for training and inference. Run the following script to generate the dataset:
cd Depth-Anything-3
bash data_preprocesisng.sh
cd ../
After running the preprocessing script, the dataset will be structured as follows:
dataset
├── images
│   ├── {scene_name}
│   │   ├── color
│   │   │   ├── 000000.png
│   │   │   ├── 000001.png
│   │   │   ├── ...
│   │   │   ├── 000100.png
│   │   ├── dynamic_mask
│   │   │   ├── 000000.png
│   │   │   ├── 000001.png
│   │   │   ├── ...
│   │   │   ├── 000100.png
│   │   │
│   │   └── DA3.npz              # Depth-Anything-3 depth + camera extrinsic, intrinsic
│   │
│   └── ...
│
├── cond_video
│   ├── {scene_name}.mp4         # conditioning video
│   └── ...
│
├── captions.txt                 # caption per scene
├── cond_video.txt               # path list of cond videos
├── video.txt                    # (optional) path list of videos for training
To run inference with our pretrained model:
cd Spatio-CogVideo/inference
bash inference.sh
This script performs video generation using the provided configuration and checkpoints.
To fine-tune the model on OpenVid or RealEstate10K:
cd Spatio-CogVideo/finetune
bash train_sft_v2v_openvid_re10k.sh
The training script includes dataset loading, optimization setup, and checkpoint saving.
Modify the script as needed to adjust hyperparameters or dataset paths.
If you find this research useful, please consider citing:
@misc{lee20253dscenepromptingsceneconsistent,
      title={3D Scene Prompting for Scene-Consistent Camera-Controllable Video Generation},
      author={JoungBin Lee and Jaewoo Jung and Jisang Han and Takuya Narihira and Kazumi Fukuda and Junyoung Seo and Sunghwan Hong and Yuki Mitsufuji and Seungryong Kim},
      year={2025},
      eprint={2510.14945},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2510.14945},
}
Our work builds upon several excellent open-source projects. We gratefully acknowledge the following repositories:
We sincerely thank the authors and contributors of these projects for making their code publicly available.






