Transformer-based sequence classification model for inference of GRN prior-knowledge
Jupyter Notebook
5
46 commits
updated Jul 1, 2026
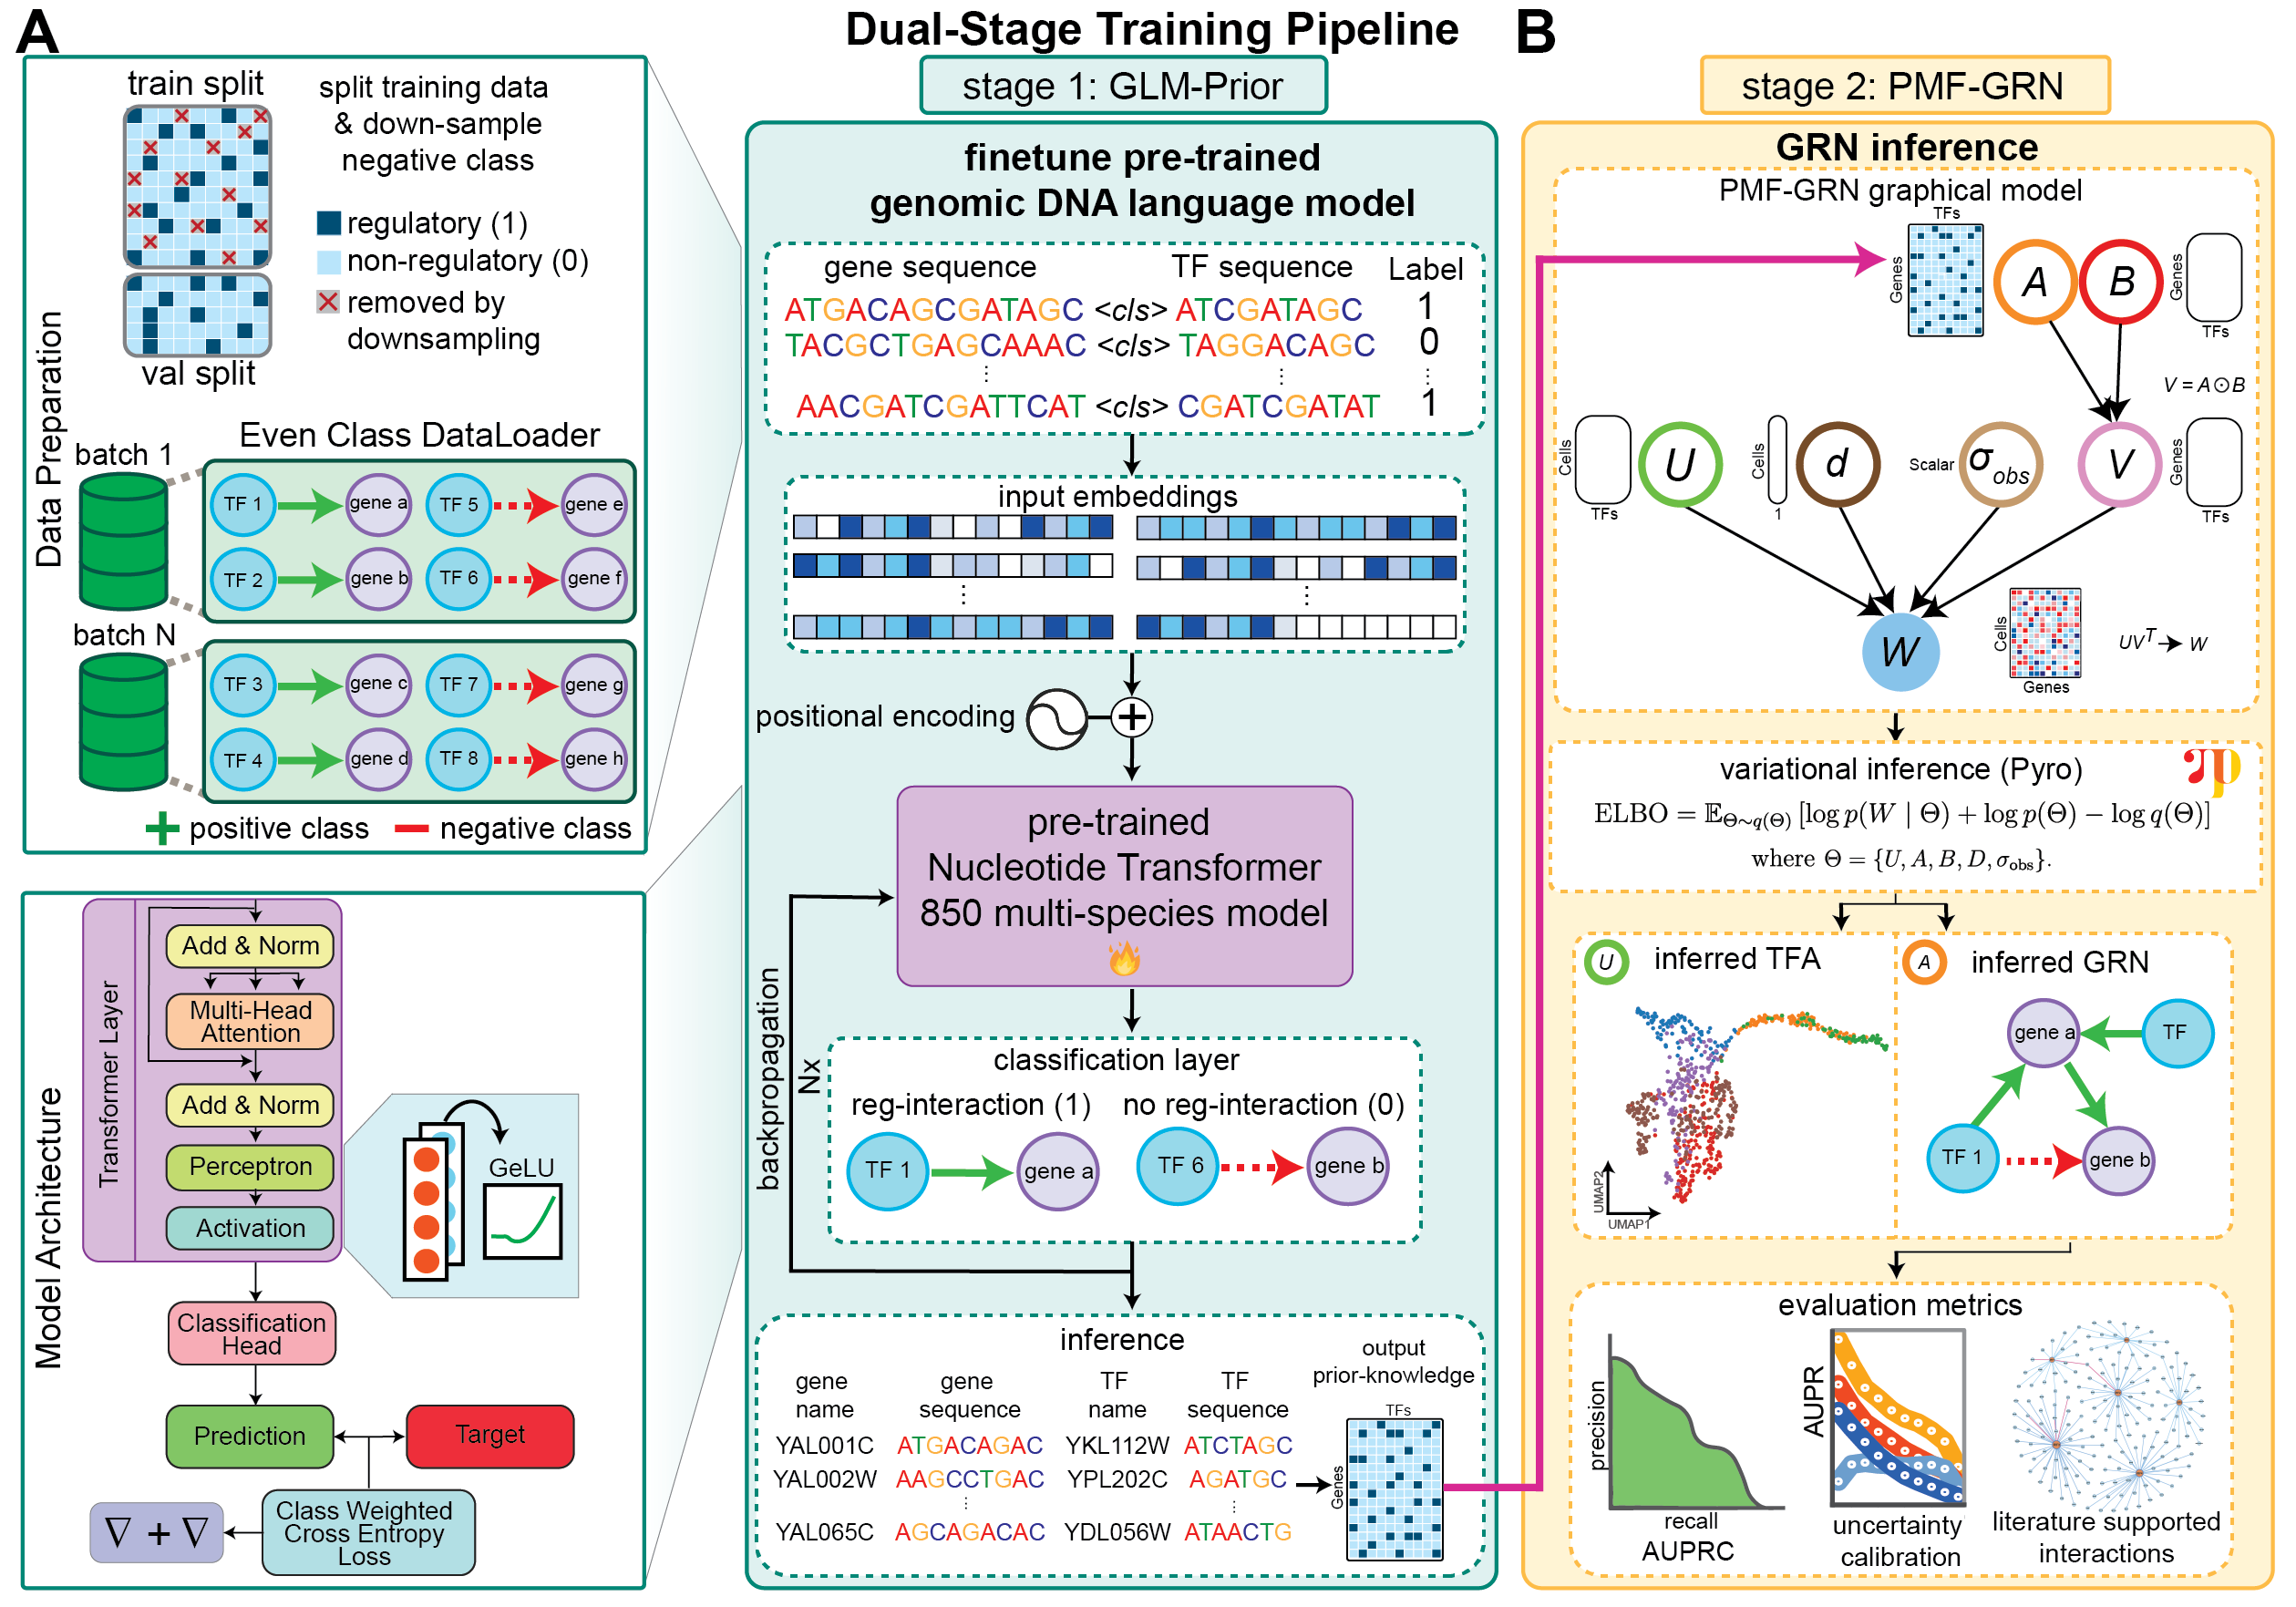
This repository contains the models, data, and scripts used in the GLM-Prior paper, which introduces a transformer-based nucleotide sequence classification approach for inferring transcription factor–target gene interaction priors.
GLM-Prior is the first stage in a dual-stage training pipeline that includes:
GLM-Prior is designed to run within a Singularity container using a Conda environment. Follow the steps below to create and activate the environment. Installation time is approximately less than 5 minutes.
conda create -p /ext3/pmf-prior-network python=3.10 -y
pip install torch==2.3.1 torchvision==0.18.1 torchaudio==2.3.1 --index-url https://download.pytorch.org/whl/cu121
pip install hydra-core pandas datasets scikit-learn transformers wandb
singularity exec --nv --overlay overlay-15GB-500K.ext3:ro --bind local:$HOME/.local cuda12.1.1-cudnn8.9.0-devel-ubuntu22.04.2.sif /bin/bash
conda env update --prefix /ext3/pmf-prior-network --file environment_prior_network.yaml --prune
source /ext3/env.sh
conda activate /ext3/pmf-prior-network
To prepare training data, use the notebooks provided in the create_sequence_datasets/ directory. There are separate notebooks for yeast, mouse, and human.
Each notebook:
Dataset Locations:
data/yeast/data/mouse/data/human/Datasets for human and mouse can be downloaded and placed into their respective folders.
For mouse and human reference datasets, download from BEELINE.
To train the GLM-Prior model on DNA sequence input:
config/train_prior_network_pipeline.yamlconfig/prior_network/finetune_nt.yamlconfig/train_prior_network_pipeline.yamlprior_network_singularity_overlay - overlay path for environmentprior_network_singularity_img - path to Singularity imagesbatch train_prior_network_pipeline.slurm TPN_pipeline
This will launch dynamic slurm scripts to:
output/<experiment_name>/prior_network_predictions.tsv
output/<experiment_name>/auprc_vs_gold.jsonTo optimize GLM-Prior for a new dataset, we recommend running a pre-training hyperparameter sweep over 1 epoch. To run a hyperparameter sweep:
Edit ./train_prior_network/finetune_nt_hp_sweep.sh for:
num_train_epochs: 1 in config/prior_network/finetune_nt.yaml./train_prior_network/finetune_nt_hp_sweep.sh $USER /scratch/$USER/GLM-Prior/envs/overlay-15GB-500K.ext3 /scratch/work/public/singularity/cuda12.1.1-cudnn8.9.0-devel-ubuntu22.04.2.sif ./train_prior_network/hp-sweep/
Each configuration will be submitted as an individual SLURM job. Weights & Biases will automatically track all sweeps. Select the configuration with the best F1 score and update your training config accordingly.
Binarized prior-knowledge can be used as input for the PMF-GRN model to perform full GRN inference.
Datasets and models associated with the paper can be found on HuggingFace
Transformer-based sequence classification model for inference of GRN prior-knowledge
Jupyter Notebook
5
46 commits
updated Jul 1, 2026
This repository contains the models, data, and scripts used in the GLM-Prior paper, which introduces a transformer-based nucleotide sequence classification approach for inferring transcription factor–target gene interaction priors.
GLM-Prior is the first stage in a dual-stage training pipeline that includes:
GLM-Prior is designed to run within a Singularity container using a Conda environment. Follow the steps below to create and activate the environment. Installation time is approximately less than 5 minutes.
conda create -p /ext3/pmf-prior-network python=3.10 -y
pip install torch==2.3.1 torchvision==0.18.1 torchaudio==2.3.1 --index-url https://download.pytorch.org/whl/cu121
pip install hydra-core pandas datasets scikit-learn transformers wandb
singularity exec --nv --overlay overlay-15GB-500K.ext3:ro --bind local:$HOME/.local cuda12.1.1-cudnn8.9.0-devel-ubuntu22.04.2.sif /bin/bash
conda env update --prefix /ext3/pmf-prior-network --file environment_prior_network.yaml --prune
source /ext3/env.sh
conda activate /ext3/pmf-prior-network
To prepare training data, use the notebooks provided in the create_sequence_datasets/ directory. There are separate notebooks for yeast, mouse, and human.
Each notebook:
Dataset Locations:
data/yeast/data/mouse/data/human/Datasets for human and mouse can be downloaded and placed into their respective folders.
For mouse and human reference datasets, download from BEELINE.
To train the GLM-Prior model on DNA sequence input:
config/train_prior_network_pipeline.yamlconfig/prior_network/finetune_nt.yamlconfig/train_prior_network_pipeline.yamlprior_network_singularity_overlay - overlay path for environmentprior_network_singularity_img - path to Singularity imagesbatch train_prior_network_pipeline.slurm TPN_pipeline
This will launch dynamic slurm scripts to:
output/<experiment_name>/prior_network_predictions.tsv
output/<experiment_name>/auprc_vs_gold.jsonTo optimize GLM-Prior for a new dataset, we recommend running a pre-training hyperparameter sweep over 1 epoch. To run a hyperparameter sweep:
Edit ./train_prior_network/finetune_nt_hp_sweep.sh for:
num_train_epochs: 1 in config/prior_network/finetune_nt.yaml./train_prior_network/finetune_nt_hp_sweep.sh $USER /scratch/$USER/GLM-Prior/envs/overlay-15GB-500K.ext3 /scratch/work/public/singularity/cuda12.1.1-cudnn8.9.0-devel-ubuntu22.04.2.sif ./train_prior_network/hp-sweep/
Each configuration will be submitted as an individual SLURM job. Weights & Biases will automatically track all sweeps. Select the configuration with the best F1 score and update your training config accordingly.
Binarized prior-knowledge can be used as input for the PMF-GRN model to perform full GRN inference.
Datasets and models associated with the paper can be found on HuggingFace