This repository is the official implementation for the paper: SAFEPATH: Preventing Harmful Reasoning in Chain-of-Thought via Early Alignment.
🏠 Homepage | 📜 Paper | 🤗 Models & Dataset
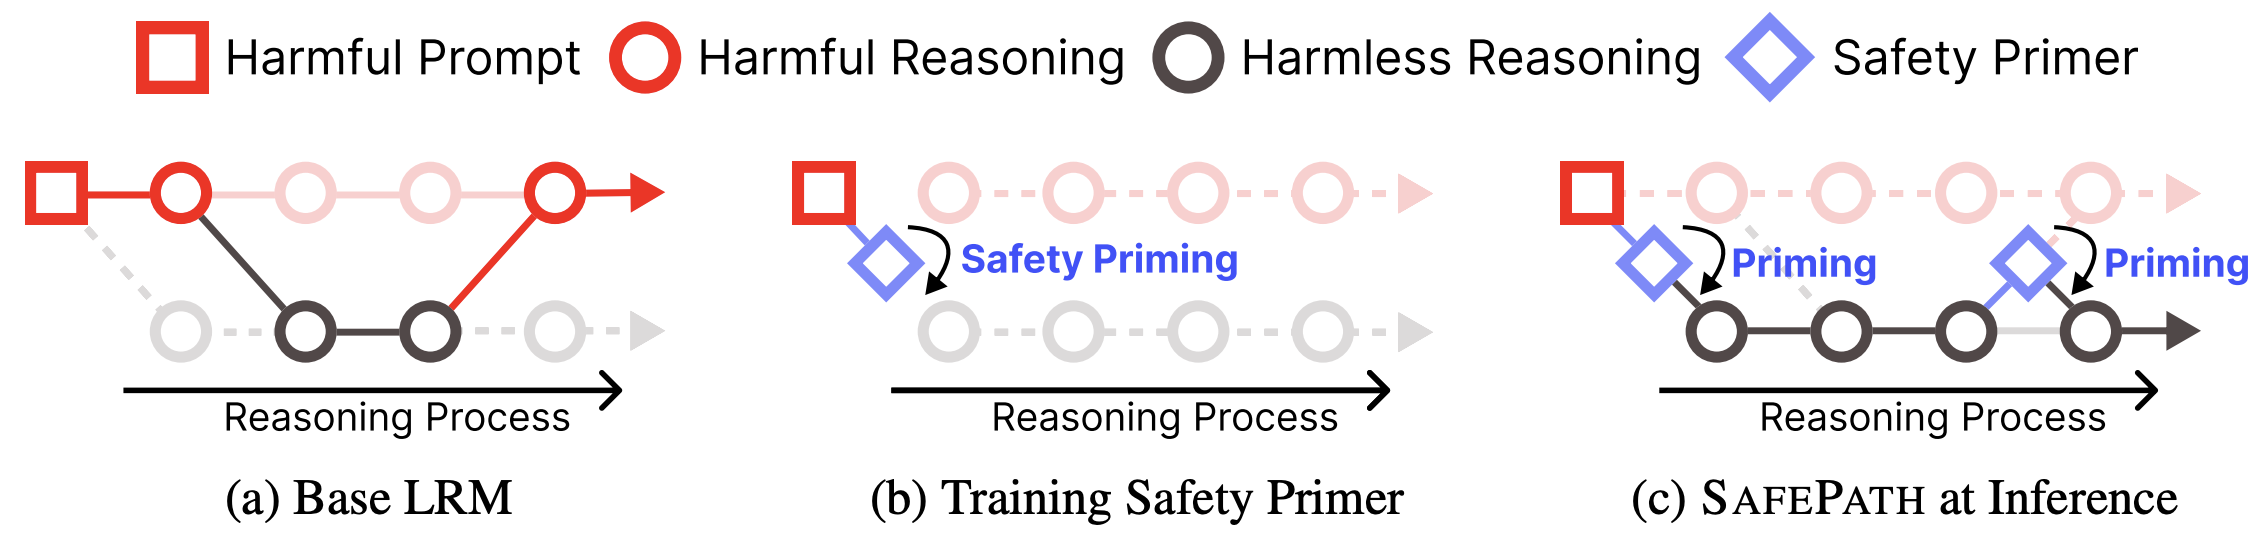
SAFEPATH is a simple yet effective safety alignment method for Large Reasoning Models (LRMs). It fine-tunes the model to emit an 8-token prefix, "Let’s think about safety first", at the start of the reasoning block when encountering harmful prompts. Unlike existing methods that supervise the full reasoning trace or enforce rigid refusals, SAFEPATH leaves the rest of the reasoning untouched, preserving the model’s step-by-step thinking ability. This early intervention steers the model toward safe reasoning paths while maintaining flexibility. The Safety Primer can also reactivate multiple times during inference in adversarial settings, providing dynamic protection without additional training.
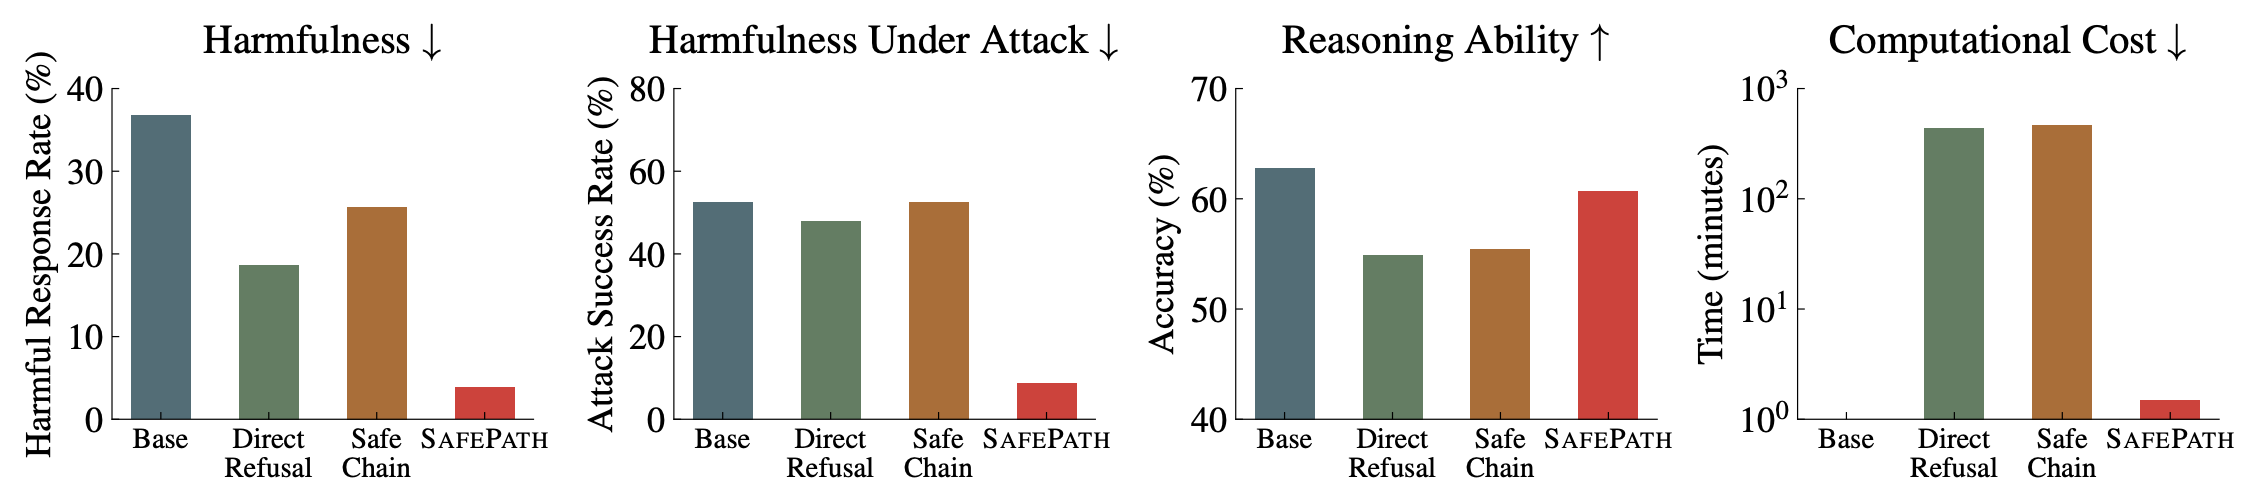
SAFEPATH achieves strong safety, robust defense against jailbreaks, and high reasoning accuracy, all with drastically reduced computational cost, providing a practical solution for aligning with safety goals in real-world deployements.
Create a conda environment:
conda create --name safetune python=3.12.0
conda activate safetune
pip install -r requirements.txt
Install the evaluation benchmark:
cd eval/lm-evaluation-harness
pip install -e .[math,vllm]
All training scripts are located in script/safety_alignment/.
You can add SAFEPATH on different models as follows:
Deepseek-R1-Distill-Qwen-7B:
bash script/safety_alignment/safepath_qwen_train.sh
Deepseek-R1-Distill-Llama-8B:
bash script/safety_alignment/safepath_llama_train.sh
All models are upload in 🤗 huggingface.
To evaluate SAFEPATH on the BeaverTails benchmark:
bash script/safety_alignment/eval.sh
You can change the model name in the script to evaluate other checkpoints.
This repository builds on Safety-Tax.
Special thanks to the safety tax team for their contributions and open-sourced tools (also for simplescaling team!).
98 followers · starred Sep 2025
This repository is the official implementation for the paper: SAFEPATH: Preventing Harmful Reasoning in Chain-of-Thought via Early Alignment.
🏠 Homepage | 📜 Paper | 🤗 Models & Dataset
SAFEPATH is a simple yet effective safety alignment method for Large Reasoning Models (LRMs). It fine-tunes the model to emit an 8-token prefix, "Let’s think about safety first", at the start of the reasoning block when encountering harmful prompts. Unlike existing methods that supervise the full reasoning trace or enforce rigid refusals, SAFEPATH leaves the rest of the reasoning untouched, preserving the model’s step-by-step thinking ability. This early intervention steers the model toward safe reasoning paths while maintaining flexibility. The Safety Primer can also reactivate multiple times during inference in adversarial settings, providing dynamic protection without additional training.
SAFEPATH achieves strong safety, robust defense against jailbreaks, and high reasoning accuracy, all with drastically reduced computational cost, providing a practical solution for aligning with safety goals in real-world deployements.
Create a conda environment:
conda create --name safetune python=3.12.0
conda activate safetune
pip install -r requirements.txt
Install the evaluation benchmark:
cd eval/lm-evaluation-harness
pip install -e .[math,vllm]
All training scripts are located in script/safety_alignment/.
You can add SAFEPATH on different models as follows:
Deepseek-R1-Distill-Qwen-7B:
bash script/safety_alignment/safepath_qwen_train.sh
Deepseek-R1-Distill-Llama-8B:
bash script/safety_alignment/safepath_llama_train.sh
All models are upload in 🤗 huggingface.
To evaluate SAFEPATH on the BeaverTails benchmark:
bash script/safety_alignment/eval.sh
You can change the model name in the script to evaluate other checkpoints.
This repository builds on Safety-Tax.
Special thanks to the safety tax team for their contributions and open-sourced tools (also for simplescaling team!).
98 followers · starred Sep 2025



