
A curated list of LLM Interpretability related material - Tutorial, Library, Survey, Paper, Blog, etc..
306
69 commits
updated Jan 22, 2026
README
Awesome-LLM-Interpretability
A curated list of LLM Interpretability related material.
ToC
- Tutorial
- History
- Code
- Survey
- Video
- Paper & Blog
Tutorial
- Concrete Steps to Get Started in Transformer Mechanistic Interpretability [Neel Nanda's blog]
- Mechanistic Interpretability Quickstart Guide [Neel Nanda's blog]
- ARENA Mechanistic Interpretability Tutorials by Callum McDougall [website]
- 200 Concrete Open Problems in Mechanistic Interpretability: Introduction by Neel Nanda [AlignmentForum]
- Transformer-specific Interpretability [EACL 2023 Tutorial]
History
- Mechanistic? [BlackBoxNLP workshop at EMNLP 2024]
- This paper explores the multiple definitions and uses of "mechanistic interpretability," tracing its evolution in NLP research and revealing a critical divide within the interpretability community.
Platform
- Neuronpedia [website]
- Accelerating researchers for Sparse Autoencoders (SAEs) by hosting models, feature dashboards, data visualizations, tooling, and more
Code
Library
- TransformerLens [github]
- A library for mechanistic interpretability of GPT-style language models
- SAELens [github]
- Training and analyzing sparse autoencoders on Language Models
- NNSight [github]
- The nnsight package enables interpreting and manipulating the internals of deep learned models.
- CircuitsVis [github]
- Mechanistic Interpretability visualizations
- baukit [github]
- Contains some methods for tracing and editing internal activations in a network.
- transformer-debugger [github]
- Transformer Debugger (TDB) is a tool developed by OpenAI's Superalignment team with the goal of supporting investigations into specific behaviors of small language models. The tool combines automated interpretability techniques with sparse autoencoders.
- pyvene [github]
- Supports customizable interventions on a range of different PyTorch modules
- Supports complex intervention schemes with an intuitive configuration format, and its interventions can be static or include trainable parameters.
- ViT-Prisma [github]
- An open-source mechanistic interpretability library for vision and multimodal models.
- pyreft [github]
- A Powerful, Parameter-Efficient, and Interpretable way of fine-tuning
Codebase
- mamba interpretability [github]
Survey
- 🌟Locate, Steer, and Improve: A Practical Survey of Actionable Mechanistic Interpretability in Large Language Models [arxiv2601]
- A Survey on Sparse Autoencoders: Interpreting the Internal Mechanisms of Large Language Models [arxiv2503]
- Representation Engineering for Large-Language Models: Survey and Research Challenges [arxiv2502]
- Toward Transparent AI: A Survey on Interpreting the Inner Structures of Deep Neural Networks [SaTML 2023] [arxiv 2207]
- Neuron-level Interpretation of Deep NLP Models: A Survey [TACL 2022]
- Explainability for Large Language Models: A Survey [TIST 2024] [arxiv 2309]
- Opening the Black Box of Large Language Models: Two Views on Holistic Interpretability [arxiv 2402]
- Usable XAI: 10 Strategies Towards Exploiting Explainability in the LLM Era [arxiv 2403]
- Mechanistic Interpretability for AI Safety -- A Review [arxiv 2404]
- A Primer on the Inner Workings of Transformer-based Language Models [arxiv 2405]
- 🌟A Practical Review of Mechanistic Interpretability for Transformer-Based Language Models [arxiv 2407]
- Internal Consistency and Self-Feedback in Large Language Models: A Survey [arxiv 2407]
- The Quest for the Right Mediator: A History, Survey, and Theoretical Grounding of Causal Interpretability [arxiv 2408]
- Attention Heads of Large Language Models: A Survey [arxiv 2409] [github]
Note: These Alignment surveys discuss the relation between Interpretability and LLM Alignment.
-
Large Language Model Alignment: A Survey [arxiv 2309]
-
AI Alignment: A Comprehensive Survey [arxiv 2310] [github] [website]
Video
- Neel Nanda's Channel [Youtube]
- Chris Olah - Looking Inside Neural Networks with Mechanistic Interpretability [Youtube]
- Concrete Open Problems in Mechanistic Interpretability: Neel Nanda at SERI MATS [Youtube]
- BlackboxNLP's Channel [Youtube]
Paper & Blog
By Source
-
🌟ICML 2024 Workshop on Mechanistic Interpretability [openreview]
-
🌟Transformer Circuits Thread [blog]
-
BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP [workshop]
-
AI Alignment Forum [forum]
-
Lesswrong [forum]
-
Neel Nanda [blog] [google scholar]
-
Mor Geva [google scholar]
-
David Bau [google scholar]
-
Jacob Steinhardt [google scholar]
-
Yonatan Belinkov [google scholar]
By Topic
Tools/Techniques/Methods
General
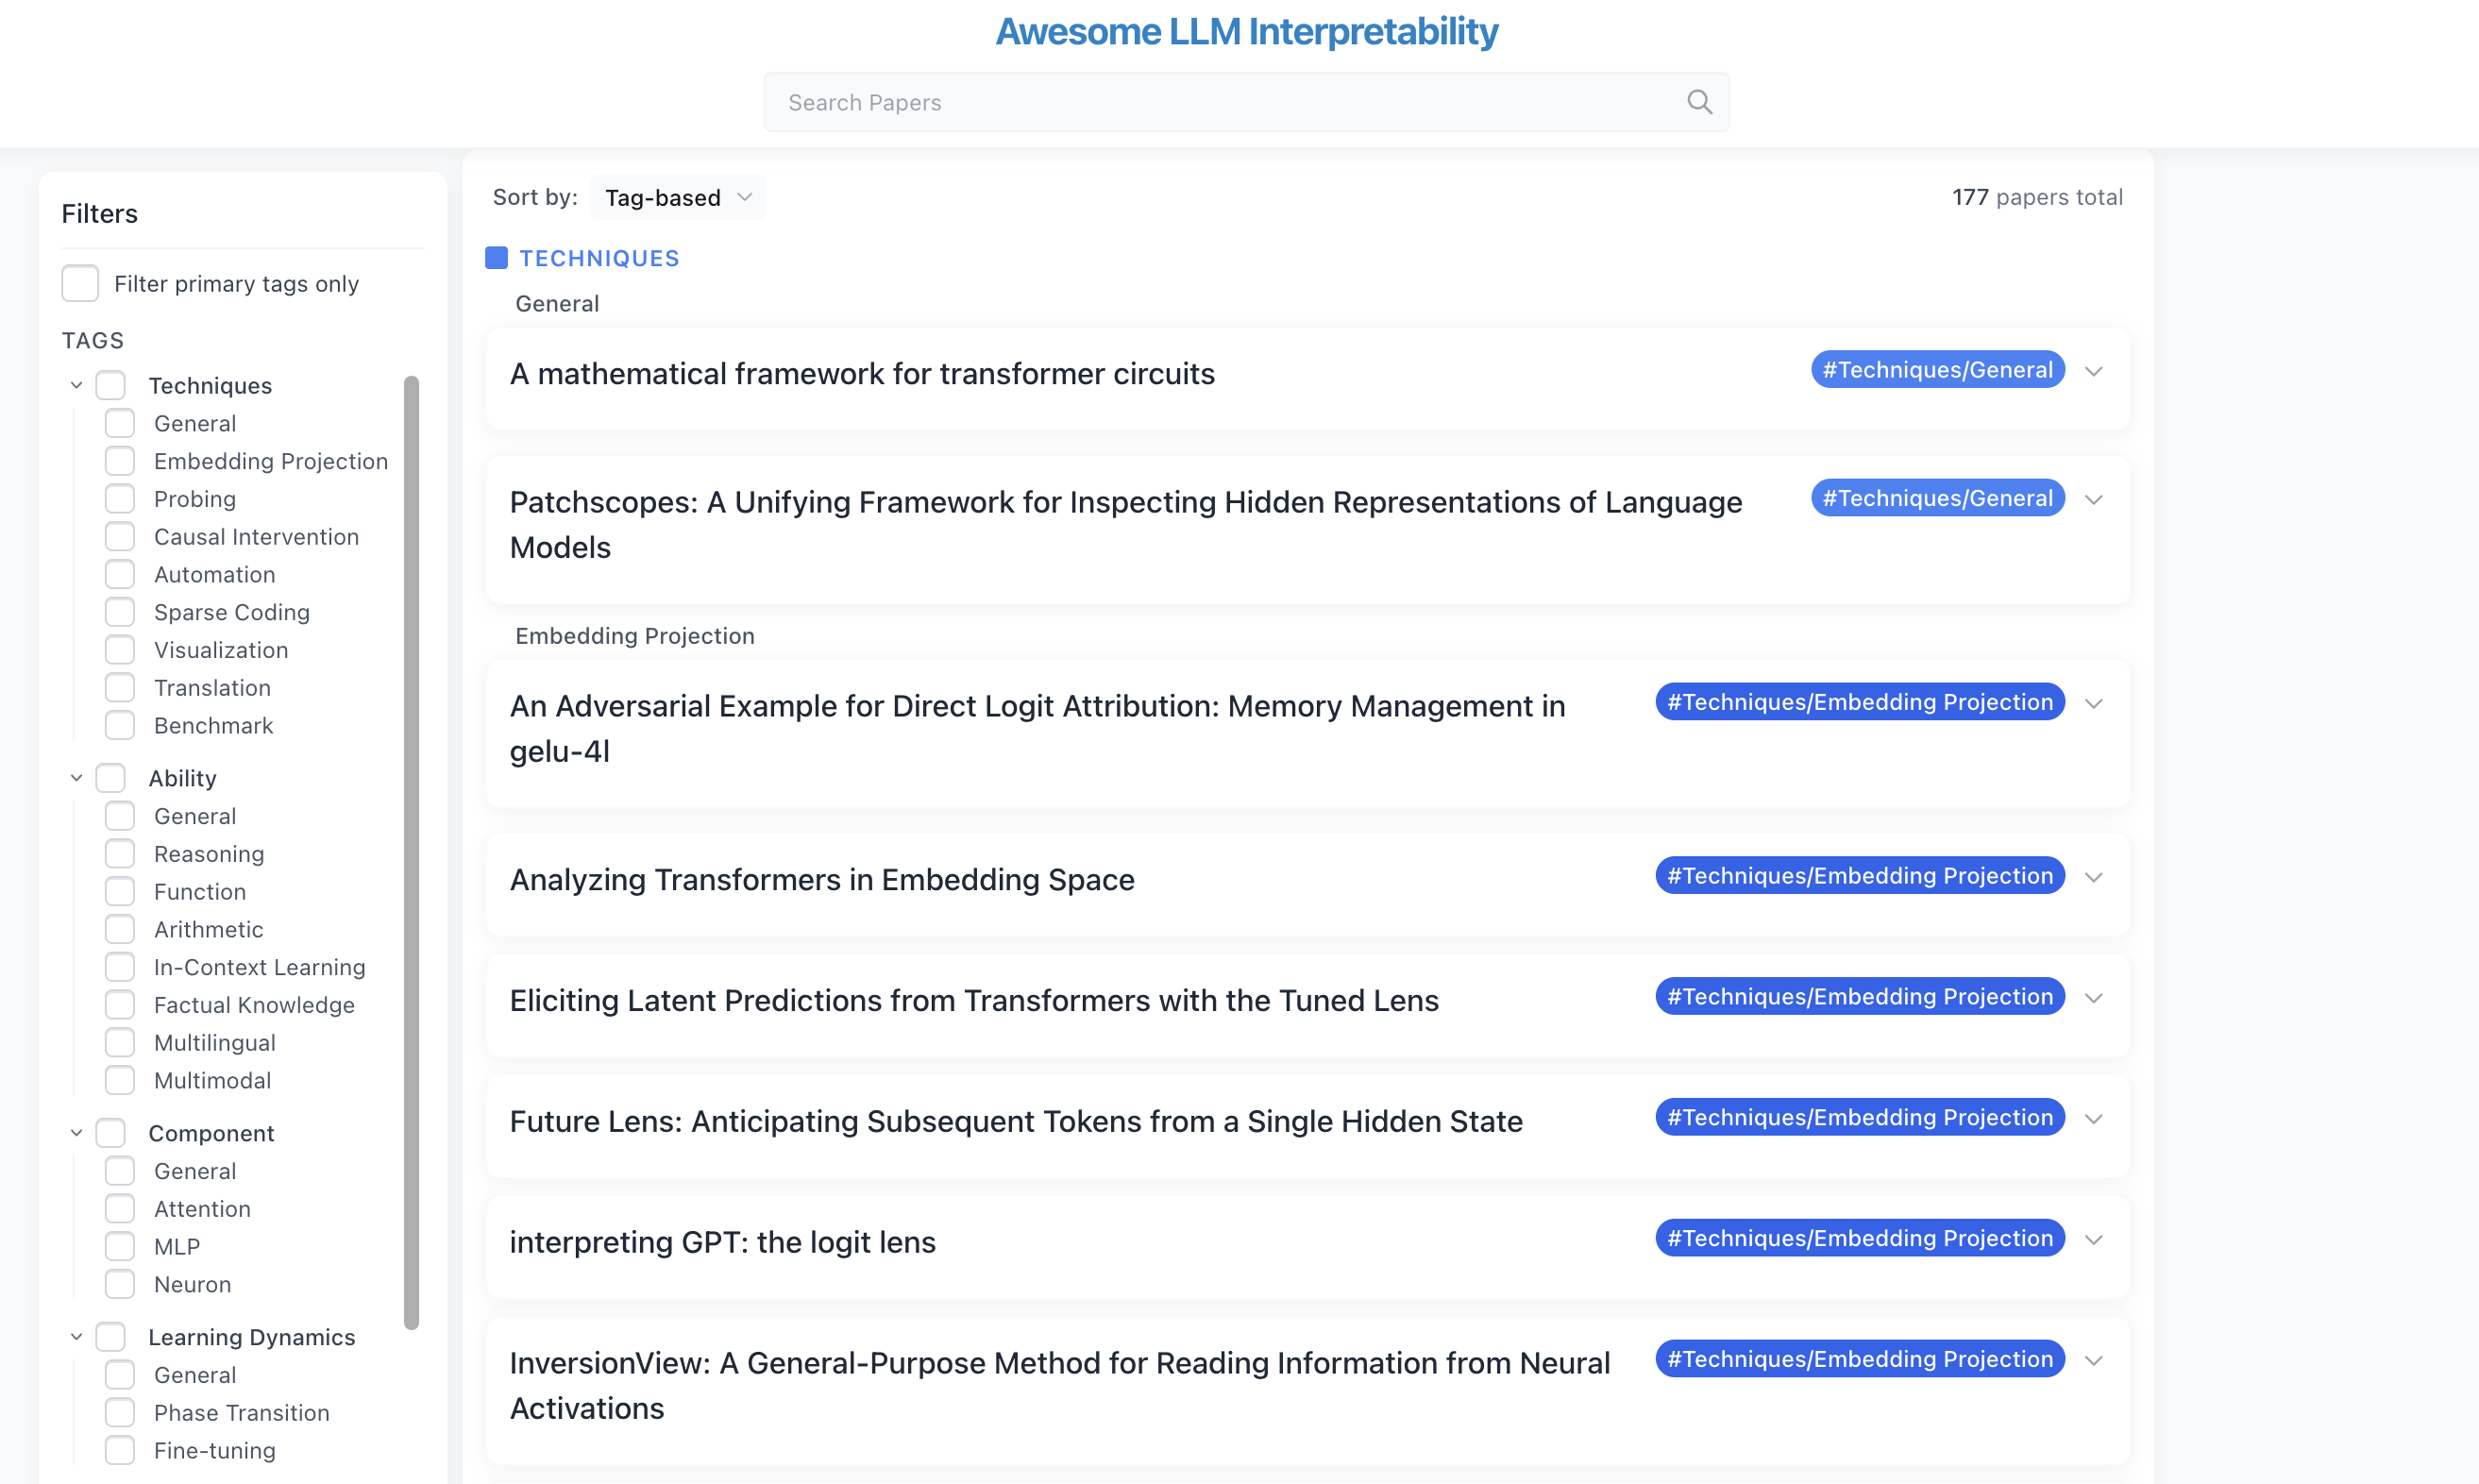
- 🌟A mathematical framework for transformer circuits [blog]
- Patchscopes: A Unifying Framework for Inspecting Hidden Representations of Language Models [arxiv]
- LatentQA: Teaching LLMs to Decode Activations Into Natural Language [arxiv]
- Activation Oracles: Training and Evaluating LLMs as General-Purpose Activation Explainers [arxiv]
- Predictive Concept Decoders: Training Scalable End-to-End Interpretability Assistants [arxiv]
Embedding Projection
-
🌟interpreting GPT: the logit lens [Lesswrong 2020]
-
🌟Analyzing Transformers in Embedding Space [ACL 2023]
-
Eliciting Latent Predictions from Transformers with the Tuned Lens [arxiv 2303]
-
An Adversarial Example for Direct Logit Attribution: Memory Management in gelu-4l arxiv 2310
-
Future Lens: Anticipating Subsequent Tokens from a Single Hidden State [CoNLL 2023]
-
SelfIE: Self-Interpretation of Large Language Model Embeddings [arxiv 2403]
-
InversionView: A General-Purpose Method for Reading Information from Neural Activations [ICML 2024 MI Workshop]
Probing
- Enhancing Neural Network Transparency through Representation Analysis [arxiv 2310] [openreview]
Causal Intervention
- Analyzing And Editing Inner Mechanisms of Backdoored Language Models [arxiv 2303]
- Finding Alignments Between Interpretable Causal Variables and Distributed Neural Representations [arxiv 2303]
- Localizing Model Behavior with Path Patching [arxiv 2304]
- Interpretability at Scale: Identifying Causal Mechanisms in Alpaca [NIPS 2023]
- Towards Best Practices of Activation Patching in Language Models: Metrics and Methods [ICLR 2024]
- Is This the Subspace You Are Looking for? An Interpretability Illusion for Subspace Activation Patching [ICLR 2024]
- A Reply to Makelov et al. (2023)'s "Interpretability Illusion" Arguments [arxiv 2401]
- CausalGym: Benchmarking causal interpretability methods on linguistic tasks [arxiv 2402]
- 🌟How to use and interpret activation patching [arxiv 2404]
Automation
- Towards Automated Circuit Discovery for Mechanistic Interpretability [NIPS 2023]
- Neuron to Graph: Interpreting Language Model Neurons at Scale [arxiv 2305] [openreview]
- Discovering Variable Binding Circuitry with Desiderata [arxiv 2307]
- Discovering Knowledge-Critical Subnetworks in Pretrained Language Models [openreview]
- Attribution Patching Outperforms Automated Circuit Discovery [arxiv 2310]
- AtP*: An efficient and scalable method for localizing LLM behaviour to components [arxiv 2403]
- Have Faith in Faithfulness: Going Beyond Circuit Overlap When Finding Model Mechanisms [arxiv 2403]
- Sparse Feature Circuits: Discovering and Editing Interpretable Causal Graphs in Language Models [arxiv 2403]
- Automatically Identifying Local and Global Circuits with Linear Computation Graphs [arxiv 2405]
- Sparse Autoencoders Enable Scalable and Reliable Circuit Identification in Language Models [arxiv 2405]
- Hypothesis Testing the Circuit Hypothesis in LLMs [ICML 2024 MI Workshop]
Sparse Coding
- 🌟Towards monosemanticity: Decomposing language models with dictionary learning [Transformer Circuits Thread]
- Sparse Autoencoders Find Highly Interpretable Features in Language Models [ICLR 2024]
- Open Source Sparse Autoencoders for all Residual Stream Layers of GPT2-Small [Alignment Forum]
- Attention SAEs Scale to GPT-2 Small [Alignment Forum]
- We Inspected Every Head In GPT-2 Small using SAEs So You Don’t Have To [Alignment Forum]
- Understanding SAE Features with the Logit Lens [Alignment Forum]
- Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet [Transformer Circuits Thread]
- Sparse Autoencoders Enable Scalable and Reliable Circuit Identification in Language Models [arxiv 2405]
- Scaling and evaluating sparse autoencoders [arxiv 2406] [code]
- Measuring Progress in Dictionary Learning for Language Model Interpretability with Board Game Models [ICML 2024 MI Workshop]
- Sparse Autoencoders Match Supervised Features for Model Steering on the IOI Task [ICML 2024 MI Workshop]
- Identifying Functionally Important Features with End-to-End Sparse Dictionary Learning [ICML 2024 MI Workshop]
- Transcoders find interpretable LLM feature circuits [ICML 2024 MI Workshop]
- Jumping Ahead: Improving Reconstruction Fidelity with JumpReLU Sparse Autoencoders [arxiv 2407]
- Sparse Autoencoders Reveal Temporal Difference Learning in Large Language Models [arxiv 2410]
- Mechanistic Permutability: Match Features Across Layers [arxiv 2410]
- Sparse Autoencoders Reveal Universal Feature Spaces Across Large Language Models [arxiv 2410]
- Investigating Sensitive Directions in GPT-2: An Improved Baseline and Comparative Analysis of SAEs [arxiv 2410]
Visualization
- Interpreting Transformer's Attention Dynamic Memory and Visualizing the Semantic Information Flow of GPT [arxiv 2305] [github]
- Sparse AutoEncoder Visulization [github]
- SAE-VIS: Announcement Post [lesswrong]
- LM Transparency Tool: Interactive Tool for Analyzing Transformer Language Models [arxiv 2404] [[github]](https://github.com/facebookresearch/ llm-transparency-tool)
Translation
- Tracr: Compiled Transformers as a Laboratory for Interpretability [arxiv 2301]
- Opening the AI black box: program synthesis via mechanistic interpretability [arxiv 2402]
- An introduction to graphical tensor notation for mechanistic interpretability [arxiv 2402]
Evaluation/Dataset/Benchmark
- Look Before You Leap: A Universal Emergent Decomposition of Retrieval Tasks in Language Models [arxiv 2312]
- RAVEL: Evaluating Interpretability Methods on Disentangling Language Model Representations [arxiv 2402]
- Towards Principled Evaluations of Sparse Autoencoders for Interpretability and Control [arxiv 2405]
- InterpBench: Semi-Synthetic Transformers for Evaluating Mechanistic Interpretability Techniques [arxiv 2407]
Task Solving/Function/Ability
General
- Circuit Component Reuse Across Tasks in Transformer Language Models [ICLR 2024 spotlight]
- Towards Universality: Studying Mechanistic Similarity Across Language Model Architectures [arxvi 2410]
- From Tokens to Words: On the Inner Lexicon of LLMs [arxiv 2410]
Reasoning
- Towards a Mechanistic Interpretation of Multi-Step Reasoning Capabilities of Language Models [EMNLP 2023]
- How Large Language Models Implement Chain-of-Thought? [openreview]
- Do Large Language Models Latently Perform Multi-Hop Reasoning? [arxiv 2402]
- How to think step-by-step: A mechanistic understanding of chain-of-thought reasoning [arxiv 2402]
- Focus on Your Question! Interpreting and Mitigating Toxic CoT Problems in Commonsense Reasoning [arxiv 2402]
- Iteration Head: A Mechanistic Study of Chain-of-Thought [arxiv 2406]
- From Sparse Dependence to Sparse Attention: Unveiling How Chain-of-Thought Enhances Transformer Sample Efficiency [arxiv 2410]
Function
- 🌟Interpretability in the wild: a circuit for indirect object identification in GPT-2 small [ICLR 2023]
- Entity Tracking in Language Models [ACL 2023]
- How does GPT-2 compute greater-than?: Interpreting mathematical abilities in a pre-trained language model [NIPS 2023]
- Can Transformers Learn to Solve Problems Recursively? [arxiv 2305]
- Analyzing And Editing Inner Mechanisms of Backdoored Language Models [NeurIPS 2023 Workshop]
- Does Circuit Analysis Interpretability Scale? Evidence from Multiple Choice Capabilities in Chinchilla [arxiv 2307]
- Refusal mechanisms: initial experiments with Llama-2-7b-chat [AlignmentForum 2312]
- Forbidden Facts: An Investigation of Competing Objectives in Llama-2 [arxiv 2312]
- How do Language Models Bind Entities in Context? [ICLR 2024]
- How Language Models Learn Context-Free Grammars? [openreview]
- 🌟A Mechanistic Understanding of Alignment Algorithms: A Case Study on DPO and Toxicity [arxiv 2401]
- Do Llamas Work in English? On the Latent Language of Multilingual Transformers [arxiv 2402]
- Evidence of Learned Look-Ahead in a Chess-Playing Neural Network [arxiv2406]
- How much do contextualized representations encode long-range context? [arxiv 2410]
Arithmetic Ability
- 🌟Progress measures for grokking via mechanistic interpretability [ICLR 2023]
- 🌟The Clock and the Pizza: Two Stories in Mechanistic Explanation of Neural Networks [NIPS 2023]
- Interpreting the Inner Mechanisms of Large Language Models in Mathematical Addition [openreview]
- Arithmetic with Language Models: from Memorization to Computation [openreview]
- Carrying over Algorithm in Transformers [openreview]
- A simple and interpretable model of grokking modular arithmetic tasks [openreview]
- Understanding Addition in Transformers [ICLR 2024]
- Increasing Trust in Language Models through the Reuse of Verified Circuits [arxiv 2402]
- Pre-trained Large Language Models Use Fourier Features to Compute Addition [arxiv 2406]
In-context Learning
- 🌟In-context learning and induction heads [Transformer Circuits Thread]
- In-Context Learning Creates Task Vectors [EMNLP 2023 Findings]
- Label Words are Anchors: An Information Flow Perspective for Understanding In-Context Learning [EMNLP 2023]
- EMNLP 2023 best paper
- LLMs Represent Contextual Tasks as Compact Function Vectors [ICLR 2024]
- Understanding In-Context Learning in Transformers and LLMs by Learning to Learn Discrete Functions [ICLR 2024]
- Where Does In-context Machine Translation Happen in Large Language Models? [openreview]
- In-Context Learning in Large Language Models: A Neuroscience-inspired Analysis of Representations [openreview]
- Analyzing Task-Encoding Tokens in Large Language Models [arxiv 2401]
- How do Large Language Models Learn In-Context? Query and Key Matrices of In-Context Heads are Two Towers for Metric Learning [arxiv 2402]
- Parallel Structures in Pre-training Data Yield In-Context Learning [arxiv 2402]
- What needs to go right for an induction head? A mechanistic study of in-context learning circuits and their formation [arxiv 2404]
- Task Diversity Shortens the ICL Plateau [arxiv 2410]
- Inference and Verbalization Functions During In-Context Learning [arxiv 2410]
Factual Knowledge
- 🌟Dissecting Recall of Factual Associations in Auto-Regressive Language Models [EMNLP 2023]
- Characterizing Mechanisms for Factual Recall in Language Models [EMNLP 2023]
- Summing Up the Facts: Additive Mechanisms behind Factual Recall in LLMs [openreview]
- A Mechanism for Solving Relational Tasks in Transformer Language Models [openreview]
- Overthinking the Truth: Understanding how Language Models Process False Demonstrations [ICLR 2024 spotlight]
- 🌟Fact Finding: Attempting to Reverse-Engineer Factual Recall on the Neuron Level [AlignmentForum 2312]
- Cutting Off the Head Ends the Conflict: A Mechanism for Interpreting and Mitigating Knowledge Conflicts in Language Models [arxiv 2402]
- Competition of Mechanisms: Tracing How Language Models Handle Facts and Counterfactuals [arxiv 2402]
- A Glitch in the Matrix? Locating and Detecting Language Model Grounding with Fakepedia [arxiv 2403]
- Mechanisms of non-factual hallucinations in language models [arxiv 2403]
- Interpreting Key Mechanisms of Factual Recall in Transformer-Based Language Models [arxiv 2403]
- Locating and Editing Factual Associations in Mamba [arxiv 2404]
- Probing Language Models on Their Knowledge Source [[arxiv 2410]](https://arxiv.org/abs/2410.05817}
Multilingual/Crosslingual
- Do Llamas Work in English? On the Latent Language of Multilingual Transformers [arxiv 2402]
- Language-Specific Neurons: The Key to Multilingual Capabilities in Large Language Models [arxiv 2402]
- How do Large Language Models Handle Multilingualism? [arxiv 2402]
- Large Language Models are Parallel Multilingual Learners [arxiv 2403]
- Understanding the role of FFNs in driving multilingual behaviour in LLMs [arxiv 2404]
- How do Llamas process multilingual text? A latent exploration through activation patching [ICML 2024 MI Workshop]
- Concept Space Alignment in Multilingual LLMs [EMNLP 2024]
- On the Similarity of Circuits across Languages: a Case Study on the Subject-verb Agreement Task [EMNLP 2024 Findings]
Multimodal
- Interpreting CLIP's Image Representation via Text-Based Decomposition [ICLR 2024 oral]
- Interpreting CLIP with Sparse Linear Concept Embeddings (SpLiCE) [NIPS 2024]
- Diffusion Lens: Interpreting Text Encoders in Text-to-Image Pipelines [arxiv 2403]
- The First to Know: How Token Distributions Reveal Hidden Knowledge in Large Vision-Language Models? [arxiv 2403]
- Understanding Information Storage and Transfer in Multi-modal Large Language Models [arxiv 2406]
- Towards Interpreting Visual Information Processing in Vision-Language Models [arxiv 2410]
- Cross-Modal Safety Mechanism Transfer in Large Vision-Language Models [arxiv 2410]
- Pixology: Probing the Linguistic and Visual Capabilities of Pixel-based Language Models [arxiv 2410]
Component
General
- The Hydra Effect: Emergent Self-repair in Language Model Computations [arxiv 2307]
- Unveiling A Core Linguistic Region in Large Language Models [arxiv 2310]
- Exploring the Residual Stream of Transformers [arxiv 2312]
- Characterizing Large Language Model Geometry Solves Toxicity Detection and Generation [arxiv 2312]
- Explorations of Self-Repair in Language Models [arxiv 2402]
- Massive Activations in Large Language Models [arxiv 2402]
- Interpreting Context Look-ups in Transformers: Investigating Attention-MLP Interactions [arxiv 2402]
- Fantastic Semantics and Where to Find Them: Investigating Which Layers of Generative LLMs Reflect Lexical Semantics [arxiv 2403]
- The Heuristic Core: Understanding Subnetwork Generalization in Pretrained Language Models [arxiv 2403]
- Localizing Paragraph Memorization in Language Models [github 2403]
Attention
-
🌟Awesome-Attention-Heads [github]
- A carefully compiled list that summarizes the diverse functions of the attention heads.
-
🌟In-context learning and induction heads [Transformer Circuits Thread]
-
On the Expressivity Role of LayerNorm in Transformers' Attention [ACL 2023 Findings]
-
On the Role of Attention in Prompt-tuning [ICML 2023]
-
Copy Suppression: Comprehensively Understanding an Attention Head [ICLR 2024]
-
Successor Heads: Recurring, Interpretable Attention Heads In The Wild [ICLR 2024]
-
A phase transition between positional and semantic learning in a solvable model of dot-product attention [arxiv 2024]
-
Retrieval Head Mechanistically Explains Long-Context Factuality [arxiv 2404]
-
Iteration Head: A Mechanistic Study of Chain-of-Thought [arxiv 2406]
-
When Attention Sink Emerges in Language Models: An Empirical View [arxiv 2410]
MLP/FFN
- 🌟Transformer Feed-Forward Layers Are Key-Value Memories [EMNLP 2021]
- Transformer Feed-Forward Layers Build Predictions by Promoting Concepts in the Vocabulary Space [EMNLP 2022]
- What does GPT store in its MLP weights? A case study of long-range dependencies [openreview]
- Understanding the role of FFNs in driving multilingual behaviour in LLMs [arxiv 2404]
Neuron
- 🌟Toy Models of Superposition [Transformer Circuits Thread]
- Knowledge Neurons in Pretrained Transformers [ACL 2022]
- Polysemanticity and Capacity in Neural Networks [arxiv 2210]
- 🌟Finding Neurons in a Haystack: Case Studies with Sparse Probing [TMLR 2023]
- DEPN: Detecting and Editing Privacy Neurons in Pretrained Language Models [EMNLP 2023]
- Neurons in Large Language Models: Dead, N-gram, Positional [arxiv 2309]
- Universal Neurons in GPT2 Language Models [arxiv 2401]
- Language-Specific Neurons: The Key to Multilingual Capabilities in Large Language Models [arxiv 2402]
- How do Large Language Models Handle Multilingualism? [arxiv 2402]
- PURE: Turning Polysemantic Neurons Into Pure Features by Identifying Relevant Circuits [arxiv 2404]
Learning Dynamics
General
- JoMA: Demystifying Multilayer Transformers via JOint Dynamics of MLP and Attention [ICLR 2024]
- Learning Associative Memories with Gradient Descent [arxiv 2402]
- Mechanics of Next Token Prediction with Self-Attention [arxiv 2402]
- The Garden of Forking Paths: Observing Dynamic Parameters Distribution in Large Language Models [arxiv 2403]
- LLM Circuit Analyses Are Consistent Across Training and Scale [ICML 2024 MI Workshop]
- Geometric Signatures of Compositionality Across a Language Model's Lifetime [arxiv 2410]
Phase Transition/Grokking
- 🌟Progress measures for grokking via mechanistic interpretability [ICLR 2023]
- A Toy Model of Universality: Reverse Engineering How Networks Learn Group Operations [ICML 2023]
- 🌟The Mechanistic Basis of Data Dependence and Abrupt Learning in an In-Context Classification Task [ICLR 2024 oral]
- Highest scores at ICLR 2024: 10, 10, 8, 8. And by one author only!
- Sudden Drops in the Loss: Syntax Acquisition, Phase Transitions, and Simplicity Bias in MLMs [ICLR 2024 spotlight]
- A simple and interpretable model of grokking modular arithmetic tasks [openreview]
- Unified View of Grokking, Double Descent and Emergent Abilities: A Perspective from Circuits Competition [arxiv 2402]
- Interpreting Grokked Transformers in Complex Modular Arithmetic [arxiv 2402]
- Towards Tracing Trustworthiness Dynamics: Revisiting Pre-training Period of Large Language Models [arxiv 2402]
- Learning to grok: Emergence of in-context learning and skill composition in modular arithmetic tasks [arxiv 2406]
- Grokked Transformers are Implicit Reasoners: A Mechanistic Journey to the Edge of Generalization [ICML 2024 MI Workshop]
Fine-tuning
- Studying Large Language Model Generalization with Influence Functions [arxiv 2308]
- Mechanistically analyzing the effects of fine-tuning on procedurally defined tasks [ICLR 2024]
- Fine-Tuning Enhances Existing Mechanisms: A Case Study on Entity Tracking [ICLR 2024]
- The Hidden Space of Transformer Language Adapters [arxiv 2402]
- Dissecting Fine-Tuning Unlearning in Large Language Models [EMNLP 2024]
Feature Representation/Probing-based
General
- Implicit Representations of Meaning in Neural Language Models [ACL 2021]
- All Roads Lead to Rome? Exploring the Invariance of Transformers' Representations [arxiv 2305]
- Observable Propagation: Uncovering Feature Vectors in Transformers [openreview]
- In-Context Learning in Large Language Models: A Neuroscience-inspired Analysis of Representations [openreview]
- Challenges with unsupervised LLM knowledge discovery [arxiv 2312]
- Still No Lie Detector for Language Models: Probing Empirical and Conceptual Roadblocks [arxiv 2307]
- Position Paper: Toward New Frameworks for Studying Model Representations [arxiv 2402]
- How Large Language Models Encode Context Knowledge? A Layer-Wise Probing Study [arxiv 2402]
- More than Correlation: Do Large Language Models Learn Causal Representations of Space [arxiv 2312]
- Do Large Language Models Mirror Cognitive Language Processing? [arxiv 2402]
- On the Scaling Laws of Geographical Representation in Language Models [arxiv 2402]
- Monotonic Representation of Numeric Properties in Language Models [arxiv 2403]
- Exploring Concept Depth: How Large Language Models Acquire Knowledge at Different Layers? [arxiv 2404]
- Simple probes can catch sleeper agents [Anthropic Blog]
- PaCE: Parsimonious Concept Engineering for Large Language Models [arxiv 2406]
- The Geometry of Categorical and Hierarchical Concepts in Large Language Models [ICML 2024 MI Workshop]
- Concept Space Alignment in Multilingual LLMs [EMNLP 2024]
- Sparse Autoencoders Reveal Universal Feature Spaces Across Large Language Models [arxiv 2410]
Linearity
- 🌟Actually, Othello-GPT Has A Linear Emergent World Representation [Neel Nanda's blog]
- Language Models Linearly Represent Sentiment [openreview]
- Language Models Represent Space and Time [openreview]
- The Geometry of Truth: Emergent Linear Structure in Large Language Model Representations of True/False Datasets [openreview]
- Linearity of Relation Decoding in Transformer Language Models [ICLR 2024]
- The Linear Representation Hypothesis and the Geometry of Large Language Models [arxiv 2311]
- Language Models Represent Beliefs of Self and Others [arxiv 2402]
- On the Origins of Linear Representations in Large Language Models [arxiv 2403]
- Refusal in LLMs is mediated by a single direction [Lesswrong 2024]
Application
Training
- Aligning Large Language Models with Human Preferences through Representation Engineering [arxiv2312]
- ReFT: Representation Finetuning for Language Models [arxiv 2404] [github]
- Direct Preference Optimization Using Sparse Feature-Level Constraints [arxiv2411]
- LLM Pretraining with Continuous Concepts [arxiv2502]
Inference-Time Intervention/Activation Steering
- 🌟Inference-Time Intervention: Eliciting Truthful Answers from a Language Model [NIPS 2023] [github]
- Activation Addition: Steering Language Models Without Optimization [arxiv 2308]
- Self-Detoxifying Language Models via Toxification Reversal [EMNLP 2023]
- DoLa: Decoding by Contrasting Layers Improves Factuality in Large Language Models [arxiv 2309]
- In-context Vectors: Making In Context Learning More Effective and Controllable Through Latent Space Steering [arxiv 2311]
- Steering Llama 2 via Contrastive Activation Addition [arxiv 2312]
- A Language Model's Guide Through Latent Space [arxiv 2402]
- Backdoor Activation Attack: Attack Large Language Models using Activation Steering for Safety-Alignment [arxiv 2311]
- Extending Activation Steering to Broad Skills and Multiple Behaviours [arxiv 2403]
- Spectral Editing of Activations for Large Language Model Alignment [arxiv 2405]
- Controlling Large Language Model Agents with Entropic Activation Steering [arxiv 2406]
- Analyzing the Generalization and Reliability of Steering Vectors [ICML 2024 MI Workshop]
- Towards Inference-time Category-wise Safety Steering for Large Language Models [arxiv 2410]
- A Timeline and Analysis for Representation Plasticity in Large Language Models [arxiv 2410]
- Semantics-Adaptive Activation Intervention for LLMs via Dynamic Steering Vectors [arxiv 2410]
Knowledge/Model Editing
- Locating and Editing Factual Associations in GPT (ROME) [NIPS 2022] [github]
- Memory-Based Model Editing at Scale [ICML 2022]
- Editing models with task arithmetic [ICLR 2023]
- Mass-Editing Memory in a Transformer [ICLR 2023]
- Detecting Edit Failures In Large Language Models: An Improved Specificity Benchmark [ACL 2023 Findings]
- Can LMs Learn New Entities from Descriptions? Challenges in Propagating Injected Knowledge [ACL 2023]
- Does Localization Inform Editing? Surprising Differences in Causality-Based Localization vs. Knowledge Editing in Language Models [NIPS 2023]
- Inspecting and Editing Knowledge Representations in Language Models [arxiv 2304] [github]
- Methods for Measuring, Updating, and Visualizing Factual Beliefs in Language Models [EACL 2023]
- Editing Common Sense in Transformers [EMNLP 2023]
- DEPN: Detecting and Editing Privacy Neurons in Pretrained Language Models [EMNLP 2023]
- MQuAKE: Assessing Knowledge Editing in Language Models via Multi-Hop Questions [EMNLP 2023]
- PMET: Precise Model Editing in a Transformer [arxiv 2308]
- Untying the Reversal Curse via Bidirectional Language Model Editing [arxiv 2310]
- Unveiling the Pitfalls of Knowledge Editing for Large Language Models [ICLR 2024]
- A Comprehensive Study of Knowledge Editing for Large Language Models [arxiv 2401]
- Trace and Edit Relation Associations in GPT [arxiv 2401]
- Model Editing with Canonical Examples [arxiv 2402]
- Updating Language Models with Unstructured Facts: Towards Practical Knowledge Editing [arxiv 2402]
- Editing Conceptual Knowledge for Large Language Models [arxiv 2403]
- Editing the Mind of Giants: An In-Depth Exploration of Pitfalls of Knowledge Editing in Large Language Models [arxiv 2406]
- Locate-then-edit for Multi-hop Factual Recall under Knowledge Editing [arxiv 2410]
- Keys to Robust Edits: from Theoretical Insights to Practical Advances [arxiv 2410]
Hallucination
- The Internal State of an LLM Knows When It's Lying [EMNLP 2023 Findings]
- Do Androids Know They're Only Dreaming of Electric Sheep? [arxiv 2312]
- INSIDE: LLMs' Internal States Retain the Power of Hallucination Detection [ICLR 2024]
- TruthX: Alleviating Hallucinations by Editing Large Language Models in Truthful Space [arxiv 2402]
- Characterizing Truthfulness in Large Language Model Generations with Local Intrinsic Dimension [arxiv 2402]
- Whispers that Shake Foundations: Analyzing and Mitigating False Premise Hallucinations in Large Language Models [arxiv 2402]
- In-Context Sharpness as Alerts: An Inner Representation Perspective for Hallucination Mitigation [arxiv 2403]
- Unsupervised Real-Time Hallucination Detection based on the Internal States of Large Language Models [arxiv 2403]
- Adaptive Activation Steering: A Tuning-Free LLM Truthfulness Improvement Method for Diverse Hallucinations Categories [arxiv 2406]
Pruning/Redundancy Analysis
- Not all Layers of LLMs are Necessary during Inference [arxiv 2403]
- ShortGPT: Layers in Large Language Models are More Redundant Than You Expect [arxiv 2403]
- The Unreasonable Ineffectiveness of the Deeper Layers [arxiv 2403]
- The Remarkable Robustness of LLMs: Stages of Inference? [ICML 2024 MI Workshop]
Contributors

66 commits

3 commits
Similar repos


A curated list of LLM Interpretability related material - Tutorial, Library, Survey, Paper, Blog, etc..
306
69 commits
updated Jan 22, 2026
README
Awesome-LLM-Interpretability
A curated list of LLM Interpretability related material.
ToC
- Tutorial
- History
- Code
- Survey
- Video
- Paper & Blog
Tutorial
- Concrete Steps to Get Started in Transformer Mechanistic Interpretability [Neel Nanda's blog]
- Mechanistic Interpretability Quickstart Guide [Neel Nanda's blog]
- ARENA Mechanistic Interpretability Tutorials by Callum McDougall [website]
- 200 Concrete Open Problems in Mechanistic Interpretability: Introduction by Neel Nanda [AlignmentForum]
- Transformer-specific Interpretability [EACL 2023 Tutorial]
History
- Mechanistic? [BlackBoxNLP workshop at EMNLP 2024]
- This paper explores the multiple definitions and uses of "mechanistic interpretability," tracing its evolution in NLP research and revealing a critical divide within the interpretability community.
Platform
- Neuronpedia [website]
- Accelerating researchers for Sparse Autoencoders (SAEs) by hosting models, feature dashboards, data visualizations, tooling, and more
Code
Library
- TransformerLens [github]
- A library for mechanistic interpretability of GPT-style language models
- SAELens [github]
- Training and analyzing sparse autoencoders on Language Models
- NNSight [github]
- The nnsight package enables interpreting and manipulating the internals of deep learned models.
- CircuitsVis [github]
- Mechanistic Interpretability visualizations
- baukit [github]
- Contains some methods for tracing and editing internal activations in a network.
- transformer-debugger [github]
- Transformer Debugger (TDB) is a tool developed by OpenAI's Superalignment team with the goal of supporting investigations into specific behaviors of small language models. The tool combines automated interpretability techniques with sparse autoencoders.
- pyvene [github]
- Supports customizable interventions on a range of different PyTorch modules
- Supports complex intervention schemes with an intuitive configuration format, and its interventions can be static or include trainable parameters.
- ViT-Prisma [github]
- An open-source mechanistic interpretability library for vision and multimodal models.
- pyreft [github]
- A Powerful, Parameter-Efficient, and Interpretable way of fine-tuning
Codebase
- mamba interpretability [github]
Survey
- 🌟Locate, Steer, and Improve: A Practical Survey of Actionable Mechanistic Interpretability in Large Language Models [arxiv2601]
- A Survey on Sparse Autoencoders: Interpreting the Internal Mechanisms of Large Language Models [arxiv2503]
- Representation Engineering for Large-Language Models: Survey and Research Challenges [arxiv2502]
- Toward Transparent AI: A Survey on Interpreting the Inner Structures of Deep Neural Networks [SaTML 2023] [arxiv 2207]
- Neuron-level Interpretation of Deep NLP Models: A Survey [TACL 2022]
- Explainability for Large Language Models: A Survey [TIST 2024] [arxiv 2309]
- Opening the Black Box of Large Language Models: Two Views on Holistic Interpretability [arxiv 2402]
- Usable XAI: 10 Strategies Towards Exploiting Explainability in the LLM Era [arxiv 2403]
- Mechanistic Interpretability for AI Safety -- A Review [arxiv 2404]
- A Primer on the Inner Workings of Transformer-based Language Models [arxiv 2405]
- 🌟A Practical Review of Mechanistic Interpretability for Transformer-Based Language Models [arxiv 2407]
- Internal Consistency and Self-Feedback in Large Language Models: A Survey [arxiv 2407]
- The Quest for the Right Mediator: A History, Survey, and Theoretical Grounding of Causal Interpretability [arxiv 2408]
- Attention Heads of Large Language Models: A Survey [arxiv 2409] [github]
Note: These Alignment surveys discuss the relation between Interpretability and LLM Alignment.
-
Large Language Model Alignment: A Survey [arxiv 2309]
-
AI Alignment: A Comprehensive Survey [arxiv 2310] [github] [website]
Video
- Neel Nanda's Channel [Youtube]
- Chris Olah - Looking Inside Neural Networks with Mechanistic Interpretability [Youtube]
- Concrete Open Problems in Mechanistic Interpretability: Neel Nanda at SERI MATS [Youtube]
- BlackboxNLP's Channel [Youtube]
Paper & Blog
By Source
-
🌟ICML 2024 Workshop on Mechanistic Interpretability [openreview]
-
🌟Transformer Circuits Thread [blog]
-
BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP [workshop]
-
AI Alignment Forum [forum]
-
Lesswrong [forum]
-
Neel Nanda [blog] [google scholar]
-
Mor Geva [google scholar]
-
David Bau [google scholar]
-
Jacob Steinhardt [google scholar]
-
Yonatan Belinkov [google scholar]
By Topic
Tools/Techniques/Methods
General
- 🌟A mathematical framework for transformer circuits [blog]
- Patchscopes: A Unifying Framework for Inspecting Hidden Representations of Language Models [arxiv]
- LatentQA: Teaching LLMs to Decode Activations Into Natural Language [arxiv]
- Activation Oracles: Training and Evaluating LLMs as General-Purpose Activation Explainers [arxiv]
- Predictive Concept Decoders: Training Scalable End-to-End Interpretability Assistants [arxiv]
Embedding Projection
-
🌟interpreting GPT: the logit lens [Lesswrong 2020]
-
🌟Analyzing Transformers in Embedding Space [ACL 2023]
-
Eliciting Latent Predictions from Transformers with the Tuned Lens [arxiv 2303]
-
An Adversarial Example for Direct Logit Attribution: Memory Management in gelu-4l arxiv 2310
-
Future Lens: Anticipating Subsequent Tokens from a Single Hidden State [CoNLL 2023]
-
SelfIE: Self-Interpretation of Large Language Model Embeddings [arxiv 2403]
-
InversionView: A General-Purpose Method for Reading Information from Neural Activations [ICML 2024 MI Workshop]
Probing
- Enhancing Neural Network Transparency through Representation Analysis [arxiv 2310] [openreview]
Causal Intervention
- Analyzing And Editing Inner Mechanisms of Backdoored Language Models [arxiv 2303]
- Finding Alignments Between Interpretable Causal Variables and Distributed Neural Representations [arxiv 2303]
- Localizing Model Behavior with Path Patching [arxiv 2304]
- Interpretability at Scale: Identifying Causal Mechanisms in Alpaca [NIPS 2023]
- Towards Best Practices of Activation Patching in Language Models: Metrics and Methods [ICLR 2024]
- Is This the Subspace You Are Looking for? An Interpretability Illusion for Subspace Activation Patching [ICLR 2024]
- A Reply to Makelov et al. (2023)'s "Interpretability Illusion" Arguments [arxiv 2401]
- CausalGym: Benchmarking causal interpretability methods on linguistic tasks [arxiv 2402]
- 🌟How to use and interpret activation patching [arxiv 2404]
Automation
- Towards Automated Circuit Discovery for Mechanistic Interpretability [NIPS 2023]
- Neuron to Graph: Interpreting Language Model Neurons at Scale [arxiv 2305] [openreview]
- Discovering Variable Binding Circuitry with Desiderata [arxiv 2307]
- Discovering Knowledge-Critical Subnetworks in Pretrained Language Models [openreview]
- Attribution Patching Outperforms Automated Circuit Discovery [arxiv 2310]
- AtP*: An efficient and scalable method for localizing LLM behaviour to components [arxiv 2403]
- Have Faith in Faithfulness: Going Beyond Circuit Overlap When Finding Model Mechanisms [arxiv 2403]
- Sparse Feature Circuits: Discovering and Editing Interpretable Causal Graphs in Language Models [arxiv 2403]
- Automatically Identifying Local and Global Circuits with Linear Computation Graphs [arxiv 2405]
- Sparse Autoencoders Enable Scalable and Reliable Circuit Identification in Language Models [arxiv 2405]
- Hypothesis Testing the Circuit Hypothesis in LLMs [ICML 2024 MI Workshop]
Sparse Coding
- 🌟Towards monosemanticity: Decomposing language models with dictionary learning [Transformer Circuits Thread]
- Sparse Autoencoders Find Highly Interpretable Features in Language Models [ICLR 2024]
- Open Source Sparse Autoencoders for all Residual Stream Layers of GPT2-Small [Alignment Forum]
- Attention SAEs Scale to GPT-2 Small [Alignment Forum]
- We Inspected Every Head In GPT-2 Small using SAEs So You Don’t Have To [Alignment Forum]
- Understanding SAE Features with the Logit Lens [Alignment Forum]
- Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet [Transformer Circuits Thread]
- Sparse Autoencoders Enable Scalable and Reliable Circuit Identification in Language Models [arxiv 2405]
- Scaling and evaluating sparse autoencoders [arxiv 2406] [code]
- Measuring Progress in Dictionary Learning for Language Model Interpretability with Board Game Models [ICML 2024 MI Workshop]
- Sparse Autoencoders Match Supervised Features for Model Steering on the IOI Task [ICML 2024 MI Workshop]
- Identifying Functionally Important Features with End-to-End Sparse Dictionary Learning [ICML 2024 MI Workshop]
- Transcoders find interpretable LLM feature circuits [ICML 2024 MI Workshop]
- Jumping Ahead: Improving Reconstruction Fidelity with JumpReLU Sparse Autoencoders [arxiv 2407]
- Sparse Autoencoders Reveal Temporal Difference Learning in Large Language Models [arxiv 2410]
- Mechanistic Permutability: Match Features Across Layers [arxiv 2410]
- Sparse Autoencoders Reveal Universal Feature Spaces Across Large Language Models [arxiv 2410]
- Investigating Sensitive Directions in GPT-2: An Improved Baseline and Comparative Analysis of SAEs [arxiv 2410]
Visualization
- Interpreting Transformer's Attention Dynamic Memory and Visualizing the Semantic Information Flow of GPT [arxiv 2305] [github]
- Sparse AutoEncoder Visulization [github]
- SAE-VIS: Announcement Post [lesswrong]
- LM Transparency Tool: Interactive Tool for Analyzing Transformer Language Models [arxiv 2404] [[github]](https://github.com/facebookresearch/ llm-transparency-tool)
Translation
- Tracr: Compiled Transformers as a Laboratory for Interpretability [arxiv 2301]
- Opening the AI black box: program synthesis via mechanistic interpretability [arxiv 2402]
- An introduction to graphical tensor notation for mechanistic interpretability [arxiv 2402]
Evaluation/Dataset/Benchmark
- Look Before You Leap: A Universal Emergent Decomposition of Retrieval Tasks in Language Models [arxiv 2312]
- RAVEL: Evaluating Interpretability Methods on Disentangling Language Model Representations [arxiv 2402]
- Towards Principled Evaluations of Sparse Autoencoders for Interpretability and Control [arxiv 2405]
- InterpBench: Semi-Synthetic Transformers for Evaluating Mechanistic Interpretability Techniques [arxiv 2407]
Task Solving/Function/Ability
General
- Circuit Component Reuse Across Tasks in Transformer Language Models [ICLR 2024 spotlight]
- Towards Universality: Studying Mechanistic Similarity Across Language Model Architectures [arxvi 2410]
- From Tokens to Words: On the Inner Lexicon of LLMs [arxiv 2410]
Reasoning
- Towards a Mechanistic Interpretation of Multi-Step Reasoning Capabilities of Language Models [EMNLP 2023]
- How Large Language Models Implement Chain-of-Thought? [openreview]
- Do Large Language Models Latently Perform Multi-Hop Reasoning? [arxiv 2402]
- How to think step-by-step: A mechanistic understanding of chain-of-thought reasoning [arxiv 2402]
- Focus on Your Question! Interpreting and Mitigating Toxic CoT Problems in Commonsense Reasoning [arxiv 2402]
- Iteration Head: A Mechanistic Study of Chain-of-Thought [arxiv 2406]
- From Sparse Dependence to Sparse Attention: Unveiling How Chain-of-Thought Enhances Transformer Sample Efficiency [arxiv 2410]
Function
- 🌟Interpretability in the wild: a circuit for indirect object identification in GPT-2 small [ICLR 2023]
- Entity Tracking in Language Models [ACL 2023]
- How does GPT-2 compute greater-than?: Interpreting mathematical abilities in a pre-trained language model [NIPS 2023]
- Can Transformers Learn to Solve Problems Recursively? [arxiv 2305]
- Analyzing And Editing Inner Mechanisms of Backdoored Language Models [NeurIPS 2023 Workshop]
- Does Circuit Analysis Interpretability Scale? Evidence from Multiple Choice Capabilities in Chinchilla [arxiv 2307]
- Refusal mechanisms: initial experiments with Llama-2-7b-chat [AlignmentForum 2312]
- Forbidden Facts: An Investigation of Competing Objectives in Llama-2 [arxiv 2312]
- How do Language Models Bind Entities in Context? [ICLR 2024]
- How Language Models Learn Context-Free Grammars? [openreview]
- 🌟A Mechanistic Understanding of Alignment Algorithms: A Case Study on DPO and Toxicity [arxiv 2401]
- Do Llamas Work in English? On the Latent Language of Multilingual Transformers [arxiv 2402]
- Evidence of Learned Look-Ahead in a Chess-Playing Neural Network [arxiv2406]
- How much do contextualized representations encode long-range context? [arxiv 2410]
Arithmetic Ability
- 🌟Progress measures for grokking via mechanistic interpretability [ICLR 2023]
- 🌟The Clock and the Pizza: Two Stories in Mechanistic Explanation of Neural Networks [NIPS 2023]
- Interpreting the Inner Mechanisms of Large Language Models in Mathematical Addition [openreview]
- Arithmetic with Language Models: from Memorization to Computation [openreview]
- Carrying over Algorithm in Transformers [openreview]
- A simple and interpretable model of grokking modular arithmetic tasks [openreview]
- Understanding Addition in Transformers [ICLR 2024]
- Increasing Trust in Language Models through the Reuse of Verified Circuits [arxiv 2402]
- Pre-trained Large Language Models Use Fourier Features to Compute Addition [arxiv 2406]
In-context Learning
- 🌟In-context learning and induction heads [Transformer Circuits Thread]
- In-Context Learning Creates Task Vectors [EMNLP 2023 Findings]
- Label Words are Anchors: An Information Flow Perspective for Understanding In-Context Learning [EMNLP 2023]
- EMNLP 2023 best paper
- LLMs Represent Contextual Tasks as Compact Function Vectors [ICLR 2024]
- Understanding In-Context Learning in Transformers and LLMs by Learning to Learn Discrete Functions [ICLR 2024]
- Where Does In-context Machine Translation Happen in Large Language Models? [openreview]
- In-Context Learning in Large Language Models: A Neuroscience-inspired Analysis of Representations [openreview]
- Analyzing Task-Encoding Tokens in Large Language Models [arxiv 2401]
- How do Large Language Models Learn In-Context? Query and Key Matrices of In-Context Heads are Two Towers for Metric Learning [arxiv 2402]
- Parallel Structures in Pre-training Data Yield In-Context Learning [arxiv 2402]
- What needs to go right for an induction head? A mechanistic study of in-context learning circuits and their formation [arxiv 2404]
- Task Diversity Shortens the ICL Plateau [arxiv 2410]
- Inference and Verbalization Functions During In-Context Learning [arxiv 2410]
Factual Knowledge
- 🌟Dissecting Recall of Factual Associations in Auto-Regressive Language Models [EMNLP 2023]
- Characterizing Mechanisms for Factual Recall in Language Models [EMNLP 2023]
- Summing Up the Facts: Additive Mechanisms behind Factual Recall in LLMs [openreview]
- A Mechanism for Solving Relational Tasks in Transformer Language Models [openreview]
- Overthinking the Truth: Understanding how Language Models Process False Demonstrations [ICLR 2024 spotlight]
- 🌟Fact Finding: Attempting to Reverse-Engineer Factual Recall on the Neuron Level [AlignmentForum 2312]
- Cutting Off the Head Ends the Conflict: A Mechanism for Interpreting and Mitigating Knowledge Conflicts in Language Models [arxiv 2402]
- Competition of Mechanisms: Tracing How Language Models Handle Facts and Counterfactuals [arxiv 2402]
- A Glitch in the Matrix? Locating and Detecting Language Model Grounding with Fakepedia [arxiv 2403]
- Mechanisms of non-factual hallucinations in language models [arxiv 2403]
- Interpreting Key Mechanisms of Factual Recall in Transformer-Based Language Models [arxiv 2403]
- Locating and Editing Factual Associations in Mamba [arxiv 2404]
- Probing Language Models on Their Knowledge Source [[arxiv 2410]](https://arxiv.org/abs/2410.05817}
Multilingual/Crosslingual
- Do Llamas Work in English? On the Latent Language of Multilingual Transformers [arxiv 2402]
- Language-Specific Neurons: The Key to Multilingual Capabilities in Large Language Models [arxiv 2402]
- How do Large Language Models Handle Multilingualism? [arxiv 2402]
- Large Language Models are Parallel Multilingual Learners [arxiv 2403]
- Understanding the role of FFNs in driving multilingual behaviour in LLMs [arxiv 2404]
- How do Llamas process multilingual text? A latent exploration through activation patching [ICML 2024 MI Workshop]
- Concept Space Alignment in Multilingual LLMs [EMNLP 2024]
- On the Similarity of Circuits across Languages: a Case Study on the Subject-verb Agreement Task [EMNLP 2024 Findings]
Multimodal
- Interpreting CLIP's Image Representation via Text-Based Decomposition [ICLR 2024 oral]
- Interpreting CLIP with Sparse Linear Concept Embeddings (SpLiCE) [NIPS 2024]
- Diffusion Lens: Interpreting Text Encoders in Text-to-Image Pipelines [arxiv 2403]
- The First to Know: How Token Distributions Reveal Hidden Knowledge in Large Vision-Language Models? [arxiv 2403]
- Understanding Information Storage and Transfer in Multi-modal Large Language Models [arxiv 2406]
- Towards Interpreting Visual Information Processing in Vision-Language Models [arxiv 2410]
- Cross-Modal Safety Mechanism Transfer in Large Vision-Language Models [arxiv 2410]
- Pixology: Probing the Linguistic and Visual Capabilities of Pixel-based Language Models [arxiv 2410]
Component
General
- The Hydra Effect: Emergent Self-repair in Language Model Computations [arxiv 2307]
- Unveiling A Core Linguistic Region in Large Language Models [arxiv 2310]
- Exploring the Residual Stream of Transformers [arxiv 2312]
- Characterizing Large Language Model Geometry Solves Toxicity Detection and Generation [arxiv 2312]
- Explorations of Self-Repair in Language Models [arxiv 2402]
- Massive Activations in Large Language Models [arxiv 2402]
- Interpreting Context Look-ups in Transformers: Investigating Attention-MLP Interactions [arxiv 2402]
- Fantastic Semantics and Where to Find Them: Investigating Which Layers of Generative LLMs Reflect Lexical Semantics [arxiv 2403]
- The Heuristic Core: Understanding Subnetwork Generalization in Pretrained Language Models [arxiv 2403]
- Localizing Paragraph Memorization in Language Models [github 2403]
Attention
-
🌟Awesome-Attention-Heads [github]
- A carefully compiled list that summarizes the diverse functions of the attention heads.
-
🌟In-context learning and induction heads [Transformer Circuits Thread]
-
On the Expressivity Role of LayerNorm in Transformers' Attention [ACL 2023 Findings]
-
On the Role of Attention in Prompt-tuning [ICML 2023]
-
Copy Suppression: Comprehensively Understanding an Attention Head [ICLR 2024]
-
Successor Heads: Recurring, Interpretable Attention Heads In The Wild [ICLR 2024]
-
A phase transition between positional and semantic learning in a solvable model of dot-product attention [arxiv 2024]
-
Retrieval Head Mechanistically Explains Long-Context Factuality [arxiv 2404]
-
Iteration Head: A Mechanistic Study of Chain-of-Thought [arxiv 2406]
-
When Attention Sink Emerges in Language Models: An Empirical View [arxiv 2410]
MLP/FFN
- 🌟Transformer Feed-Forward Layers Are Key-Value Memories [EMNLP 2021]
- Transformer Feed-Forward Layers Build Predictions by Promoting Concepts in the Vocabulary Space [EMNLP 2022]
- What does GPT store in its MLP weights? A case study of long-range dependencies [openreview]
- Understanding the role of FFNs in driving multilingual behaviour in LLMs [arxiv 2404]
Neuron
- 🌟Toy Models of Superposition [Transformer Circuits Thread]
- Knowledge Neurons in Pretrained Transformers [ACL 2022]
- Polysemanticity and Capacity in Neural Networks [arxiv 2210]
- 🌟Finding Neurons in a Haystack: Case Studies with Sparse Probing [TMLR 2023]
- DEPN: Detecting and Editing Privacy Neurons in Pretrained Language Models [EMNLP 2023]
- Neurons in Large Language Models: Dead, N-gram, Positional [arxiv 2309]
- Universal Neurons in GPT2 Language Models [arxiv 2401]
- Language-Specific Neurons: The Key to Multilingual Capabilities in Large Language Models [arxiv 2402]
- How do Large Language Models Handle Multilingualism? [arxiv 2402]
- PURE: Turning Polysemantic Neurons Into Pure Features by Identifying Relevant Circuits [arxiv 2404]
Learning Dynamics
General
- JoMA: Demystifying Multilayer Transformers via JOint Dynamics of MLP and Attention [ICLR 2024]
- Learning Associative Memories with Gradient Descent [arxiv 2402]
- Mechanics of Next Token Prediction with Self-Attention [arxiv 2402]
- The Garden of Forking Paths: Observing Dynamic Parameters Distribution in Large Language Models [arxiv 2403]
- LLM Circuit Analyses Are Consistent Across Training and Scale [ICML 2024 MI Workshop]
- Geometric Signatures of Compositionality Across a Language Model's Lifetime [arxiv 2410]
Phase Transition/Grokking
- 🌟Progress measures for grokking via mechanistic interpretability [ICLR 2023]
- A Toy Model of Universality: Reverse Engineering How Networks Learn Group Operations [ICML 2023]
- 🌟The Mechanistic Basis of Data Dependence and Abrupt Learning in an In-Context Classification Task [ICLR 2024 oral]
- Highest scores at ICLR 2024: 10, 10, 8, 8. And by one author only!
- Sudden Drops in the Loss: Syntax Acquisition, Phase Transitions, and Simplicity Bias in MLMs [ICLR 2024 spotlight]
- A simple and interpretable model of grokking modular arithmetic tasks [openreview]
- Unified View of Grokking, Double Descent and Emergent Abilities: A Perspective from Circuits Competition [arxiv 2402]
- Interpreting Grokked Transformers in Complex Modular Arithmetic [arxiv 2402]
- Towards Tracing Trustworthiness Dynamics: Revisiting Pre-training Period of Large Language Models [arxiv 2402]
- Learning to grok: Emergence of in-context learning and skill composition in modular arithmetic tasks [arxiv 2406]
- Grokked Transformers are Implicit Reasoners: A Mechanistic Journey to the Edge of Generalization [ICML 2024 MI Workshop]
Fine-tuning
- Studying Large Language Model Generalization with Influence Functions [arxiv 2308]
- Mechanistically analyzing the effects of fine-tuning on procedurally defined tasks [ICLR 2024]
- Fine-Tuning Enhances Existing Mechanisms: A Case Study on Entity Tracking [ICLR 2024]
- The Hidden Space of Transformer Language Adapters [arxiv 2402]
- Dissecting Fine-Tuning Unlearning in Large Language Models [EMNLP 2024]
Feature Representation/Probing-based
General
- Implicit Representations of Meaning in Neural Language Models [ACL 2021]
- All Roads Lead to Rome? Exploring the Invariance of Transformers' Representations [arxiv 2305]
- Observable Propagation: Uncovering Feature Vectors in Transformers [openreview]
- In-Context Learning in Large Language Models: A Neuroscience-inspired Analysis of Representations [openreview]
- Challenges with unsupervised LLM knowledge discovery [arxiv 2312]
- Still No Lie Detector for Language Models: Probing Empirical and Conceptual Roadblocks [arxiv 2307]
- Position Paper: Toward New Frameworks for Studying Model Representations [arxiv 2402]
- How Large Language Models Encode Context Knowledge? A Layer-Wise Probing Study [arxiv 2402]
- More than Correlation: Do Large Language Models Learn Causal Representations of Space [arxiv 2312]
- Do Large Language Models Mirror Cognitive Language Processing? [arxiv 2402]
- On the Scaling Laws of Geographical Representation in Language Models [arxiv 2402]
- Monotonic Representation of Numeric Properties in Language Models [arxiv 2403]
- Exploring Concept Depth: How Large Language Models Acquire Knowledge at Different Layers? [arxiv 2404]
- Simple probes can catch sleeper agents [Anthropic Blog]
- PaCE: Parsimonious Concept Engineering for Large Language Models [arxiv 2406]
- The Geometry of Categorical and Hierarchical Concepts in Large Language Models [ICML 2024 MI Workshop]
- Concept Space Alignment in Multilingual LLMs [EMNLP 2024]
- Sparse Autoencoders Reveal Universal Feature Spaces Across Large Language Models [arxiv 2410]
Linearity
- 🌟Actually, Othello-GPT Has A Linear Emergent World Representation [Neel Nanda's blog]
- Language Models Linearly Represent Sentiment [openreview]
- Language Models Represent Space and Time [openreview]
- The Geometry of Truth: Emergent Linear Structure in Large Language Model Representations of True/False Datasets [openreview]
- Linearity of Relation Decoding in Transformer Language Models [ICLR 2024]
- The Linear Representation Hypothesis and the Geometry of Large Language Models [arxiv 2311]
- Language Models Represent Beliefs of Self and Others [arxiv 2402]
- On the Origins of Linear Representations in Large Language Models [arxiv 2403]
- Refusal in LLMs is mediated by a single direction [Lesswrong 2024]
Application
Training
- Aligning Large Language Models with Human Preferences through Representation Engineering [arxiv2312]
- ReFT: Representation Finetuning for Language Models [arxiv 2404] [github]
- Direct Preference Optimization Using Sparse Feature-Level Constraints [arxiv2411]
- LLM Pretraining with Continuous Concepts [arxiv2502]
Inference-Time Intervention/Activation Steering
- 🌟Inference-Time Intervention: Eliciting Truthful Answers from a Language Model [NIPS 2023] [github]
- Activation Addition: Steering Language Models Without Optimization [arxiv 2308]
- Self-Detoxifying Language Models via Toxification Reversal [EMNLP 2023]
- DoLa: Decoding by Contrasting Layers Improves Factuality in Large Language Models [arxiv 2309]
- In-context Vectors: Making In Context Learning More Effective and Controllable Through Latent Space Steering [arxiv 2311]
- Steering Llama 2 via Contrastive Activation Addition [arxiv 2312]
- A Language Model's Guide Through Latent Space [arxiv 2402]
- Backdoor Activation Attack: Attack Large Language Models using Activation Steering for Safety-Alignment [arxiv 2311]
- Extending Activation Steering to Broad Skills and Multiple Behaviours [arxiv 2403]
- Spectral Editing of Activations for Large Language Model Alignment [arxiv 2405]
- Controlling Large Language Model Agents with Entropic Activation Steering [arxiv 2406]
- Analyzing the Generalization and Reliability of Steering Vectors [ICML 2024 MI Workshop]
- Towards Inference-time Category-wise Safety Steering for Large Language Models [arxiv 2410]
- A Timeline and Analysis for Representation Plasticity in Large Language Models [arxiv 2410]
- Semantics-Adaptive Activation Intervention for LLMs via Dynamic Steering Vectors [arxiv 2410]
Knowledge/Model Editing
- Locating and Editing Factual Associations in GPT (ROME) [NIPS 2022] [github]
- Memory-Based Model Editing at Scale [ICML 2022]
- Editing models with task arithmetic [ICLR 2023]
- Mass-Editing Memory in a Transformer [ICLR 2023]
- Detecting Edit Failures In Large Language Models: An Improved Specificity Benchmark [ACL 2023 Findings]
- Can LMs Learn New Entities from Descriptions? Challenges in Propagating Injected Knowledge [ACL 2023]
- Does Localization Inform Editing? Surprising Differences in Causality-Based Localization vs. Knowledge Editing in Language Models [NIPS 2023]
- Inspecting and Editing Knowledge Representations in Language Models [arxiv 2304] [github]
- Methods for Measuring, Updating, and Visualizing Factual Beliefs in Language Models [EACL 2023]
- Editing Common Sense in Transformers [EMNLP 2023]
- DEPN: Detecting and Editing Privacy Neurons in Pretrained Language Models [EMNLP 2023]
- MQuAKE: Assessing Knowledge Editing in Language Models via Multi-Hop Questions [EMNLP 2023]
- PMET: Precise Model Editing in a Transformer [arxiv 2308]
- Untying the Reversal Curse via Bidirectional Language Model Editing [arxiv 2310]
- Unveiling the Pitfalls of Knowledge Editing for Large Language Models [ICLR 2024]
- A Comprehensive Study of Knowledge Editing for Large Language Models [arxiv 2401]
- Trace and Edit Relation Associations in GPT [arxiv 2401]
- Model Editing with Canonical Examples [arxiv 2402]
- Updating Language Models with Unstructured Facts: Towards Practical Knowledge Editing [arxiv 2402]
- Editing Conceptual Knowledge for Large Language Models [arxiv 2403]
- Editing the Mind of Giants: An In-Depth Exploration of Pitfalls of Knowledge Editing in Large Language Models [arxiv 2406]
- Locate-then-edit for Multi-hop Factual Recall under Knowledge Editing [arxiv 2410]
- Keys to Robust Edits: from Theoretical Insights to Practical Advances [arxiv 2410]
Hallucination
- The Internal State of an LLM Knows When It's Lying [EMNLP 2023 Findings]
- Do Androids Know They're Only Dreaming of Electric Sheep? [arxiv 2312]
- INSIDE: LLMs' Internal States Retain the Power of Hallucination Detection [ICLR 2024]
- TruthX: Alleviating Hallucinations by Editing Large Language Models in Truthful Space [arxiv 2402]
- Characterizing Truthfulness in Large Language Model Generations with Local Intrinsic Dimension [arxiv 2402]
- Whispers that Shake Foundations: Analyzing and Mitigating False Premise Hallucinations in Large Language Models [arxiv 2402]
- In-Context Sharpness as Alerts: An Inner Representation Perspective for Hallucination Mitigation [arxiv 2403]
- Unsupervised Real-Time Hallucination Detection based on the Internal States of Large Language Models [arxiv 2403]
- Adaptive Activation Steering: A Tuning-Free LLM Truthfulness Improvement Method for Diverse Hallucinations Categories [arxiv 2406]
Pruning/Redundancy Analysis
- Not all Layers of LLMs are Necessary during Inference [arxiv 2403]
- ShortGPT: Layers in Large Language Models are More Redundant Than You Expect [arxiv 2403]
- The Unreasonable Ineffectiveness of the Deeper Layers [arxiv 2403]
- The Remarkable Robustness of LLMs: Stages of Inference? [ICML 2024 MI Workshop]
Similar repos
Contributors
66 commits
3 commits