[AAAI 2026] Official Code for VQAThinker: Exploring Generalizable and Explainable Video Quality Assessment via Reinforcement Learning
Python
32
16 commits
updated Nov 28, 2025


This is the official code of VQAThinker, the first open-source NR-VQA model enhanced via reinforcement learning, capable of performing both video quality scoring and understanding.
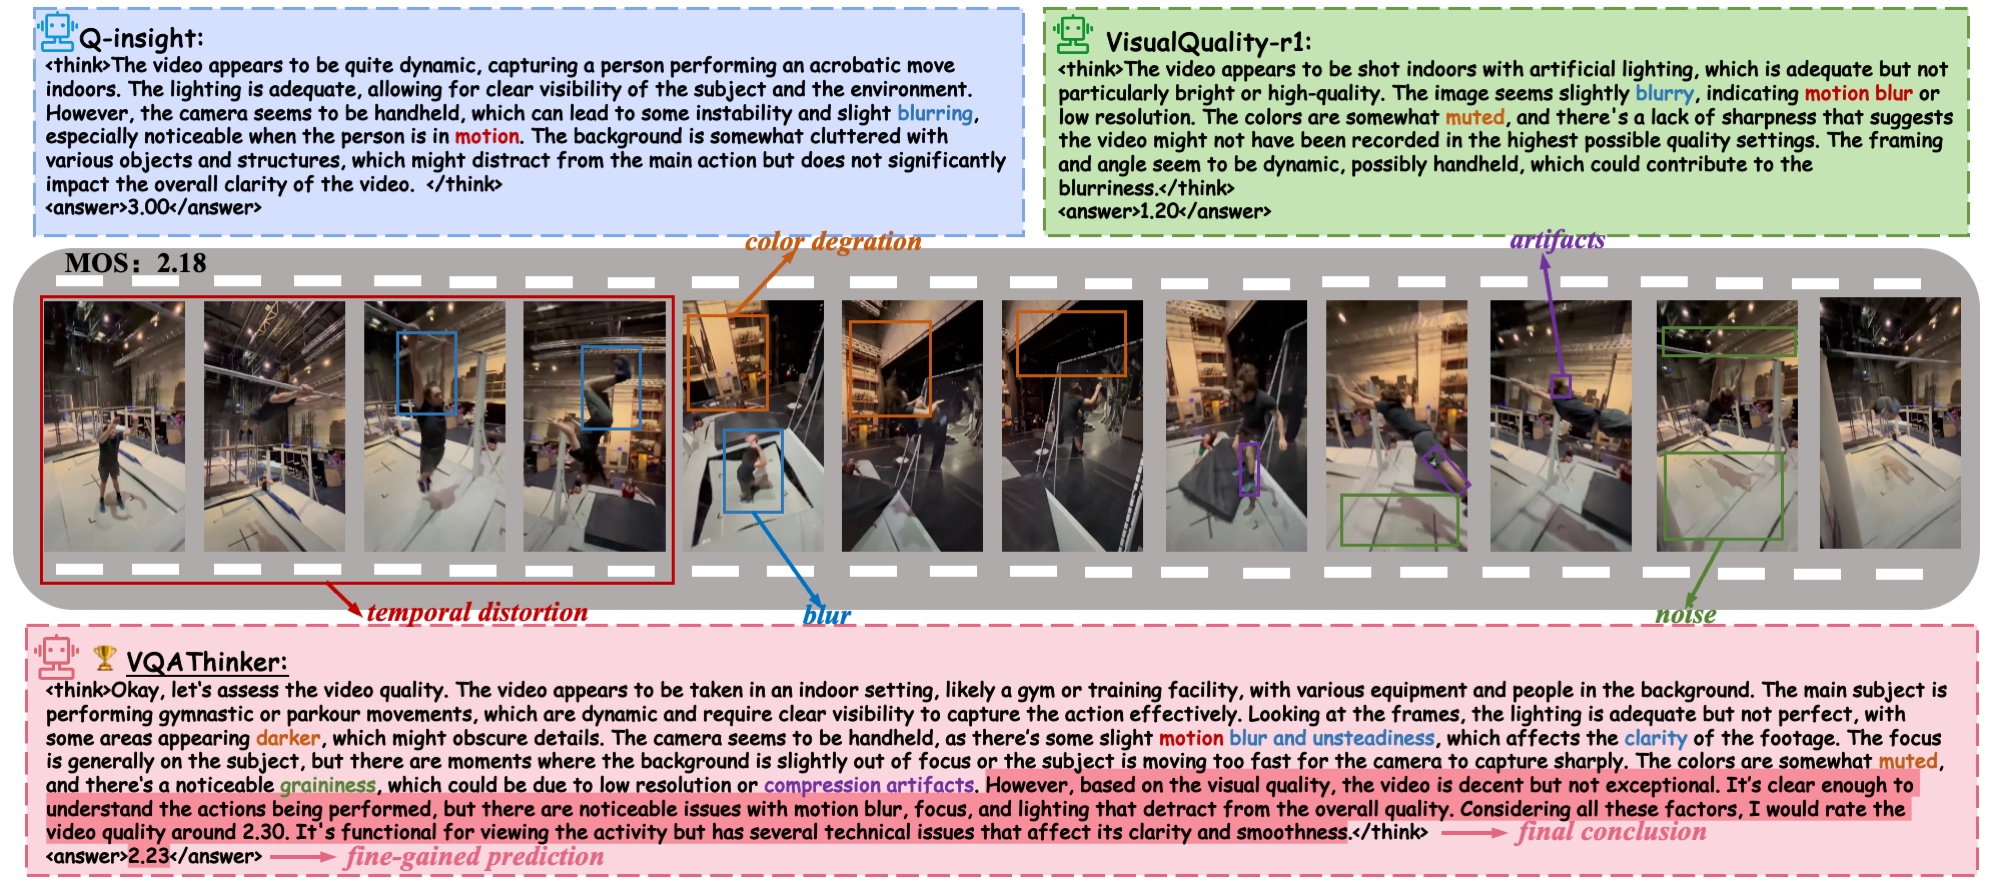
Video quality assessment (VQA) aims to objectively quantify perceptual quality degradation in alignment with human visual perception. Despite recent advances, existing VQA models still suffer from two critical limitations: poor generalization to out-of-distribution (OOD) videos and limited explainability, which restrict their applicability in real-world scenarios.
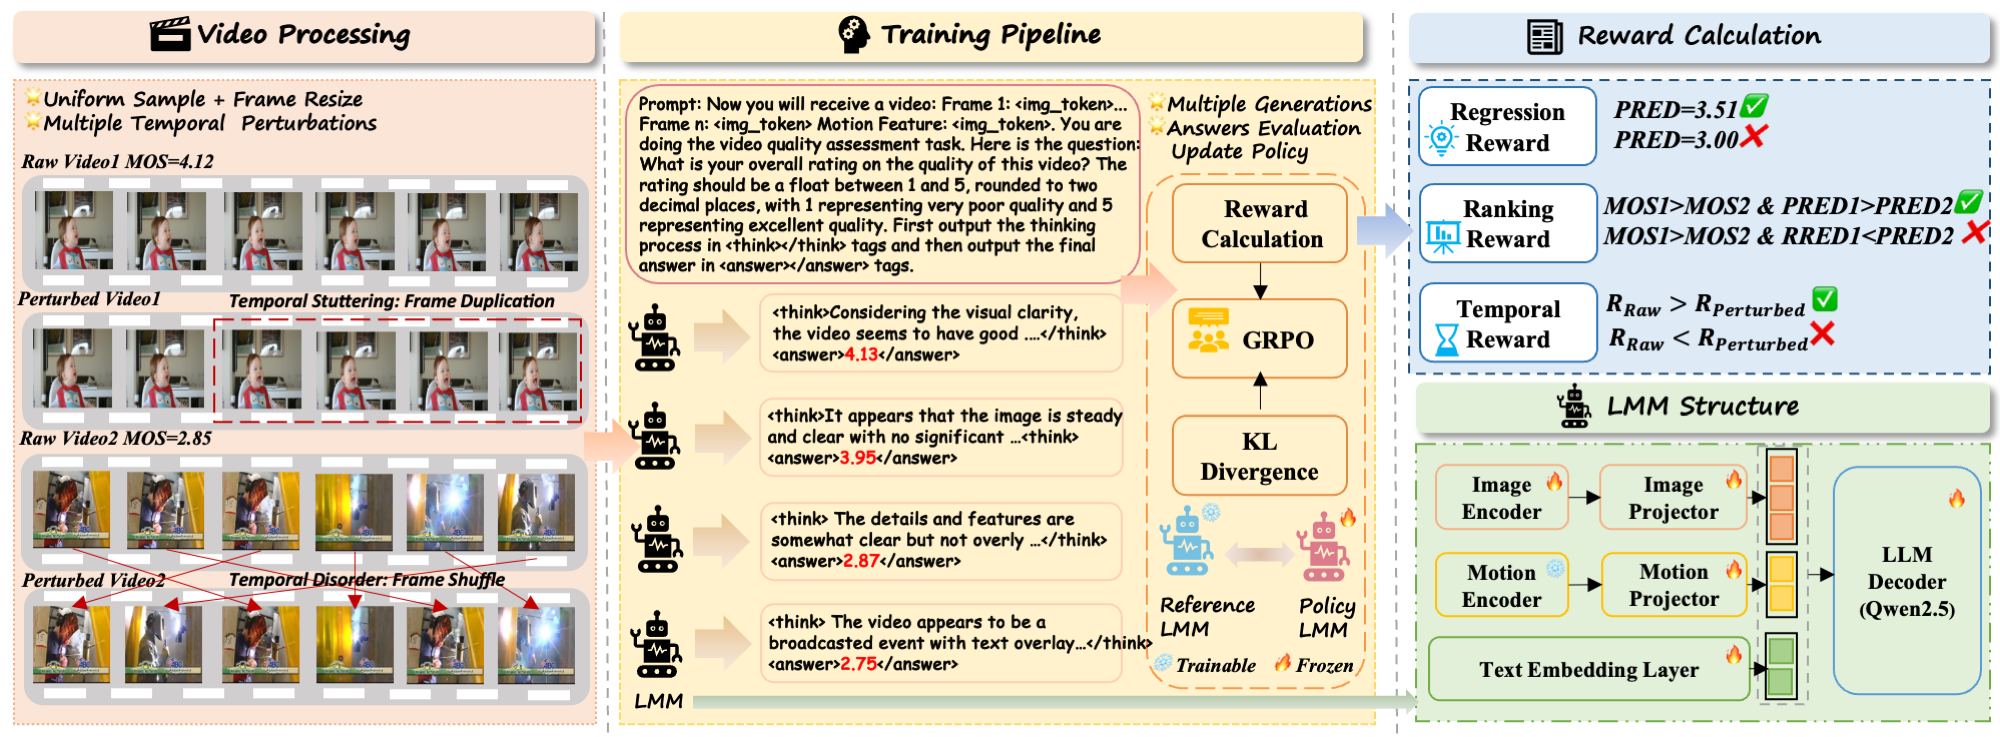
To address these challenges, we propose VQAThinker, a reasoning-based VQA framework that leverages large multimodal models (LMMs) with reinforcement learning to jointly model video quality understanding and scoring, emulating human perceptual decision-making.
Specifically, we adopt group relative policy optimization (GRPO), a rule-guided reinforcement learning algorithm that enables reasoning over video quality under score-level supervision, and introduce three VQA-specific rewards:
Extensive experiments demonstrate that VQAThinker achieves state-of-the-art performance on both in-domain and OOD VQA benchmarks, showing strong generalization for video quality scoring. Furthermore, evaluations on video quality understanding tasks validate its superiority in distortion attribution and quality description compared to existing explainable VQA models and LMMs. These findings demonstrate that reinforcement learning offers an effective pathway toward building generalizable and explainable VQA models solely with score-level supervision.
conda create -n vqathinker python=3.11
conda activate vqathinker
bash setup.sh
cd test
You need to download the pre-trained model weights before running inference: 👉InternVL3-VQAThinker-8B.
The weights should be saved in the folder InternVL3-VQAThinker-8B/.
⚠️ Note: When evaluating your own fine-tuned checkpoint, please replace the modeling_internvl_chat.py file in the checkpoint directory with the version provided in the test directory.
python single_infer.py
Before running, please modify the parameters in single_infer.py:
python batch_infer.py
This script is used to evaluate the 10 datasets reported in the paper.
Before running, please modify the parameters in batch_infer.py:
⚠️ Note: The default batch_size is 16, which requires at least 48 GB of GPU memory for testing.
Adjust batch_size according to your available GPU memory.
cd train
⚠️ Note: First, replace the modeling_internvl_chat.py file under the InternVL3-8B/ checkpoint directory with the version provided in the train directory.
bash run_scripts/run_grpo_vqa_internvl.sh
To enable the temporal reward, set the --temporal flag to true.
For using your own dataset, please format the data as a JSONL file. The expected format is shown below:
```json
{"id": 0, "dataset_name": "LSVQ", "image": ["yfcc-batch6/4134.mp4"], "conversations": [{"from": "human", "value": "You are doing the video quality assessment task. Here is the question: What is your overall rating on the quality of this video? The rating should be a float between 1 and 5, rounded to two decimal places, with 1 representing very poor quality and 5 representing excellent quality."}, {"from": "gpt", "value": 2.611842}]}
{"id": 1, "dataset_name": "LSVQ", "image": ["ia-batch14/btvnj-MIF_711_Holiday_Fire_Safety.mp4"], "conversations": [{"from": "human", "value": "You are doing the video quality assessment task. Here is the question: What is your overall rating on the quality of this video? The rating should be a float between 1 and 5, rounded to two decimal places, with 1 representing very poor quality and 5 representing excellent quality."}, {"from": "gpt", "value": 3.232857}]}
...
If you find this code is useful for your research, please cite:
@article{cao2025vqathinker,
  title={Vqathinker: Exploring generalizable and explainable video quality assessment via reinforcement learning},
  author={Cao, Linhan and Sun, Wei and Zhang, Weixia and Zhu, Xiangyang and Jia, Jun and Zhang, Kaiwei and Zhu, Dandan and Zhai, Guangtao and Min, Xiongkuo},
  journal={arXiv preprint arXiv:2508.06051},
  year={2025}
}
[AAAI 2026] Official Code for VQAThinker: Exploring Generalizable and Explainable Video Quality Assessment via Reinforcement Learning
Python
32
16 commits
updated Nov 28, 2025
This is the official code of VQAThinker, the first open-source NR-VQA model enhanced via reinforcement learning, capable of performing both video quality scoring and understanding.
Video quality assessment (VQA) aims to objectively quantify perceptual quality degradation in alignment with human visual perception. Despite recent advances, existing VQA models still suffer from two critical limitations: poor generalization to out-of-distribution (OOD) videos and limited explainability, which restrict their applicability in real-world scenarios.
To address these challenges, we propose VQAThinker, a reasoning-based VQA framework that leverages large multimodal models (LMMs) with reinforcement learning to jointly model video quality understanding and scoring, emulating human perceptual decision-making.
Specifically, we adopt group relative policy optimization (GRPO), a rule-guided reinforcement learning algorithm that enables reasoning over video quality under score-level supervision, and introduce three VQA-specific rewards:
Extensive experiments demonstrate that VQAThinker achieves state-of-the-art performance on both in-domain and OOD VQA benchmarks, showing strong generalization for video quality scoring. Furthermore, evaluations on video quality understanding tasks validate its superiority in distortion attribution and quality description compared to existing explainable VQA models and LMMs. These findings demonstrate that reinforcement learning offers an effective pathway toward building generalizable and explainable VQA models solely with score-level supervision.
conda create -n vqathinker python=3.11
conda activate vqathinker
bash setup.sh
cd test
You need to download the pre-trained model weights before running inference: 👉InternVL3-VQAThinker-8B.
The weights should be saved in the folder InternVL3-VQAThinker-8B/.
⚠️ Note: When evaluating your own fine-tuned checkpoint, please replace the modeling_internvl_chat.py file in the checkpoint directory with the version provided in the test directory.
python single_infer.py
Before running, please modify the parameters in single_infer.py:
python batch_infer.py
This script is used to evaluate the 10 datasets reported in the paper.
Before running, please modify the parameters in batch_infer.py:
⚠️ Note: The default batch_size is 16, which requires at least 48 GB of GPU memory for testing.
Adjust batch_size according to your available GPU memory.
cd train
⚠️ Note: First, replace the modeling_internvl_chat.py file under the InternVL3-8B/ checkpoint directory with the version provided in the train directory.
bash run_scripts/run_grpo_vqa_internvl.sh
To enable the temporal reward, set the --temporal flag to true.
For using your own dataset, please format the data as a JSONL file. The expected format is shown below:
```json
{"id": 0, "dataset_name": "LSVQ", "image": ["yfcc-batch6/4134.mp4"], "conversations": [{"from": "human", "value": "You are doing the video quality assessment task. Here is the question: What is your overall rating on the quality of this video? The rating should be a float between 1 and 5, rounded to two decimal places, with 1 representing very poor quality and 5 representing excellent quality."}, {"from": "gpt", "value": 2.611842}]}
{"id": 1, "dataset_name": "LSVQ", "image": ["ia-batch14/btvnj-MIF_711_Holiday_Fire_Safety.mp4"], "conversations": [{"from": "human", "value": "You are doing the video quality assessment task. Here is the question: What is your overall rating on the quality of this video? The rating should be a float between 1 and 5, rounded to two decimal places, with 1 representing very poor quality and 5 representing excellent quality."}, {"from": "gpt", "value": 3.232857}]}
...
If you find this code is useful for your research, please cite:
@article{cao2025vqathinker,
  title={Vqathinker: Exploring generalizable and explainable video quality assessment via reinforcement learning},
  author={Cao, Linhan and Sun, Wei and Zhang, Weixia and Zhu, Xiangyang and Jia, Jun and Zhang, Kaiwei and Zhu, Dandan and Zhai, Guangtao and Min, Xiongkuo},
  journal={arXiv preprint arXiv:2508.06051},
  year={2025}
}



