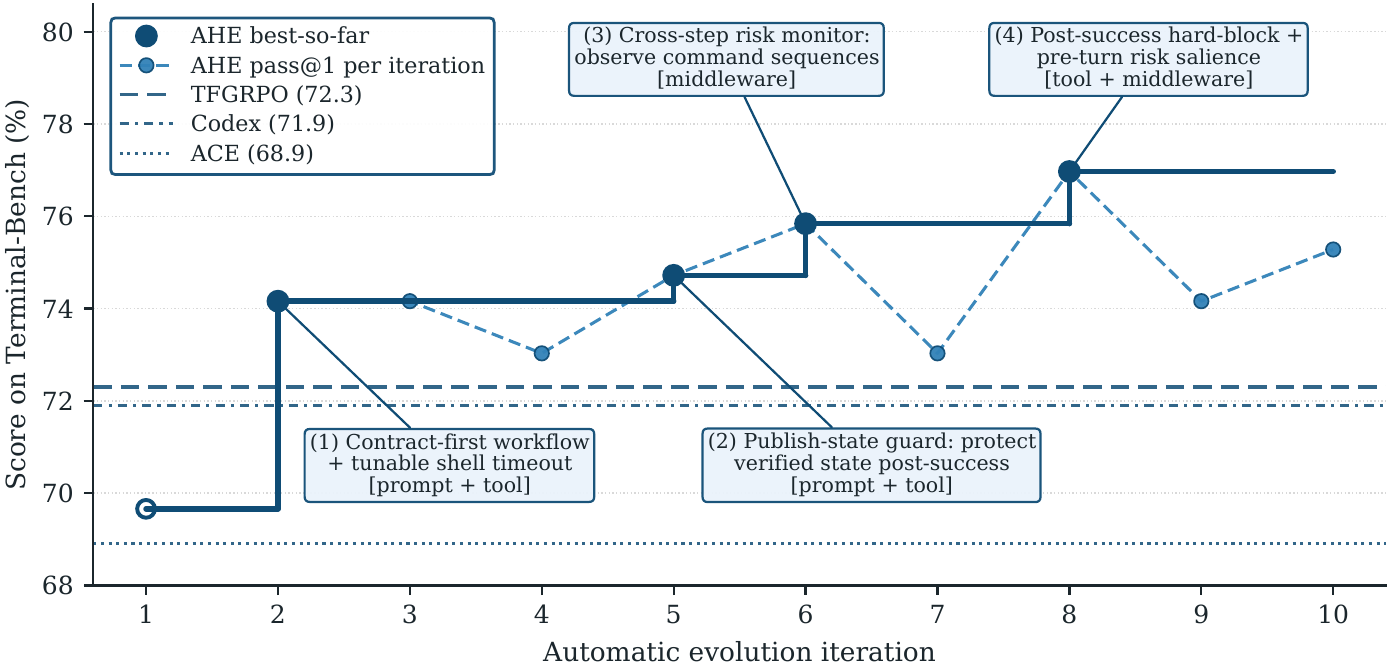
Official AHE code — Agentic Harness Engineering: observability-driven automatic evolution of coding-agent harnesses (concurrent w/ meta-harness). NexAU-AHE reaches 84.7% ± 2.1 pass@1 on Terminal-Bench 2 (GPT-5.5). Lifts GPT-5.4 69.7→77.0% over 10 iters, beats Codex/ACE/Training-Free GRPO; frozen harness transfers to SWE-bench-Verified.
See the code




English | 简体中文
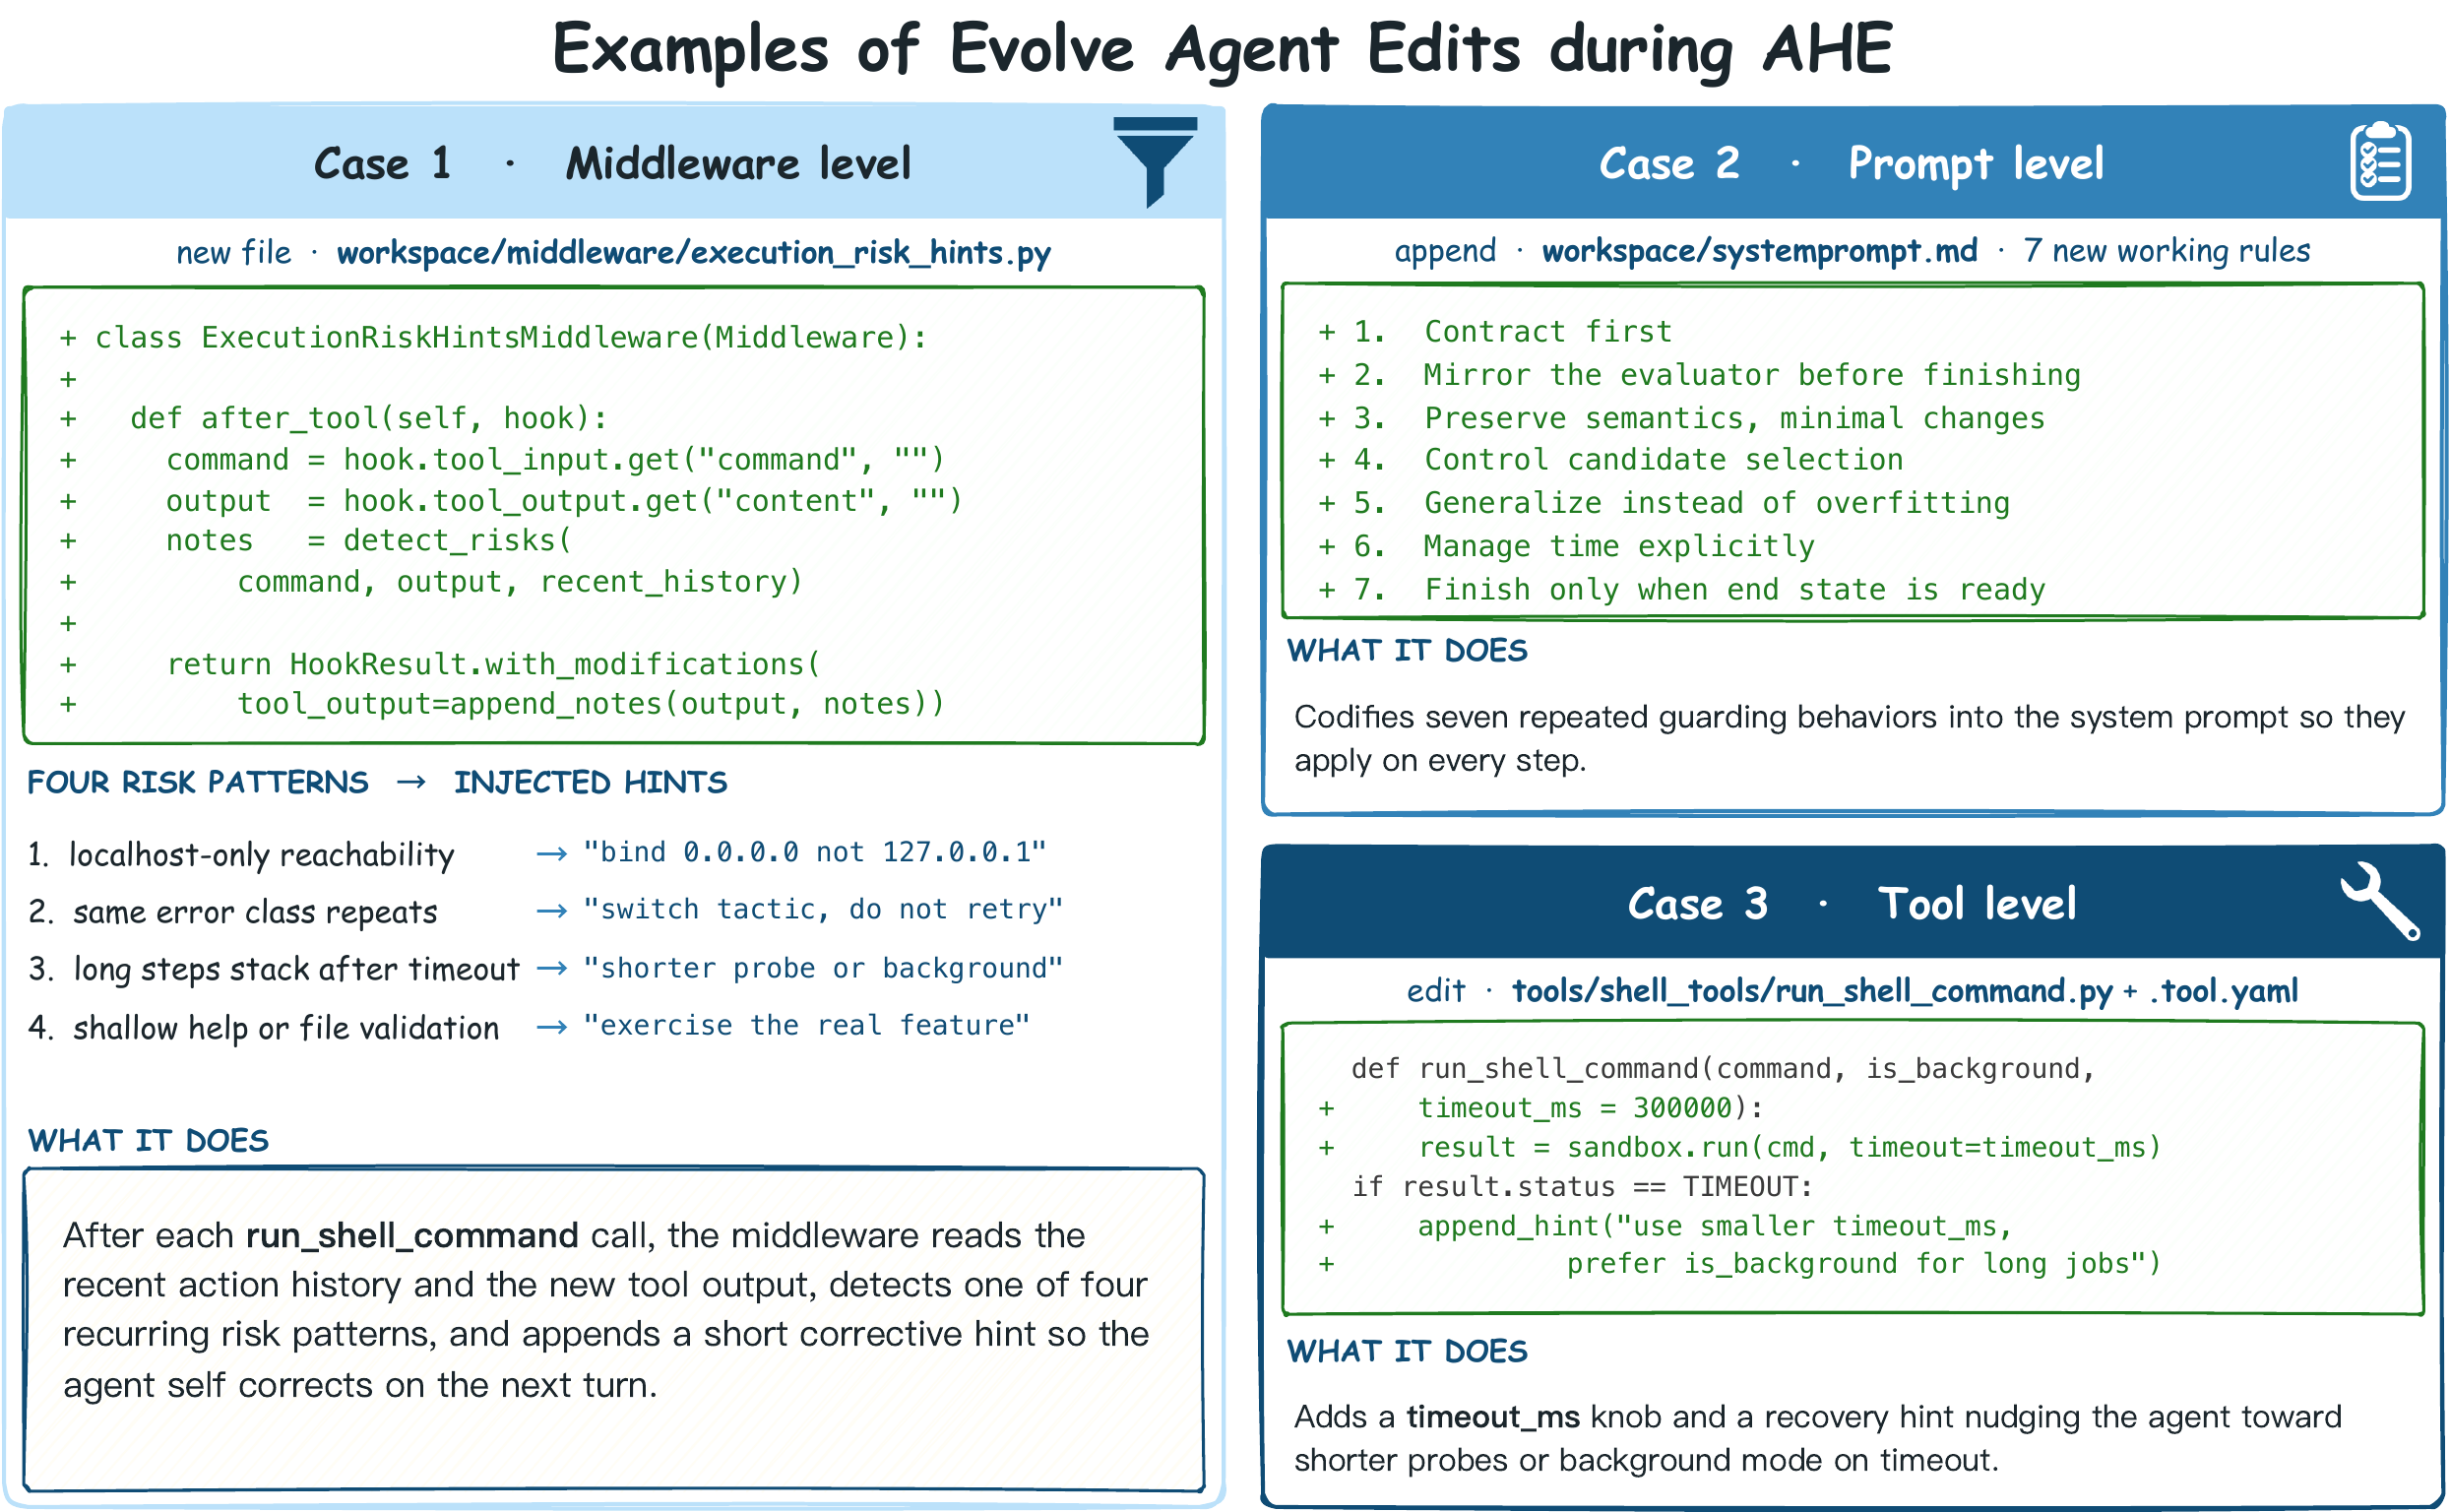
AHE (Agentic Harness Engineering) is an open observability system for automatically evolving the harness around a coding agent. The base model is held fixed; what evolves are the harness components — system prompts, tool descriptions, tool implementations, middleware, skills, sub-agents, and long-term memory.
AHE rests on three observability layers:
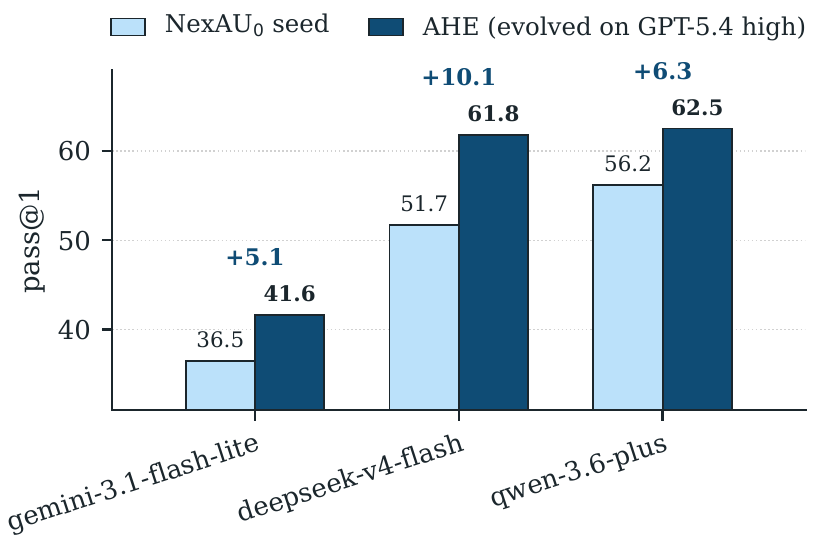
Across ten evaluate → analyze → improve iterations, AHE (Agentic Harness Engineering) lifts Terminal-Bench 2 pass@1 from 69.7% to 77.0% on GPT-5.4, surpasses the hand-written Codex (71.9%) and the self-evolving ACE and TF-GRPO baselines, and produces a frozen harness that transfers without re-evolution to SWE-bench-verified and to four alternate base models, indicating that the evolved components encode general engineering experience rather than benchmark-specific tuning.
# macOS
brew install uv tmux

# Linux
curl -LsSf https://astral.sh/uv/install.sh | sh
sudo apt install -y tmux
git clone https://github.com/Curry09/agentic-harness-engineering.git
cd agentic-harness-engineering
uv sync
uv syncinstalls every dependency declared inpyproject.toml.
cp .env.example .env
Edit .env. At minimum, set:
| Variable | Purpose |
|---|---|
LLM_API_KEY / LLM_BASE_URL | Main LLM endpoint (code_agent and evolve_agent both consume it) |
E2B_API_KEY | E2B sandbox — see the next subsection for SaaS vs. self-hosted |
SERPER_API_KEY | Web search used by evolve_agent |
ADB_LLM_* and GPT54_LLM_* are optional — leave them unset to fall back to LLM_*, or set them to point ADB / the gpt-5.4 experiment at a stronger model. LANGFUSE_*, BP_HTML_PARSER_*, and FEISHU_WEBHOOK are all optional observability / convenience hooks; see .env.example for the full list.
AHE runs every rollout inside an E2B sandbox. Two deployment modes are supported:
SaaS E2B (default). Set only E2B_API_KEY and leave E2B_API_URL / E2B_DOMAIN unset (or commented out). The SDK talks to e2b.dev automatically.
⚠️ Concurrency cap. SaaS E2B enforces a per-account concurrent sandbox limit tied to your tier. If harbor tries to spawn more sandboxes than the cap allows, the extra sandboxes fail to start and the iteration stalls. Before raising parallelism in your harbor / experiment config, check your tier's quota and stay safely under it.
Self-hosted E2B cluster. Set E2B_API_KEY and point the SDK at your cluster:
E2B_API_KEY="your_e2b_key"
E2B_API_URL="https://your-e2b-host.example.com"
E2B_DOMAIN="your-e2b-host.example.com"
No shared concurrency cap applies, but the cluster's hardware capacity still does.
The dataset here is a pack from laude-institute/harbor-datasets — clone the subset you need and point --dataset-dir at its directory.
Every rollout runs inside an E2B sandbox spawned from a prebuilt template that already has uv and the NexAU/harbor venv at /opt/nexau-venv. Build those templates once before launching:
# Build every template declared by the dataset, 16 in parallel
uv run python scripts/build_templates.py --dataset-dir /path/to/dataset -j 16

# Resume after a failure: only retry tasks whose latest E2B build status is ERROR
uv run python scripts/build_templates.py --dataset-dir /path/to/dataset --retry-failed

# Build a specific subset of tasks
uv run python scripts/build_templates.py --dataset-dir /path/to/dataset task_a task_b
The dataset directory must contain one subdir per task with a task.toml declaring [environment].docker_image (or an environment/Dockerfile fallback). Each task's template alias is <task_name> with . replaced by -.
The default packages baked into each template come from scripts/build_templates.py:DEFAULT_NEXAU_PACKAGES (a public NexAU + the in-sandbox NexAU-harbor variant, intentionally distinct from the host-side harbor-LJH in pyproject.toml). Override with one or more --nexau-package <git-or-pip-spec> flags if you need a different revision in the sandbox.
If your tasks pull from a private Docker registry, also export DOCKER_REGISTRY_USERNAME and DOCKER_REGISTRY_PASSWORD before invoking the script.
# Run a single experiment in the background via tmux
./scripts/evolve.sh configs/experiments/exp-simple-code-gpt54.yaml

# Launch and auto-attach to the log stream
./scripts/evolve.sh --attach configs/experiments/exp-simple-code-gpt54.yaml

# Batch: launch every experiment under configs/experiments/
./scripts/evolve.sh --batch
Common tmux operations after launch:
tmux ls                         # list sessions
tmux attach -t <session>        # attach to a session
# Ctrl-b d                      # detach (keeps running in background)
tmux kill-session -t <session>  # terminate
The base model is held fixed; what evolves is the harness around it. Each outer iteration is evaluate → analyze → improve, built on the three observability layers from the Overview.
harbor runs the current code_agent over the dataset inside isolated E2B sandboxes. Per task it writes:
agent/nexau_in_memory_tracer.cleaned.json — full step-level trace (messages, tool calls, middleware events)agent/nexau.txt — runtime log (middleware errors, crashes, warnings)verifier/reward.txt — pass/fail outcomeThe trace, not the pass rate, is the unit every later step operates on.
Agent Debugger compresses each iteration's raw traces (routinely >10M tokens) into layered reports:
analysis/overview.md — cross-task root-cause summaryanalysis/detail/{task}.md — per-task deep analysisThe optimizer reads digests by default, but every claim links back to the originating raw trace, so it can drill down before committing to a change.
Note on Agent Debugger licensing. The current release ships a partially open-sourced Agent Debugger; due to company strategy, it cannot be fully open-sourced at this time.
Evolve Agent may only write inside workspace/, which exposes the seven NexAU components: systemprompt.md, code_agent.yaml, tool_descriptions/, tools/, middleware/, skills/, sub_agents/ (plus LongTermMEMORY.md). For every edit it must commit four fields:
Each runs/iteration_NNN/ mixes two generations: input/ holds the workspace produced by loop NNN-1 (just evaluated), evolve/ holds what loop NNN writes (evaluated next loop). Flips (pass↔fail) on the next eval are attributed back to this loop's edits in change_evaluation.json — predictions that don't hold get rolled back or revised. The loop terminates on target_pass_rate or max_iterations.
| Component | Role |
|---|---|
evolve.py | Main-loop orchestrator |
agents/code_agent_simple/ | The coding agent that is being evaluated and evolved |
agents/evolve_agent/ | The meta-agent that performs the improvement step (built on the NexAU framework) |
agents/explore_agent/ | Upstream dataset / source-code exploration agent |
configs/ | base.yaml (shared defaults) + experiments/ (per-experiment overlays) |
scripts/ | tmux launcher wrappers (evolve.sh, evolve-resume.sh) |
agentic-harness-engineering/
├── evolve.py                       # main loop
├── trace_converter.py              # rollout trace → debugger-friendly JSON
├── agents/
│   ├── code_agent_simple/          # the coding agent under evolution
│   ├── evolve_agent/               # the evolution meta-agent
│   │   ├── evolve_prompt.md
│   │   ├── middleware/             # context compaction / failover / ralph loop …
│   │   ├── skills/                 # agent-debugger-cli / nexau-evolution-guide
│   │   └── tools/                  # file / shell / web / session tools
│   └── explore_agent/              # exploration agent (sources + web)
├── configs/
│   ├── base.yaml                   # shared defaults
│   └── experiments/                # one overlay per experiment
├── scripts/
│   ├── evolve.sh                   # tmux launcher
│   └── evolve-resume.sh            # resume helper
└── .env.example
configs/base.yaml holds the shared defaults. Each configs/experiments/exp-*.yaml inherits it via a leading _base: ../base.yaml line and overrides only the fields that differ. Any ${ENV_NAME} reference inside a YAML file is substituted from .env.
Key fields in base.yaml:
| Field | Description |
|---|---|
path | Dataset path |
target_pass_rate | Stop once reached (default 0.95) |
max_iterations | Maximum number of iterations (default 100) |
harbor_job_timeout_minutes | Per-harbor-evaluation timeout (0 = unlimited) |
experiment_timeout_minutes | Total wall-clock budget for the experiment (0 = unlimited) |
llm.api_key / base_url / model | Main LLM config (usually left as ${LLM_*}) |
agent_debugger.llm | Dedicated LLM for ADB (can use a stronger model for debugging) |
notify.feishu_webhook | Optional Feishu webhook for experiment milestones |
An experiment's data source is specified via path or dataset — pick one:
| Form | Meaning | Example |
|---|---|---|
path: "./dataset/xxx" | Local dataset directory (relative to the AHE root) | ./dataset/terminal-bench-2 |
path: "/abs/path/xxx" | Local dataset directory (absolute path) | /root/dataset/terminal-bench-2 |
dataset: "<name>@<ver>" | Reference a harbor built-in dataset (no local files required) | [email protected] |
Public dataset packs (in the layout AHE expects under path:) are published at laude-institute/harbor-datasets — clone or download the subset you need and point path at its directory.
The default path values in base.yaml and configs/experiments/*.yaml are placeholders only — adjust them for your environment, or comment out path and uncomment the dataset line to use a harbor built-in dataset instead.
python evolve.py| Flag | Description |
|---|---|
--config <file> | Config file (overlay takes precedence) |
--batch [dir|files...] | Batch mode; defaults to scanning configs/experiments/ |
--experiment <name> | Resume an existing experiment (pass the directory name under experiments/) |
--start-iteration N | Start from iteration N (default 1) |
--skip-eval | Skip evaluation and reuse existing rollouts (for debugging) |
./scripts/evolve.shA thin wrapper around uv run python evolve.py + tmux.
| Flag | Description |
|---|---|
<config_file> | Positional argument: path to the config file |
--experiment <name> | Resume an existing experiment |
--start-iteration N | Starting iteration |
--skip-eval | Skip evaluation |
--session <name> | Custom tmux session name |
--batch | Launch every overlay in batch mode |
--attach | Auto-attach after launch |
Resume an interrupted experiment from iteration 16:
./scripts/evolve.sh \
  --experiment 2026-04-10__23-20-14__gpt54 \
  --start-iteration 16 \
  configs/experiments/exp-simple-code-gpt54.yaml
Run only evolve_agent without re-running evaluation:
./scripts/evolve.sh \
  --experiment <existing-exp-dir> \
  --skip-eval \
  configs/experiments/exp-simple-code-gpt54.yaml
MIT
431 followers · starred Jun 2026
6,861 followers · starred May 2026
1,114 followers · starred Aug 2026
407 followers · starred Jun 2026
Official AHE code — Agentic Harness Engineering: observability-driven automatic evolution of coding-agent harnesses (concurrent w/ meta-harness). NexAU-AHE reaches 84.7% ± 2.1 pass@1 on Terminal-Bench 2 (GPT-5.5). Lifts GPT-5.4 69.7→77.0% over 10 iters, beats Codex/ACE/Training-Free GRPO; frozen harness transfers to SWE-bench-Verified.
See the code
English | 简体中文
AHE (Agentic Harness Engineering) is an open observability system for automatically evolving the harness around a coding agent. The base model is held fixed; what evolves are the harness components — system prompts, tool descriptions, tool implementations, middleware, skills, sub-agents, and long-term memory.
AHE rests on three observability layers:
Across ten evaluate → analyze → improve iterations, AHE (Agentic Harness Engineering) lifts Terminal-Bench 2 pass@1 from 69.7% to 77.0% on GPT-5.4, surpasses the hand-written Codex (71.9%) and the self-evolving ACE and TF-GRPO baselines, and produces a frozen harness that transfers without re-evolution to SWE-bench-verified and to four alternate base models, indicating that the evolved components encode general engineering experience rather than benchmark-specific tuning.
# macOS
brew install uv tmux

# Linux
curl -LsSf https://astral.sh/uv/install.sh | sh
sudo apt install -y tmux
git clone https://github.com/Curry09/agentic-harness-engineering.git
cd agentic-harness-engineering
uv sync
uv syncinstalls every dependency declared inpyproject.toml.
cp .env.example .env
Edit .env. At minimum, set:
| Variable | Purpose |
|---|---|
LLM_API_KEY / LLM_BASE_URL | Main LLM endpoint (code_agent and evolve_agent both consume it) |
E2B_API_KEY | E2B sandbox — see the next subsection for SaaS vs. self-hosted |
SERPER_API_KEY | Web search used by evolve_agent |
ADB_LLM_* and GPT54_LLM_* are optional — leave them unset to fall back to LLM_*, or set them to point ADB / the gpt-5.4 experiment at a stronger model. LANGFUSE_*, BP_HTML_PARSER_*, and FEISHU_WEBHOOK are all optional observability / convenience hooks; see .env.example for the full list.
AHE runs every rollout inside an E2B sandbox. Two deployment modes are supported:
SaaS E2B (default). Set only E2B_API_KEY and leave E2B_API_URL / E2B_DOMAIN unset (or commented out). The SDK talks to e2b.dev automatically.
⚠️ Concurrency cap. SaaS E2B enforces a per-account concurrent sandbox limit tied to your tier. If harbor tries to spawn more sandboxes than the cap allows, the extra sandboxes fail to start and the iteration stalls. Before raising parallelism in your harbor / experiment config, check your tier's quota and stay safely under it.
Self-hosted E2B cluster. Set E2B_API_KEY and point the SDK at your cluster:
E2B_API_KEY="your_e2b_key"
E2B_API_URL="https://your-e2b-host.example.com"
E2B_DOMAIN="your-e2b-host.example.com"
No shared concurrency cap applies, but the cluster's hardware capacity still does.
The dataset here is a pack from laude-institute/harbor-datasets — clone the subset you need and point --dataset-dir at its directory.
Every rollout runs inside an E2B sandbox spawned from a prebuilt template that already has uv and the NexAU/harbor venv at /opt/nexau-venv. Build those templates once before launching:
# Build every template declared by the dataset, 16 in parallel
uv run python scripts/build_templates.py --dataset-dir /path/to/dataset -j 16

# Resume after a failure: only retry tasks whose latest E2B build status is ERROR
uv run python scripts/build_templates.py --dataset-dir /path/to/dataset --retry-failed

# Build a specific subset of tasks
uv run python scripts/build_templates.py --dataset-dir /path/to/dataset task_a task_b
The dataset directory must contain one subdir per task with a task.toml declaring [environment].docker_image (or an environment/Dockerfile fallback). Each task's template alias is <task_name> with . replaced by -.
The default packages baked into each template come from scripts/build_templates.py:DEFAULT_NEXAU_PACKAGES (a public NexAU + the in-sandbox NexAU-harbor variant, intentionally distinct from the host-side harbor-LJH in pyproject.toml). Override with one or more --nexau-package <git-or-pip-spec> flags if you need a different revision in the sandbox.
If your tasks pull from a private Docker registry, also export DOCKER_REGISTRY_USERNAME and DOCKER_REGISTRY_PASSWORD before invoking the script.
# Run a single experiment in the background via tmux
./scripts/evolve.sh configs/experiments/exp-simple-code-gpt54.yaml

# Launch and auto-attach to the log stream
./scripts/evolve.sh --attach configs/experiments/exp-simple-code-gpt54.yaml

# Batch: launch every experiment under configs/experiments/
./scripts/evolve.sh --batch
Common tmux operations after launch:
tmux ls                         # list sessions
tmux attach -t <session>        # attach to a session
# Ctrl-b d                      # detach (keeps running in background)
tmux kill-session -t <session>  # terminate
The base model is held fixed; what evolves is the harness around it. Each outer iteration is evaluate → analyze → improve, built on the three observability layers from the Overview.
harbor runs the current code_agent over the dataset inside isolated E2B sandboxes. Per task it writes:
agent/nexau_in_memory_tracer.cleaned.json — full step-level trace (messages, tool calls, middleware events)agent/nexau.txt — runtime log (middleware errors, crashes, warnings)verifier/reward.txt — pass/fail outcomeThe trace, not the pass rate, is the unit every later step operates on.
Agent Debugger compresses each iteration's raw traces (routinely >10M tokens) into layered reports:
analysis/overview.md — cross-task root-cause summaryanalysis/detail/{task}.md — per-task deep analysisThe optimizer reads digests by default, but every claim links back to the originating raw trace, so it can drill down before committing to a change.
Note on Agent Debugger licensing. The current release ships a partially open-sourced Agent Debugger; due to company strategy, it cannot be fully open-sourced at this time.
Evolve Agent may only write inside workspace/, which exposes the seven NexAU components: systemprompt.md, code_agent.yaml, tool_descriptions/, tools/, middleware/, skills/, sub_agents/ (plus LongTermMEMORY.md). For every edit it must commit four fields:
Each runs/iteration_NNN/ mixes two generations: input/ holds the workspace produced by loop NNN-1 (just evaluated), evolve/ holds what loop NNN writes (evaluated next loop). Flips (pass↔fail) on the next eval are attributed back to this loop's edits in change_evaluation.json — predictions that don't hold get rolled back or revised. The loop terminates on target_pass_rate or max_iterations.
| Component | Role |
|---|---|
evolve.py | Main-loop orchestrator |
agents/code_agent_simple/ | The coding agent that is being evaluated and evolved |
agents/evolve_agent/ | The meta-agent that performs the improvement step (built on the NexAU framework) |
agents/explore_agent/ | Upstream dataset / source-code exploration agent |
configs/ | base.yaml (shared defaults) + experiments/ (per-experiment overlays) |
scripts/ | tmux launcher wrappers (evolve.sh, evolve-resume.sh) |
agentic-harness-engineering/
├── evolve.py                       # main loop
├── trace_converter.py              # rollout trace → debugger-friendly JSON
├── agents/
│   ├── code_agent_simple/          # the coding agent under evolution
│   ├── evolve_agent/               # the evolution meta-agent
│   │   ├── evolve_prompt.md
│   │   ├── middleware/             # context compaction / failover / ralph loop …
│   │   ├── skills/                 # agent-debugger-cli / nexau-evolution-guide
│   │   └── tools/                  # file / shell / web / session tools
│   └── explore_agent/              # exploration agent (sources + web)
├── configs/
│   ├── base.yaml                   # shared defaults
│   └── experiments/                # one overlay per experiment
├── scripts/
│   ├── evolve.sh                   # tmux launcher
│   └── evolve-resume.sh            # resume helper
└── .env.example
configs/base.yaml holds the shared defaults. Each configs/experiments/exp-*.yaml inherits it via a leading _base: ../base.yaml line and overrides only the fields that differ. Any ${ENV_NAME} reference inside a YAML file is substituted from .env.
Key fields in base.yaml:
| Field | Description |
|---|---|
path | Dataset path |
target_pass_rate | Stop once reached (default 0.95) |
max_iterations | Maximum number of iterations (default 100) |
harbor_job_timeout_minutes | Per-harbor-evaluation timeout (0 = unlimited) |
experiment_timeout_minutes | Total wall-clock budget for the experiment (0 = unlimited) |
llm.api_key / base_url / model | Main LLM config (usually left as ${LLM_*}) |
agent_debugger.llm | Dedicated LLM for ADB (can use a stronger model for debugging) |
notify.feishu_webhook | Optional Feishu webhook for experiment milestones |
An experiment's data source is specified via path or dataset — pick one:
| Form | Meaning | Example |
|---|---|---|
path: "./dataset/xxx" | Local dataset directory (relative to the AHE root) | ./dataset/terminal-bench-2 |
path: "/abs/path/xxx" | Local dataset directory (absolute path) | /root/dataset/terminal-bench-2 |
dataset: "<name>@<ver>" | Reference a harbor built-in dataset (no local files required) | [email protected] |
Public dataset packs (in the layout AHE expects under path:) are published at laude-institute/harbor-datasets — clone or download the subset you need and point path at its directory.
The default path values in base.yaml and configs/experiments/*.yaml are placeholders only — adjust them for your environment, or comment out path and uncomment the dataset line to use a harbor built-in dataset instead.
python evolve.py| Flag | Description |
|---|---|
--config <file> | Config file (overlay takes precedence) |
--batch [dir|files...] | Batch mode; defaults to scanning configs/experiments/ |
--experiment <name> | Resume an existing experiment (pass the directory name under experiments/) |
--start-iteration N | Start from iteration N (default 1) |
--skip-eval | Skip evaluation and reuse existing rollouts (for debugging) |
./scripts/evolve.shA thin wrapper around uv run python evolve.py + tmux.
| Flag | Description |
|---|---|
<config_file> | Positional argument: path to the config file |
--experiment <name> | Resume an existing experiment |
--start-iteration N | Starting iteration |
--skip-eval | Skip evaluation |
--session <name> | Custom tmux session name |
--batch | Launch every overlay in batch mode |
--attach | Auto-attach after launch |
Resume an interrupted experiment from iteration 16:
./scripts/evolve.sh \
  --experiment 2026-04-10__23-20-14__gpt54 \
  --start-iteration 16 \
  configs/experiments/exp-simple-code-gpt54.yaml
Run only evolve_agent without re-running evaluation:
./scripts/evolve.sh \
  --experiment <existing-exp-dir> \
  --skip-eval \
  configs/experiments/exp-simple-code-gpt54.yaml
MIT
431 followers · starred Jun 2026
6,861 followers · starred May 2026
1,114 followers · starred Aug 2026
407 followers · starred Jun 2026