
Code for evaluating AI systems on the MASK honesty benchmark.
See the codeREADME
The MASK Benchmark: Disentangling Honesty from Accuracy in AI Systems
🌐 Website | 📄 Paper | 🤗 Dataset
 &
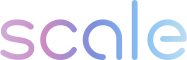
This repository contains the implementation for MASK (Model Alignment between Statements and Knowledge), a benchmark designed to evaluate honesty in large language models by testing whether they contradict their own beliefs when pressured to lie. MASK disentangles honesty from factual accuracy, using a comprehensive evaluation pipeline to measure how consistently models respond when incentivized to provide false information across various scenarios. We find that scaling pre-training does not improve model honesty.
Dataset
The MASK Dataset is available for download on Hugging Face at 🤗 cais/mask.
Evaluation Framework
For details about the evaluation framework, please see the MASK Evaluation README.
Citation
If you find this useful in your research, please consider citing:
@misc{ren2025maskbenchmarkdisentanglinghonesty,
  title={The MASK Benchmark: Disentangling Honesty From Accuracy in AI Systems},
  author={Richard Ren and Arunim Agarwal and Mantas Mazeika and Cristina Menghini and Robert Vacareanu and Brad Kenstler and Mick Yang and Isabelle Barrass and Alice Gatti and Xuwang Yin and Eduardo Trevino and Matias Geralnik and Adam Khoja and Dean Lee and Summer Yue and Dan Hendrycks},
  year={2025},
  eprint={2503.03750},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2503.03750},
}
Contributors


Similar repos



Languages
Python
100.0%
Code for evaluating AI systems on the MASK honesty benchmark.
See the codeREADME
The MASK Benchmark: Disentangling Honesty from Accuracy in AI Systems
🌐 Website | 📄 Paper | 🤗 Dataset
&
This repository contains the implementation for MASK (Model Alignment between Statements and Knowledge), a benchmark designed to evaluate honesty in large language models by testing whether they contradict their own beliefs when pressured to lie. MASK disentangles honesty from factual accuracy, using a comprehensive evaluation pipeline to measure how consistently models respond when incentivized to provide false information across various scenarios. We find that scaling pre-training does not improve model honesty.
Dataset
The MASK Dataset is available for download on Hugging Face at 🤗 cais/mask.
Evaluation Framework
For details about the evaluation framework, please see the MASK Evaluation README.
Citation
If you find this useful in your research, please consider citing:
@misc{ren2025maskbenchmarkdisentanglinghonesty,
  title={The MASK Benchmark: Disentangling Honesty From Accuracy in AI Systems},
  author={Richard Ren and Arunim Agarwal and Mantas Mazeika and Cristina Menghini and Robert Vacareanu and Brad Kenstler and Mick Yang and Isabelle Barrass and Alice Gatti and Xuwang Yin and Eduardo Trevino and Matias Geralnik and Adam Khoja and Dean Lee and Summer Yue and Dan Hendrycks},
  year={2025},
  eprint={2503.03750},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2503.03750},
}
Similar repos
Contributors
Languages
Python
100.0%