[NeurIPS 2025 Main] SWE-SQL: Illuminating LLM Pathways to Solve User SQL Issues in Real-World Applications
See the code


remove_distinct function). Please pull the latest code from our GitHub repository.BIRD-Critic 1.0 introduces a novel SQL benchmark designed to evaluate a key capability: Can large language models (LLMs) diagnose and solve user issues within real-world database environments?
The benchmark comprises 600 tasks for development and 200 held-out out-of-distribution (OOD) tests. BIRD-CRITIC 1.0 is built on realistic user issues across 4 prominent open-source SQL dialects: MySQL, PostgreSQL, SQL Server, and Oracle. It expands beyond simple SELECT queries to cover a wider range of SQL operations, reflecting actual application scenarios. Finally, an optimized execution-based evaluation environment is included for rigorous and efficient validation.
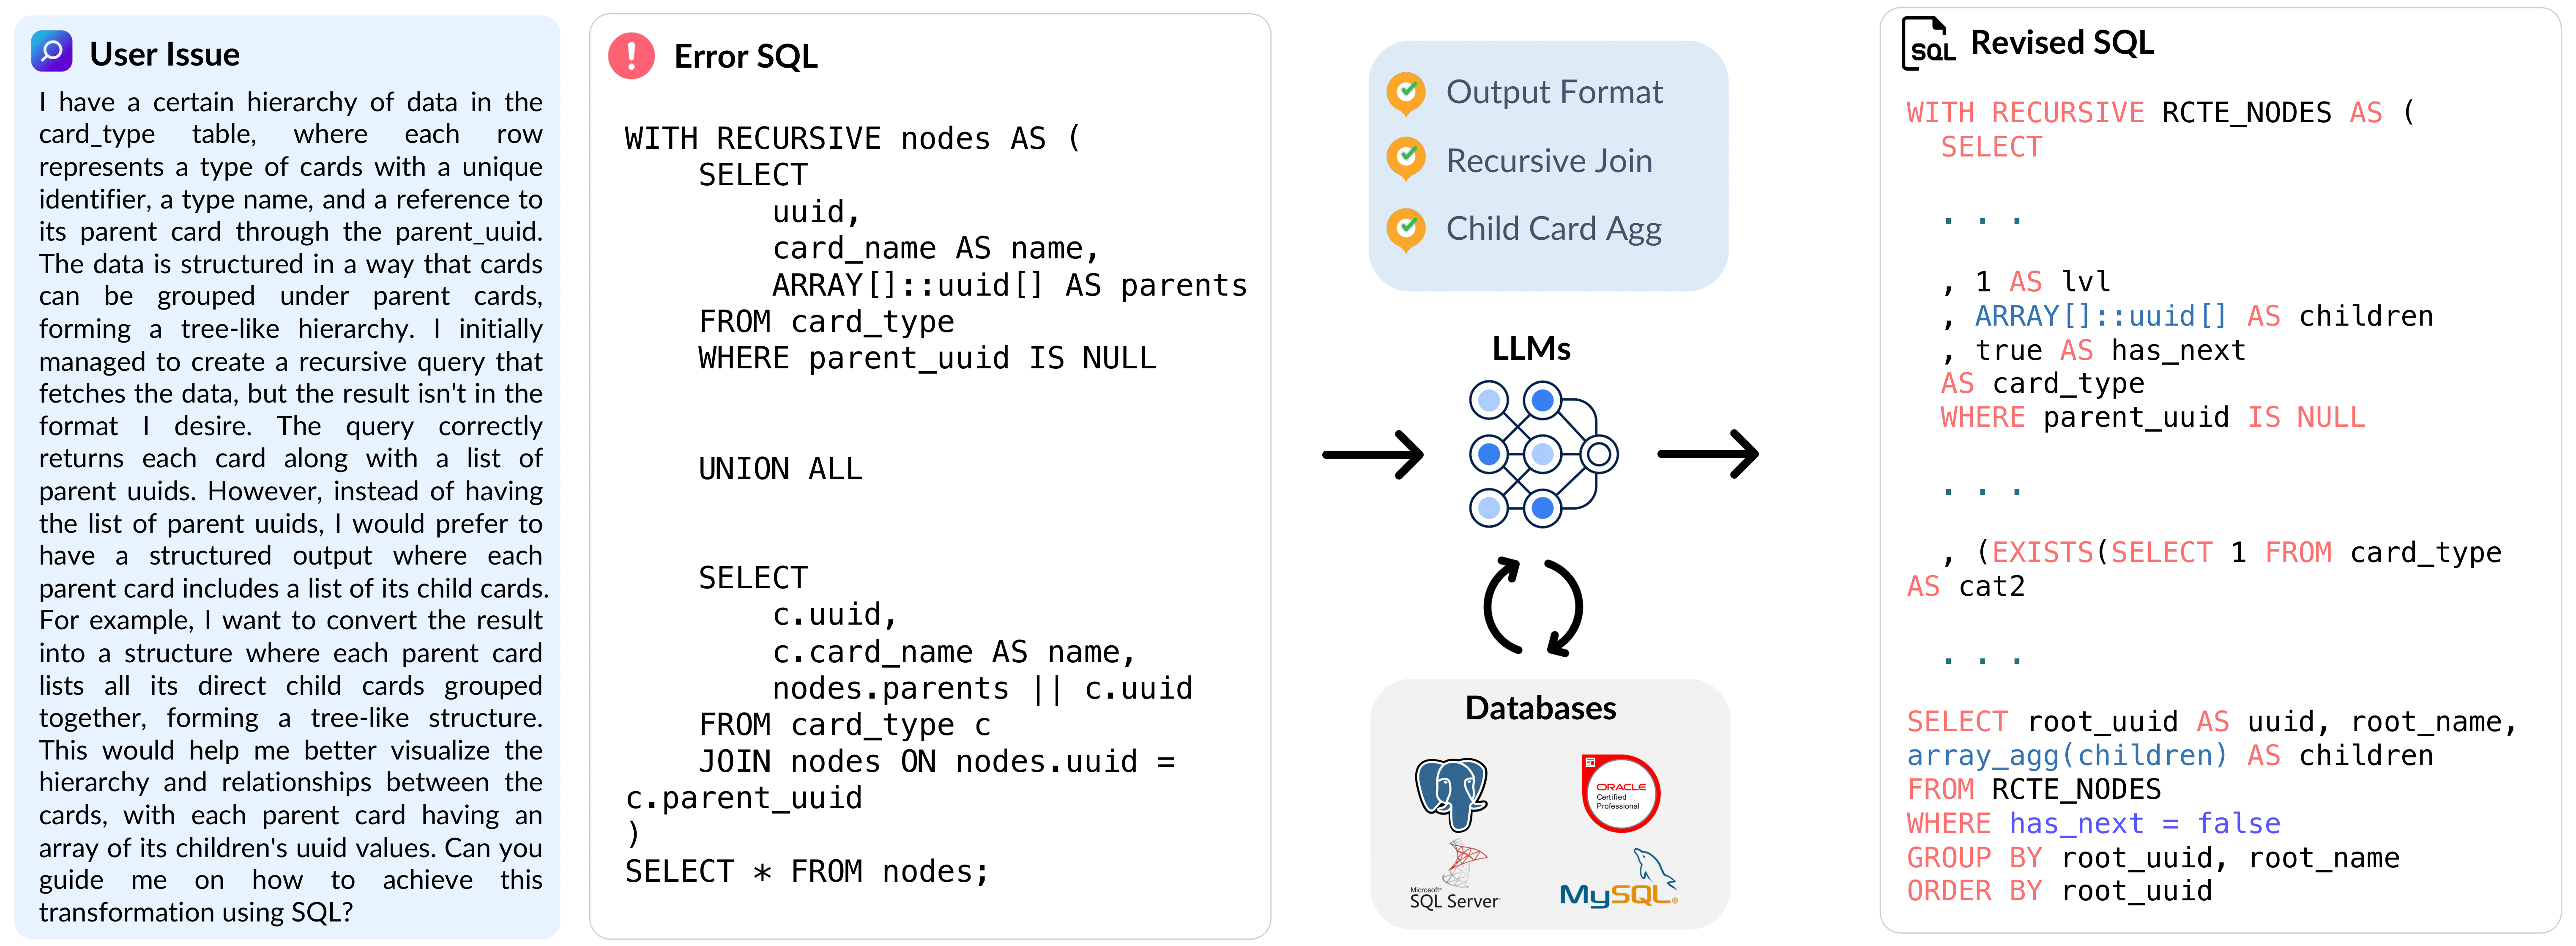
Each task in BIRD-CRITIC has been verified by human experts on the following dimensions:
We are releasing a lite version of BIRD-Critic, bird-critic-1.0-flash-exp, which includes 200 high-quality user issues on PostgreSQL when developing real-world applications. We curate tasks by:
The open version of BIRD-CRITIC 1.0, bird-critic-1.0-open, is a comprehensive benchmark that includes 570 tasks across 4 SQL dialects: MySQL, PostgreSQL, SQL Server, and Oracle. It covers a wide range of SQL operations and user issues.
| Rank | Model Name | Score | Level |
|---|---|---|---|
| 1 | o3-mini-2025-01-31 | 34.50 | 🏆 Leading |
| 2 | deepseek-reasoner (r1) | 33.67 | 🌟 Elite |
| 3 | o1-preview-2024-09-12 | 33.33 | 🌟 Elite |
| 4 | claude-3-7-sonnet-20250219(thinking) | 30.67 | 🌟 Elite |
| 5 | gemini-2.0-flash-thinking-exp-01-21 | 30.17 | 🌟 Elite |
| 6 | grok-3-beta | 29.83 | 💎 Superior |
Complete results of Open version can be found here. Bird-CRITIC 1.0 Flash result can be found here
bird-critic-1.0-pg, is a dataset containing 530 high-quality user issues focused on real-world PostgreSQL database applications.
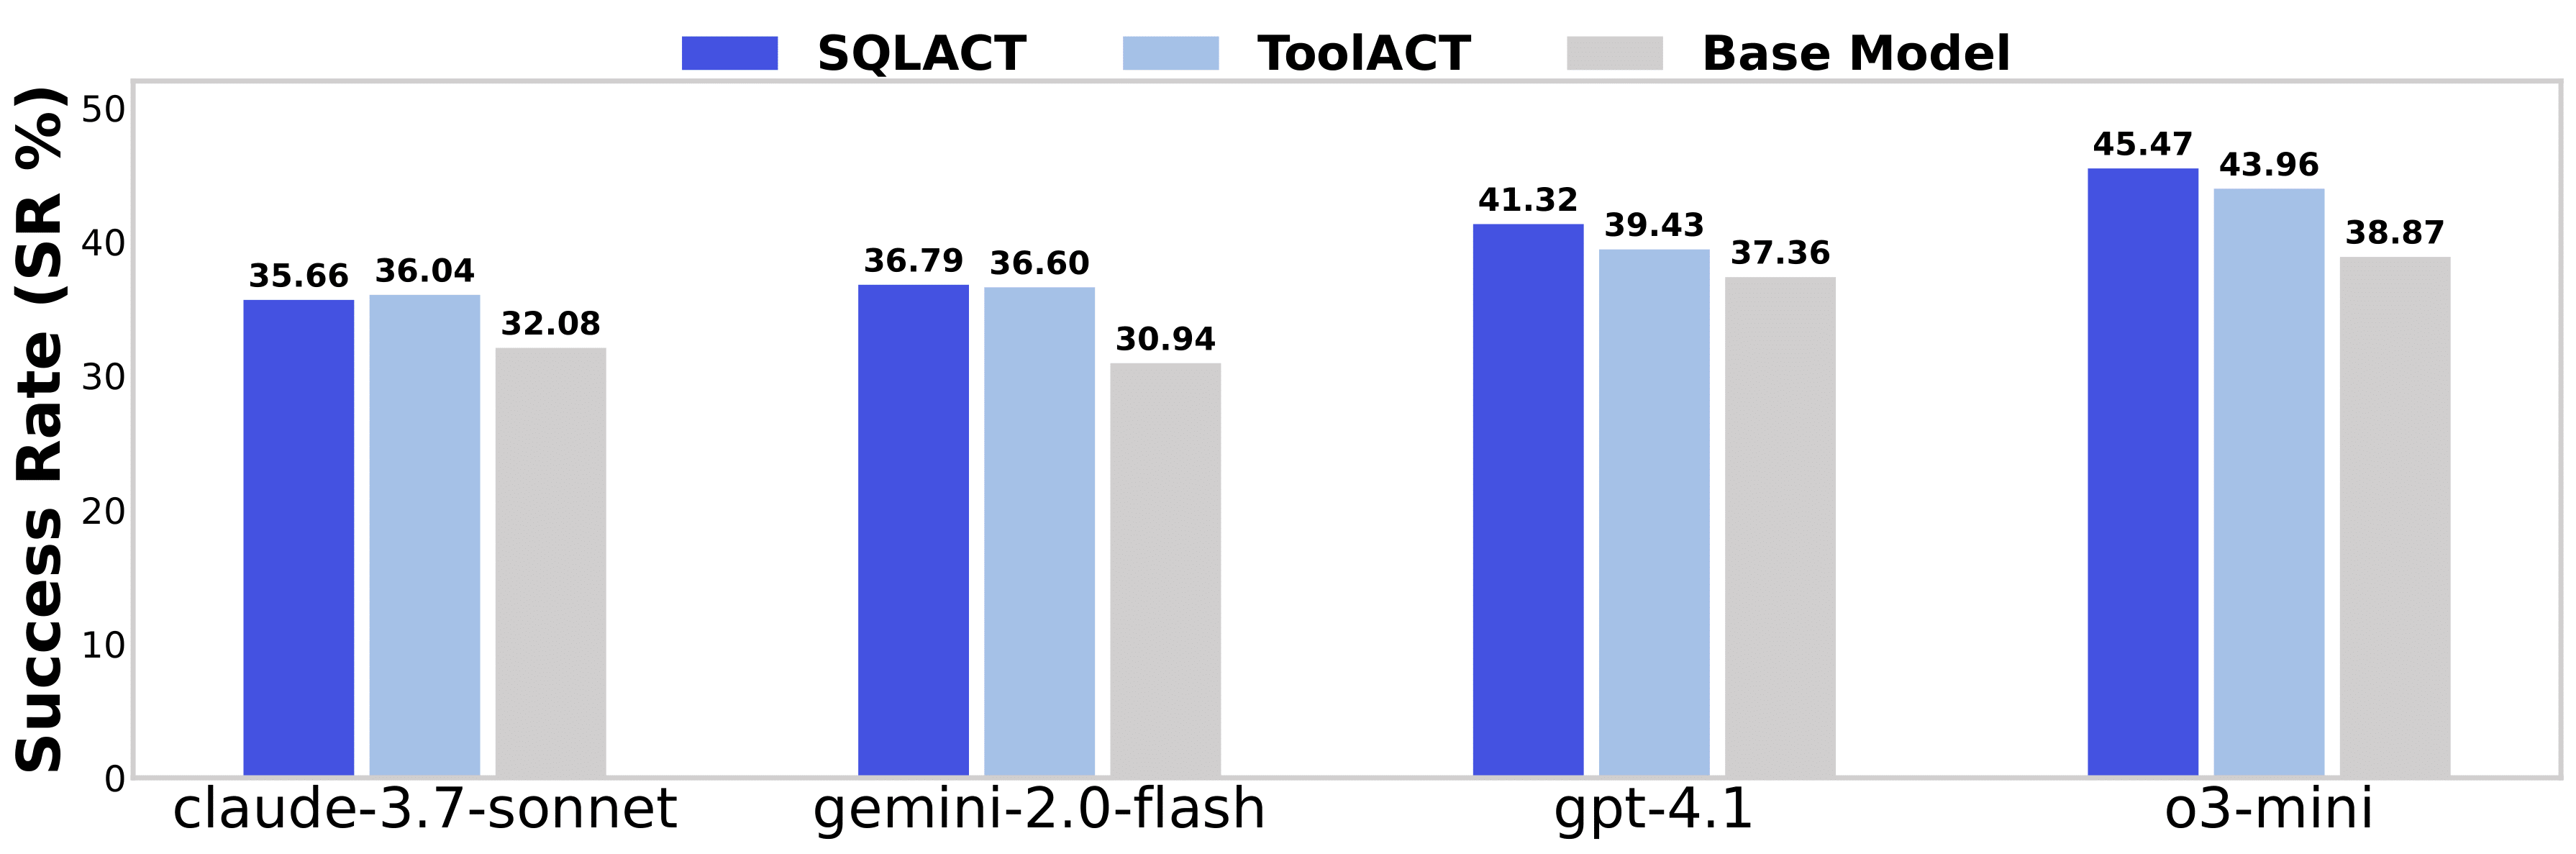
Key Findings:
The BIRD-CRITIC 1.0 benchmark is available in the following configurations:
bird-critic-1.0-flash-exp: A lite version consisting of 200 instances on PostgreSQL.bird-critic-1.0-open: The full version containing 570 instances across MySQL, PostgreSQL, SQL Server, and Oracle.bird-critic-1.0-postgresql: A 530-instance version specifically for PostgreSQL.bird-critic-1.0-bigquery: A lite version containing between 100 and 200 instances for BigQuery.db_id: The name of the database.query: The user query is rewritten in the BIRD environment.issue_sql: The buggy SQL query written by the user.sol_sql: The ground truth SQL solution.preprocess_sql: SQL queries to run before executing the solution or prediction.clean_up_sql: SQL queries to run after the test cases to revert any changes made to the database.test_cases: A set of test cases to validate the predicted corrected SQL.efficiency: True if this question needs optimization, measure the cost by Query Execution Plan (QEP)external_data: For the external JSON data if present./baseline directory../evaluation directory.To avoid data leakage by auto-crawling, certain fields (e.g., sol_sql, test_cases) are excluded from the public dataset. For the full dataset, please email: 📧 [email protected] with subject tag [bird-critic-1 GT&Test Cases], which will be sent automatically within 30 mins.
You can download the dataset from HuggingFace using the following command:
from datasets import load_dataset
# Load the flash version of the dataset
dataset = load_dataset("birdsql/bird-critic-1.0-flash-exp")
print(dataset["flash"][0])

# Load the open version of the dataset
dataset = load_dataset("birdsql/bird-critic-1.0-open")
print(dataset["open"][0])
Or you can use the provided script to download the open version of the dataset and split it into different dialects.
cd baseline/data
python pull_data.py \
  --schema_path path/to/open_schema.jsonl \
  --input_path path/to/input.jsonl \ # Path to the input JSONL file (may be empty if you want to download the dataset from HuggingFace)
  --output_folder path/to/output_dir # output folder of the split files
.
├── LICENSE
├── README.md
├── baseline
│   ├── data
│   ├── outputs
│   ├── run
│   └── src
├── evaluation
│   ├── docker-compose.yml
│   ├── env
│   ├── mssql_table_dumps
│   ├── mysql_table_dumps
│   ├── oracle_table_dumps
│   ├── postgre_table_dumps
│   ├── run
│   └── src
├── materials
│   ├── ...
└── requirements.txt
To run the baseline code you need to install the following dependencies:
conda create -n bird_critic python=3.10 -y
conda activate bird_critic
pip install -r requirements.txt
You also need to setup the model name (eg., gpt-4o-2024-08-06) with the API key in the config.py file. Then you can run the following command to generate the output:
# Generate the prompt
cd baseline/run
bash generate_prompt.sh

# LLM Inference, need to set the API key in config.py
bash run_baseline.sh
The output will be save in the ./baseline/outputs/final_output/
We use docker to provide a consistent environment for running the benchmark. To set up the environment, follow these steps:
./evaluation named with postgre_table_dumps,mssql_table_dumps, mysql_table_dumps and oracle_table_dumps.cd evaluation
docker compose up --build
perform_query_on_{dialect}_databases() function in the evaluation/src/{dialect}_utils.py file to interact with the each database. The function will return the result of the query.docker compose exec so_eval_env bash
cd run
bash run_eval.sh
You have to specify the dialect you want to evaluate in the run_eval.sh script. The options are:
postgresqlmysqlsqlserveroracle
The output report file will be saved in the same folder as your input file.
If you want the log file for each instance, you can set the --logging to true in the run_eval.sh script.If you find our work helpful, please cite as:
@article{li2025swe,
  title={SWE-SQL: Illuminating LLM Pathways to Solve User SQL Issues in Real-World Applications},
  author={Li, Jinyang and Li, Xiaolong and Qu, Ge and Jacobsson, Per and Qin, Bowen and Hui, Binyuan and Si, Shuzheng and Huo, Nan and Xu, Xiaohan and Zhang, Yue and others},
  journal={arXiv preprint arXiv:2506.18951},
  year={2025}
}
BIRD Team & Google Cloud
29 followers · starred Feb 2025
135 followers · starred Feb 2025
23 followers · starred Apr 2025
[NeurIPS 2025 Main] SWE-SQL: Illuminating LLM Pathways to Solve User SQL Issues in Real-World Applications
See the code
remove_distinct function). Please pull the latest code from our GitHub repository.BIRD-Critic 1.0 introduces a novel SQL benchmark designed to evaluate a key capability: Can large language models (LLMs) diagnose and solve user issues within real-world database environments?
The benchmark comprises 600 tasks for development and 200 held-out out-of-distribution (OOD) tests. BIRD-CRITIC 1.0 is built on realistic user issues across 4 prominent open-source SQL dialects: MySQL, PostgreSQL, SQL Server, and Oracle. It expands beyond simple SELECT queries to cover a wider range of SQL operations, reflecting actual application scenarios. Finally, an optimized execution-based evaluation environment is included for rigorous and efficient validation.
Each task in BIRD-CRITIC has been verified by human experts on the following dimensions:
We are releasing a lite version of BIRD-Critic, bird-critic-1.0-flash-exp, which includes 200 high-quality user issues on PostgreSQL when developing real-world applications. We curate tasks by:
The open version of BIRD-CRITIC 1.0, bird-critic-1.0-open, is a comprehensive benchmark that includes 570 tasks across 4 SQL dialects: MySQL, PostgreSQL, SQL Server, and Oracle. It covers a wide range of SQL operations and user issues.
| Rank | Model Name | Score | Level |
|---|---|---|---|
| 1 | o3-mini-2025-01-31 | 34.50 | 🏆 Leading |
| 2 | deepseek-reasoner (r1) | 33.67 | 🌟 Elite |
| 3 | o1-preview-2024-09-12 | 33.33 | 🌟 Elite |
| 4 | claude-3-7-sonnet-20250219(thinking) | 30.67 | 🌟 Elite |
| 5 | gemini-2.0-flash-thinking-exp-01-21 | 30.17 | 🌟 Elite |
| 6 | grok-3-beta | 29.83 | 💎 Superior |
Complete results of Open version can be found here. Bird-CRITIC 1.0 Flash result can be found here
bird-critic-1.0-pg, is a dataset containing 530 high-quality user issues focused on real-world PostgreSQL database applications.
Key Findings:
The BIRD-CRITIC 1.0 benchmark is available in the following configurations:
bird-critic-1.0-flash-exp: A lite version consisting of 200 instances on PostgreSQL.bird-critic-1.0-open: The full version containing 570 instances across MySQL, PostgreSQL, SQL Server, and Oracle.bird-critic-1.0-postgresql: A 530-instance version specifically for PostgreSQL.bird-critic-1.0-bigquery: A lite version containing between 100 and 200 instances for BigQuery.db_id: The name of the database.query: The user query is rewritten in the BIRD environment.issue_sql: The buggy SQL query written by the user.sol_sql: The ground truth SQL solution.preprocess_sql: SQL queries to run before executing the solution or prediction.clean_up_sql: SQL queries to run after the test cases to revert any changes made to the database.test_cases: A set of test cases to validate the predicted corrected SQL.efficiency: True if this question needs optimization, measure the cost by Query Execution Plan (QEP)external_data: For the external JSON data if present./baseline directory../evaluation directory.To avoid data leakage by auto-crawling, certain fields (e.g., sol_sql, test_cases) are excluded from the public dataset. For the full dataset, please email: 📧 [email protected] with subject tag [bird-critic-1 GT&Test Cases], which will be sent automatically within 30 mins.
You can download the dataset from HuggingFace using the following command:
from datasets import load_dataset
# Load the flash version of the dataset
dataset = load_dataset("birdsql/bird-critic-1.0-flash-exp")
print(dataset["flash"][0])

# Load the open version of the dataset
dataset = load_dataset("birdsql/bird-critic-1.0-open")
print(dataset["open"][0])
Or you can use the provided script to download the open version of the dataset and split it into different dialects.
cd baseline/data
python pull_data.py \
  --schema_path path/to/open_schema.jsonl \
  --input_path path/to/input.jsonl \ # Path to the input JSONL file (may be empty if you want to download the dataset from HuggingFace)
  --output_folder path/to/output_dir # output folder of the split files
.
├── LICENSE
├── README.md
├── baseline
│   ├── data
│   ├── outputs
│   ├── run
│   └── src
├── evaluation
│   ├── docker-compose.yml
│   ├── env
│   ├── mssql_table_dumps
│   ├── mysql_table_dumps
│   ├── oracle_table_dumps
│   ├── postgre_table_dumps
│   ├── run
│   └── src
├── materials
│   ├── ...
└── requirements.txt
To run the baseline code you need to install the following dependencies:
conda create -n bird_critic python=3.10 -y
conda activate bird_critic
pip install -r requirements.txt
You also need to setup the model name (eg., gpt-4o-2024-08-06) with the API key in the config.py file. Then you can run the following command to generate the output:
# Generate the prompt
cd baseline/run
bash generate_prompt.sh

# LLM Inference, need to set the API key in config.py
bash run_baseline.sh
The output will be save in the ./baseline/outputs/final_output/
We use docker to provide a consistent environment for running the benchmark. To set up the environment, follow these steps:
./evaluation named with postgre_table_dumps,mssql_table_dumps, mysql_table_dumps and oracle_table_dumps.cd evaluation
docker compose up --build
perform_query_on_{dialect}_databases() function in the evaluation/src/{dialect}_utils.py file to interact with the each database. The function will return the result of the query.docker compose exec so_eval_env bash
cd run
bash run_eval.sh
You have to specify the dialect you want to evaluate in the run_eval.sh script. The options are:
postgresqlmysqlsqlserveroracle
The output report file will be saved in the same folder as your input file.
If you want the log file for each instance, you can set the --logging to true in the run_eval.sh script.If you find our work helpful, please cite as:
@article{li2025swe,
  title={SWE-SQL: Illuminating LLM Pathways to Solve User SQL Issues in Real-World Applications},
  author={Li, Jinyang and Li, Xiaolong and Qu, Ge and Jacobsson, Per and Qin, Bowen and Hui, Binyuan and Si, Shuzheng and Huo, Nan and Xu, Xiaohan and Zhang, Yue and others},
  journal={arXiv preprint arXiv:2506.18951},
  year={2025}
}
BIRD Team & Google Cloud
29 followers · starred Feb 2025
135 followers · starred Feb 2025
23 followers · starred Apr 2025



