ICLR 2026: Towards Bridging the Gap between Large-Scale Pretraining and Efficient Finetuning for Humanoid Controls
Python
121
6 commits
updated Mar 28, 2026


Weidong Huang · Zhehan Li · Hangxin Liu · Biao Hou · Yao Su· Jingwen Zhang†
· Primary contact: Weidong Huang
(bigeasthuang@gmail.com)
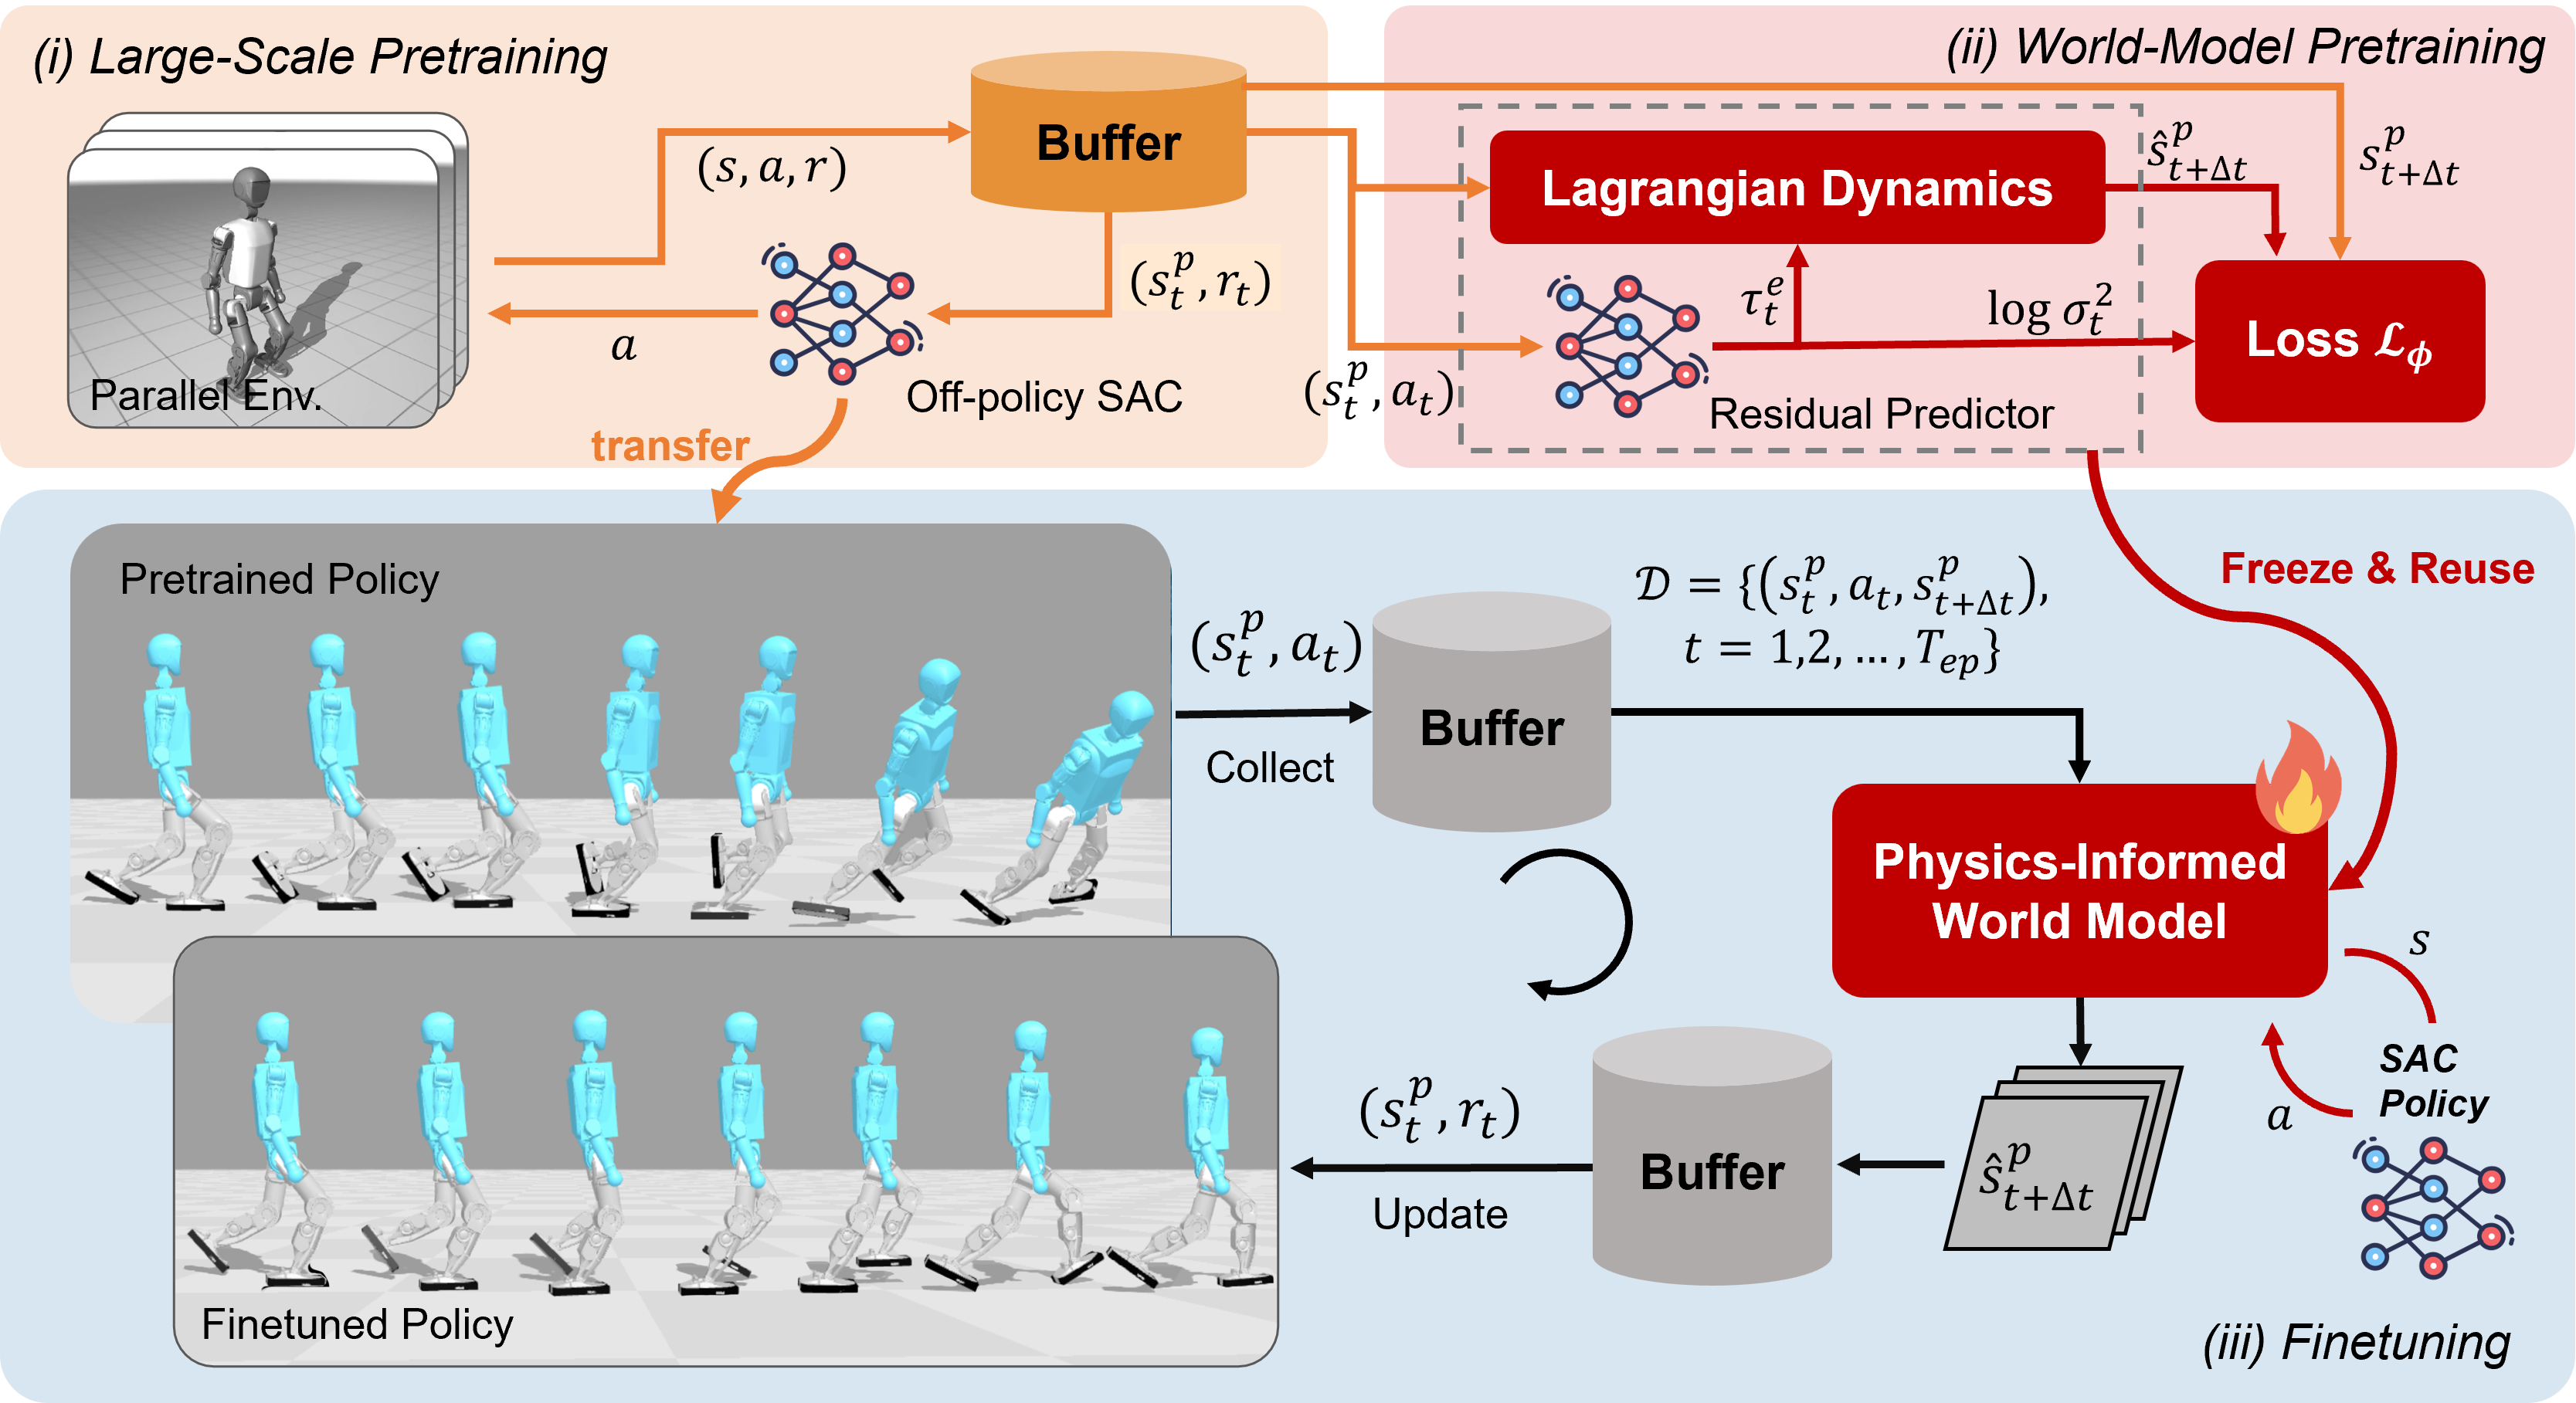
LIFT (Large-scale pretraIning and efficient FineTuning) is a three-stage framework that bridges scalable simulation pretraining and safe, efficient adaptation for humanoid control:
| Real World Deployment | Brax (Sim2Sim) | Brax (After Finetuning) |
|---|---|---|

|

|

|
See more (videos + code) on the project website: https://lift-humanoid.github.io/
(Ubuntu 22.04 and Python 3.10 recommended). Minimal quickstart:
This code is tested on NVIDIA H800 and 4090.
conda create -n lift python=3.10 -c conda-forge -y
conda activate lift
cd mujoco_playground
pip install -e .
cd ..
cd brax_env
pip install -e .
cd ..
pip install -r requirements.txt
Train Policy → Pretrain World Model → Finetune
Train Policy: pretrain with SAC (large batch + high UTD) in MuJoCo Playground and enable zero-shot deployment of the pretrained policy on physical humanoids.
Pretrain World Model: pretrain the physics-informed world model using the SAC offline data.
Sim2Sim and Fine-tuning: transfer the pretrained policy to Brax and fine-tune with a physics-informed world model. The environment executes deterministic actions; stochastic exploration is confined to the world model.
Use T1LowDimSimFinetuneJoystickFlatTerrain or G1LowDimJoystickFlatTerrain to pretrain the policy and save replay data for world-model pretraining + fine-tuning.
# T1 Low-Dim Sim Finetune (flat) — policy pretraining + buffer for WM/fine-tuning
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --domain_randomization --num_timesteps 40000000 --num_evals 10 --save_buffer_data  --wandb_entity your_wandb_entity

# G1 Low-Dim (flat) — policy pretraining + buffer for WM/fine-tuning
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=G1LowDimJoystickFlatTerrain --domain_randomization --num_timesteps 60000000 --num_evals 10 --save_buffer_data  --wandb_entity your_wandb_entity

# T1 Low-Dim Real World Finetune (flat) — policy pretraining + buffer for WM/fine-tuning (this setting is used for real world finetune experiment)
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimRealFinetuneJoystickFlatTerrain --domain_randomization --num_timesteps 40000000 --num_evals 10 --save_buffer_data  --wandb_entity your_wandb_entity
G1JoystickFlatTerrainG1JoystickRoughTerrainT1JoystickRoughTerrainT1JoystickFlatTerrainT1LowDimJoystickRoughTerrainT1LowDimJoystickFlatTerrain# T1LowDimJoystickRoughTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimJoystickRoughTerrain --wandb_entity your_wandb_entity --domain_randomization --suffix xxx
# T1LowDimJoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimJoystickFlatTerrain --wandb_entity your_wandb_entity --domain_randomization --suffix xxx
# G1JoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python -u train_in_mujoco_playground.py --env_name=G1JoystickFlatTerrain --wandb_entity your_wandb_entity --suffix xxx
# G1JoystickRoughTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=G1JoystickRoughTerrain --wandb_entity your_wandb_entity --suffix xxx
# T1JoystickRoughTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1JoystickRoughTerrain --wandb_entity your_wandb_entity --suffix xxx
# T1JoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1JoystickFlatTerrain --wandb_entity your_wandb_entity --suffix xxx
Training logs and artifacts are saved under:
logs/
  <ENV>-<YYYYmmdd-HHMMSS>-<suffix?>/
    checkpoints/     # config snapshot (e.g., config.json)
    policies/        # policy{step}.pkl (normalizer + policy params via dill)
    videos/          # rollout{step}.mp4 (if --render)
    buffer_data/     # saved replay (if --save_buffer_data)
Model naming
*.pkl: direct sim-to-sim zero-shot from MuJoCo Playground to Brax (no Brax training).Note
[-1, 1] m/s. During fine-tuning, set new targets (e.g., 1.0/1.2/1.5 m/s).# T1 — zero-shot sim2sim
CUDA_VISIBLE_DEVICES=0 python eval_in_brax.py --env t1 --model models/T1LowDimSimFinetuneJoystickFlatTerrain_policy40009000.pkl
# T1 Low-Dim Sim Finetune (flat)
CUDA_VISIBLE_DEVICES=0 python -u train_wm_from_file.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --data_path=logs/T1LowDimSimFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix> --wandb_entity your_wandb_entity

# G1 Low-Dim (flat)
CUDA_VISIBLE_DEVICES=0 python -u train_wm_from_file.py --env_name=G1LowDimJoystickFlatTerrain --data_path logs/G1LowDimJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix> --wandb_entity your_wandb_entity
Training logs and artifacts are saved under:
logs/
  <ENV>-<YYYYmmdd-HHMMSS>-<suffix?>/
    checkpoints/     # config snapshot (e.g., config.json)
    videos/          # rollout{step}.mp4 (if --render)
    wm_states/     # world model state
# Finetune in Brax (sim2sim) with pretrained policy + WM
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --suffix=sim2sim --ac_training_state_path=logs/T1LowDimSimFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/policies/policyXXXX.pkl --wm_training_state_path=logs/T1LowDimSimFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/wm_states/wm_stateXXXXX.pkl --wandb_entity your_wandb_entity

# example:
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --suffix=sim2sim --ac_training_state_path=models/T1LowDimSimFinetuneJoystickFlatTerrain_policy40009000.pkl --wm_training_state_path=models/T1LowDimSimFinetuneJoystickFlatTerrain_wm_state40.pkl --wandb_entity your_wandb_entity

# G1 Low-Dim (flat) fine-tune
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=G1LowDimJoystickFlatTerrain --suffix=sim2sim --ac_training_state_path=logs/G1LowDimJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/policies/policyXXXX.pkl --wm_training_state_path=logs/G1LowDimJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/wm_states/wm_stateXXXXX.pkl --wandb_entity your_wandb_entity

# Real-world fine-tune uses T1LowDimRealFinetuneJoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=T1LowDimRealFinetuneJoystickFlatTerrain --suffix=real --ac_training_state_path=logs/T1LowDimRealFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/policies/policyXXXX.pkl --wm_training_state_path=logs/T1LowDimRealFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/wm_states/wm_stateXXXXX.pkl --wandb_entity your_wandb_entity
For zero-shot real deployment, pretrain on T1LowDimJoystickRoughTerrain, convert the SAC policy to TorchScript, validate in MuJoCo, then deploy with BoosterGym.
# 1) Pretrain the zero-shot policy
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimJoystickRoughTerrain --domain_randomization --suffix zeroshot

# 2) Convert SAC .pkl to TorchScript and check performance in MuJoCo (converts automatically if needed)
python mujoco_env/play_mujoco.py --sac_training_state_path logs/T1LowDimJoystickRoughTerrain-YYYYmmdd-HHMMSS-zeroshot/policies/policyXXXX.pkl --render

example:
python mujoco_env/play_mujoco.py --sac_training_state_path models/T1LowDimJoystickRoughTerrain_policy110119000.pkl

# this policy is trained using the T1LowDimJoystickRoughTerrain
Then deploy the TorchScript policy with the BoosterGym real-robot deployment pipeline.
Use train_in_mujoco_playground_optuna.py to tune SAC parameters for any robot/environment.
You could use the following command for multi-GPU hyperparameter tuning.
# Example: tune on T1 Low-Dim (flat)
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground_optuna.py --env_name=T1LowDimJoystickRoughTerrain --storage=sqlite:///optuna_sac_t1.db --study_name=t1_sac_tuning --sampler=cmaes --domain_randomization --popsize=12
If you find this repository helpful, please consider citing:
@inproceedings{
lifthumanoid,
title={Towards Bridging the Gap between Large-Scale Pretraining and Efficient Finetuning for Humanoid Control},
author={Weidong Huang and Zhehan Li and Hangxin Liu and Biao Hou and Yao Su and Jingwen Zhang},
booktitle={The Fourteenth International Conference on Learning Representations},
year={2026},
url={https://openreview.net/forum?id=NEOTsyyYH7}
}
Thanks to the open-source community for foundational tooling and datasets.
@inproceedings{akiba2019optuna,
  title={{O}ptuna: A Next-Generation Hyperparameter Optimization Framework},
  author={Akiba, Takuya and Sano, Shotaro and Yanase, Toshihiko and Ohta, Takeru and Koyama, Masanori},
  booktitle={The 25th ACM SIGKDD International Conference on Knowledge Discovery \& Data Mining},
  pages={2623--2631},
  year={2019}
}
@software{brax2021github,
  author = {C. Daniel Freeman and Erik Frey and Anton Raichuk and Sertan Girgin and Igor Mordatch and Olivier Bachem},
  title = {Brax - A Differentiable Physics Engine for Large Scale Rigid Body Simulation},
  url = {http://github.com/google/brax},
  version = {0.14.0},
  year = {2021},
}
@inproceedings{levy2024learning,
  title={Learning to Walk from Three Minutes of Real-World Data with Semi-structured Dynamics Models},
  author={Levy, Jacob and Westenbroek, Tyler and Fridovich-Keil, David},
  booktitle={8th Annual Conference on Robot Learning},
  year={2024}
}
@article{zakka2025mujoco,
  title={MuJoCo Playground},
  author={Zakka, Kevin and Tabanpour, Baruch and Liao, Qiayuan and Haiderbhai, Mustafa and Holt, Samuel and Luo, Jing Yuan and Allshire, Arthur and Frey, Erik and Sreenath, Koushil and Kahrs, Lueder A and others},
  journal={arXiv preprint arXiv:2502.08844},
  year={2025}
}
@article{raffin2025isaacsim,
  title   = "Getting SAC to Work on a Massive Parallel Simulator: An RL Journey With Off-Policy Algorithms",
  author  = "Raffin, Antonin",
  journal = "araffin.github.io",
  year    = "2025",
  month   = "Feb",
  url     = "https://araffin.github.io/post/sac-massive-sim/"
}
@article{wang2025booster,
  title={Booster Gym: An End-to-End Reinforcement Learning Framework for Humanoid Robot Locomotion},
  author={Wang, Yushi and Chen, Penghui and Han, Xinyu and Wu, Feng and Zhao, Mingguo},
  journal={arXiv preprint arXiv:2506.15132},
  year={2025}
}
@article{liao2025beyondmimic,
  title={Beyondmimic: From motion tracking to versatile humanoid control via guided diffusion},
  author={Liao, Qiayuan and Truong, Takara E and Huang, Xiaoyu and Gao, Yuman and Tevet, Guy and Sreenath, Koushil and Liu, C Karen},
  journal={arXiv preprint arXiv:2508.08241},
  year={2025}
}
ICLR 2026: Towards Bridging the Gap between Large-Scale Pretraining and Efficient Finetuning for Humanoid Controls
Python
121
6 commits
updated Mar 28, 2026
Weidong Huang · Zhehan Li · Hangxin Liu · Biao Hou · Yao Su· Jingwen Zhang†
· Primary contact: Weidong Huang
(bigeasthuang@gmail.com)
LIFT (Large-scale pretraIning and efficient FineTuning) is a three-stage framework that bridges scalable simulation pretraining and safe, efficient adaptation for humanoid control:
| Real World Deployment | Brax (Sim2Sim) | Brax (After Finetuning) |
|---|---|---|
|
|
|
|
See more (videos + code) on the project website: https://lift-humanoid.github.io/
(Ubuntu 22.04 and Python 3.10 recommended). Minimal quickstart:
This code is tested on NVIDIA H800 and 4090.
conda create -n lift python=3.10 -c conda-forge -y
conda activate lift
cd mujoco_playground
pip install -e .
cd ..
cd brax_env
pip install -e .
cd ..
pip install -r requirements.txt
Train Policy → Pretrain World Model → Finetune
Train Policy: pretrain with SAC (large batch + high UTD) in MuJoCo Playground and enable zero-shot deployment of the pretrained policy on physical humanoids.
Pretrain World Model: pretrain the physics-informed world model using the SAC offline data.
Sim2Sim and Fine-tuning: transfer the pretrained policy to Brax and fine-tune with a physics-informed world model. The environment executes deterministic actions; stochastic exploration is confined to the world model.
Use T1LowDimSimFinetuneJoystickFlatTerrain or G1LowDimJoystickFlatTerrain to pretrain the policy and save replay data for world-model pretraining + fine-tuning.
# T1 Low-Dim Sim Finetune (flat) — policy pretraining + buffer for WM/fine-tuning
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --domain_randomization --num_timesteps 40000000 --num_evals 10 --save_buffer_data  --wandb_entity your_wandb_entity

# G1 Low-Dim (flat) — policy pretraining + buffer for WM/fine-tuning
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=G1LowDimJoystickFlatTerrain --domain_randomization --num_timesteps 60000000 --num_evals 10 --save_buffer_data  --wandb_entity your_wandb_entity

# T1 Low-Dim Real World Finetune (flat) — policy pretraining + buffer for WM/fine-tuning (this setting is used for real world finetune experiment)
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimRealFinetuneJoystickFlatTerrain --domain_randomization --num_timesteps 40000000 --num_evals 10 --save_buffer_data  --wandb_entity your_wandb_entity
G1JoystickFlatTerrainG1JoystickRoughTerrainT1JoystickRoughTerrainT1JoystickFlatTerrainT1LowDimJoystickRoughTerrainT1LowDimJoystickFlatTerrain# T1LowDimJoystickRoughTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimJoystickRoughTerrain --wandb_entity your_wandb_entity --domain_randomization --suffix xxx
# T1LowDimJoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimJoystickFlatTerrain --wandb_entity your_wandb_entity --domain_randomization --suffix xxx
# G1JoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python -u train_in_mujoco_playground.py --env_name=G1JoystickFlatTerrain --wandb_entity your_wandb_entity --suffix xxx
# G1JoystickRoughTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=G1JoystickRoughTerrain --wandb_entity your_wandb_entity --suffix xxx
# T1JoystickRoughTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1JoystickRoughTerrain --wandb_entity your_wandb_entity --suffix xxx
# T1JoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1JoystickFlatTerrain --wandb_entity your_wandb_entity --suffix xxx
Training logs and artifacts are saved under:
logs/
  <ENV>-<YYYYmmdd-HHMMSS>-<suffix?>/
    checkpoints/     # config snapshot (e.g., config.json)
    policies/        # policy{step}.pkl (normalizer + policy params via dill)
    videos/          # rollout{step}.mp4 (if --render)
    buffer_data/     # saved replay (if --save_buffer_data)
Model naming
*.pkl: direct sim-to-sim zero-shot from MuJoCo Playground to Brax (no Brax training).Note
[-1, 1] m/s. During fine-tuning, set new targets (e.g., 1.0/1.2/1.5 m/s).# T1 — zero-shot sim2sim
CUDA_VISIBLE_DEVICES=0 python eval_in_brax.py --env t1 --model models/T1LowDimSimFinetuneJoystickFlatTerrain_policy40009000.pkl
# T1 Low-Dim Sim Finetune (flat)
CUDA_VISIBLE_DEVICES=0 python -u train_wm_from_file.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --data_path=logs/T1LowDimSimFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix> --wandb_entity your_wandb_entity

# G1 Low-Dim (flat)
CUDA_VISIBLE_DEVICES=0 python -u train_wm_from_file.py --env_name=G1LowDimJoystickFlatTerrain --data_path logs/G1LowDimJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix> --wandb_entity your_wandb_entity
Training logs and artifacts are saved under:
logs/
  <ENV>-<YYYYmmdd-HHMMSS>-<suffix?>/
    checkpoints/     # config snapshot (e.g., config.json)
    videos/          # rollout{step}.mp4 (if --render)
    wm_states/     # world model state
# Finetune in Brax (sim2sim) with pretrained policy + WM
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --suffix=sim2sim --ac_training_state_path=logs/T1LowDimSimFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/policies/policyXXXX.pkl --wm_training_state_path=logs/T1LowDimSimFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/wm_states/wm_stateXXXXX.pkl --wandb_entity your_wandb_entity

# example:
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=T1LowDimSimFinetuneJoystickFlatTerrain --suffix=sim2sim --ac_training_state_path=models/T1LowDimSimFinetuneJoystickFlatTerrain_policy40009000.pkl --wm_training_state_path=models/T1LowDimSimFinetuneJoystickFlatTerrain_wm_state40.pkl --wandb_entity your_wandb_entity

# G1 Low-Dim (flat) fine-tune
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=G1LowDimJoystickFlatTerrain --suffix=sim2sim --ac_training_state_path=logs/G1LowDimJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/policies/policyXXXX.pkl --wm_training_state_path=logs/G1LowDimJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/wm_states/wm_stateXXXXX.pkl --wandb_entity your_wandb_entity

# Real-world fine-tune uses T1LowDimRealFinetuneJoystickFlatTerrain
CUDA_VISIBLE_DEVICES=0 python finetune.py --env_name=T1LowDimRealFinetuneJoystickFlatTerrain --suffix=real --ac_training_state_path=logs/T1LowDimRealFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/policies/policyXXXX.pkl --wm_training_state_path=logs/T1LowDimRealFinetuneJoystickFlatTerrain-YYYYmmdd-HHMMSS-<suffix>/wm_states/wm_stateXXXXX.pkl --wandb_entity your_wandb_entity
For zero-shot real deployment, pretrain on T1LowDimJoystickRoughTerrain, convert the SAC policy to TorchScript, validate in MuJoCo, then deploy with BoosterGym.
# 1) Pretrain the zero-shot policy
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground.py --env_name=T1LowDimJoystickRoughTerrain --domain_randomization --suffix zeroshot

# 2) Convert SAC .pkl to TorchScript and check performance in MuJoCo (converts automatically if needed)
python mujoco_env/play_mujoco.py --sac_training_state_path logs/T1LowDimJoystickRoughTerrain-YYYYmmdd-HHMMSS-zeroshot/policies/policyXXXX.pkl --render

example:
python mujoco_env/play_mujoco.py --sac_training_state_path models/T1LowDimJoystickRoughTerrain_policy110119000.pkl

# this policy is trained using the T1LowDimJoystickRoughTerrain
Then deploy the TorchScript policy with the BoosterGym real-robot deployment pipeline.
Use train_in_mujoco_playground_optuna.py to tune SAC parameters for any robot/environment.
You could use the following command for multi-GPU hyperparameter tuning.
# Example: tune on T1 Low-Dim (flat)
CUDA_VISIBLE_DEVICES=0 python train_in_mujoco_playground_optuna.py --env_name=T1LowDimJoystickRoughTerrain --storage=sqlite:///optuna_sac_t1.db --study_name=t1_sac_tuning --sampler=cmaes --domain_randomization --popsize=12
If you find this repository helpful, please consider citing:
@inproceedings{
lifthumanoid,
title={Towards Bridging the Gap between Large-Scale Pretraining and Efficient Finetuning for Humanoid Control},
author={Weidong Huang and Zhehan Li and Hangxin Liu and Biao Hou and Yao Su and Jingwen Zhang},
booktitle={The Fourteenth International Conference on Learning Representations},
year={2026},
url={https://openreview.net/forum?id=NEOTsyyYH7}
}
Thanks to the open-source community for foundational tooling and datasets.
@inproceedings{akiba2019optuna,
  title={{O}ptuna: A Next-Generation Hyperparameter Optimization Framework},
  author={Akiba, Takuya and Sano, Shotaro and Yanase, Toshihiko and Ohta, Takeru and Koyama, Masanori},
  booktitle={The 25th ACM SIGKDD International Conference on Knowledge Discovery \& Data Mining},
  pages={2623--2631},
  year={2019}
}
@software{brax2021github,
  author = {C. Daniel Freeman and Erik Frey and Anton Raichuk and Sertan Girgin and Igor Mordatch and Olivier Bachem},
  title = {Brax - A Differentiable Physics Engine for Large Scale Rigid Body Simulation},
  url = {http://github.com/google/brax},
  version = {0.14.0},
  year = {2021},
}
@inproceedings{levy2024learning,
  title={Learning to Walk from Three Minutes of Real-World Data with Semi-structured Dynamics Models},
  author={Levy, Jacob and Westenbroek, Tyler and Fridovich-Keil, David},
  booktitle={8th Annual Conference on Robot Learning},
  year={2024}
}
@article{zakka2025mujoco,
  title={MuJoCo Playground},
  author={Zakka, Kevin and Tabanpour, Baruch and Liao, Qiayuan and Haiderbhai, Mustafa and Holt, Samuel and Luo, Jing Yuan and Allshire, Arthur and Frey, Erik and Sreenath, Koushil and Kahrs, Lueder A and others},
  journal={arXiv preprint arXiv:2502.08844},
  year={2025}
}
@article{raffin2025isaacsim,
  title   = "Getting SAC to Work on a Massive Parallel Simulator: An RL Journey With Off-Policy Algorithms",
  author  = "Raffin, Antonin",
  journal = "araffin.github.io",
  year    = "2025",
  month   = "Feb",
  url     = "https://araffin.github.io/post/sac-massive-sim/"
}
@article{wang2025booster,
  title={Booster Gym: An End-to-End Reinforcement Learning Framework for Humanoid Robot Locomotion},
  author={Wang, Yushi and Chen, Penghui and Han, Xinyu and Wu, Feng and Zhao, Mingguo},
  journal={arXiv preprint arXiv:2506.15132},
  year={2025}
}
@article{liao2025beyondmimic,
  title={Beyondmimic: From motion tracking to versatile humanoid control via guided diffusion},
  author={Liao, Qiayuan and Truong, Takara E and Huang, Xiaoyu and Gao, Yuman and Tevet, Guy and Sreenath, Koushil and Liu, C Karen},
  journal={arXiv preprint arXiv:2508.08241},
  year={2025}
}



