This corpus release contains 4,993 abstracts annotated with (P)articipants, (I)nterventions, and (O)utcomes. Training labels are sourced from AMT workers and aggregated to reduce noise. Test labels are collected from medical professionals. A sample annotated document looks like:
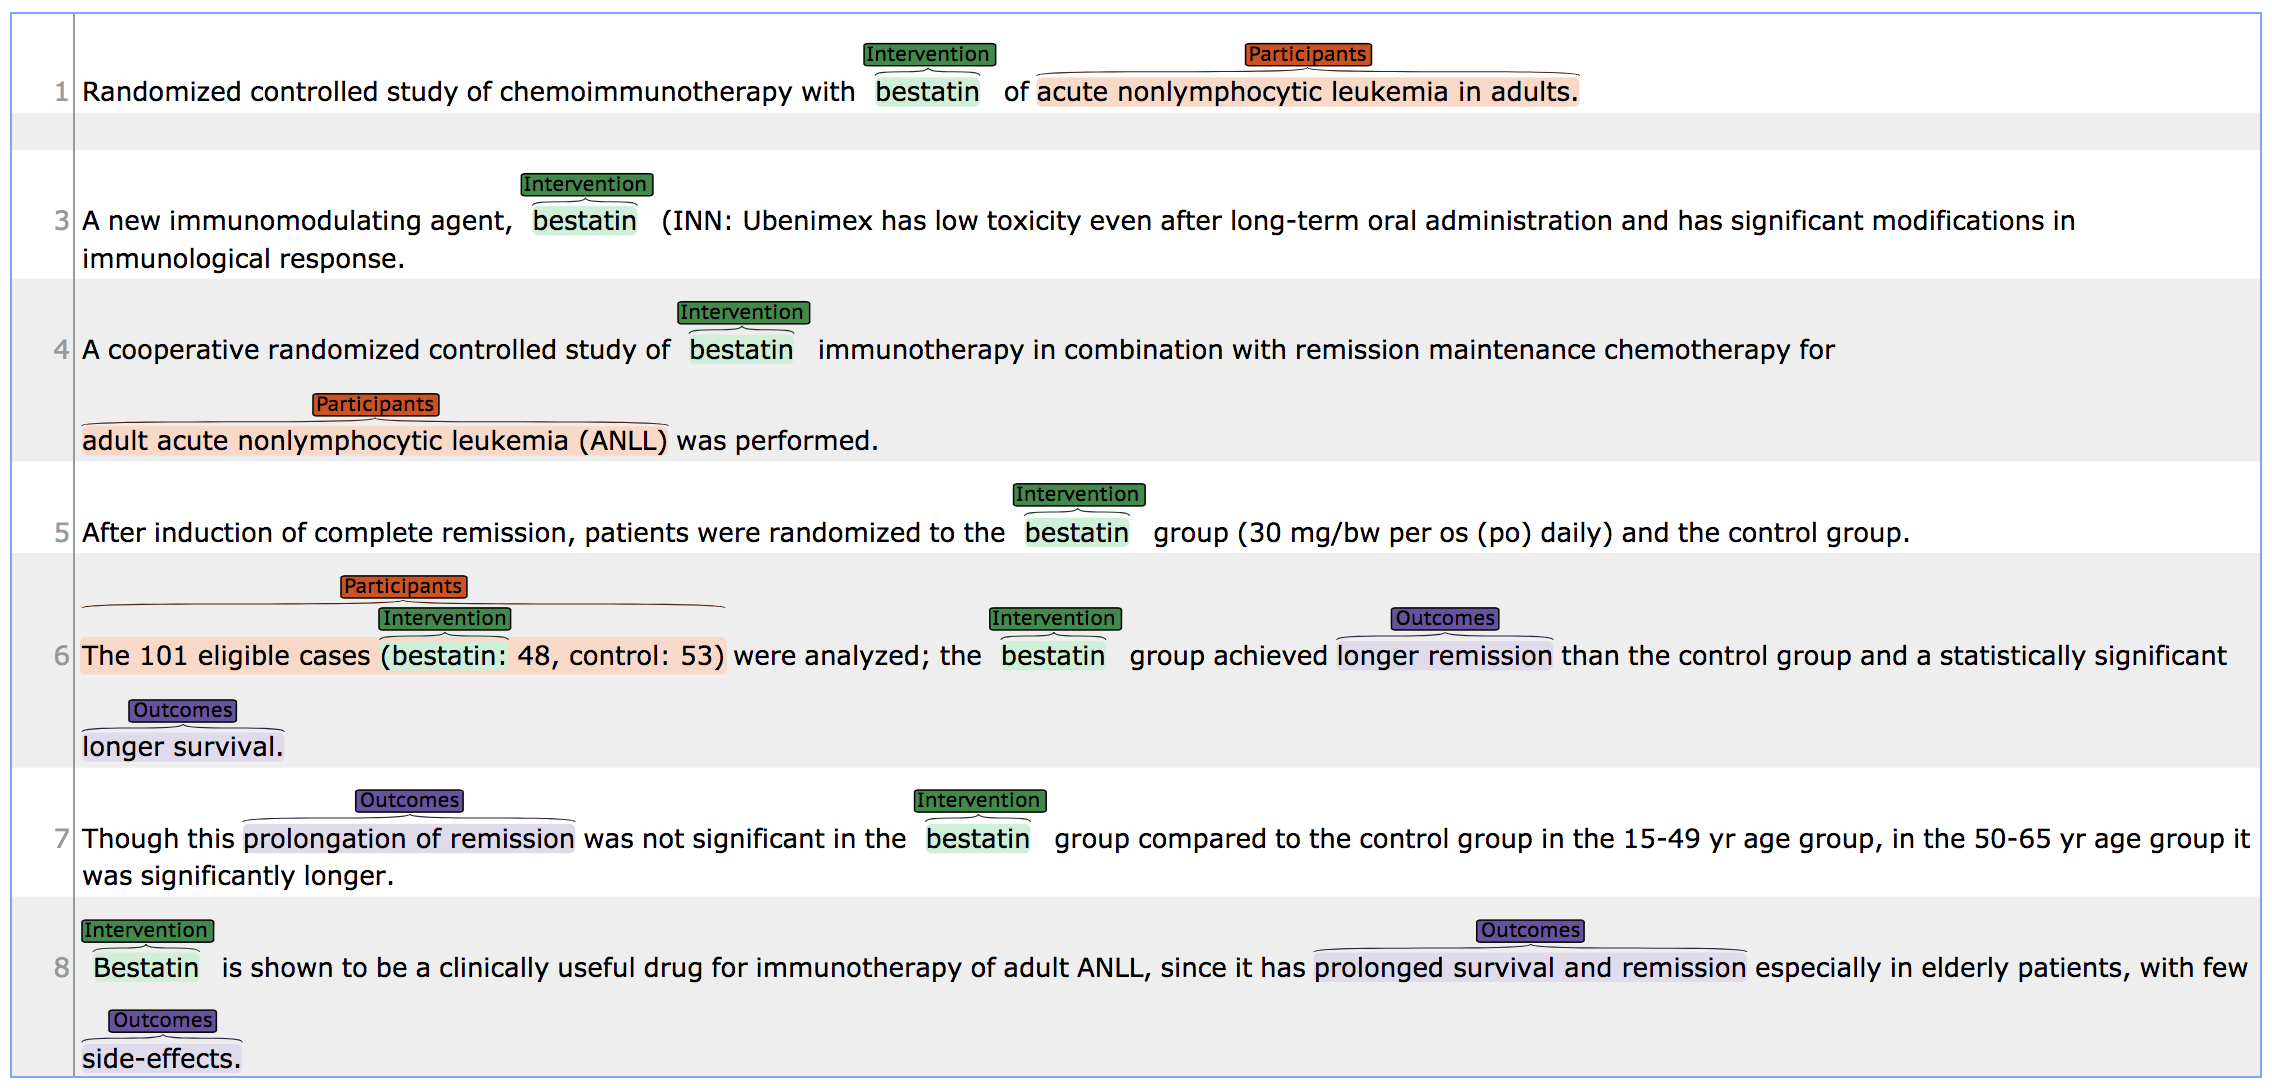
Full annotations are available in ebm_nlp_*.tar.gz, which are organized as follows.
documents/
Documents are labeled by their PubMed identification number (PMID). Each document has two files:
documents/{PMID}.text Raw text of the abstractdocuments/{PMID}.tokens Tokenized text to which the labels are assignedannotations/{aggregated|individual}/
Since each document is multiply-annotated, we present two versions of the data:
aggregated Recommended - One set of labels per document derived from a voting strategy.individual All labels from each worker (multiply-annotated documents, noisy).../{starting_spans|hierarchical_labels}/
starting_spans/ Labels for P/I/O text spanshierarchical_labels/ Detailed labels for each starting span.../{participants|interventions|outcomes}/
Labels for each P/I/O element are separated since they occasionally overlap (for 3% of tokens). An example of combining them for joint learning can be found in https://github.com/bepnye/EBM-NLP/tree/master/models/lstm-crf
The label mappings for each PIO element are:
| label | P | I | O |
|---|---|---|---|
| 0 | No label | No label | No label |
| 1 | Age | Surgical | Physical |
| 2 | Sex | Physical | Pain |
| 3 | Sample size | Drug | Mortality |
| 4 | Condition | Educational | Adverse effects |
| 5 | Psychological | Mental | |
| 6 | Other | Other | |
| 7 | Control |
319 followers · starred Dec 2022
1,474 followers · starred Dec 2022
This corpus release contains 4,993 abstracts annotated with (P)articipants, (I)nterventions, and (O)utcomes. Training labels are sourced from AMT workers and aggregated to reduce noise. Test labels are collected from medical professionals. A sample annotated document looks like:
Full annotations are available in ebm_nlp_*.tar.gz, which are organized as follows.
documents/
Documents are labeled by their PubMed identification number (PMID). Each document has two files:
documents/{PMID}.text Raw text of the abstractdocuments/{PMID}.tokens Tokenized text to which the labels are assignedannotations/{aggregated|individual}/
Since each document is multiply-annotated, we present two versions of the data:
aggregated Recommended - One set of labels per document derived from a voting strategy.individual All labels from each worker (multiply-annotated documents, noisy).../{starting_spans|hierarchical_labels}/
starting_spans/ Labels for P/I/O text spanshierarchical_labels/ Detailed labels for each starting span.../{participants|interventions|outcomes}/
Labels for each P/I/O element are separated since they occasionally overlap (for 3% of tokens). An example of combining them for joint learning can be found in https://github.com/bepnye/EBM-NLP/tree/master/models/lstm-crf
The label mappings for each PIO element are:
| label | P | I | O |
|---|---|---|---|
| 0 | No label | No label | No label |
| 1 | Age | Surgical | Physical |
| 2 | Sex | Physical | Pain |
| 3 | Sample size | Drug | Mortality |
| 4 | Condition | Educational | Adverse effects |
| 5 | Psychological | Mental | |
| 6 | Other | Other | |
| 7 | Control |
319 followers · starred Dec 2022
1,474 followers · starred Dec 2022