beccabai/Data-centric_multimodal_LLM

Survey on Data-centric Large Language Models

94

25 commits

updated Jul 8, 2024

See the code

README

Data-centric Multimodal LLM

Survey on data-centric multimodal large language models
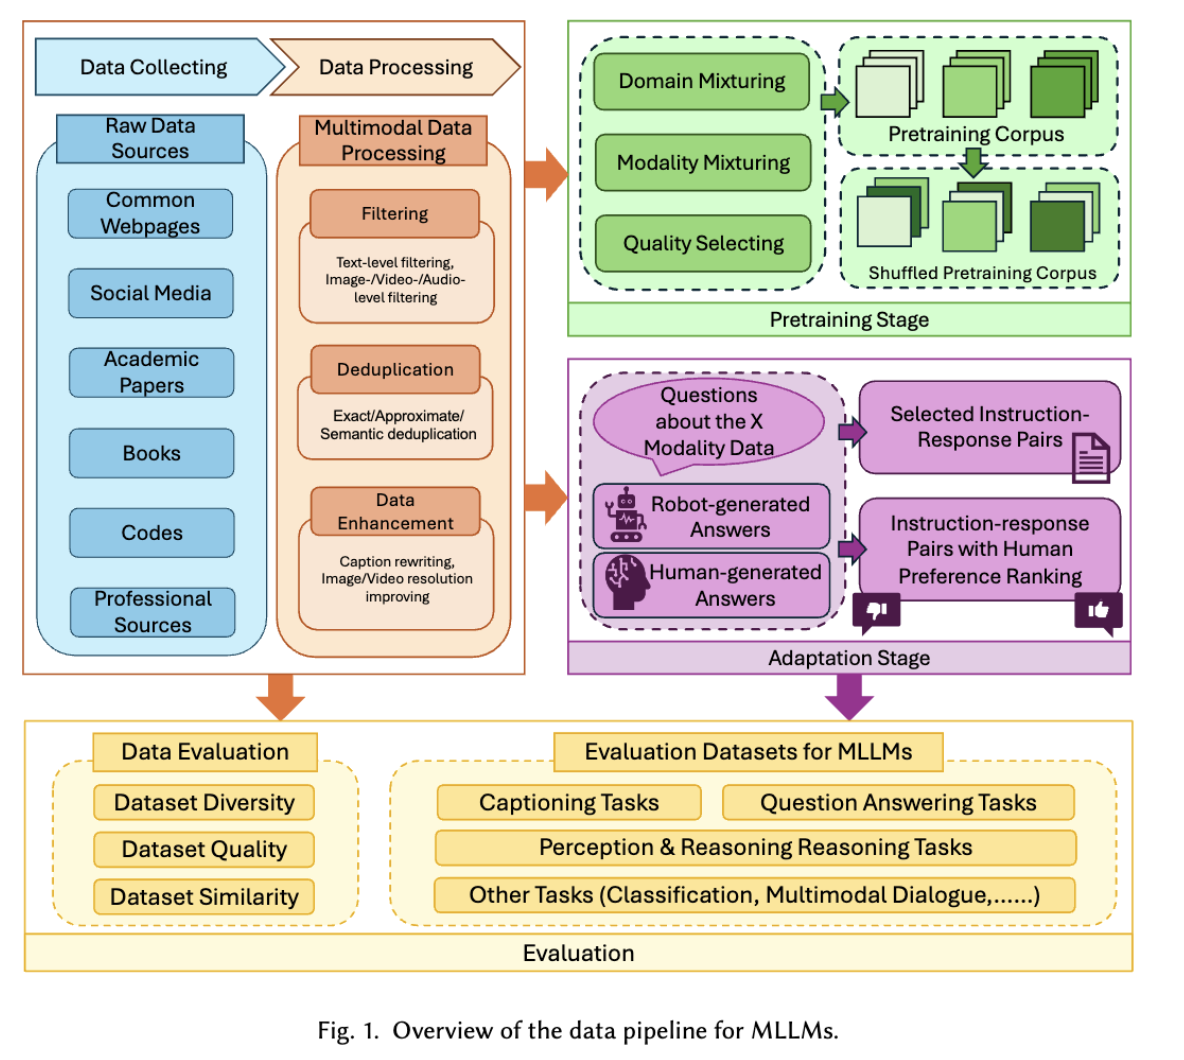
Paper

Sources

List of Sources

Source NameSource LinkType
CommonCrawlhttps://commoncrawl.org/Common Webpages
Flickrhttps://www.flickr.com/Common Webpages
Flickr Videohttps://www.flickr.com/photos/tags/vídeo/Common Webpages
FreeSoundhttps://freesound.orgCommon Webpages
BBC Sound Effects4https://sound-effects.bbcrewind.co.ukCommon Webpages
SoundBiblehttps://soundbible.com/Common Webpages
Wikipediahttps://www.wikipedia.org/Wikipedia
Wikimedia Commonshttps://commons.wikimedia.org/Wikipedia
Stack Exchangehttps://stackexchange.com/Social Media
Reddithttps://www.reddit.com/Social Media
Ubuntu IRChttps://ubuntu.com/Social Media
Youtubehttps://www.youtube.comSocial Media
Xhttps://x.comSocial Media
S2ORChttps://github.com/allenai/s2orcAcademic Papers
Arxivhttps://arxiv.org/Academic Papers
Project Gutenberghttps://www.gutenberg.orgBooks
Smashwordshttps://www.smashwords.com/Books
Bibliotikhttps://bibliotik.me/Books
National Diet Libraryhttps://dl.ndl.go.jp/ja/photoBooks
BigQuery public datasethttps://cloud.google.com/bigquery/public-dataCode
GitHubhttps://github.com/Code
FreeLawhttps://www.freelaw.in/Legal
Chinese legal documentshttps://www.spp.gov.cn/spp/fl/Legal
Khan Academy exerciseshttps://www.khanacademy.orgMaths
MEDLINEwww.medline.comMedical
Patienthttps://patient.infoMedical
WebMDhttps://www.webmd.comMedical
NIHhttps://www.nih.gov/Medical
39 Ask Doctorhttps://ask.39.net/Medical
Medical Examshttps://drive.google.com/file/d/1ImYUSLk9JbgHXOemfvyiDiirluZHPeQw/viewMedical
Baidu Doctorhttps://muzhi.baidu.com/Medical
120 Askshttps://www.120ask.com/Medical
BMJ Case Reportshttps://casereports.bmj.comMedical
XYWYhttp://www.xywy.comMedical
Qianwen Healthhttps://51zyzy.comMedical
PubMedhttps://pubmed.ncbi.nlm.nih.govMedical
EDGARhttps://www.sec.gov/edgarFinancial
SEC Financial Statement and Notes Data Setshttps://www.sec.gov/dera/data/financial-statement-and-notes-data-setFinancial
Sina Financehttps://finance.sina.com.cn/Financial
Tencent Financehttps://new.qq.com/ch/finance/Financial
Eastmoneyhttps://www.eastmoney.com/Financial
Gubahttps://guba.eastmoney.com/Financial
Xueqiuhttps://xueqiu.com/Financial
Phoenix Financehttps://finance.ifeng.com/Financial
36Krhttps://36kr.com/Financial
Huxiuhttps://www.huxiu.com/Financial

Commonly-used datasets

Textual-Pretraining Datasets:

DatasetsLink
RedPajama-Data-1Thttps://www.together.ai/blog/redpajama
RedPajama-Data-v2https://www.together.ai/blog/redpajama-data-v2
SlimPajamahttps://huggingface.co/datasets/cerebras/SlimPajama-627B
Falcon-RefinedWebhttps://huggingface.co/datasets/tiiuae/falcon-refinedweb
Pilehttps://github.com/EleutherAI/the-pile?tab=readme-ov-file
ROOTShttps://huggingface.co/bigscience-data
WuDaoCorporahttps://data.baai.ac.cn/details/WuDaoCorporaText
Common Crawlhttps://commoncrawl.org/
C4https://huggingface.co/datasets/c4
mC4https://arxiv.org/pdf/2010.11934.pdf
Dolma Datasethttps://github.com/allenai/dolma
OSCAR-22.01https://oscar-project.github.io/documentation/versions/oscar-2201/
OSCAR-23.01https://huggingface.co/datasets/oscar-corpus/OSCAR-2301
colossal-oscar-1.0https://huggingface.co/datasets/oscar-corpus/colossal-oscar-1.0
Wiki40bhttps://www.tensorflow.org/datasets/catalog/wiki40b
Pushshift Reddit Datasethttps://paperswithcode.com/dataset/pushshift-reddit
OpenWebTextCorpushttps://paperswithcode.com/dataset/openwebtext
OpenWebText2https://openwebtext2.readthedocs.io/en/latest/
BookCorpushttps://huggingface.co/datasets/bookcorpus
Gutenberghttps://shibamoulilahiri.github.io/gutenberg_dataset.html
CC-Stories-Rhttps://paperswithcode.com/dataset/cc-stories
CC-NEWEShttps://huggingface.co/datasets/cc_news
REALNEWShttps://paperswithcode.com/dataset/realnews
Reddit submission datasethttps://www.philippsinger.info/reddit/
General Reddit Datasethttps://www.tensorflow.org/datasets/catalog/reddit
AMPShttps://drive.google.com/file/d/1hQsua3TkpEmcJD_UWQx8dmNdEZPyxw23/view

MM-Pretraining Datasets:

Dataset NamePaper Title (with hyperlink)Modality
ALIGNScaling up visual and vision-language representation learning with noisy text supervisionImage
LTIPFlamingo: a visual language model for few-shot learningImage
MS-COCOMicrosoft coco: Common objects in contextImage
Visual GenomeVisual genome: Connecting language and vision using crowdsourced dense image annotationsImage
CC3MConceptual captions: A cleaned, hypernymed, image alt-text dataset for automatic image captioningImage
CC12MConceptual 12M: Pushing Web-Scale Image-Text Pre-Training To Recognize Long-Tail Visual ConceptsGraph
SBUIm2text: Describing images using 1 million captioned photographsImage
LAION-5BLaion-5b: An open large-scale dataset for training next generation image-text modelsImage
LAION-400MLaion-400m: Open dataset of clip-filtered 400 million image-text pairsImage
LAION-COCOLaion-coco: In the style of MS COCOImage
Flickr30kFrom image descriptions to visual denotations: New similarity metrics for semantic inference over event descriptionsImage
AI ChallengerAi challenger: A large-scale dataset for going deeper in image understandingImage
COYOCOYO-700M: Image-Text Pair DatasetImage
WukongWukong: A 100 million large-scale chinese cross-modal pre-training benchmarkImage
COCO CaptionMicrosoft coco captions: Data collection and evaluation serverImage
WebLIPali: A jointly-scaled multilingual language-image modelImage
Episodic WebLIPali-x: On scaling up a multilingual vision and language modelImage
CC595kVisual instruction tuningImage
ReferItGameReferitgame: Referring to objects in photographs of natural scenesImage
RefCOCO&RefCOCO+Modeling context in referring expressionsImage
Visual-7WVisual7w: Grounded question answering in imagesImage
OCR-VQAOcr-vqa: Visual question answering by reading text in imagesImage
ST-VQAScene text visual question answeringImage
DocVQADocvqa: A dataset for vqa on document imagesImage
TextVQATowards vqa models that can readImage
DataCompDatacomp: In search of the next generation of multimodal datasetsImage
GQAGqa: A new dataset for real-world visual reasoning and compositional question answeringImage
VQAVQA: Visual Question AnsweringImage
VQAv2Making the v in vqa matter: Elevating the role of image understanding in visual question answeringImage
DVQADvqa: Understanding data visualizations via question answeringImage
A-OK-VQAA-okvqa: A benchmark for visual question answering using world knowledgeImage
Text CaptionsTextcaps: a dataset for image captioning with reading comprehensionImage
M3WFlamingo: a visual language model for few-shot learningImage
MMC4Multimodal c4: An open, billion-scale corpus of images interleaved with textImage
MSRVTTMsr-vtt: A large video description dataset for bridging video and languageVideo
WebVid-2MFrozen in time: A joint video and image encoder for end-to-end retrievalVideo
VTPFlamingo: a visual language model for few-shot learningVideo
AISHELL-1Aishell-1: An open-source mandarin speech corpus and a speech recognition baselineAudio
AISHELL-2Aishell-2: Transforming mandarin asr research into industrial scaleAudio
WaveCapsWavcaps: A chatgpt-assisted weakly-labelled audio captioning dataset for audio-language multimodal researchAudio
VisDialVisual dialogImage
VSDial-CNX-llm: Bootstrapping advanced large language models by treating multi-modalities as foreign languagesImage, Audio
MELONAudio Retrieval for Multimodal Design Documents: A New Dataset and AlgorithmsImage, Text, Audio

Common Textual SFT Datasets:

Dataset NameLanguageConstruction MethodGithub LinkPaper LinkDataset Link
databricks-dolly-15KENHGhttps://huggingface.co/datasets/databricks/databricks-dolly-15k
InstructionWild_v2EN & ZHHGhttps://github.com/XueFuzhao/InstructionWild
LCCCZHHGhttps://github.com/thu-coai/CDial-GPThttps://arxiv.org/pdf/2008.03946.pdf
OASST1Multi (35)HGhttps://github.com/imoneoi/openchathttps://arxiv.org/pdf/2309.11235.pdfhttps://huggingface.co/openchat
OL-CCZHHGhttps://data.baai.ac.cn/details/OL-CC
Zhihu-KOLZHHGhttps://github.com/wangrui6/Zhihu-KOLhttps://huggingface.co/datasets/wangrui6/Zhihu-KOL
Aya DatasetMulti (65)HGhttps://arxiv.org/abs/2402.06619https://hf.co/datasets/CohereForAI/aya_dataset
InstructIEEN & ZHHGhttps://github.com/zjunlp/KnowLMhttps://arxiv.org/abs/2305.11527https://huggingface.co/datasets/zjunlp/InstructIE
Alpaca_dataENMChttps://github.com/tatsu-lab/stanford_alpaca#data-release
BELLE_Generated_ChatZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/generated_chat_0.4M
BELLE_Multiturn_ChatZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/multiturn_chat_0.8M
BELLE_train_0.5M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/1.5Mhttps://huggingface.co/datasets/BelleGroup/train_0.5M_CN
BELLE_train_1M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/1.5Mhttps://huggingface.co/datasets/BelleGroup/train_1M_CN
BELLE_train_2M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/train_2M_CN
BELLE_train_3.5M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/train_3.5M_CN
CAMELMulti & PLMChttps://github.com/camel-ai/camelhttps://arxiv.org/pdf/2303.17760.pdfhttps://huggingface.co/camel-ai
Chatgpt_corpusZHMChttps://github.com/PlexPt/chatgpt-corpus/releases/tag/3
InstructionWild_v1EN & ZHMChttps://github.com/XueFuzhao/InstructionWild
LMSYS-Chat-1MMultiMChttps://arxiv.org/pdf/2309.11998.pdfhttps://huggingface.co/datasets/lmsys/lmsys-chat-1m
MOSS_002_sft_dataEN & ZHMChttps://github.com/OpenLMLab/MOSShttps://huggingface.co/datasets/fnlp/moss-002-sft-data
MOSS_003_sft_dataEN & ZHMChttps://github.com/OpenLMLab/MOSS
MOSS_003_sft_plugin_dataEN & ZHMChttps://github.com/OpenLMLab/MOSS
OpenChatENMChttps://github.com/imoneoi/openchathttps://arxiv.org/pdf/2309.11235.pdfhttps://huggingface.co/openchat
RedGPT-Dataset-V1-CNZHMChttps://github.com/DA-southampton/RedGPT
Self-InstructENMChttps://github.com/yizhongw/self-instructhttps://aclanthology.org/2023.acl-long.754.pdf
ShareChatMultiMC
ShareGPT-Chinese-English-90kEN & ZHMChttps://github.com/CrazyBoyM/llama2-Chinese-chathttps://huggingface.co/datasets/shareAI/ShareGPT-Chinese-English-90k
ShareGPT90KENMChttps://huggingface.co/datasets/RyokoAI/ShareGPT52K
UltraChatENMChttps://github.com/thunlp/UltraChat#UltraLMhttps://arxiv.org/pdf/2305.14233.pdf
UnnaturalENMChttps://github.com/orhonovich/unnatural-instructionshttps://aclanthology.org/2023.acl-long.806.pdf
WebGLM-QAENMChttps://github.com/THUDM/WebGLMhttps://arxiv.org/pdf/2306.07906.pdfhttps://huggingface.co/datasets/THUDM/webglm-qa
Wizard_evol_instruct_196KENMChttps://github.com/nlpxucan/WizardLMhttps://arxiv.org/pdf/2304.12244.pdfhttps://huggingface.co/datasets/WizardLM/WizardLM_evol_instruct_V2_196k
Wizard_evol_instruct_70KENMChttps://github.com/nlpxucan/WizardLMhttps://arxiv.org/pdf/2304.12244.pdfhttps://huggingface.co/datasets/WizardLM/WizardLM_evol_instruct_70k
CrossFitENCIhttps://github.com/INK-USC/CrossFithttps://arxiv.org/pdf/2104.08835.pdf
DialogStudioENCIhttps://github.com/salesforce/DialogStudiohttps://arxiv.org/pdf/2307.10172.pdfhttps://huggingface.co/datasets/Salesforce/dialogstudio
DynosaurENCIhttps://github.com/WadeYin9712/Dynosaurhttps://arxiv.org/pdf/2305.14327.pdfhttps://huggingface.co/datasets?search=dynosaur
Flan-miniENCIhttps://github.com/declare-lab/flacunahttps://arxiv.org/pdf/2307.02053.pdfhttps://huggingface.co/datasets/declare-lab/flan-mini
FlanMultiCIhttps://github.com/google-research/flanhttps://arxiv.org/pdf/2109.01652.pdf
FlanMultiCIhttps://github.com/google-research/FLAN/tree/main/flan/v2https://arxiv.org/pdf/2301.13688.pdfhttps://huggingface.co/datasets/SirNeural/flan_v2
InstructDialENCIhttps://github.com/prakharguptaz/Instructdialhttps://arxiv.org/pdf/2205.12673.pdf
NATURAL INSTRUCTIONSENCIhttps://github.com/allenai/natural-instructionshttps://aclanthology.org/2022.acl-long.244.pdfhttps://instructions.apps.allenai.org/
OIGENCIhttps://huggingface.co/datasets/laion/OIG
Open-PlatypusENCIhttps://github.com/arielnlee/Platypushttps://arxiv.org/pdf/2308.07317.pdfhttps://huggingface.co/datasets/garage-bAInd/Open-Platypus
OPT-IMLMultiCIhttps://github.com/facebookresearch/metaseqhttps://arxiv.org/pdf/2212.12017.pdf
PromptSourceENCIhttps://github.com/bigscience-workshop/promptsourcehttps://aclanthology.org/2022.acl-demo.9.pdf
SUPER-NATURAL INSTRUCTIONSMultiCIhttps://github.com/allenai/natural-instructionshttps://arxiv.org/pdf/2204.07705.pdf
T0ENCIhttps://arxiv.org/pdf/2110.08207.pdf
UnifiedSKGENCIhttps://github.com/xlang-ai/UnifiedSKGhttps://arxiv.org/pdf/2201.05966.pdf
xP3Multi (46)CIhttps://github.com/bigscience-workshop/xmtfhttps://aclanthology.org/2023.acl-long.891.pdf
IEPileEN & ZHCIhttps://github.com/zjunlp/IEPilehttps://arxiv.org/abs/2402.14710https://huggingface.co/datasets/zjunlp/iepile
FireflyZHHG & CIhttps://github.com/yangjianxin1/Fireflyhttps://huggingface.co/datasets/YeungNLP/firefly-train-1.1M
LIMA-sftENHG & CIhttps://arxiv.org/pdf/2305.11206.pdfhttps://huggingface.co/datasets/GAIR/lima
COIG-CQIAZHHG & CIhttps://arxiv.org/abs/2403.18058https://huggingface.co/datasets/m-a-p/COIG-CQIA
InstructGPT-sftENHG & MChttps://arxiv.org/pdf/2203.02155.pdf
Alpaca_GPT4_dataENCI & MChttps://github.com/Instruction-Tuning-with-GPT-4/GPT-4-LLM#data-releasehttps://arxiv.org/pdf/2304.03277.pdf
Alpaca_GPT4_data_zhZHCI & MChttps://github.com/Instruction-Tuning-with-GPT-4/GPT-4-LLM#data-releasehttps://huggingface.co/datasets/shibing624/alpaca-zh
Bactrain-XMulti (52)CI & MChttps://github.com/mbzuai-nlp/bactrian-xhttps://arxiv.org/pdf/2305.15011.pdfhttps://huggingface.co/datasets/MBZUAI/Bactrian-X
BaizeENCI & MChttps://github.com/project-baize/baize-chatbothttps://arxiv.org/pdf/2304.01196.pdfhttps://github.com/project-baize/baize-chatbot/tree/main/data
GPT4AllENCI & MChttps://github.com/nomic-ai/gpt4allhttps://gpt4all.io/reports/GPT4All_Technical_Report_3.pdfhttps://huggingface.co/datasets/QingyiSi/Alpaca-CoT/tree/main/GPT4all
GuanacoDatasetMultiCI & MChttps://huggingface.co/datasets/JosephusCheung/GuanacoDataset
LaMini-LMENCI & MChttps://github.com/mbzuai-nlp/LaMini-LMhttps://arxiv.org/pdf/2304.14402.pdfhttps://huggingface.co/datasets/MBZUAI/LaMini-instruction
LogiCoTEN & ZHCI & MChttps://github.com/csitfun/logicothttps://arxiv.org/pdf/2305.12147.pdfhttps://huggingface.co/datasets/csitfun/LogiCoT
LongFormENCI & MChttps://github.com/akoksal/LongFormhttps://arxiv.org/pdf/2304.08460.pdfhttps://huggingface.co/datasets/akoksal/LongForm
Luotuo-QA-BEN & ZHCI & MChttps://github.com/LC1332/Luotuo-QAhttps://huggingface.co/datasets/Logic123456789/Luotuo-QA-B
OpenOrcaMultiCI & MChttps://arxiv.org/pdf/2306.02707.pdfhttps://huggingface.co/datasets/Open-Orca/OpenOrca
Wizard_evol_instruct_zhZHCI & MChttps://github.com/LC1332/Chinese-alpaca-lorahttps://huggingface.co/datasets/silk-road/Wizard-LM-Chinese-instruct-evol
COIGZHHG & CI & MChttps://github.com/FlagOpen/FlagInstructhttps://arxiv.org/pdf/2304.07987.pdfhttps://huggingface.co/datasets/BAAI/COIG
HC3EN & ZHHG & CI & MChttps://github.com/Hello-SimpleAI/chatgpt-comparison-detectionhttps://arxiv.org/pdf/2301.07597.pdf
Phoenix-sft-data-v1MultiHG & CI & MChttps://github.com/FreedomIntelligence/LLMZoohttps://arxiv.org/pdf/2304.10453.pdfhttps://huggingface.co/datasets/FreedomIntelligence/phoenix-sft-data-v1
TigerBot_sft_enENHG & CI & MChttps://github.com/TigerResearch/TigerBothttps://arxiv.org/abs/2312.08688https://huggingface.co/datasets/TigerResearch/sft_en
TigerBot_sft_zhZHHG & CI & MChttps://github.com/TigerResearch/TigerBothttps://arxiv.org/abs/2312.08688https://huggingface.co/datasets/TigerResearch/sft_zh
Aya CollectionMulti (114)HG & CI & MChttps://arxiv.org/abs/2402.06619https://hf.co/datasets/CohereForAI/aya_collection

Domain Specific Textual SFT Datasets:

Dataset NameLanguageDomainConstruction MethodGithub LinkPaper LinkDataset Link
ChatDoctorENMedicalHG & MChttps://github.com/Kent0n-Li/ChatDoctorhttps://arxiv.org/ftp/arxiv/papers/2303/2303.14070.pdf
ChatMed_Consult_DatasetZHMedicalMChttps://github.com/michael-wzhu/ChatMedhttps://huggingface.co/datasets/michaelwzhu/ChatMed_Consult_Dataset
CMtMedQAZHMedicalHGhttps://github.com/SupritYoung/Zhongjinghttps://arxiv.org/pdf/2308.03549.pdfhttps://huggingface.co/datasets/Suprit/CMtMedQA
DISC-Med-SFTZHMedicalHG & CIhttps://github.com/FudanDISC/DISC-MedLLMhttps://arxiv.org/pdf/2308.14346.pdfhttps://huggingface.co/datasets/Flmc/DISC-Med-SFT
HuatuoGPT-sft-data-v1ZHMedicalHG & MChttps://github.com/FreedomIntelligence/HuatuoGPThttps://arxiv.org/pdf/2305.15075.pdfhttps://huggingface.co/datasets/FreedomIntelligence/HuatuoGPT-sft-data-v1
Huatuo-26MZHMedicalCIhttps://github.com/FreedomIntelligence/Huatuo-26Mhttps://arxiv.org/pdf/2305.01526.pdf
MedDialogEN & ZHMedicalHGhttps://github.com/UCSD-AI4H/Medical-Dialogue-Systemhttps://aclanthology.org/2020.emnlp-main.743.pdf
Medical MeadowENMedicalHG & CIhttps://github.com/kbressem/medAlpacahttps://arxiv.org/pdf/2304.08247.pdfhttps://huggingface.co/medalpaca
Medical-sftEN & ZHMedicalCIhttps://github.com/shibing624/MedicalGPThttps://huggingface.co/datasets/shibing624/medical
QiZhenGPT-sft-20kZHMedicalCIhttps://github.com/CMKRG/QiZhenGPT
ShenNong_TCM_DatasetZHMedicalMChttps://github.com/michael-wzhu/ShenNong-TCM-LLMhttps://huggingface.co/datasets/michaelwzhu/ShenNong_TCM_Dataset
Code_Alpaca_20KEN & PLCodeMChttps://github.com/sahil280114/codealpaca
CodeContestEN & PLCodeCIhttps://github.com/google-deepmind/code_contestshttps://arxiv.org/pdf/2203.07814.pdf
CommitPackFTEN & PL (277)CodeHGhttps://github.com/bigcode-project/octopackhttps://arxiv.org/pdf/2308.07124.pdfhttps://huggingface.co/datasets/bigcode/commitpackft
ToolAlpacaEN & PLCodeHG & MChttps://github.com/tangqiaoyu/ToolAlpacahttps://arxiv.org/pdf/2306.05301.pdf
ToolBenchEN & PLCodeHG & MChttps://github.com/OpenBMB/ToolBenchhttps://arxiv.org/pdf/2307.16789v2.pdf
DISC-Law-SFTZHLawHG & CI & MChttps://github.com/FudanDISC/DISC-LawLLMhttps://arxiv.org/pdf/2309.11325.pdf
HanFei 1.0ZHLaw-https://github.com/siat-nlp/HanFei
LawGPT_zhZHLawCI & MChttps://github.com/LiuHC0428/LAW-GPT
Lawyer LLaMA_sftZHLawCI & MChttps://github.com/AndrewZhe/lawyer-llamahttps://arxiv.org/pdf/2305.15062.pdfhttps://github.com/AndrewZhe/lawyer-llama/tree/main/data
BELLE_School_MathZHMathMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/school_math_0.25M
GoatENMathHGhttps://github.com/liutiedong/goathttps://arxiv.org/pdf/2305.14201.pdfhttps://huggingface.co/datasets/tiedong/goat
MWPEN & ZHMathCIhttps://github.com/LYH-YF/MWPToolkithttps://browse.arxiv.org/pdf/2109.00799.pdfhttps://huggingface.co/datasets/Macropodus/MWP-Instruct
OpenMathInstruct-1ENMathCI & MChttps://github.com/Kipok/NeMo-Skillshttps://arxiv.org/abs/2402.10176https://huggingface.co/datasets/nvidia/OpenMathInstruct-1
Child_chat_dataZHEducationHG & MChttps://github.com/HIT-SCIR-SC/QiaoBan
Educhat-sft-002-data-osmEN & ZHEducationCIhttps://github.com/icalk-nlp/EduChathttps://arxiv.org/pdf/2308.02773.pdfhttps://huggingface.co/datasets/ecnu-icalk/educhat-sft-002-data-osm
TaoLi_dataZHEducationHG & CIhttps://github.com/blcuicall/taoli
DISC-Fin-SFTZHFinancialHG & CI & MChttps://github.com/FudanDISC/DISC-FinLLMhttp://arxiv.org/abs/2310.15205
AlphaFinEN & ZHFinancialHG & CI & MChttps://github.com/AlphaFin-proj/AlphaFinhttps://arxiv.org/abs/2403.12582https://huggingface.co/datasets/AlphaFin/AlphaFin-dataset-v1
GeoSignalENGeoscienceHG & CI & MChttps://github.com/davendw49/k2https://arxiv.org/pdf/2306.05064.pdfhttps://huggingface.co/datasets/daven3/geosignal
MeChatZHMental HealthCI & MChttps://github.com/qiuhuachuan/smilehttps://arxiv.org/pdf/2305.00450.pdfhttps://github.com/qiuhuachuan/smile/tree/main/data
Mol-InstructionsENBiologyHG & CI & MChttps://github.com/zjunlp/Mol-Instructionshttps://arxiv.org/pdf/2306.08018.pdfhttps://huggingface.co/datasets/zjunlp/Mol-Instructions
Owl-InstructionEN & ZHITHG & MChttps://github.com/HC-Guo/Owlhttps://arxiv.org/pdf/2309.09298.pdf
PROSOCIALDIALOGENSocial NormsHG & MChttps://arxiv.org/pdf/2205.12688.pdfhttps://huggingface.co/datasets/allenai/prosocial-dialog
TransGPT-sftZHTransportationHGhttps://github.com/DUOMO/TransGPThttps://huggingface.co/datasets/DUOMO-Lab/TransGPT-sft

Multimodal SFT Datasets:

Model NameModalityLink
LRV-InstructionImagehttps://huggingface.co/datasets/VictorSanh/LrvInstruction?row=0
Clotho-DetailAudiohttps://github.com/magic-research/bubogpt/blob/main/dataset/README.md#audio-dataset-instruction
CogVLM-SFT-311KImagehttps://huggingface.co/datasets/THUDM/CogVLM-SFT-311K
ComVintImagehttps://drive.google.com/file/d/1eH5t8YoI2CGR2dTqZO0ETWpBukjcZWsd/view
DataEngine-InstDataImagehttps://opendatalab.com/OpenDataLab/DataEngine-InstData
GranD_fImagehttps://huggingface.co/datasets/MBZUAI/GranD-f/tree/main
LLaVAImagehttps://huggingface.co/datasets/liuhaotian/LLaVA-Instruct-150K
LLaVA-1.5Imagehttps://huggingface.co/datasets/liuhaotian/LLaVA-Instruct-150K/blob/main/llava_v1_5_mix665k.json
LVLM_NLFImagehttps://huggingface.co/datasets/YangyiYY/LVLM_NLF/tree/main
M3ITImagehttps://huggingface.co/datasets/MMInstruction/M3IT
MMC-Instruction DatasetImagehttps://github.com/FuxiaoLiu/MMC/blob/main/README.md
MiniGPT-4Imagehttps://drive.google.com/file/d/1nJXhoEcy3KTExr17I7BXqY5Y9Lx_-n-9/view
MiniGPT-v2Imagehttps://github.com/Vision-CAIR/MiniGPT-4/blob/main/dataset/README_MINIGPTv2_FINETUNE.md
PVITImagehttps://huggingface.co/datasets/PVIT/pvit_data_stage2/tree/main
PointLLM Instruction data3Dhttps://huggingface.co/datasets/RunsenXu/PointLLM/tree/main
ShareGPT4VImagehttps://huggingface.co/datasets/Lin-Chen/ShareGPT4V/tree/main
Shikra-RDImagehttps://drive.google.com/file/d/1CNLu1zJKPtliQEYCZlZ8ykH00ppInnyN/view
SparklesDialogueImagehttps://github.com/HYPJUDY/Sparkles/tree/main/dataset
T2MImage,Video,Audiohttps://github.com/NExT-GPT/NExT-GPT/tree/main/data/IT_data/T-T+X_data
TextBindImagehttps://drive.google.com/drive/folders/1-SkzQRInSfrVyZeB0EZJzpCPXXwHb27W
TextMonkeyImagehttps://www.modelscope.cn/datasets/lvskiller/TextMonkey_data/files
VGGSS-InstructionImage,Audiohttps://bubo-gpt.github.io/
VIGC-InstDataImagehttps://opendatalab.com/OpenDataLab/VIGC-InstData
VILAImagehttps://github.com/Efficient-Large-Model/VILA/tree/main/data_prepare
VLSafeImagehttps://arxiv.org/abs/2312.07533
Video-ChatGPT-video-it-dataVideohttps://github.com/mbzuai-oryx/Video-ChatGPT
VideoChat-video-it-dataVideohttps://github.com/OpenGVLab/InternVideo/tree/main/Data/instruction_data
X-InstructBLIP-it-dataImage,Video,Audiohttps://github.com/salesforce/LAVIS/tree/main/projects/xinstructblip

Data-centric pretraining

Domain mixture

  1. Doremi: Optimizing data mixtures speeds up language model pretraining - paper
  2. Data selection for language models via importance resampling - paper
  3. Glam: Efficient scaling of language models with mixture-of-experts - paper
  4. Videollm: Modeling video sequence with large language models - paper
  5. Vast: A vision-audio-subtitle-text omni-modality foundation model and dataset - paper
  6. Moviechat: From dense token to sparse memory for long video understanding - paper
  7. Internvid: A large-scale video-text dataset for multimodal understanding and generation - paper
  8. Youku-mplug: A 10 million large-scale chinese video-language dataset for pre-training and benchmarks - paper

Modality Mixture

  1. MM1: Methods, Analysis & Insights from Multimodal LLM Pre-training - paper
  2. From scarcity to efficiency: Improving clip training via visual-enriched captions - paper
  3. Valor: Vision-audio-language omni-perception pretraining model and dataset - paper
  4. AutoAD:Moviedescription in context - paper
  5. Chat-UniVi: Unified Visual Representation Empowers Large Language Models with Image and Video Understanding - paper
  6. VideoChat: Chat-Centric Video Understanding - paper
  7. Mvbench: A comprehensive multi-modal video understanding benchmark - paper
  8. LLaMA-VID: An image is worth 2 tokens in large language models - paper
  9. Video-llava:Learningunitedvisualrepresentation by alignment before projection - paper
  10. Valley: Video assistant with large language model enhanced ability - paper
  11. Video-llama: An instruction-tuned audio-visual language model for video understanding - paper
  12. Macaw-LLM: Multi-Modal Language Modeling with Image, Audio, Video, and Text Integration - paper
  13. Audio-Visual LLM for Video Understanding - paper
  14. Fine-grained Audio-Visual Joint Representations for Multimodal Large Language Models - paper

Quality Selection

  1. DataComp: In search of the next generation of multimodal datasets - paper
  2. Finetuned Multimodal Language Models Are High-Quality Image-Text Data Filters - paper
  3. CiT: Curation in Training for Effective Vision-Language Data - paper
  4. Sieve: Multimodal Dataset Pruning Using Image Captioning Models - paper
  5. Variance Alignment Score: A Simple But Tough-to-Beat Data Selection Method for Multimodal Contrastive Learning - paper

Data-centric adaptation

Data-Centric Supervised Finetuning

  1. Unnatural instructions: Tuning language models with (almost) no human labor - paper
  2. Active Learning for Convolutional Neural Networks: A Core-Set Approach - paper
  3. Moderate Coreset: A Universal Method of Data Selection for Real-world Data-efficient Deep Learning - paper
  4. Similar: Submodular information measures based active learning in realistic scenarios - paper
  5. Practical coreset constructions for machine learning - paper
  6. Deep learning on a data diet: Finding important examples early in training - paper
  7. A new active labeling method for deep learning - paper
  8. Maybe only 0.5% data is needed: A preliminary exploration of low training data instruction tuning - paper
  9. DEFT: Data Efficient Fine-Tuning for Pre-Trained Language Models via Unsupervised Core-Set Selection - paper
  10. Beyond neural scaling laws: beating power law scaling via data pruning - paper
  11. Mods: Model-oriented data selection for instruction tuning. - paper
  12. DeBERTa: Decoding-enhanced BERT with Disentangled Attention - paper
  13. Alpagasus: Training a better alpaca with fewer data - paper
  14. Rethinking the Instruction Quality: LIFT is What You Need - paper
  15. What Makes Good Data for Alignment? A Comprehensive Study of Automatic Data Selection in Instruction Tuning - paper
  16. InsTag: Instruction Tagging for Analyzing Supervised Fine-tuning of Large Language Models - paper
  17. SelectLLM: Can LLMs Select Important Instructions to Annotate? - paper
  18. Improved Baselines with Visual Instruction Tuning - paper
  19. NLU on Data Diets: Dynamic Data Subset Selection for NLP Classification Tasks - paper
  20. LESS: Selecting Influential Data for Targeted Instruction Tuning - paper
  21. From quantity to quality: Boosting llm performance with self-guided data selection for instruction tuning - paper
  22. One shot learning as instruction data prospector for large language models - paper
  23. Active Instruction Tuning: Improving Cross-Task Generalization by Training on Prompt Sensitive Tasks - paper
  24. SelectIT: Selective Instruction Tuning for Large Language Models via Uncertainty-Aware Self-Reflection - paper

Data-Centric Human Preference Alignment

  1. Training language models to follow instructions with human feedback - paper
  2. LLaMA-VID: An image is worth 2 tokens in large language models - paper
  3. Aligning large multimodal models with factually augmented rlhf - paper
  4. Dress: Instructing large vision-language models to align and interact with humans via natural language feedback - paper

Evaluation

  1. Gans trained by a two time-scale update rule converge to a local nash equilibrium - paper
  2. Assessing generative models via precision and recall - paper
  3. Unsupervised Quality Estimation for Neural Machine Translation - paper
  4. Mixture models for diverse machine translation: Tricks of the trade - paper
  5. The vendi score: A diversity evaluation metric for machine learning - paper
  6. Cousins Of The Vendi Score: A Family Of Similarity-Based Diversity Metrics For Science And Machine Learning - paper
  7. Navigating text-to-image customization: From lycoris fine-tuning to model evaluation - paper
  8. TRUE: Re-evaluating factual consistency evaluation - paper
  9. Object hallucination in image captioning - paper
  10. Faithscore: Evaluating hallucinations in large vision-language models - paper
  11. Deep coral: Correlation alignment for deep domain adaptation - paper
  12. Transferability in deep learning: A survey - paper
  13. Mauve scores for generative models: Theory and practice - paper
  14. Translating Videos to Natural Language Using Deep Recurrent Neural Networks - paper

Evaluation Datasets:

DatasetModalityTypeLink
MMMUImageCaption and General VQAhttps://mmmu-benchmark.github.io
MMEImageCaption and General VQAhttps://arxiv.org/abs/2306.13394
NocapsImageCaption and General VQAhttps://github.com/nocaps-org
GQAImageCaption and General VQAhttps://cs.stanford.edu/people/dorarad/gqa/about.html
DVQAImageCaption and General VQAhttps://github.com/kushalkafle/DVQA_dataset
VSRImageCaption and General VQAhttps://github.com/cambridgeltl/visual-spatial-reasoning?tab=readme-ov-file
OKVQAImageCaption and General VQAhttps://okvqa.allenai.org/
VizwizImageCaption and General VQAhttps://vizwiz.org/
POPEImageCaption and General VQAhttps://github.com/RUCAIBox/POPE
TextVQAImageText-Oriented VQAhttps://textvqa.org/
DocVQAImageText-Oriented VQAhttps://www.docvqa.org/
ChartQAImageText-Oriented VQAhttps://github.com/vis-nlp/ChartQA
AI2DImageText-Oriented VQAhttps://allenai.org/data/diagrams
OCR-VQAImageText-Oriented VQAhttps://ocr-vqa.github.io/
ScienceQAImageText-Oriented VQAhttps://scienceqa.github.io/
MathVImageText-Oriented VQAhttps://mathvista.github.io/
MMVetImageText-Oriented VQAhttps://github.com/yuweihao/MM-Vet
RefCOCO, RefCOCO+, RefCOCOgImageReferring Expression Comprehensionhttps://github.com/lichengunc/refer
GRITImageReferring Expression Comprehensionhttps://allenai.org/project/grit/home
TouchStoneImageInstruction Followinghttps://allenai.org/project/grit/home
SEED-BenchImageInstruction Followinghttps://allenai.org/project/grit/home
MMEImageInstruction Followinghttps://allenai.org/project/grit/home
LLaVAWImageInstruction Followinghttps://github.com/haotian-liu/LLaVA
HMImageOtherhttps://ai.meta.com/blog/hateful-memes-challenge-and-data-set/
MMBImageOtherhttps://github.com/open-compass/MMBench
MSVDVideoVideo question answeringhttps://paperswithcode.com/dataset/msvd
MSRVTTVideoVideo question answeringhttps://paperswithcode.com/dataset/msr-vtt
TGIF-QAVideoVideo question answeringhttps://paperswithcode.com/dataset/tgif-qa
ActivityNet-QAVideoVideo question answeringhttps://paperswithcode.com/dataset/activitynet-qa
LSMDCVideoVideo question answeringhttps://paperswithcode.com/dataset/lsmdc
MoVQAVideoVideo question answeringhttps://arxiv.org/abs/2312.04817
DiDeMoVideoVideo captioning and Video retrievalhttps://paperswithcode.com/dataset/didemo
VATEXVideoVideo captioning and Video retrievalhttps://eric-xw.github.io/vatex-website/about.html
MVBenchVideoOtherhttps://github.com/OpenGVLab/Ask-Anything/tree/main/video_chat2
EgoSchemaVideoOtherhttps://egoschema.github.io/
VideoChatGPTVideoOtherhttps://github.com/mbzuai-oryx/Video-ChatGPT/tree/main
Charade-STAVideoOtherhttps://github.com/jiyanggao/TALL
QVHighlightVideoOtherhttps://github.com/jayleicn/moment_detr/tree/main/data
AudioCapsAudioAudio retrievalhttps://audiocaps.github.io/
ClothoAudioAudio retrievalhttps://zenodo.org/records/4743815
ClothoAQAAudioAudio question answeringhttps://zenodo.org/records/6473207
Audio-MusicAVQAAudioAudio question answeringhttps://gewu-lab.github.io/MUSIC-AVQA/

Contributors

beccabai

16 commits

beccabai/Data-centric_multimodal_LLM

Survey on Data-centric Large Language Models

94

25 commits

updated Jul 8, 2024

See the code

README

Data-centric Multimodal LLM

Survey on data-centric multimodal large language models

Paper

Sources

List of Sources

Source NameSource LinkType
CommonCrawlhttps://commoncrawl.org/Common Webpages
Flickrhttps://www.flickr.com/Common Webpages
Flickr Videohttps://www.flickr.com/photos/tags/vídeo/Common Webpages
FreeSoundhttps://freesound.orgCommon Webpages
BBC Sound Effects4https://sound-effects.bbcrewind.co.ukCommon Webpages
SoundBiblehttps://soundbible.com/Common Webpages
Wikipediahttps://www.wikipedia.org/Wikipedia
Wikimedia Commonshttps://commons.wikimedia.org/Wikipedia
Stack Exchangehttps://stackexchange.com/Social Media
Reddithttps://www.reddit.com/Social Media
Ubuntu IRChttps://ubuntu.com/Social Media
Youtubehttps://www.youtube.comSocial Media
Xhttps://x.comSocial Media
S2ORChttps://github.com/allenai/s2orcAcademic Papers
Arxivhttps://arxiv.org/Academic Papers
Project Gutenberghttps://www.gutenberg.orgBooks
Smashwordshttps://www.smashwords.com/Books
Bibliotikhttps://bibliotik.me/Books
National Diet Libraryhttps://dl.ndl.go.jp/ja/photoBooks
BigQuery public datasethttps://cloud.google.com/bigquery/public-dataCode
GitHubhttps://github.com/Code
FreeLawhttps://www.freelaw.in/Legal
Chinese legal documentshttps://www.spp.gov.cn/spp/fl/Legal
Khan Academy exerciseshttps://www.khanacademy.orgMaths
MEDLINEwww.medline.comMedical
Patienthttps://patient.infoMedical
WebMDhttps://www.webmd.comMedical
NIHhttps://www.nih.gov/Medical
39 Ask Doctorhttps://ask.39.net/Medical
Medical Examshttps://drive.google.com/file/d/1ImYUSLk9JbgHXOemfvyiDiirluZHPeQw/viewMedical
Baidu Doctorhttps://muzhi.baidu.com/Medical
120 Askshttps://www.120ask.com/Medical
BMJ Case Reportshttps://casereports.bmj.comMedical
XYWYhttp://www.xywy.comMedical
Qianwen Healthhttps://51zyzy.comMedical
PubMedhttps://pubmed.ncbi.nlm.nih.govMedical
EDGARhttps://www.sec.gov/edgarFinancial
SEC Financial Statement and Notes Data Setshttps://www.sec.gov/dera/data/financial-statement-and-notes-data-setFinancial
Sina Financehttps://finance.sina.com.cn/Financial
Tencent Financehttps://new.qq.com/ch/finance/Financial
Eastmoneyhttps://www.eastmoney.com/Financial
Gubahttps://guba.eastmoney.com/Financial
Xueqiuhttps://xueqiu.com/Financial
Phoenix Financehttps://finance.ifeng.com/Financial
36Krhttps://36kr.com/Financial
Huxiuhttps://www.huxiu.com/Financial

Commonly-used datasets

Textual-Pretraining Datasets:

DatasetsLink
RedPajama-Data-1Thttps://www.together.ai/blog/redpajama
RedPajama-Data-v2https://www.together.ai/blog/redpajama-data-v2
SlimPajamahttps://huggingface.co/datasets/cerebras/SlimPajama-627B
Falcon-RefinedWebhttps://huggingface.co/datasets/tiiuae/falcon-refinedweb
Pilehttps://github.com/EleutherAI/the-pile?tab=readme-ov-file
ROOTShttps://huggingface.co/bigscience-data
WuDaoCorporahttps://data.baai.ac.cn/details/WuDaoCorporaText
Common Crawlhttps://commoncrawl.org/
C4https://huggingface.co/datasets/c4
mC4https://arxiv.org/pdf/2010.11934.pdf
Dolma Datasethttps://github.com/allenai/dolma
OSCAR-22.01https://oscar-project.github.io/documentation/versions/oscar-2201/
OSCAR-23.01https://huggingface.co/datasets/oscar-corpus/OSCAR-2301
colossal-oscar-1.0https://huggingface.co/datasets/oscar-corpus/colossal-oscar-1.0
Wiki40bhttps://www.tensorflow.org/datasets/catalog/wiki40b
Pushshift Reddit Datasethttps://paperswithcode.com/dataset/pushshift-reddit
OpenWebTextCorpushttps://paperswithcode.com/dataset/openwebtext
OpenWebText2https://openwebtext2.readthedocs.io/en/latest/
BookCorpushttps://huggingface.co/datasets/bookcorpus
Gutenberghttps://shibamoulilahiri.github.io/gutenberg_dataset.html
CC-Stories-Rhttps://paperswithcode.com/dataset/cc-stories
CC-NEWEShttps://huggingface.co/datasets/cc_news
REALNEWShttps://paperswithcode.com/dataset/realnews
Reddit submission datasethttps://www.philippsinger.info/reddit/
General Reddit Datasethttps://www.tensorflow.org/datasets/catalog/reddit
AMPShttps://drive.google.com/file/d/1hQsua3TkpEmcJD_UWQx8dmNdEZPyxw23/view

MM-Pretraining Datasets:

Dataset NamePaper Title (with hyperlink)Modality
ALIGNScaling up visual and vision-language representation learning with noisy text supervisionImage
LTIPFlamingo: a visual language model for few-shot learningImage
MS-COCOMicrosoft coco: Common objects in contextImage
Visual GenomeVisual genome: Connecting language and vision using crowdsourced dense image annotationsImage
CC3MConceptual captions: A cleaned, hypernymed, image alt-text dataset for automatic image captioningImage
CC12MConceptual 12M: Pushing Web-Scale Image-Text Pre-Training To Recognize Long-Tail Visual ConceptsGraph
SBUIm2text: Describing images using 1 million captioned photographsImage
LAION-5BLaion-5b: An open large-scale dataset for training next generation image-text modelsImage
LAION-400MLaion-400m: Open dataset of clip-filtered 400 million image-text pairsImage
LAION-COCOLaion-coco: In the style of MS COCOImage
Flickr30kFrom image descriptions to visual denotations: New similarity metrics for semantic inference over event descriptionsImage
AI ChallengerAi challenger: A large-scale dataset for going deeper in image understandingImage
COYOCOYO-700M: Image-Text Pair DatasetImage
WukongWukong: A 100 million large-scale chinese cross-modal pre-training benchmarkImage
COCO CaptionMicrosoft coco captions: Data collection and evaluation serverImage
WebLIPali: A jointly-scaled multilingual language-image modelImage
Episodic WebLIPali-x: On scaling up a multilingual vision and language modelImage
CC595kVisual instruction tuningImage
ReferItGameReferitgame: Referring to objects in photographs of natural scenesImage
RefCOCO&RefCOCO+Modeling context in referring expressionsImage
Visual-7WVisual7w: Grounded question answering in imagesImage
OCR-VQAOcr-vqa: Visual question answering by reading text in imagesImage
ST-VQAScene text visual question answeringImage
DocVQADocvqa: A dataset for vqa on document imagesImage
TextVQATowards vqa models that can readImage
DataCompDatacomp: In search of the next generation of multimodal datasetsImage
GQAGqa: A new dataset for real-world visual reasoning and compositional question answeringImage
VQAVQA: Visual Question AnsweringImage
VQAv2Making the v in vqa matter: Elevating the role of image understanding in visual question answeringImage
DVQADvqa: Understanding data visualizations via question answeringImage
A-OK-VQAA-okvqa: A benchmark for visual question answering using world knowledgeImage
Text CaptionsTextcaps: a dataset for image captioning with reading comprehensionImage
M3WFlamingo: a visual language model for few-shot learningImage
MMC4Multimodal c4: An open, billion-scale corpus of images interleaved with textImage
MSRVTTMsr-vtt: A large video description dataset for bridging video and languageVideo
WebVid-2MFrozen in time: A joint video and image encoder for end-to-end retrievalVideo
VTPFlamingo: a visual language model for few-shot learningVideo
AISHELL-1Aishell-1: An open-source mandarin speech corpus and a speech recognition baselineAudio
AISHELL-2Aishell-2: Transforming mandarin asr research into industrial scaleAudio
WaveCapsWavcaps: A chatgpt-assisted weakly-labelled audio captioning dataset for audio-language multimodal researchAudio
VisDialVisual dialogImage
VSDial-CNX-llm: Bootstrapping advanced large language models by treating multi-modalities as foreign languagesImage, Audio
MELONAudio Retrieval for Multimodal Design Documents: A New Dataset and AlgorithmsImage, Text, Audio

Common Textual SFT Datasets:

Dataset NameLanguageConstruction MethodGithub LinkPaper LinkDataset Link
databricks-dolly-15KENHGhttps://huggingface.co/datasets/databricks/databricks-dolly-15k
InstructionWild_v2EN & ZHHGhttps://github.com/XueFuzhao/InstructionWild
LCCCZHHGhttps://github.com/thu-coai/CDial-GPThttps://arxiv.org/pdf/2008.03946.pdf
OASST1Multi (35)HGhttps://github.com/imoneoi/openchathttps://arxiv.org/pdf/2309.11235.pdfhttps://huggingface.co/openchat
OL-CCZHHGhttps://data.baai.ac.cn/details/OL-CC
Zhihu-KOLZHHGhttps://github.com/wangrui6/Zhihu-KOLhttps://huggingface.co/datasets/wangrui6/Zhihu-KOL
Aya DatasetMulti (65)HGhttps://arxiv.org/abs/2402.06619https://hf.co/datasets/CohereForAI/aya_dataset
InstructIEEN & ZHHGhttps://github.com/zjunlp/KnowLMhttps://arxiv.org/abs/2305.11527https://huggingface.co/datasets/zjunlp/InstructIE
Alpaca_dataENMChttps://github.com/tatsu-lab/stanford_alpaca#data-release
BELLE_Generated_ChatZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/generated_chat_0.4M
BELLE_Multiturn_ChatZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/multiturn_chat_0.8M
BELLE_train_0.5M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/1.5Mhttps://huggingface.co/datasets/BelleGroup/train_0.5M_CN
BELLE_train_1M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/1.5Mhttps://huggingface.co/datasets/BelleGroup/train_1M_CN
BELLE_train_2M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/train_2M_CN
BELLE_train_3.5M_CNZHMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/train_3.5M_CN
CAMELMulti & PLMChttps://github.com/camel-ai/camelhttps://arxiv.org/pdf/2303.17760.pdfhttps://huggingface.co/camel-ai
Chatgpt_corpusZHMChttps://github.com/PlexPt/chatgpt-corpus/releases/tag/3
InstructionWild_v1EN & ZHMChttps://github.com/XueFuzhao/InstructionWild
LMSYS-Chat-1MMultiMChttps://arxiv.org/pdf/2309.11998.pdfhttps://huggingface.co/datasets/lmsys/lmsys-chat-1m
MOSS_002_sft_dataEN & ZHMChttps://github.com/OpenLMLab/MOSShttps://huggingface.co/datasets/fnlp/moss-002-sft-data
MOSS_003_sft_dataEN & ZHMChttps://github.com/OpenLMLab/MOSS
MOSS_003_sft_plugin_dataEN & ZHMChttps://github.com/OpenLMLab/MOSS
OpenChatENMChttps://github.com/imoneoi/openchathttps://arxiv.org/pdf/2309.11235.pdfhttps://huggingface.co/openchat
RedGPT-Dataset-V1-CNZHMChttps://github.com/DA-southampton/RedGPT
Self-InstructENMChttps://github.com/yizhongw/self-instructhttps://aclanthology.org/2023.acl-long.754.pdf
ShareChatMultiMC
ShareGPT-Chinese-English-90kEN & ZHMChttps://github.com/CrazyBoyM/llama2-Chinese-chathttps://huggingface.co/datasets/shareAI/ShareGPT-Chinese-English-90k
ShareGPT90KENMChttps://huggingface.co/datasets/RyokoAI/ShareGPT52K
UltraChatENMChttps://github.com/thunlp/UltraChat#UltraLMhttps://arxiv.org/pdf/2305.14233.pdf
UnnaturalENMChttps://github.com/orhonovich/unnatural-instructionshttps://aclanthology.org/2023.acl-long.806.pdf
WebGLM-QAENMChttps://github.com/THUDM/WebGLMhttps://arxiv.org/pdf/2306.07906.pdfhttps://huggingface.co/datasets/THUDM/webglm-qa
Wizard_evol_instruct_196KENMChttps://github.com/nlpxucan/WizardLMhttps://arxiv.org/pdf/2304.12244.pdfhttps://huggingface.co/datasets/WizardLM/WizardLM_evol_instruct_V2_196k
Wizard_evol_instruct_70KENMChttps://github.com/nlpxucan/WizardLMhttps://arxiv.org/pdf/2304.12244.pdfhttps://huggingface.co/datasets/WizardLM/WizardLM_evol_instruct_70k
CrossFitENCIhttps://github.com/INK-USC/CrossFithttps://arxiv.org/pdf/2104.08835.pdf
DialogStudioENCIhttps://github.com/salesforce/DialogStudiohttps://arxiv.org/pdf/2307.10172.pdfhttps://huggingface.co/datasets/Salesforce/dialogstudio
DynosaurENCIhttps://github.com/WadeYin9712/Dynosaurhttps://arxiv.org/pdf/2305.14327.pdfhttps://huggingface.co/datasets?search=dynosaur
Flan-miniENCIhttps://github.com/declare-lab/flacunahttps://arxiv.org/pdf/2307.02053.pdfhttps://huggingface.co/datasets/declare-lab/flan-mini
FlanMultiCIhttps://github.com/google-research/flanhttps://arxiv.org/pdf/2109.01652.pdf
FlanMultiCIhttps://github.com/google-research/FLAN/tree/main/flan/v2https://arxiv.org/pdf/2301.13688.pdfhttps://huggingface.co/datasets/SirNeural/flan_v2
InstructDialENCIhttps://github.com/prakharguptaz/Instructdialhttps://arxiv.org/pdf/2205.12673.pdf
NATURAL INSTRUCTIONSENCIhttps://github.com/allenai/natural-instructionshttps://aclanthology.org/2022.acl-long.244.pdfhttps://instructions.apps.allenai.org/
OIGENCIhttps://huggingface.co/datasets/laion/OIG
Open-PlatypusENCIhttps://github.com/arielnlee/Platypushttps://arxiv.org/pdf/2308.07317.pdfhttps://huggingface.co/datasets/garage-bAInd/Open-Platypus
OPT-IMLMultiCIhttps://github.com/facebookresearch/metaseqhttps://arxiv.org/pdf/2212.12017.pdf
PromptSourceENCIhttps://github.com/bigscience-workshop/promptsourcehttps://aclanthology.org/2022.acl-demo.9.pdf
SUPER-NATURAL INSTRUCTIONSMultiCIhttps://github.com/allenai/natural-instructionshttps://arxiv.org/pdf/2204.07705.pdf
T0ENCIhttps://arxiv.org/pdf/2110.08207.pdf
UnifiedSKGENCIhttps://github.com/xlang-ai/UnifiedSKGhttps://arxiv.org/pdf/2201.05966.pdf
xP3Multi (46)CIhttps://github.com/bigscience-workshop/xmtfhttps://aclanthology.org/2023.acl-long.891.pdf
IEPileEN & ZHCIhttps://github.com/zjunlp/IEPilehttps://arxiv.org/abs/2402.14710https://huggingface.co/datasets/zjunlp/iepile
FireflyZHHG & CIhttps://github.com/yangjianxin1/Fireflyhttps://huggingface.co/datasets/YeungNLP/firefly-train-1.1M
LIMA-sftENHG & CIhttps://arxiv.org/pdf/2305.11206.pdfhttps://huggingface.co/datasets/GAIR/lima
COIG-CQIAZHHG & CIhttps://arxiv.org/abs/2403.18058https://huggingface.co/datasets/m-a-p/COIG-CQIA
InstructGPT-sftENHG & MChttps://arxiv.org/pdf/2203.02155.pdf
Alpaca_GPT4_dataENCI & MChttps://github.com/Instruction-Tuning-with-GPT-4/GPT-4-LLM#data-releasehttps://arxiv.org/pdf/2304.03277.pdf
Alpaca_GPT4_data_zhZHCI & MChttps://github.com/Instruction-Tuning-with-GPT-4/GPT-4-LLM#data-releasehttps://huggingface.co/datasets/shibing624/alpaca-zh
Bactrain-XMulti (52)CI & MChttps://github.com/mbzuai-nlp/bactrian-xhttps://arxiv.org/pdf/2305.15011.pdfhttps://huggingface.co/datasets/MBZUAI/Bactrian-X
BaizeENCI & MChttps://github.com/project-baize/baize-chatbothttps://arxiv.org/pdf/2304.01196.pdfhttps://github.com/project-baize/baize-chatbot/tree/main/data
GPT4AllENCI & MChttps://github.com/nomic-ai/gpt4allhttps://gpt4all.io/reports/GPT4All_Technical_Report_3.pdfhttps://huggingface.co/datasets/QingyiSi/Alpaca-CoT/tree/main/GPT4all
GuanacoDatasetMultiCI & MChttps://huggingface.co/datasets/JosephusCheung/GuanacoDataset
LaMini-LMENCI & MChttps://github.com/mbzuai-nlp/LaMini-LMhttps://arxiv.org/pdf/2304.14402.pdfhttps://huggingface.co/datasets/MBZUAI/LaMini-instruction
LogiCoTEN & ZHCI & MChttps://github.com/csitfun/logicothttps://arxiv.org/pdf/2305.12147.pdfhttps://huggingface.co/datasets/csitfun/LogiCoT
LongFormENCI & MChttps://github.com/akoksal/LongFormhttps://arxiv.org/pdf/2304.08460.pdfhttps://huggingface.co/datasets/akoksal/LongForm
Luotuo-QA-BEN & ZHCI & MChttps://github.com/LC1332/Luotuo-QAhttps://huggingface.co/datasets/Logic123456789/Luotuo-QA-B
OpenOrcaMultiCI & MChttps://arxiv.org/pdf/2306.02707.pdfhttps://huggingface.co/datasets/Open-Orca/OpenOrca
Wizard_evol_instruct_zhZHCI & MChttps://github.com/LC1332/Chinese-alpaca-lorahttps://huggingface.co/datasets/silk-road/Wizard-LM-Chinese-instruct-evol
COIGZHHG & CI & MChttps://github.com/FlagOpen/FlagInstructhttps://arxiv.org/pdf/2304.07987.pdfhttps://huggingface.co/datasets/BAAI/COIG
HC3EN & ZHHG & CI & MChttps://github.com/Hello-SimpleAI/chatgpt-comparison-detectionhttps://arxiv.org/pdf/2301.07597.pdf
Phoenix-sft-data-v1MultiHG & CI & MChttps://github.com/FreedomIntelligence/LLMZoohttps://arxiv.org/pdf/2304.10453.pdfhttps://huggingface.co/datasets/FreedomIntelligence/phoenix-sft-data-v1
TigerBot_sft_enENHG & CI & MChttps://github.com/TigerResearch/TigerBothttps://arxiv.org/abs/2312.08688https://huggingface.co/datasets/TigerResearch/sft_en
TigerBot_sft_zhZHHG & CI & MChttps://github.com/TigerResearch/TigerBothttps://arxiv.org/abs/2312.08688https://huggingface.co/datasets/TigerResearch/sft_zh
Aya CollectionMulti (114)HG & CI & MChttps://arxiv.org/abs/2402.06619https://hf.co/datasets/CohereForAI/aya_collection

Domain Specific Textual SFT Datasets:

Dataset NameLanguageDomainConstruction MethodGithub LinkPaper LinkDataset Link
ChatDoctorENMedicalHG & MChttps://github.com/Kent0n-Li/ChatDoctorhttps://arxiv.org/ftp/arxiv/papers/2303/2303.14070.pdf
ChatMed_Consult_DatasetZHMedicalMChttps://github.com/michael-wzhu/ChatMedhttps://huggingface.co/datasets/michaelwzhu/ChatMed_Consult_Dataset
CMtMedQAZHMedicalHGhttps://github.com/SupritYoung/Zhongjinghttps://arxiv.org/pdf/2308.03549.pdfhttps://huggingface.co/datasets/Suprit/CMtMedQA
DISC-Med-SFTZHMedicalHG & CIhttps://github.com/FudanDISC/DISC-MedLLMhttps://arxiv.org/pdf/2308.14346.pdfhttps://huggingface.co/datasets/Flmc/DISC-Med-SFT
HuatuoGPT-sft-data-v1ZHMedicalHG & MChttps://github.com/FreedomIntelligence/HuatuoGPThttps://arxiv.org/pdf/2305.15075.pdfhttps://huggingface.co/datasets/FreedomIntelligence/HuatuoGPT-sft-data-v1
Huatuo-26MZHMedicalCIhttps://github.com/FreedomIntelligence/Huatuo-26Mhttps://arxiv.org/pdf/2305.01526.pdf
MedDialogEN & ZHMedicalHGhttps://github.com/UCSD-AI4H/Medical-Dialogue-Systemhttps://aclanthology.org/2020.emnlp-main.743.pdf
Medical MeadowENMedicalHG & CIhttps://github.com/kbressem/medAlpacahttps://arxiv.org/pdf/2304.08247.pdfhttps://huggingface.co/medalpaca
Medical-sftEN & ZHMedicalCIhttps://github.com/shibing624/MedicalGPThttps://huggingface.co/datasets/shibing624/medical
QiZhenGPT-sft-20kZHMedicalCIhttps://github.com/CMKRG/QiZhenGPT
ShenNong_TCM_DatasetZHMedicalMChttps://github.com/michael-wzhu/ShenNong-TCM-LLMhttps://huggingface.co/datasets/michaelwzhu/ShenNong_TCM_Dataset
Code_Alpaca_20KEN & PLCodeMChttps://github.com/sahil280114/codealpaca
CodeContestEN & PLCodeCIhttps://github.com/google-deepmind/code_contestshttps://arxiv.org/pdf/2203.07814.pdf
CommitPackFTEN & PL (277)CodeHGhttps://github.com/bigcode-project/octopackhttps://arxiv.org/pdf/2308.07124.pdfhttps://huggingface.co/datasets/bigcode/commitpackft
ToolAlpacaEN & PLCodeHG & MChttps://github.com/tangqiaoyu/ToolAlpacahttps://arxiv.org/pdf/2306.05301.pdf
ToolBenchEN & PLCodeHG & MChttps://github.com/OpenBMB/ToolBenchhttps://arxiv.org/pdf/2307.16789v2.pdf
DISC-Law-SFTZHLawHG & CI & MChttps://github.com/FudanDISC/DISC-LawLLMhttps://arxiv.org/pdf/2309.11325.pdf
HanFei 1.0ZHLaw-https://github.com/siat-nlp/HanFei
LawGPT_zhZHLawCI & MChttps://github.com/LiuHC0428/LAW-GPT
Lawyer LLaMA_sftZHLawCI & MChttps://github.com/AndrewZhe/lawyer-llamahttps://arxiv.org/pdf/2305.15062.pdfhttps://github.com/AndrewZhe/lawyer-llama/tree/main/data
BELLE_School_MathZHMathMChttps://github.com/LianjiaTech/BELLE/tree/main/data/10Mhttps://huggingface.co/datasets/BelleGroup/school_math_0.25M
GoatENMathHGhttps://github.com/liutiedong/goathttps://arxiv.org/pdf/2305.14201.pdfhttps://huggingface.co/datasets/tiedong/goat
MWPEN & ZHMathCIhttps://github.com/LYH-YF/MWPToolkithttps://browse.arxiv.org/pdf/2109.00799.pdfhttps://huggingface.co/datasets/Macropodus/MWP-Instruct
OpenMathInstruct-1ENMathCI & MChttps://github.com/Kipok/NeMo-Skillshttps://arxiv.org/abs/2402.10176https://huggingface.co/datasets/nvidia/OpenMathInstruct-1
Child_chat_dataZHEducationHG & MChttps://github.com/HIT-SCIR-SC/QiaoBan
Educhat-sft-002-data-osmEN & ZHEducationCIhttps://github.com/icalk-nlp/EduChathttps://arxiv.org/pdf/2308.02773.pdfhttps://huggingface.co/datasets/ecnu-icalk/educhat-sft-002-data-osm
TaoLi_dataZHEducationHG & CIhttps://github.com/blcuicall/taoli
DISC-Fin-SFTZHFinancialHG & CI & MChttps://github.com/FudanDISC/DISC-FinLLMhttp://arxiv.org/abs/2310.15205
AlphaFinEN & ZHFinancialHG & CI & MChttps://github.com/AlphaFin-proj/AlphaFinhttps://arxiv.org/abs/2403.12582https://huggingface.co/datasets/AlphaFin/AlphaFin-dataset-v1
GeoSignalENGeoscienceHG & CI & MChttps://github.com/davendw49/k2https://arxiv.org/pdf/2306.05064.pdfhttps://huggingface.co/datasets/daven3/geosignal
MeChatZHMental HealthCI & MChttps://github.com/qiuhuachuan/smilehttps://arxiv.org/pdf/2305.00450.pdfhttps://github.com/qiuhuachuan/smile/tree/main/data
Mol-InstructionsENBiologyHG & CI & MChttps://github.com/zjunlp/Mol-Instructionshttps://arxiv.org/pdf/2306.08018.pdfhttps://huggingface.co/datasets/zjunlp/Mol-Instructions
Owl-InstructionEN & ZHITHG & MChttps://github.com/HC-Guo/Owlhttps://arxiv.org/pdf/2309.09298.pdf
PROSOCIALDIALOGENSocial NormsHG & MChttps://arxiv.org/pdf/2205.12688.pdfhttps://huggingface.co/datasets/allenai/prosocial-dialog
TransGPT-sftZHTransportationHGhttps://github.com/DUOMO/TransGPThttps://huggingface.co/datasets/DUOMO-Lab/TransGPT-sft

Multimodal SFT Datasets:

Model NameModalityLink
LRV-InstructionImagehttps://huggingface.co/datasets/VictorSanh/LrvInstruction?row=0
Clotho-DetailAudiohttps://github.com/magic-research/bubogpt/blob/main/dataset/README.md#audio-dataset-instruction
CogVLM-SFT-311KImagehttps://huggingface.co/datasets/THUDM/CogVLM-SFT-311K
ComVintImagehttps://drive.google.com/file/d/1eH5t8YoI2CGR2dTqZO0ETWpBukjcZWsd/view
DataEngine-InstDataImagehttps://opendatalab.com/OpenDataLab/DataEngine-InstData
GranD_fImagehttps://huggingface.co/datasets/MBZUAI/GranD-f/tree/main
LLaVAImagehttps://huggingface.co/datasets/liuhaotian/LLaVA-Instruct-150K
LLaVA-1.5Imagehttps://huggingface.co/datasets/liuhaotian/LLaVA-Instruct-150K/blob/main/llava_v1_5_mix665k.json
LVLM_NLFImagehttps://huggingface.co/datasets/YangyiYY/LVLM_NLF/tree/main
M3ITImagehttps://huggingface.co/datasets/MMInstruction/M3IT
MMC-Instruction DatasetImagehttps://github.com/FuxiaoLiu/MMC/blob/main/README.md
MiniGPT-4Imagehttps://drive.google.com/file/d/1nJXhoEcy3KTExr17I7BXqY5Y9Lx_-n-9/view
MiniGPT-v2Imagehttps://github.com/Vision-CAIR/MiniGPT-4/blob/main/dataset/README_MINIGPTv2_FINETUNE.md
PVITImagehttps://huggingface.co/datasets/PVIT/pvit_data_stage2/tree/main
PointLLM Instruction data3Dhttps://huggingface.co/datasets/RunsenXu/PointLLM/tree/main
ShareGPT4VImagehttps://huggingface.co/datasets/Lin-Chen/ShareGPT4V/tree/main
Shikra-RDImagehttps://drive.google.com/file/d/1CNLu1zJKPtliQEYCZlZ8ykH00ppInnyN/view
SparklesDialogueImagehttps://github.com/HYPJUDY/Sparkles/tree/main/dataset
T2MImage,Video,Audiohttps://github.com/NExT-GPT/NExT-GPT/tree/main/data/IT_data/T-T+X_data
TextBindImagehttps://drive.google.com/drive/folders/1-SkzQRInSfrVyZeB0EZJzpCPXXwHb27W
TextMonkeyImagehttps://www.modelscope.cn/datasets/lvskiller/TextMonkey_data/files
VGGSS-InstructionImage,Audiohttps://bubo-gpt.github.io/
VIGC-InstDataImagehttps://opendatalab.com/OpenDataLab/VIGC-InstData
VILAImagehttps://github.com/Efficient-Large-Model/VILA/tree/main/data_prepare
VLSafeImagehttps://arxiv.org/abs/2312.07533
Video-ChatGPT-video-it-dataVideohttps://github.com/mbzuai-oryx/Video-ChatGPT
VideoChat-video-it-dataVideohttps://github.com/OpenGVLab/InternVideo/tree/main/Data/instruction_data
X-InstructBLIP-it-dataImage,Video,Audiohttps://github.com/salesforce/LAVIS/tree/main/projects/xinstructblip

Data-centric pretraining

Domain mixture

  1. Doremi: Optimizing data mixtures speeds up language model pretraining - paper
  2. Data selection for language models via importance resampling - paper
  3. Glam: Efficient scaling of language models with mixture-of-experts - paper
  4. Videollm: Modeling video sequence with large language models - paper
  5. Vast: A vision-audio-subtitle-text omni-modality foundation model and dataset - paper
  6. Moviechat: From dense token to sparse memory for long video understanding - paper
  7. Internvid: A large-scale video-text dataset for multimodal understanding and generation - paper
  8. Youku-mplug: A 10 million large-scale chinese video-language dataset for pre-training and benchmarks - paper

Modality Mixture

  1. MM1: Methods, Analysis & Insights from Multimodal LLM Pre-training - paper
  2. From scarcity to efficiency: Improving clip training via visual-enriched captions - paper
  3. Valor: Vision-audio-language omni-perception pretraining model and dataset - paper
  4. AutoAD:Moviedescription in context - paper
  5. Chat-UniVi: Unified Visual Representation Empowers Large Language Models with Image and Video Understanding - paper
  6. VideoChat: Chat-Centric Video Understanding - paper
  7. Mvbench: A comprehensive multi-modal video understanding benchmark - paper
  8. LLaMA-VID: An image is worth 2 tokens in large language models - paper
  9. Video-llava:Learningunitedvisualrepresentation by alignment before projection - paper
  10. Valley: Video assistant with large language model enhanced ability - paper
  11. Video-llama: An instruction-tuned audio-visual language model for video understanding - paper
  12. Macaw-LLM: Multi-Modal Language Modeling with Image, Audio, Video, and Text Integration - paper
  13. Audio-Visual LLM for Video Understanding - paper
  14. Fine-grained Audio-Visual Joint Representations for Multimodal Large Language Models - paper

Quality Selection

  1. DataComp: In search of the next generation of multimodal datasets - paper
  2. Finetuned Multimodal Language Models Are High-Quality Image-Text Data Filters - paper
  3. CiT: Curation in Training for Effective Vision-Language Data - paper
  4. Sieve: Multimodal Dataset Pruning Using Image Captioning Models - paper
  5. Variance Alignment Score: A Simple But Tough-to-Beat Data Selection Method for Multimodal Contrastive Learning - paper

Data-centric adaptation

Data-Centric Supervised Finetuning

  1. Unnatural instructions: Tuning language models with (almost) no human labor - paper
  2. Active Learning for Convolutional Neural Networks: A Core-Set Approach - paper
  3. Moderate Coreset: A Universal Method of Data Selection for Real-world Data-efficient Deep Learning - paper
  4. Similar: Submodular information measures based active learning in realistic scenarios - paper
  5. Practical coreset constructions for machine learning - paper
  6. Deep learning on a data diet: Finding important examples early in training - paper
  7. A new active labeling method for deep learning - paper
  8. Maybe only 0.5% data is needed: A preliminary exploration of low training data instruction tuning - paper
  9. DEFT: Data Efficient Fine-Tuning for Pre-Trained Language Models via Unsupervised Core-Set Selection - paper
  10. Beyond neural scaling laws: beating power law scaling via data pruning - paper
  11. Mods: Model-oriented data selection for instruction tuning. - paper
  12. DeBERTa: Decoding-enhanced BERT with Disentangled Attention - paper
  13. Alpagasus: Training a better alpaca with fewer data - paper
  14. Rethinking the Instruction Quality: LIFT is What You Need - paper
  15. What Makes Good Data for Alignment? A Comprehensive Study of Automatic Data Selection in Instruction Tuning - paper
  16. InsTag: Instruction Tagging for Analyzing Supervised Fine-tuning of Large Language Models - paper
  17. SelectLLM: Can LLMs Select Important Instructions to Annotate? - paper
  18. Improved Baselines with Visual Instruction Tuning - paper
  19. NLU on Data Diets: Dynamic Data Subset Selection for NLP Classification Tasks - paper
  20. LESS: Selecting Influential Data for Targeted Instruction Tuning - paper
  21. From quantity to quality: Boosting llm performance with self-guided data selection for instruction tuning - paper
  22. One shot learning as instruction data prospector for large language models - paper
  23. Active Instruction Tuning: Improving Cross-Task Generalization by Training on Prompt Sensitive Tasks - paper
  24. SelectIT: Selective Instruction Tuning for Large Language Models via Uncertainty-Aware Self-Reflection - paper

Data-Centric Human Preference Alignment

  1. Training language models to follow instructions with human feedback - paper
  2. LLaMA-VID: An image is worth 2 tokens in large language models - paper
  3. Aligning large multimodal models with factually augmented rlhf - paper
  4. Dress: Instructing large vision-language models to align and interact with humans via natural language feedback - paper

Evaluation

  1. Gans trained by a two time-scale update rule converge to a local nash equilibrium - paper
  2. Assessing generative models via precision and recall - paper
  3. Unsupervised Quality Estimation for Neural Machine Translation - paper
  4. Mixture models for diverse machine translation: Tricks of the trade - paper
  5. The vendi score: A diversity evaluation metric for machine learning - paper
  6. Cousins Of The Vendi Score: A Family Of Similarity-Based Diversity Metrics For Science And Machine Learning - paper
  7. Navigating text-to-image customization: From lycoris fine-tuning to model evaluation - paper
  8. TRUE: Re-evaluating factual consistency evaluation - paper
  9. Object hallucination in image captioning - paper
  10. Faithscore: Evaluating hallucinations in large vision-language models - paper
  11. Deep coral: Correlation alignment for deep domain adaptation - paper
  12. Transferability in deep learning: A survey - paper
  13. Mauve scores for generative models: Theory and practice - paper
  14. Translating Videos to Natural Language Using Deep Recurrent Neural Networks - paper

Evaluation Datasets:

DatasetModalityTypeLink
MMMUImageCaption and General VQAhttps://mmmu-benchmark.github.io
MMEImageCaption and General VQAhttps://arxiv.org/abs/2306.13394
NocapsImageCaption and General VQAhttps://github.com/nocaps-org
GQAImageCaption and General VQAhttps://cs.stanford.edu/people/dorarad/gqa/about.html
DVQAImageCaption and General VQAhttps://github.com/kushalkafle/DVQA_dataset
VSRImageCaption and General VQAhttps://github.com/cambridgeltl/visual-spatial-reasoning?tab=readme-ov-file
OKVQAImageCaption and General VQAhttps://okvqa.allenai.org/
VizwizImageCaption and General VQAhttps://vizwiz.org/
POPEImageCaption and General VQAhttps://github.com/RUCAIBox/POPE
TextVQAImageText-Oriented VQAhttps://textvqa.org/
DocVQAImageText-Oriented VQAhttps://www.docvqa.org/
ChartQAImageText-Oriented VQAhttps://github.com/vis-nlp/ChartQA
AI2DImageText-Oriented VQAhttps://allenai.org/data/diagrams
OCR-VQAImageText-Oriented VQAhttps://ocr-vqa.github.io/
ScienceQAImageText-Oriented VQAhttps://scienceqa.github.io/
MathVImageText-Oriented VQAhttps://mathvista.github.io/
MMVetImageText-Oriented VQAhttps://github.com/yuweihao/MM-Vet
RefCOCO, RefCOCO+, RefCOCOgImageReferring Expression Comprehensionhttps://github.com/lichengunc/refer
GRITImageReferring Expression Comprehensionhttps://allenai.org/project/grit/home
TouchStoneImageInstruction Followinghttps://allenai.org/project/grit/home
SEED-BenchImageInstruction Followinghttps://allenai.org/project/grit/home
MMEImageInstruction Followinghttps://allenai.org/project/grit/home
LLaVAWImageInstruction Followinghttps://github.com/haotian-liu/LLaVA
HMImageOtherhttps://ai.meta.com/blog/hateful-memes-challenge-and-data-set/
MMBImageOtherhttps://github.com/open-compass/MMBench
MSVDVideoVideo question answeringhttps://paperswithcode.com/dataset/msvd
MSRVTTVideoVideo question answeringhttps://paperswithcode.com/dataset/msr-vtt
TGIF-QAVideoVideo question answeringhttps://paperswithcode.com/dataset/tgif-qa
ActivityNet-QAVideoVideo question answeringhttps://paperswithcode.com/dataset/activitynet-qa
LSMDCVideoVideo question answeringhttps://paperswithcode.com/dataset/lsmdc
MoVQAVideoVideo question answeringhttps://arxiv.org/abs/2312.04817
DiDeMoVideoVideo captioning and Video retrievalhttps://paperswithcode.com/dataset/didemo
VATEXVideoVideo captioning and Video retrievalhttps://eric-xw.github.io/vatex-website/about.html
MVBenchVideoOtherhttps://github.com/OpenGVLab/Ask-Anything/tree/main/video_chat2
EgoSchemaVideoOtherhttps://egoschema.github.io/
VideoChatGPTVideoOtherhttps://github.com/mbzuai-oryx/Video-ChatGPT/tree/main
Charade-STAVideoOtherhttps://github.com/jiyanggao/TALL
QVHighlightVideoOtherhttps://github.com/jayleicn/moment_detr/tree/main/data
AudioCapsAudioAudio retrievalhttps://audiocaps.github.io/
ClothoAudioAudio retrievalhttps://zenodo.org/records/4743815
ClothoAQAAudioAudio question answeringhttps://zenodo.org/records/6473207
Audio-MusicAVQAAudioAudio question answeringhttps://gewu-lab.github.io/MUSIC-AVQA/

Contributors

beccabai

16 commits
