Sushi engine runs very high quality quant model in Apple Silicon, using hybrid affine/exl3 with special expert tuning techniques.
Zig
281
1,459 commits
updated Oct 19, 2026
A local AI server for low-bit, very high quality Sushi quants, using custom EXL3-Affine hybrid converter. It is a detached fork of ddalcu's mlx-serve. Sushi runs stand-alone and also as a guest engine inside mlx-serve, Apple Silicon M1+ is required.
Usage see recommended launch commands and coding agent usage.
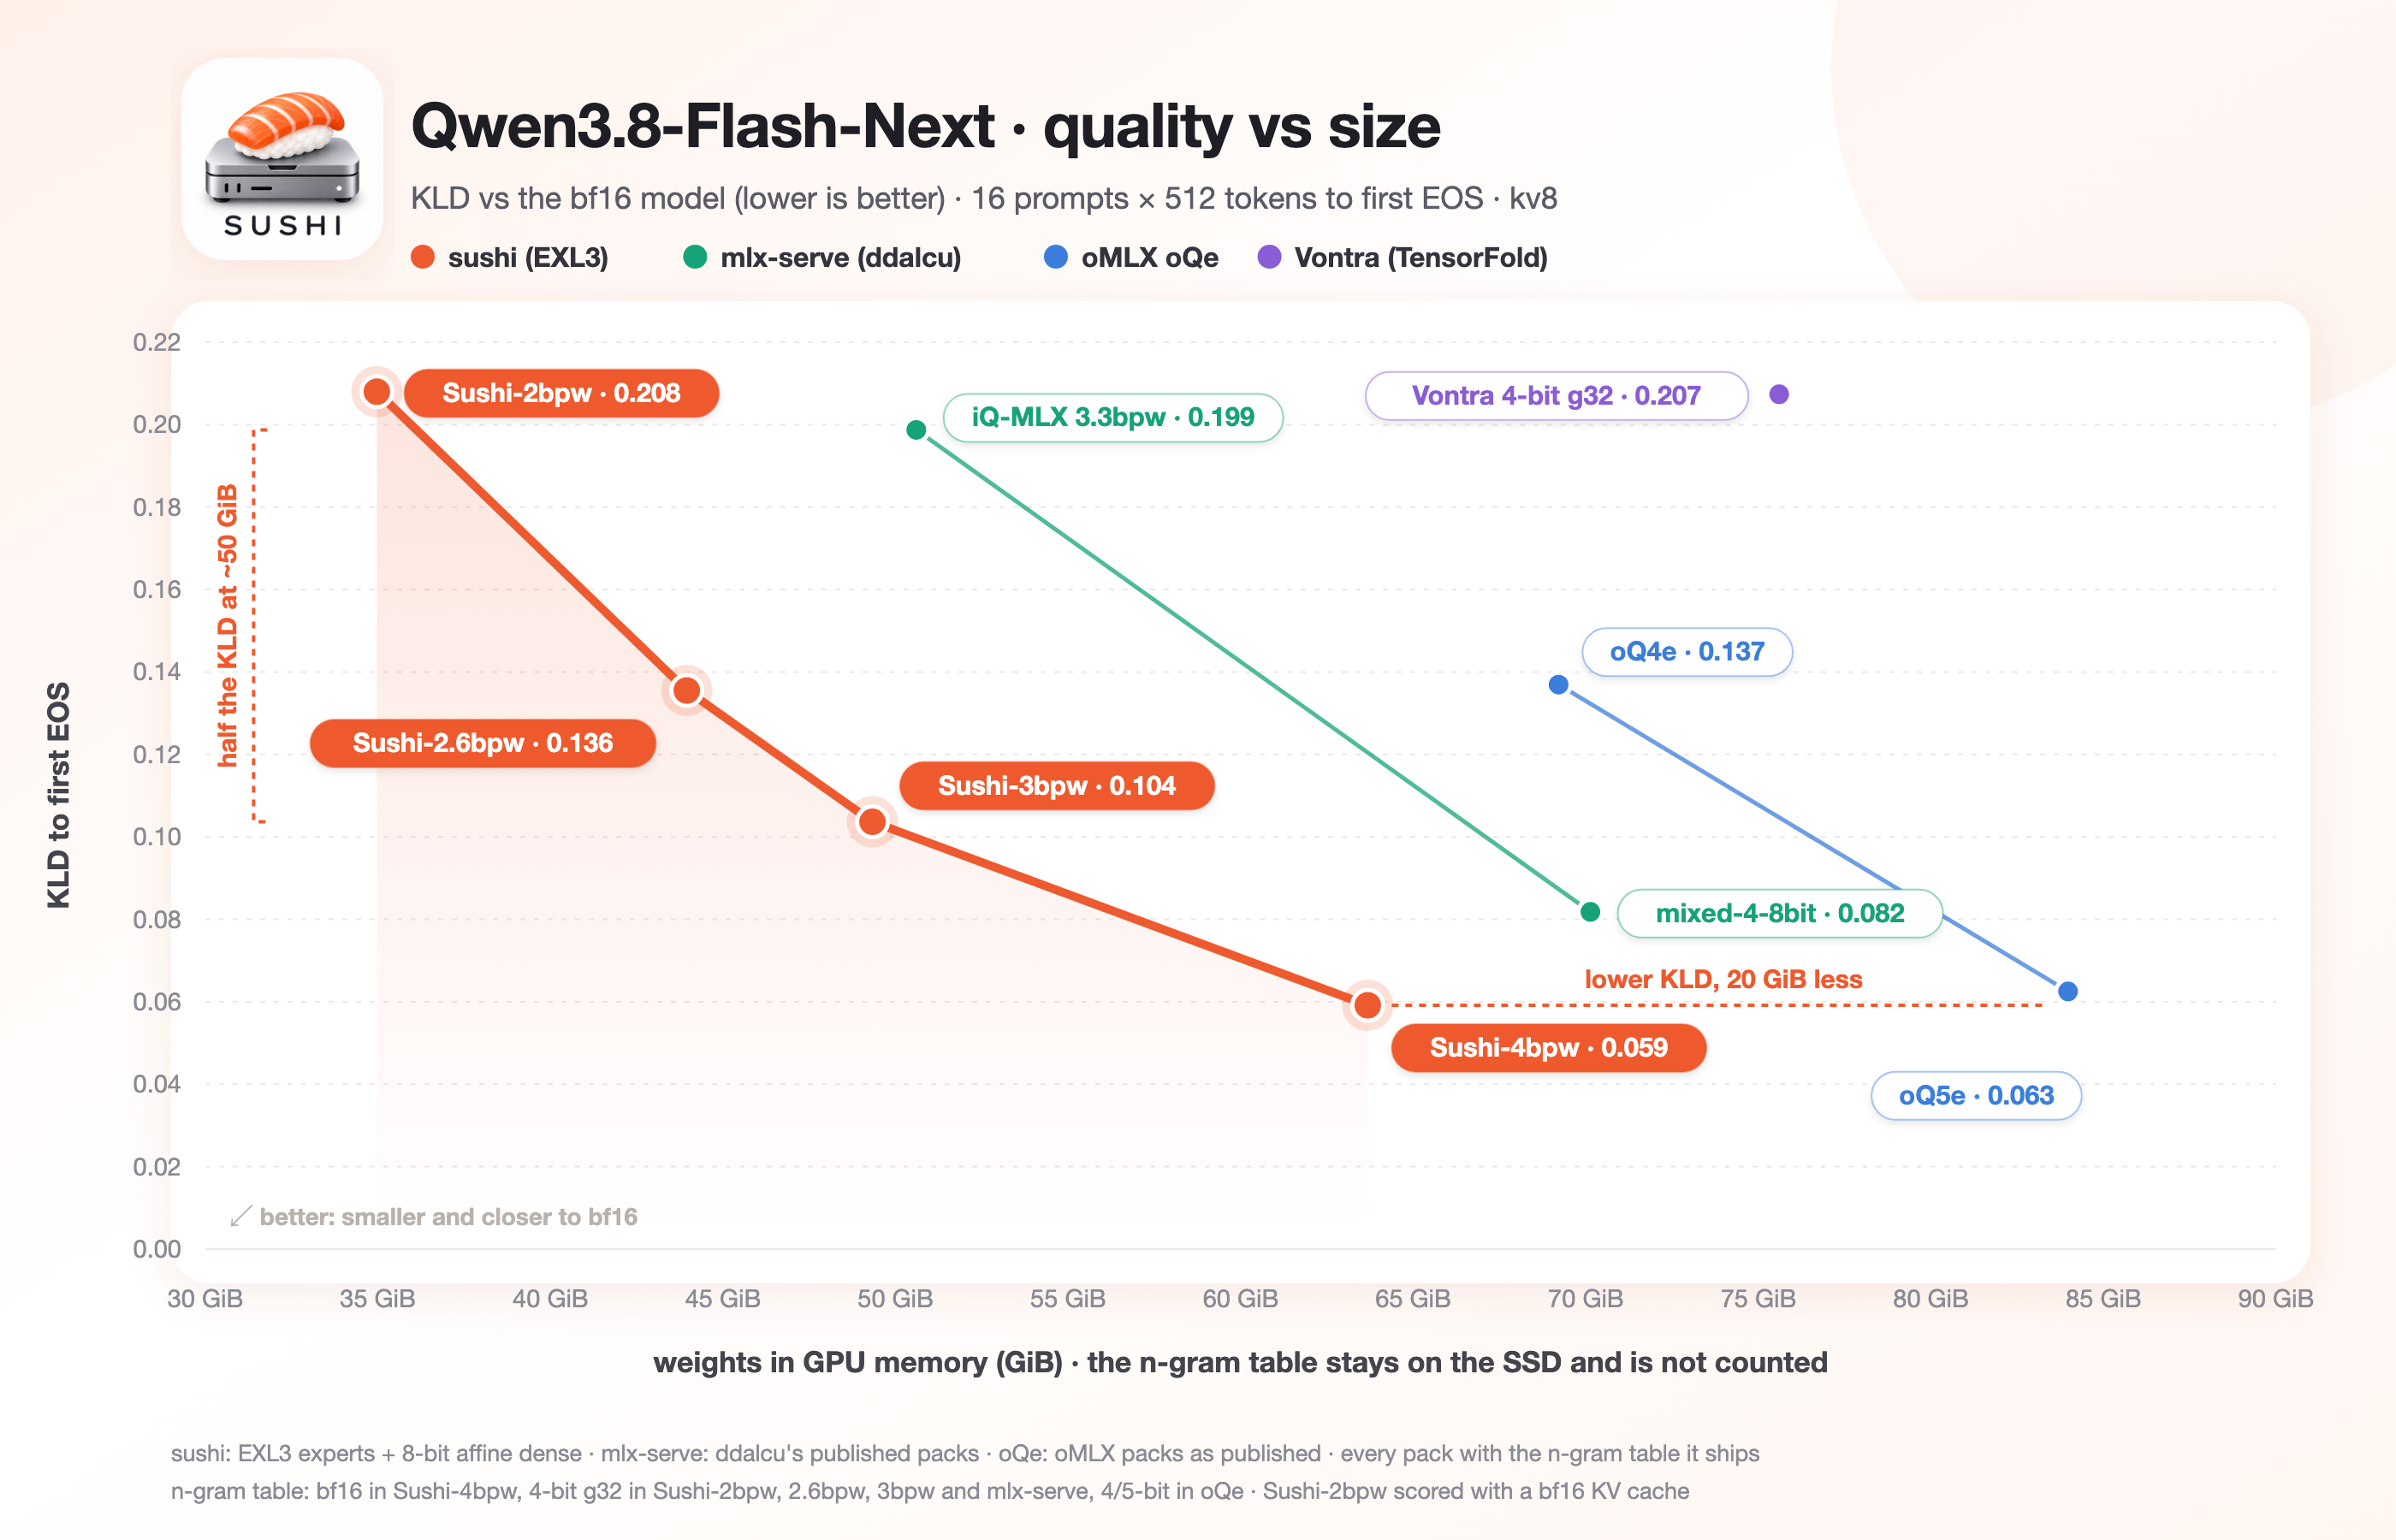
brew install beamivalice/tap/sushi
Update with brew upgrade sushi.
127.0.0.1:12345.GPU memory in GiB to serve one prompt that fills the whole context (8-bit KV, MTP on with --mtp-head-kv-quant; GLM
with its DFlash2 assistant and vision tower). The prompt cache and the n-gram table stay on the SSD and are not counted.
The Qwen columns are at the default f32 GatedDeltaNet state; --qwen-gdn 16 (bf16) takes about 0.2 GiB off each Qwen cell.
| context | Sushi-2bpw | Sushi-2.6bpw | Sushi-4bpw | MiMo-2.3bpw | GLM-2bpw | GLM-2.4bpw |
|---|---|---|---|---|---|---|
| weights only | 35.2 | 44.2 | 63.9 | 89.7 | 78.3 | 89.8 |
| 128k | 40.3 | 49.3 | 69.0 | 93.7 | 82.6 | 94.1 |
| 256k | 43.2 | 52.1 | 71.9 | 95.8 | 83.8 | 95.2 |
| 512k | 48.2 | 57.2 | 76.9 | 99.9 | 86.0 | 97.5 |
| 1M | 58.4 | 67.4 | 87.1 | 108.2 | 90.5 | 102.0 |
A context fits when its number is below the GPU limit you set with sudo sysctl iogpu.wired_limit_mb. Max context is
the largest multiple of 8192 tokens that fits, at 8-bit / 4-bit KV, with 256 MiB spare and capped at 1M (GLM has no
4-bit KV):
| Mac | GPU limit | Sushi-2bpw | Sushi-2.6bpw | Sushi-4bpw | MiMo-2.3bpw | GLM-2bpw | GLM-2.4bpw |
|---|---|---|---|---|---|---|---|
| 48 GB † | 43,000 MB (42.0 GiB) | 200k / 304k | — | — | — | — | — |
| 64 GB † | 59,000 MB (57.6 GiB) | 976k / 1M | 528k / 840k | — | — | — | — |
| 96 GB | 90,000 MB (87.9 GiB) | 1M / 1M | 1M / 1M | 1M / 1M | — | 696k / — | — |
| 128 GB | 120,000 MB (117.2 GiB) | 1M / 1M | 1M / 1M | 1M / 1M | 1M / 1M | 1M / — | 1M / — |
† At --qwen-gdn 16 (bf16 GatedDeltaNet state), which the 32, 48 and 64 GB launch lines use. The f32 default gives
less: 192k / 288k at 48 GB, and 968k / 1M and 520k / 824k at 64 GB.
A Mac with less memory than a Sushi pack can still serve it: --ssd-budget-gb N keeps N GiB resident and streams
the routed experts from the SSD, with the same replies as a resident load, at a speed set by the SSD. A streamed load
serves text unless --vision loads the vision tower, whose weights then come out of the N GiB.
Sushi-2bpw streams on a 32 GB Mac with MTP on, at about 20 tok/s decode:
sudo sysctl iogpu.wired_limit_mb=27000
sushi serve --model ~/.sushi/models/Qwen3.8-Flash-Next-Sushi-2bpw --ssd-budget-gb 18 --ctx-size 66000 \
  --qwen-gdn 16 --expert-pick-tolerance 0.3
--qwen-gdn 16 stores Qwen's recurrent state in bf16 instead of the f32 default, which halves the state in every cache
checkpoint (about 54 MB each) and is what the 32, 48 and 64 GB recipes run.
--ssd-budget-gb 18 keeps 18 GiB resident (trunk, KV cache and an expert cache) and reads the remaining experts from
the SSD. --expert-pick-tolerance 0.3 is lossy: when a routed expert is not cached, it uses the best cached expert
whose router probability is at least 0.7 of the missed one's, which saves an SSD read; leave it out for replies
identical to a resident load. The plan may come within 1 GiB of the GPU limit
(--wired-margin-gib N, 1 to 32). The GPU limit resets at reboot.
| Sushi 🍣 1.2.2 | M5 Max | 2k | 4k | 8k | 16k | 32k | 64k | 128k |
|---|---|---|---|---|---|---|---|---|
| GLM 5.3 Flash-2bpw | Prefill | 883 | 780 | 739 | 724 | 713 | 649 | 570 |
| Decode | 47.5 | 48.8 | 47.7 | 47.1 | 43.8 | 44.8 | 44.5 | |
| TTFT (s) | 2.35 | 5.24 | 11.2 | 22.5 | 46.0 | 101.1 | 229.9 | |
| GLM 5.3 Flash-2.4bpw | Prefill | 859 | 833 | 821 | 816 | 805 | 737 | 645 |
| Decode | 50.1 | 51.8 | 48.7 | 46.4 | 47.4 | 46.6 | 44.2 | |
| TTFT (s) | 2.42 | 4.91 | 10.1 | 20.0 | 40.7 | 89.1 | 203.3 | |
| MiMo V2.6 Flash-2.3bpw | Prefill | 1,308 | 1,227 | 1,225 | 1,144 | 994 | 891 | 679 |
| Decode | 56.7 | 55.4 | 56.2 | 65.5 | 54.9 | 57.2 | 50.2 | |
| TTFT (s) | 1.61 | 3.33 | 6.75 | 14.3 | 33.0 | 73.7 | 193.0 | |
| Qwen 3.8 Flash-Next-2.6bpw | Prefill | 2,144 | 2,355 | 2,413 | 2,414 | 2,399 | 2,348 | 2,255 |
| Decode | 92.3 | 86.1 | 88.8 | 89.2 | 90.9 | 83.1 | 79.6 | |
| TTFT (s) | 0.98 | 1.73 | 3.43 | 6.74 | 13.7 | 27.9 | 58.2 | |
| Qwen 3.8 Flash-Next-4bpw | Prefill | 1,871 | 2,113 | 2,192 | 2,187 | 2,262 | 2,225 | 2,178 |
| Decode | 77.9 | 72.8 | 85.2 | 90.3 | 82.6 | 78.3 | 71.3 | |
| TTFT (s) | 1.13 | 1.93 | 3.77 | 7.44 | 14.5 | 29.4 | 60.2 |
Community reports, using llmprobe --bench-only:
| Class | Typical RAM | Pack | Prefill tok/s | Gen tok/s |
|---|---|---|---|---|
| M1 Max | 64 GB | 3bpw | ~350 | ~32 |
| M2 Max | 64 GB | 3bpw | ~400 | ~38-40 |
| M3 Ultra 60c | 256 GB | 4bpw | ~420 | ~60 |
| M4 Max | 64 GB | 3bpw | ~690 | ~60-65 |
| M5 Pro | 64 GB | 2.6bpw | ~900 | ~50-55 |
| M5 Max | 128 GB | 3bpw | ~1,900 | ~95 |
| M5 Max | 128 GB | 4bpw | ~1,750 | ~90 |
| M5 Max | 128 GB | MiMo 2.3bpw | ~1,130 | ~70 |
| M5 Max | 128 GB | GLM 2.4bpw | ~860 | ~55 |
MIT, for sushi and the mlx-serve code it forks (LICENSE); ported kernels and vendored code are listed in NOTICE. The Qwen packs follow the Qwen Community License and the MiMo pack Xiaomi's MIT license, stated on each Hugging Face page.
4,397 followers · starred Sep 2026
587 followers · starred Sep 2026
424 followers · starred Sep 2026
292 followers · starred Sep 2026
Sushi engine runs very high quality quant model in Apple Silicon, using hybrid affine/exl3 with special expert tuning techniques.
Zig
281
1,459 commits
updated Oct 19, 2026
A local AI server for low-bit, very high quality Sushi quants, using custom EXL3-Affine hybrid converter. It is a detached fork of ddalcu's mlx-serve. Sushi runs stand-alone and also as a guest engine inside mlx-serve, Apple Silicon M1+ is required.
Usage see recommended launch commands and coding agent usage.
brew install beamivalice/tap/sushi
Update with brew upgrade sushi.
127.0.0.1:12345.GPU memory in GiB to serve one prompt that fills the whole context (8-bit KV, MTP on with --mtp-head-kv-quant; GLM
with its DFlash2 assistant and vision tower). The prompt cache and the n-gram table stay on the SSD and are not counted.
The Qwen columns are at the default f32 GatedDeltaNet state; --qwen-gdn 16 (bf16) takes about 0.2 GiB off each Qwen cell.
| context | Sushi-2bpw | Sushi-2.6bpw | Sushi-4bpw | MiMo-2.3bpw | GLM-2bpw | GLM-2.4bpw |
|---|---|---|---|---|---|---|
| weights only | 35.2 | 44.2 | 63.9 | 89.7 | 78.3 | 89.8 |
| 128k | 40.3 | 49.3 | 69.0 | 93.7 | 82.6 | 94.1 |
| 256k | 43.2 | 52.1 | 71.9 | 95.8 | 83.8 | 95.2 |
| 512k | 48.2 | 57.2 | 76.9 | 99.9 | 86.0 | 97.5 |
| 1M | 58.4 | 67.4 | 87.1 | 108.2 | 90.5 | 102.0 |
A context fits when its number is below the GPU limit you set with sudo sysctl iogpu.wired_limit_mb. Max context is
the largest multiple of 8192 tokens that fits, at 8-bit / 4-bit KV, with 256 MiB spare and capped at 1M (GLM has no
4-bit KV):
| Mac | GPU limit | Sushi-2bpw | Sushi-2.6bpw | Sushi-4bpw | MiMo-2.3bpw | GLM-2bpw | GLM-2.4bpw |
|---|---|---|---|---|---|---|---|
| 48 GB † | 43,000 MB (42.0 GiB) | 200k / 304k | — | — | — | — | — |
| 64 GB † | 59,000 MB (57.6 GiB) | 976k / 1M | 528k / 840k | — | — | — | — |
| 96 GB | 90,000 MB (87.9 GiB) | 1M / 1M | 1M / 1M | 1M / 1M | — | 696k / — | — |
| 128 GB | 120,000 MB (117.2 GiB) | 1M / 1M | 1M / 1M | 1M / 1M | 1M / 1M | 1M / — | 1M / — |
† At --qwen-gdn 16 (bf16 GatedDeltaNet state), which the 32, 48 and 64 GB launch lines use. The f32 default gives
less: 192k / 288k at 48 GB, and 968k / 1M and 520k / 824k at 64 GB.
A Mac with less memory than a Sushi pack can still serve it: --ssd-budget-gb N keeps N GiB resident and streams
the routed experts from the SSD, with the same replies as a resident load, at a speed set by the SSD. A streamed load
serves text unless --vision loads the vision tower, whose weights then come out of the N GiB.
Sushi-2bpw streams on a 32 GB Mac with MTP on, at about 20 tok/s decode:
sudo sysctl iogpu.wired_limit_mb=27000
sushi serve --model ~/.sushi/models/Qwen3.8-Flash-Next-Sushi-2bpw --ssd-budget-gb 18 --ctx-size 66000 \
  --qwen-gdn 16 --expert-pick-tolerance 0.3
--qwen-gdn 16 stores Qwen's recurrent state in bf16 instead of the f32 default, which halves the state in every cache
checkpoint (about 54 MB each) and is what the 32, 48 and 64 GB recipes run.
--ssd-budget-gb 18 keeps 18 GiB resident (trunk, KV cache and an expert cache) and reads the remaining experts from
the SSD. --expert-pick-tolerance 0.3 is lossy: when a routed expert is not cached, it uses the best cached expert
whose router probability is at least 0.7 of the missed one's, which saves an SSD read; leave it out for replies
identical to a resident load. The plan may come within 1 GiB of the GPU limit
(--wired-margin-gib N, 1 to 32). The GPU limit resets at reboot.
| Sushi 🍣 1.2.2 | M5 Max | 2k | 4k | 8k | 16k | 32k | 64k | 128k |
|---|---|---|---|---|---|---|---|---|
| GLM 5.3 Flash-2bpw | Prefill | 883 | 780 | 739 | 724 | 713 | 649 | 570 |
| Decode | 47.5 | 48.8 | 47.7 | 47.1 | 43.8 | 44.8 | 44.5 | |
| TTFT (s) | 2.35 | 5.24 | 11.2 | 22.5 | 46.0 | 101.1 | 229.9 | |
| GLM 5.3 Flash-2.4bpw | Prefill | 859 | 833 | 821 | 816 | 805 | 737 | 645 |
| Decode | 50.1 | 51.8 | 48.7 | 46.4 | 47.4 | 46.6 | 44.2 | |
| TTFT (s) | 2.42 | 4.91 | 10.1 | 20.0 | 40.7 | 89.1 | 203.3 | |
| MiMo V2.6 Flash-2.3bpw | Prefill | 1,308 | 1,227 | 1,225 | 1,144 | 994 | 891 | 679 |
| Decode | 56.7 | 55.4 | 56.2 | 65.5 | 54.9 | 57.2 | 50.2 | |
| TTFT (s) | 1.61 | 3.33 | 6.75 | 14.3 | 33.0 | 73.7 | 193.0 | |
| Qwen 3.8 Flash-Next-2.6bpw | Prefill | 2,144 | 2,355 | 2,413 | 2,414 | 2,399 | 2,348 | 2,255 |
| Decode | 92.3 | 86.1 | 88.8 | 89.2 | 90.9 | 83.1 | 79.6 | |
| TTFT (s) | 0.98 | 1.73 | 3.43 | 6.74 | 13.7 | 27.9 | 58.2 | |
| Qwen 3.8 Flash-Next-4bpw | Prefill | 1,871 | 2,113 | 2,192 | 2,187 | 2,262 | 2,225 | 2,178 |
| Decode | 77.9 | 72.8 | 85.2 | 90.3 | 82.6 | 78.3 | 71.3 | |
| TTFT (s) | 1.13 | 1.93 | 3.77 | 7.44 | 14.5 | 29.4 | 60.2 |
Community reports, using llmprobe --bench-only:
| Class | Typical RAM | Pack | Prefill tok/s | Gen tok/s |
|---|---|---|---|---|
| M1 Max | 64 GB | 3bpw | ~350 | ~32 |
| M2 Max | 64 GB | 3bpw | ~400 | ~38-40 |
| M3 Ultra 60c | 256 GB | 4bpw | ~420 | ~60 |
| M4 Max | 64 GB | 3bpw | ~690 | ~60-65 |
| M5 Pro | 64 GB | 2.6bpw | ~900 | ~50-55 |
| M5 Max | 128 GB | 3bpw | ~1,900 | ~95 |
| M5 Max | 128 GB | 4bpw | ~1,750 | ~90 |
| M5 Max | 128 GB | MiMo 2.3bpw | ~1,130 | ~70 |
| M5 Max | 128 GB | GLM 2.4bpw | ~860 | ~55 |
MIT, for sushi and the mlx-serve code it forks (LICENSE); ported kernels and vendored code are listed in NOTICE. The Qwen packs follow the Qwen Community License and the MiMo pack Xiaomi's MIT license, stated on each Hugging Face page.
4,397 followers · starred Sep 2026
587 followers · starred Sep 2026
424 followers · starred Sep 2026
292 followers · starred Sep 2026



