
[ICLR 2025] SONICS: Synthetic Or Not - Identifying Counterfeit Songs
See the codeREADME
SONICS: Synthetic Or Not - Identifying Counterfeit Songs
ICLR 2025 [Poster]



This repository contains the official source code for our paper SONICS: Synthetic Or Not - Identifying Counterfeit Songs.
📌 Abstract
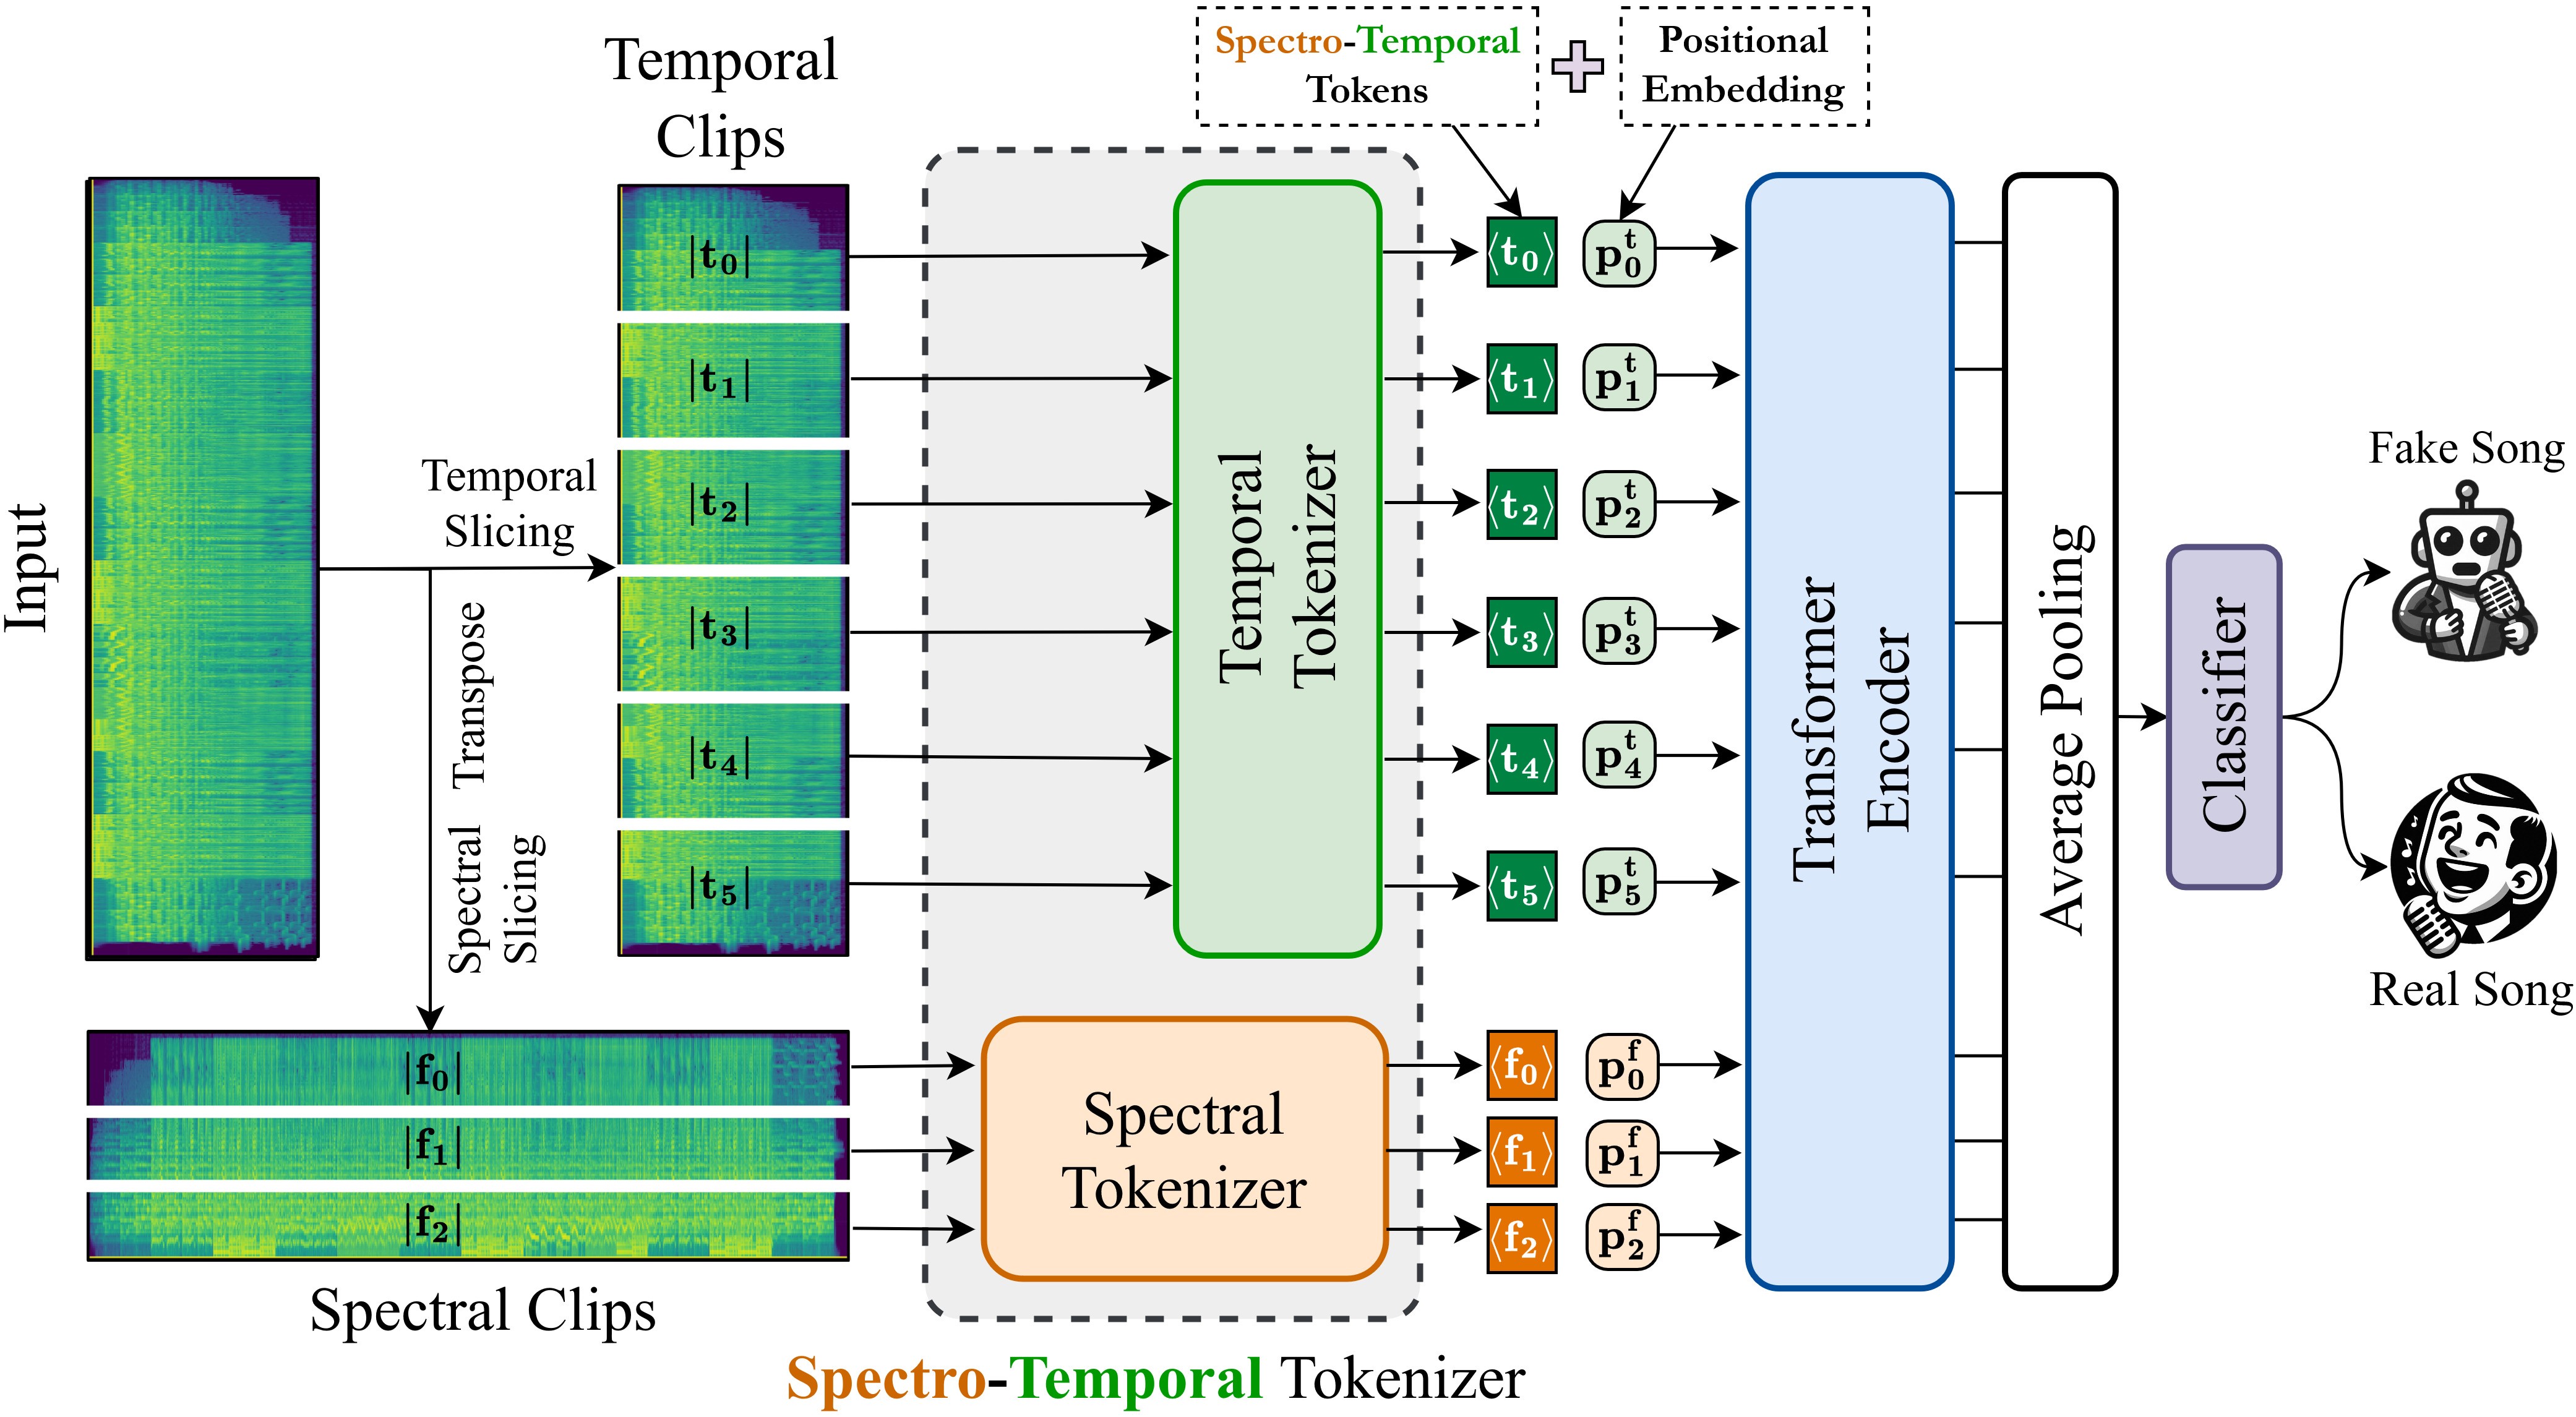
The recent surge in AI-generated songs presents exciting possibilities and challenges. These innovations necessitate the ability to distinguish between human-composed and synthetic songs to safeguard artistic integrity and protect human musical artistry. Existing research and datasets in fake song detection only focus on singing voice deepfake detection (SVDD), where the vocals are AI-generated but the instrumental music is sourced from real songs. However, these approaches are inadequate for detecting contemporary end-to-end artificial songs where all components (vocals, music, lyrics, and style) could be AI-generated. Additionally, existing datasets lack music-lyrics diversity, long-duration songs, and open-access fake songs. To address these gaps, we introduce SONICS, a novel dataset for end-to-end Synthetic Song Detection (SSD), comprising over 97k songs (4,751 hours) with over 49k synthetic songs from popular platforms like Suno and Udio. Furthermore, we highlight the importance of modeling long-range temporal dependencies in songs for effective authenticity detection, an aspect entirely overlooked in existing methods. To utilize long-range patterns, we introduce SpecTTTra, a novel architecture that significantly improves time and memory efficiency over conventional CNN and Transformer-based models. For long songs, our top-performing variant outperforms ViT by 8% in F1 score, is 38% faster, and uses 26% less memory, while also surpassing ConvNeXt with a 1% F1 score gain, 20% speed boost, and 67% memory reduction.
🎵 Spectro-Temporal Tokens Transformer (Spec🔱ra)
🖥️ System Configuration
- Disk Space: 150GB
- GPU Memory: 48GB
- RAM: 32GB
- Python Version: 3.10
- OS: Ubuntu 20.04
- CUDA Version: 12.4
This is if you want to reproduce the results.
🚀 Installation
For training:
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
For inference:
pip install git+https://github.com/awsaf49/sonics.git
📂 Dataset
You can download the dataset either from Hugging Face or Kaggle.
Download from Hugging Face:
from huggingface_hub import snapshot_download

snapshot_download(repo_id="awsaf49/sonics", repo_type="dataset", local_dir="your_local_folder")
Download from Kaggle:
First, set up the Kaggle API by following this documentation.
Then, run:
kaggle datasets download -d awsaf49/sonics-dataset --unzip
Folder Structure:
├── dataset
│   ├── fake_songs
│   │   └── yyy.mp3
│   ├── real_songs.csv
│   └── fake_songs.csv
Note: This dataset contains only fake songs. For real songs, use the
youtube_idfromreal_songs.csvto manually download them and place them inside/dataset/real_songs/folder.
Data Split
To split it into train, val, and test set, we will need to run the following command from the parent folder
python data_split.py
Note: The
real_songs.csvandfake_songs.csvcontain the metadata for the songs including duration, split, etc and config file contains path of the metadata.
Note: Output files including checkpoints, model predictions will be saved in
./output/<experiment_name>/folder.
📜 Metadata Properties
real_songs.csv
| Column Name | Description |
|---|---|
id | Unique file ID |
filename | Name of the file |
title | Title of the song |
artist | Artist's name |
year | Release year |
lyrics | Lyrics of the song |
lyrics_features | Text features of lyrics extracted by LLM |
duration | Total duration (seconds) |
youtube_id | YouTube ID of real song (not provided as mp3) |
label | "real" (all entries) |
artist_overlap | Whether train/test split contains the same artist |
target | 0 (real songs) |
skip_time | Instrumental-only duration before vocals (seconds) |
no_vocal | Whether the song has vocals (True/False) |
split | train/test/valid split |
fake_songs.csv
| Column Name | Description |
|---|---|
id | Unique file ID |
filename | Name of the file |
title | Title of the song |
duration | Total duration (seconds) |
algorithm | Algorithm used for generation |
style | Characteristics of the song style |
source | Generated from Suno or Udio |
lyrics_features | Text features of lyrics extracted by LLM |
topic | Song theme (e.g., Star Trek, Pokémon) |
genre | Song genre (e.g., salsa, grunge) |
mood | Mood of the song (e.g., mournful, tense) |
label | "full fake", "half fake", "mostly fake" |
target | 1 (fake songs) |
split | train/test/valid split |
🏋️ Training
python train.py --config <path_to_config_file>
Config files are available inside /configs folder.
🔍 Testing
python test.py --config <path_to_config_file> --ckpt_path <path_to_checkpoint_file>
📊 Model Profiling
python model_profile.py --config <path_to_config_file> --batch_size 12
🏆 Model Performance
| Model Name | HF Link | Variant | Duration | f_clip | t_clip | F1 | Sensitivity | Specificity | Speed (A/S) | FLOPs (G) | Mem. (GB) | # Act. (M) | # Param. (M) |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
sonics-spectttra-alpha-5s |  HF | SpecTTTra-α | 5s | 1 | 3 | 0.78 | 0.69 | 0.94 | 148 | 2.9 | 0.5 | 6 | 17 |
sonics-spectttra-beta-5s | HF | SpecTTTra-β | 5s | 3 | 5 | 0.78 | 0.69 | 0.94 | 152 | 1.1 | 0.2 | 5 | 17 |
sonics-spectttra-gamma-5s | HF | SpecTTTra-γ | 5s | 5 | 7 | 0.76 | 0.66 | 0.92 | 154 | 0.7 | 0.1 | 2 | 17 |
sonics-spectttra-alpha-120s | HF | SpecTTTra-α | 120s | 1 | 3 | 0.97 | 0.96 | 0.99 | 47 | 23.7 | 3.9 | 50 | 19 |
sonics-spectttra-beta-120s | HF | SpecTTTra-β | 120s | 3 | 5 | 0.92 | 0.86 | 0.99 | 80 | 14.0 | 2.3 | 29 | 21 |
sonics-spectttra-gamma-120s | HF | SpecTTTra-γ | 120s | 5 | 7 | 0.88 | 0.79 | 0.99 | 97 | 10.1 | 1.6 | 20 | 24 |
🎶 Model Usage
# Install from GitHub
pip install git+https://github.com/awsaf49/sonics.git

# Load model
from sonics import HFAudioClassifier
model = HFAudioClassifier.from_pretrained("awsaf49/sonics-spectttra-gamma-5s")
🎵 Song Arena
Can you detect if a song is AI-generated or real? Find out at our 🤗 Song Arena!
📝 Citation
@inproceedings{rahman2024sonics,
        title={SONICS: Synthetic Or Not - Identifying Counterfeit Songs},
        author={Rahman, Md Awsafur and Hakim, Zaber Ibn Abdul and Sarker, Najibul Haque and Paul, Bishmoy and Fattah, Shaikh Anowarul},
        booktitle={International Conference on Learning Representations (ICLR)},
        year={2025},
      }
📜 License
This project is licensed under:
- MIT License for code and models
- CC BY-NC 4.0 License for the dataset
See LICENSE for details.
Similar repos


Languages
Python
100.0%
[ICLR 2025] SONICS: Synthetic Or Not - Identifying Counterfeit Songs
See the codeREADME
SONICS: Synthetic Or Not - Identifying Counterfeit Songs
ICLR 2025 [Poster]
This repository contains the official source code for our paper SONICS: Synthetic Or Not - Identifying Counterfeit Songs.
📌 Abstract
The recent surge in AI-generated songs presents exciting possibilities and challenges. These innovations necessitate the ability to distinguish between human-composed and synthetic songs to safeguard artistic integrity and protect human musical artistry. Existing research and datasets in fake song detection only focus on singing voice deepfake detection (SVDD), where the vocals are AI-generated but the instrumental music is sourced from real songs. However, these approaches are inadequate for detecting contemporary end-to-end artificial songs where all components (vocals, music, lyrics, and style) could be AI-generated. Additionally, existing datasets lack music-lyrics diversity, long-duration songs, and open-access fake songs. To address these gaps, we introduce SONICS, a novel dataset for end-to-end Synthetic Song Detection (SSD), comprising over 97k songs (4,751 hours) with over 49k synthetic songs from popular platforms like Suno and Udio. Furthermore, we highlight the importance of modeling long-range temporal dependencies in songs for effective authenticity detection, an aspect entirely overlooked in existing methods. To utilize long-range patterns, we introduce SpecTTTra, a novel architecture that significantly improves time and memory efficiency over conventional CNN and Transformer-based models. For long songs, our top-performing variant outperforms ViT by 8% in F1 score, is 38% faster, and uses 26% less memory, while also surpassing ConvNeXt with a 1% F1 score gain, 20% speed boost, and 67% memory reduction.
🎵 Spectro-Temporal Tokens Transformer (Spec🔱ra)
🖥️ System Configuration
- Disk Space: 150GB
- GPU Memory: 48GB
- RAM: 32GB
- Python Version: 3.10
- OS: Ubuntu 20.04
- CUDA Version: 12.4
This is if you want to reproduce the results.
🚀 Installation
For training:
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
For inference:
pip install git+https://github.com/awsaf49/sonics.git
📂 Dataset
You can download the dataset either from Hugging Face or Kaggle.
Download from Hugging Face:
from huggingface_hub import snapshot_download

snapshot_download(repo_id="awsaf49/sonics", repo_type="dataset", local_dir="your_local_folder")
Download from Kaggle:
First, set up the Kaggle API by following this documentation.
Then, run:
kaggle datasets download -d awsaf49/sonics-dataset --unzip
Folder Structure:
├── dataset
│   ├── fake_songs
│   │   └── yyy.mp3
│   ├── real_songs.csv
│   └── fake_songs.csv
Note: This dataset contains only fake songs. For real songs, use the
youtube_idfromreal_songs.csvto manually download them and place them inside/dataset/real_songs/folder.
Data Split
To split it into train, val, and test set, we will need to run the following command from the parent folder
python data_split.py
Note: The
real_songs.csvandfake_songs.csvcontain the metadata for the songs including duration, split, etc and config file contains path of the metadata.
Note: Output files including checkpoints, model predictions will be saved in
./output/<experiment_name>/folder.
📜 Metadata Properties
real_songs.csv
| Column Name | Description |
|---|---|
id | Unique file ID |
filename | Name of the file |
title | Title of the song |
artist | Artist's name |
year | Release year |
lyrics | Lyrics of the song |
lyrics_features | Text features of lyrics extracted by LLM |
duration | Total duration (seconds) |
youtube_id | YouTube ID of real song (not provided as mp3) |
label | "real" (all entries) |
artist_overlap | Whether train/test split contains the same artist |
target | 0 (real songs) |
skip_time | Instrumental-only duration before vocals (seconds) |
no_vocal | Whether the song has vocals (True/False) |
split | train/test/valid split |
fake_songs.csv
| Column Name | Description |
|---|---|
id | Unique file ID |
filename | Name of the file |
title | Title of the song |
duration | Total duration (seconds) |
algorithm | Algorithm used for generation |
style | Characteristics of the song style |
source | Generated from Suno or Udio |
lyrics_features | Text features of lyrics extracted by LLM |
topic | Song theme (e.g., Star Trek, Pokémon) |
genre | Song genre (e.g., salsa, grunge) |
mood | Mood of the song (e.g., mournful, tense) |
label | "full fake", "half fake", "mostly fake" |
target | 1 (fake songs) |
split | train/test/valid split |
🏋️ Training
python train.py --config <path_to_config_file>
Config files are available inside /configs folder.
🔍 Testing
python test.py --config <path_to_config_file> --ckpt_path <path_to_checkpoint_file>
📊 Model Profiling
python model_profile.py --config <path_to_config_file> --batch_size 12
🏆 Model Performance
| Model Name | HF Link | Variant | Duration | f_clip | t_clip | F1 | Sensitivity | Specificity | Speed (A/S) | FLOPs (G) | Mem. (GB) | # Act. (M) | # Param. (M) |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
sonics-spectttra-alpha-5s | HF | SpecTTTra-α | 5s | 1 | 3 | 0.78 | 0.69 | 0.94 | 148 | 2.9 | 0.5 | 6 | 17 |
sonics-spectttra-beta-5s | HF | SpecTTTra-β | 5s | 3 | 5 | 0.78 | 0.69 | 0.94 | 152 | 1.1 | 0.2 | 5 | 17 |
sonics-spectttra-gamma-5s | HF | SpecTTTra-γ | 5s | 5 | 7 | 0.76 | 0.66 | 0.92 | 154 | 0.7 | 0.1 | 2 | 17 |
sonics-spectttra-alpha-120s | HF | SpecTTTra-α | 120s | 1 | 3 | 0.97 | 0.96 | 0.99 | 47 | 23.7 | 3.9 | 50 | 19 |
sonics-spectttra-beta-120s | HF | SpecTTTra-β | 120s | 3 | 5 | 0.92 | 0.86 | 0.99 | 80 | 14.0 | 2.3 | 29 | 21 |
sonics-spectttra-gamma-120s | HF | SpecTTTra-γ | 120s | 5 | 7 | 0.88 | 0.79 | 0.99 | 97 | 10.1 | 1.6 | 20 | 24 |
🎶 Model Usage
# Install from GitHub
pip install git+https://github.com/awsaf49/sonics.git

# Load model
from sonics import HFAudioClassifier
model = HFAudioClassifier.from_pretrained("awsaf49/sonics-spectttra-gamma-5s")
🎵 Song Arena
Can you detect if a song is AI-generated or real? Find out at our 🤗 Song Arena!
📝 Citation
@inproceedings{rahman2024sonics,
        title={SONICS: Synthetic Or Not - Identifying Counterfeit Songs},
        author={Rahman, Md Awsafur and Hakim, Zaber Ibn Abdul and Sarker, Najibul Haque and Paul, Bishmoy and Fattah, Shaikh Anowarul},
        booktitle={International Conference on Learning Representations (ICLR)},
        year={2025},
      }
📜 License
This project is licensed under:
- MIT License for code and models
- CC BY-NC 4.0 License for the dataset
See LICENSE for details.
Similar repos
Languages
Python
100.0%