
You already have the agent. This is everything around it. great_cto runs Claude Code as a pipeline of 70 specialist agents — an independent model checks each stage before the next builds on it, spending caps refuse rather than warn, and three decisions stay yours: what gets built, how, and whether it ships.
93
stars
1,490
commits
JavaScript
primary language
Sep 15, 2026
updated
README
Ship products with the coding agent you already have.



npx great-cto init
Website · One real run → · Live demo · Blog · Changelog
Русский · 简体中文 · 繁體中文 · 日本語 · 한국어 · Español · Português · Deutsch · Français
Your coding agent ships code. This is what checks it.
You write a spec. Your Claude Code builds against it, a second model from another family reads the same diff, and where they disagree you see the disagreement and decide. Three decisions stay yours — what gets built, how, and whether it ships. What lands is a repository you own and a URL that works.
Seven products built this way in the open benchmark: median $171 in tokens, measured 2026-07-10. You pay your own LLM provider; great_cto is MIT and bills nothing.
   describe a product
        │
   🤖  problem framed · options weighed · brief written
        ▼
   👤  checkpoint 1 — approve WHAT gets built
        │
   🤖  architecture · data model · screens · plan
        ▼
   👤  checkpoint 2 — approve HOW it gets built
        │
   🤖  scaffold → backend → frontend → tests → review → security
        ▼
   👤  checkpoint 3 — approve the deploy
        │
   🤖  deployed · repo · live URL
Three stops is the default, not the floor. One line takes it to one:
approval-level: ship-only
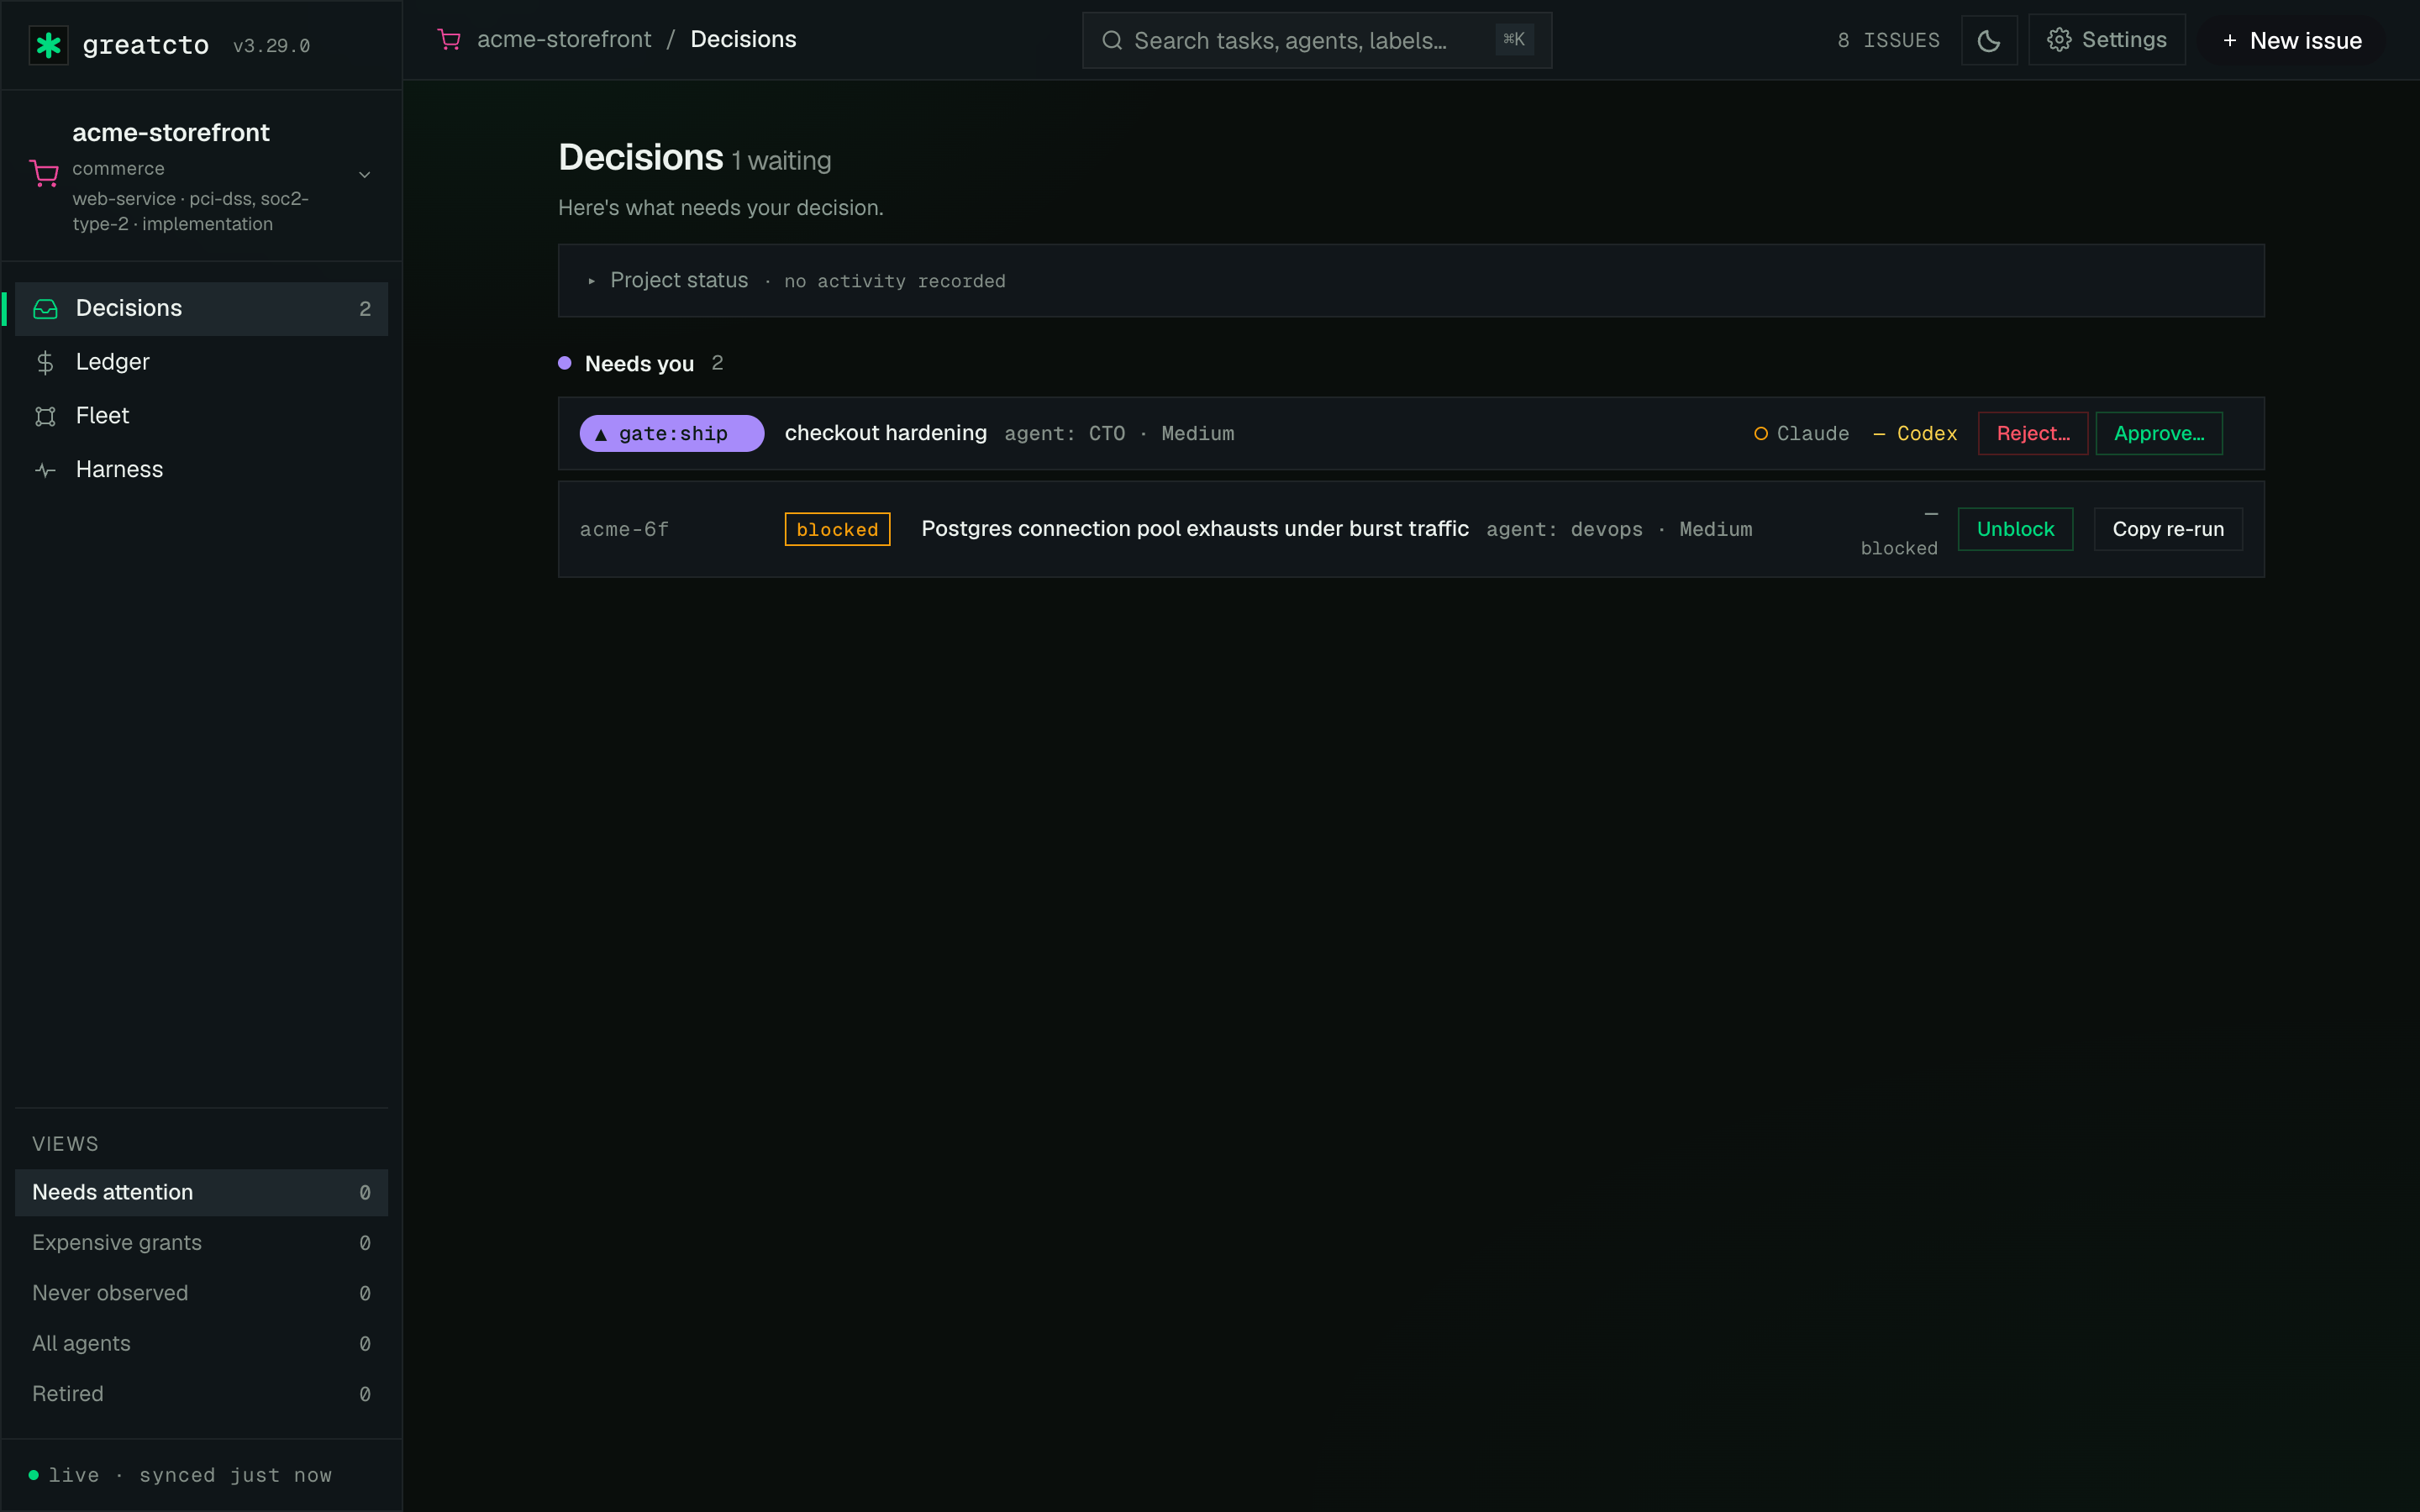
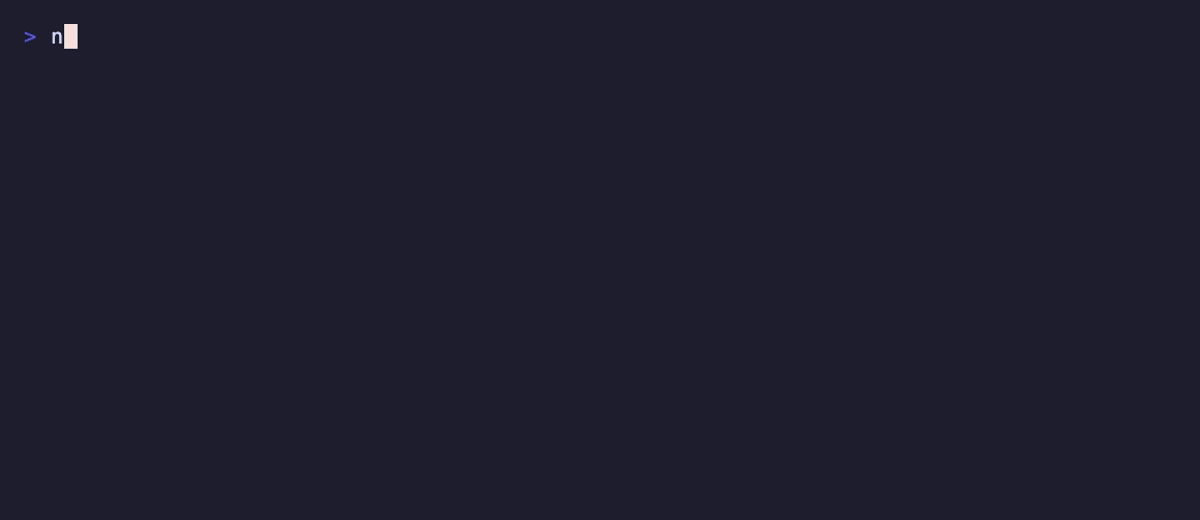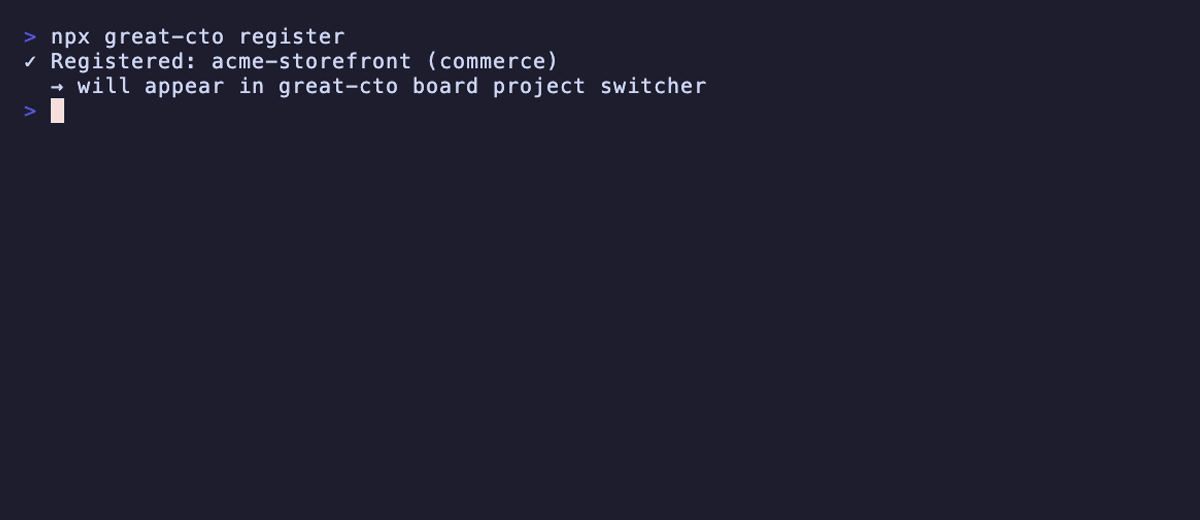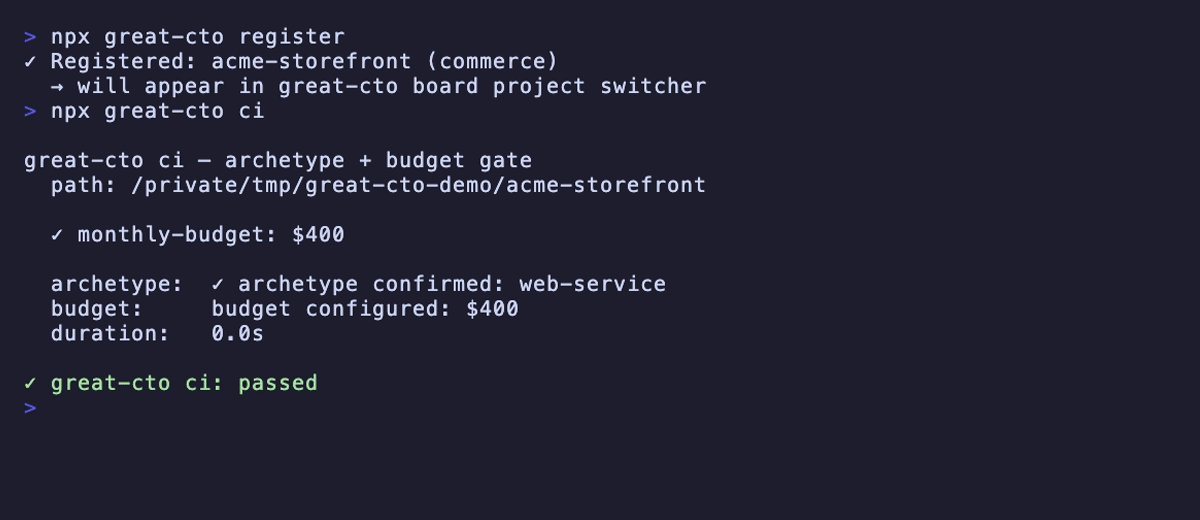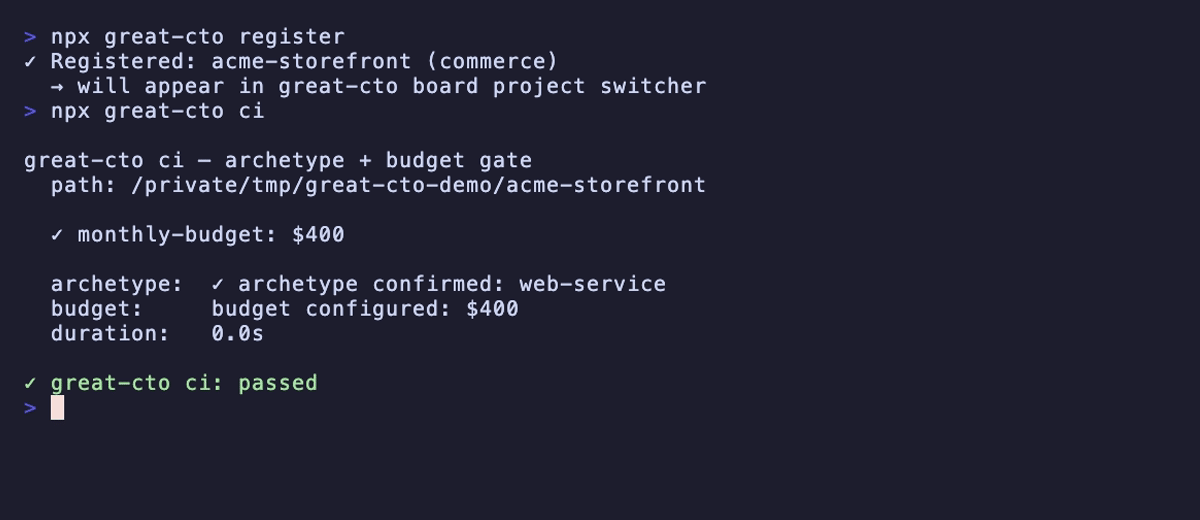
The board at localhost:3141 fills itself in — Decisions (what needs you),
Ledger (what it cost), Fleet (which agent to stop trusting), Harness
(who gave the second opinion, and what it actually did). Nothing on it renders
an absence as a pass: a scan that never ran is n/a, never a green zero.
Numbers, measured
| One feature, end to end, fully traced | 1h 26m · $3.40 in tokens — the receipts |
| A whole product — 7 built in the open benchmark | median $171 in tokens · 70/100 quality (58–86), measured 2026-07-10 — reproduce it |
| Typical month, 20 pipeline runs | ~$34 — you pay your own LLM provider, nothing else |
| Products it knows how to build | 60, across 15 US industries, through 6 reusable pipelines |
The quality score is produced by running each product's own tests, not by counting files — which is why it says 70 and not a rounder, prettier number.
Quick start
npx great-cto init
Restart Claude Code, then:
/start "build a dispatch & scheduling app for an HVAC business"
The pipeline takes it from there. Day to day you touch three things:
/start "…" | describe a product or feature — the pipeline runs it |
/inbox | what needs you: pending gates, P0s, blocked tasks |
/digest | weekly DORA metrics + cost-per-feature roll-up |
Requires Node ≥ 18.17. Companion plugins (Superpowers, Beads) install
automatically. After init, verify the host actually loaded the plugin —
claude plugin list --json should show no errors for great-cto.
On OpenAI Codex (npx great-cto init --host codex) you get the skills and
MCP server. Codex still has no native plugin surface for hooks, slash commands
or role agents, so /start does not become a Codex slash command and Claude
hooks do not silently run there. That is a limit of the host, not a setting:
hooks in a plugin manifest is never read
(openai/codex#16430,
#39895).
The supported pipeline path is the separate controller shipped by the npm CLI:
npx --yes great-cto@3.29.0 codex-host doctor
npx --yes great-cto@3.29.0 codex-host start --dir "$PWD" --prompt "build the feature" --allow src,tests,docs
npx --yes great-cto@3.29.0 codex-host resume <run-uuid>
It routes the shared graph through controlled Codex role profiles, applies only validated text proposals, runs an independent verifier, preserves the run cursor outside the worker repository and enforces human gates. Optional operator-owned policies add offline Docker checks and approval-bound local or GitHub Release publication with byte verification and recovery. The boundary is deliberate: this is a controlled host runtime, not emulation of native Codex hooks, arbitrary shell deployment, npm publishing or service activation. See the Codex host guide and support contract.
Two harnesses, one review. Independently of the controlled host, Codex can
also be the second opinion for a Claude Code run. From inside Claude Code it
reads the same diff, and each
review line carries the sha of the tree it read, so "reviewed" can be proven
about this diff rather than asserted. The log holds 4 lines so far, 1
carrying a sha; no catch-rate is claimed from that, and none should be.
Since 3.26.0 Codex takes part in the pipeline as that second reviewer. Declare it once:
# .great_cto/PROJECT.md
capabilities:
  second_opinion: codex      # or: openrouter · none
and on every high-stakes change the Claude code-reviewer and codex exec
(read-only sandbox, your Codex login, no API key) review the same diff at the
same time. Findings merge; a P0 from either side blocks; where they disagree,
both sets reach the human at the gate — the stricter one sets the verdict, and
nobody averages. The board's Harness screen detects Codex, holds the choice,
and shows beside it what the second opinion did: every run, including skipped
ones, from .great_cto/cross-review.log. Four states, and the fourth is the
point — declared but unavailable is never shown as off.
How much it helps is measured there, not asserted here. What the log holds so far: the first real Codex review — of the commit that wired Codex in — found a P1 that the author and the test suite had both missed; the review of the fix found nothing. Two runs is evidence of the mechanism, not a rate. The rate is the card's job.
When it asks you
One setting in .great_cto/PROJECT.md decides where the pipeline stops:
approval-level | Stops you at | Stops |
|---|---|---|
ship-only | the deploy — and briefs you on what gets built | 1 |
product-only | what we build · whether it ships | 2 |
gates-only (default) | what we build · the design · the deploy | 3 |
strict | the design · code review · the deploy | 3 |
auto | nothing in the pipeline | 0 |
Counts are pipeline stops. Every level also carries one guard that is not a
process choice: importing data over existing records stops you at every
level, auto included, because that one destroys what was there.
ship-only is the minimum that is still honest. One stop — the deploy, the
only decision whose consequence leaves your machine. The what gets built
decision does not vanish, because a pipeline that spends a day on the wrong thing
is the expensive failure: it arrives as one screen in your console, printed once,
before the build starts.
ABOUT TO BUILD — say nothing and this proceeds, say something and it stops.

  What gets built:  the offline-first checkout; ship the queue before the UI
  Why:              reliability wins this segment, not features
  Stop if:          under 20% of orders are created offline after four weeks
  Left open:        which conflict rule for a re-submitted order

  Full brief: docs/product/BRIEF-checkout.md
Silence is consent, and the screen says so. If the brief cannot be read, the gate comes back — "I could not show you" is never delivered as "you were shown and said nothing".
gates-only gained the product gate in v3.0.0. It used to stop on how to build
and whether to release, and never on what to build — the decision that is
wrong for six stages before anyone finds out. It costs one pause per product,
not per feature: product-owner is an entry point and runs only from /start.
A regulated archetype — fintech, healthcare, gov — keeps its security,
compliance and ship gates at every level, including auto. A lighter level
delegates judgement; it never skips compliance. Full table: docs/GATES.md.
Four things it refuses to say
The same rule, in the four places it costs something to keep: a thing that did not happen must never look like a thing that did.
| When | What is easy to show | What it shows instead |
|---|---|---|
| A second opinion is declared but its harness is missing | off | unavailable — declared and unreachable is not a choice you made |
| A check ran and could not decide | pass | unverifiable — and the stage does not proceed on it |
| A run's cost was never measured | $0.00 | unmeasured — and budgets do not fire on it |
| A stage was assessed by nobody | 0 | null — a pass rate divides by what was actually assessed |
Each of these is a place where the honest answer is longer, uglier, and harder to build than the confident one. That is the whole product.
The proof is subtraction. v3.27.0 and v3.27.1 deleted this project's own favourable numbers — "cost savings vs FTE", a spend comparison against a human team, a projected month — because none of them could be shown to be true.
The three doubts worth having
“I can't trust code I didn't watch being written.”
Neither do we, so nothing is taken on an agent's word about itself. Each stage is
checked against what it actually produced — do the named files exist, do the
frozen acceptance criteria pass when run, and only then is a separate model asked
whether each requirement is addressed. Where that check cannot tell, it returns
unverifiable, which is not a pass.
“It will spend money while I sleep.”
Per-agent budgets decline to dispatch past their cap and name the number. A run
whose cost could not be measured reads unmeasured and holds nothing — a limit
firing on a number nobody measured is worse than no limit, and a confident
$0.00 for unmeasured work is how a spend goes unnoticed.
“And then I'm locked in.” One command to install, MIT, running on your machine against your own LLM account. Delete great_cto and the repository it built is still yours — ordinary Next.js, Postgres and Stripe that any engineer can pick up.
What makes it different
- Specialists, not a generalist — 70 agents with narrow jobs and their own review gates, instead of one assistant that types faster than it thinks. The roster →
- Critics before code — architecture, spec, and schema critics run before planning, where a mistake still costs hours instead of days.
- Scope enforced at write time — an agent physically cannot touch files outside its brief. Not flagged at review; refused at write.
- QA that distrusts itself — critical paths written as Gherkin before test code, then mutation testing asks whether the suite would catch anything at all.
- Memory across sessions — decisions, lessons, and promoted patterns persist per project and globally; an interrupted run resumes knowing which stages ran.
- Cost you can see — per-agent spend, estimate-vs-actual drift, and cost-per-accepted-change on the board, not in a spreadsheet.
- Spending caps that refuse —
agent-budgets:in PROJECT.md caps what a stage may spend; the pipeline declines to dispatch past it and names the number. An estimate never refuses — see the table above. - A stage is checked before the next builds on it — files named by the
verdict must exist, frozen
## ACCEPTANCEcriteria must pass when run, and only then is a second model asked whether each requirement is addressed. Cheapest question first, and three answers rather than two:verified,rework, orunverifiable. An agent that claims nothing and freezes no criteria is reported — otherwise the cheapest way to pass is claiming nothing. - Work goes back, and the return has a ceiling — a failed stage returns
REWORKwith the findings quoted and the same agent fixes it;BLOCKEDmeans a human must decide. After three passes it becomes the human's problem, because two machines handing work back and forth do not get bored. - Quality kept apart from what happened — the verdict says what a run did, a score says how well, in its own append-only store by a different actor at a different time. Scorers may disagree, and every score names who made it.
- Silence is recorded — the dispatcher writes what it decided to
.great_cto/pipeline-runs.jsonl, including when it decided nothing and why. Every pipeline defect found this year hid in the gap between "nothing should happen" and "nothing could happen".
Everything runs locally, MIT-licensed, on your own keys. Your code stays on your machine; prompts go to your LLM provider and nowhere else. Telemetry is off by default (docs/PRIVACY.md).
Limitations
- Not a hosted app builder — it does not replace your coding agent; without one there is nothing for it to orchestrate.
- For one builder — a solo founder or CTO. Two or more engineers sharing the pipeline have outgrown it.
- Not a CI/CD system — gates run locally; you still merge through GitHub Actions.
- Not certification-audited — PCI/HIPAA/SOC2 scaffolds are starting points, not certifications.
- Not deterministic — LLM output. Gate verdicts deserve a sanity check.
- Spend is measured, attribution is not yet per-agent — cost is read from
the host's own session transcript rather than from an agent's self-report, so
the tokens are real. But the transcript the hook is handed covers the session,
not one subagent, so a run's cost can be attributed to whichever stage finished
last — inflated by orders of magnitude. Treat per-agent figures as a ceiling
until this is fixed. A stage with no measurement at all still shows
unmeasuredrather than a confident$0.00, and budgets do not fire for it.
Documentation
Docs hub → · Getting started · Gates & approval levels · Agents · Commands · Archetypes · Architecture · MCP · FAQ · Everything else — critics, jurisdictions, cost breakdown, CI, alerts
Community
Issues · Discussions · Blog · Security policy · Contributing
MIT — LICENSE. Built by @avelikiy: CTO building AI-native trading and fintech platforms; great_cto is my own loops, automated one agent at a time.
If it saved you time, a star helps other solo builders find it.
Stop being the only person who can ship.
Contributors


Similar repos


Languages
JavaScript
73.4%
HTML
10.1%
TypeScript
7.3%
Shell
5.5%
Python
3.8%
You already have the agent. This is everything around it. great_cto runs Claude Code as a pipeline of 70 specialist agents — an independent model checks each stage before the next builds on it, spending caps refuse rather than warn, and three decisions stay yours: what gets built, how, and whether it ships.
93
stars
1,490
commits
JavaScript
primary language
Sep 15, 2026
updated
README
Ship products with the coding agent you already have.
npx great-cto init
Website · One real run → · Live demo · Blog · Changelog
Русский · 简体中文 · 繁體中文 · 日本語 · 한국어 · Español · Português · Deutsch · Français
Your coding agent ships code. This is what checks it.
You write a spec. Your Claude Code builds against it, a second model from another family reads the same diff, and where they disagree you see the disagreement and decide. Three decisions stay yours — what gets built, how, and whether it ships. What lands is a repository you own and a URL that works.
Seven products built this way in the open benchmark: median $171 in tokens, measured 2026-07-10. You pay your own LLM provider; great_cto is MIT and bills nothing.
   describe a product
        │
   🤖  problem framed · options weighed · brief written
        ▼
   👤  checkpoint 1 — approve WHAT gets built
        │
   🤖  architecture · data model · screens · plan
        ▼
   👤  checkpoint 2 — approve HOW it gets built
        │
   🤖  scaffold → backend → frontend → tests → review → security
        ▼
   👤  checkpoint 3 — approve the deploy
        │
   🤖  deployed · repo · live URL
Three stops is the default, not the floor. One line takes it to one:
approval-level: ship-only
The board at localhost:3141 fills itself in — Decisions (what needs you),
Ledger (what it cost), Fleet (which agent to stop trusting), Harness
(who gave the second opinion, and what it actually did). Nothing on it renders
an absence as a pass: a scan that never ran is n/a, never a green zero.
Numbers, measured
| One feature, end to end, fully traced | 1h 26m · $3.40 in tokens — the receipts |
| A whole product — 7 built in the open benchmark | median $171 in tokens · 70/100 quality (58–86), measured 2026-07-10 — reproduce it |
| Typical month, 20 pipeline runs | ~$34 — you pay your own LLM provider, nothing else |
| Products it knows how to build | 60, across 15 US industries, through 6 reusable pipelines |
The quality score is produced by running each product's own tests, not by counting files — which is why it says 70 and not a rounder, prettier number.
Quick start
npx great-cto init
Restart Claude Code, then:
/start "build a dispatch & scheduling app for an HVAC business"
The pipeline takes it from there. Day to day you touch three things:
/start "…" | describe a product or feature — the pipeline runs it |
/inbox | what needs you: pending gates, P0s, blocked tasks |
/digest | weekly DORA metrics + cost-per-feature roll-up |
Requires Node ≥ 18.17. Companion plugins (Superpowers, Beads) install
automatically. After init, verify the host actually loaded the plugin —
claude plugin list --json should show no errors for great-cto.
On OpenAI Codex (npx great-cto init --host codex) you get the skills and
MCP server. Codex still has no native plugin surface for hooks, slash commands
or role agents, so /start does not become a Codex slash command and Claude
hooks do not silently run there. That is a limit of the host, not a setting:
hooks in a plugin manifest is never read
(openai/codex#16430,
#39895).
The supported pipeline path is the separate controller shipped by the npm CLI:
npx --yes great-cto@3.29.0 codex-host doctor
npx --yes great-cto@3.29.0 codex-host start --dir "$PWD" --prompt "build the feature" --allow src,tests,docs
npx --yes great-cto@3.29.0 codex-host resume <run-uuid>
It routes the shared graph through controlled Codex role profiles, applies only validated text proposals, runs an independent verifier, preserves the run cursor outside the worker repository and enforces human gates. Optional operator-owned policies add offline Docker checks and approval-bound local or GitHub Release publication with byte verification and recovery. The boundary is deliberate: this is a controlled host runtime, not emulation of native Codex hooks, arbitrary shell deployment, npm publishing or service activation. See the Codex host guide and support contract.
Two harnesses, one review. Independently of the controlled host, Codex can
also be the second opinion for a Claude Code run. From inside Claude Code it
reads the same diff, and each
review line carries the sha of the tree it read, so "reviewed" can be proven
about this diff rather than asserted. The log holds 4 lines so far, 1
carrying a sha; no catch-rate is claimed from that, and none should be.
Since 3.26.0 Codex takes part in the pipeline as that second reviewer. Declare it once:
# .great_cto/PROJECT.md
capabilities:
  second_opinion: codex      # or: openrouter · none
and on every high-stakes change the Claude code-reviewer and codex exec
(read-only sandbox, your Codex login, no API key) review the same diff at the
same time. Findings merge; a P0 from either side blocks; where they disagree,
both sets reach the human at the gate — the stricter one sets the verdict, and
nobody averages. The board's Harness screen detects Codex, holds the choice,
and shows beside it what the second opinion did: every run, including skipped
ones, from .great_cto/cross-review.log. Four states, and the fourth is the
point — declared but unavailable is never shown as off.
How much it helps is measured there, not asserted here. What the log holds so far: the first real Codex review — of the commit that wired Codex in — found a P1 that the author and the test suite had both missed; the review of the fix found nothing. Two runs is evidence of the mechanism, not a rate. The rate is the card's job.
When it asks you
One setting in .great_cto/PROJECT.md decides where the pipeline stops:
approval-level | Stops you at | Stops |
|---|---|---|
ship-only | the deploy — and briefs you on what gets built | 1 |
product-only | what we build · whether it ships | 2 |
gates-only (default) | what we build · the design · the deploy | 3 |
strict | the design · code review · the deploy | 3 |
auto | nothing in the pipeline | 0 |
Counts are pipeline stops. Every level also carries one guard that is not a
process choice: importing data over existing records stops you at every
level, auto included, because that one destroys what was there.
ship-only is the minimum that is still honest. One stop — the deploy, the
only decision whose consequence leaves your machine. The what gets built
decision does not vanish, because a pipeline that spends a day on the wrong thing
is the expensive failure: it arrives as one screen in your console, printed once,
before the build starts.
ABOUT TO BUILD — say nothing and this proceeds, say something and it stops.

  What gets built:  the offline-first checkout; ship the queue before the UI
  Why:              reliability wins this segment, not features
  Stop if:          under 20% of orders are created offline after four weeks
  Left open:        which conflict rule for a re-submitted order

  Full brief: docs/product/BRIEF-checkout.md
Silence is consent, and the screen says so. If the brief cannot be read, the gate comes back — "I could not show you" is never delivered as "you were shown and said nothing".
gates-only gained the product gate in v3.0.0. It used to stop on how to build
and whether to release, and never on what to build — the decision that is
wrong for six stages before anyone finds out. It costs one pause per product,
not per feature: product-owner is an entry point and runs only from /start.
A regulated archetype — fintech, healthcare, gov — keeps its security,
compliance and ship gates at every level, including auto. A lighter level
delegates judgement; it never skips compliance. Full table: docs/GATES.md.
Four things it refuses to say
The same rule, in the four places it costs something to keep: a thing that did not happen must never look like a thing that did.
| When | What is easy to show | What it shows instead |
|---|---|---|
| A second opinion is declared but its harness is missing | off | unavailable — declared and unreachable is not a choice you made |
| A check ran and could not decide | pass | unverifiable — and the stage does not proceed on it |
| A run's cost was never measured | $0.00 | unmeasured — and budgets do not fire on it |
| A stage was assessed by nobody | 0 | null — a pass rate divides by what was actually assessed |
Each of these is a place where the honest answer is longer, uglier, and harder to build than the confident one. That is the whole product.
The proof is subtraction. v3.27.0 and v3.27.1 deleted this project's own favourable numbers — "cost savings vs FTE", a spend comparison against a human team, a projected month — because none of them could be shown to be true.
The three doubts worth having
“I can't trust code I didn't watch being written.”
Neither do we, so nothing is taken on an agent's word about itself. Each stage is
checked against what it actually produced — do the named files exist, do the
frozen acceptance criteria pass when run, and only then is a separate model asked
whether each requirement is addressed. Where that check cannot tell, it returns
unverifiable, which is not a pass.
“It will spend money while I sleep.”
Per-agent budgets decline to dispatch past their cap and name the number. A run
whose cost could not be measured reads unmeasured and holds nothing — a limit
firing on a number nobody measured is worse than no limit, and a confident
$0.00 for unmeasured work is how a spend goes unnoticed.
“And then I'm locked in.” One command to install, MIT, running on your machine against your own LLM account. Delete great_cto and the repository it built is still yours — ordinary Next.js, Postgres and Stripe that any engineer can pick up.
What makes it different
- Specialists, not a generalist — 70 agents with narrow jobs and their own review gates, instead of one assistant that types faster than it thinks. The roster →
- Critics before code — architecture, spec, and schema critics run before planning, where a mistake still costs hours instead of days.
- Scope enforced at write time — an agent physically cannot touch files outside its brief. Not flagged at review; refused at write.
- QA that distrusts itself — critical paths written as Gherkin before test code, then mutation testing asks whether the suite would catch anything at all.
- Memory across sessions — decisions, lessons, and promoted patterns persist per project and globally; an interrupted run resumes knowing which stages ran.
- Cost you can see — per-agent spend, estimate-vs-actual drift, and cost-per-accepted-change on the board, not in a spreadsheet.
- Spending caps that refuse —
agent-budgets:in PROJECT.md caps what a stage may spend; the pipeline declines to dispatch past it and names the number. An estimate never refuses — see the table above. - A stage is checked before the next builds on it — files named by the
verdict must exist, frozen
## ACCEPTANCEcriteria must pass when run, and only then is a second model asked whether each requirement is addressed. Cheapest question first, and three answers rather than two:verified,rework, orunverifiable. An agent that claims nothing and freezes no criteria is reported — otherwise the cheapest way to pass is claiming nothing. - Work goes back, and the return has a ceiling — a failed stage returns
REWORKwith the findings quoted and the same agent fixes it;BLOCKEDmeans a human must decide. After three passes it becomes the human's problem, because two machines handing work back and forth do not get bored. - Quality kept apart from what happened — the verdict says what a run did, a score says how well, in its own append-only store by a different actor at a different time. Scorers may disagree, and every score names who made it.
- Silence is recorded — the dispatcher writes what it decided to
.great_cto/pipeline-runs.jsonl, including when it decided nothing and why. Every pipeline defect found this year hid in the gap between "nothing should happen" and "nothing could happen".
Everything runs locally, MIT-licensed, on your own keys. Your code stays on your machine; prompts go to your LLM provider and nowhere else. Telemetry is off by default (docs/PRIVACY.md).
Limitations
- Not a hosted app builder — it does not replace your coding agent; without one there is nothing for it to orchestrate.
- For one builder — a solo founder or CTO. Two or more engineers sharing the pipeline have outgrown it.
- Not a CI/CD system — gates run locally; you still merge through GitHub Actions.
- Not certification-audited — PCI/HIPAA/SOC2 scaffolds are starting points, not certifications.
- Not deterministic — LLM output. Gate verdicts deserve a sanity check.
- Spend is measured, attribution is not yet per-agent — cost is read from
the host's own session transcript rather than from an agent's self-report, so
the tokens are real. But the transcript the hook is handed covers the session,
not one subagent, so a run's cost can be attributed to whichever stage finished
last — inflated by orders of magnitude. Treat per-agent figures as a ceiling
until this is fixed. A stage with no measurement at all still shows
unmeasuredrather than a confident$0.00, and budgets do not fire for it.
Documentation
Docs hub → · Getting started · Gates & approval levels · Agents · Commands · Archetypes · Architecture · MCP · FAQ · Everything else — critics, jurisdictions, cost breakdown, CI, alerts
Community
Issues · Discussions · Blog · Security policy · Contributing
MIT — LICENSE. Built by @avelikiy: CTO building AI-native trading and fintech platforms; great_cto is my own loops, automated one agent at a time.
If it saved you time, a star helps other solo builders find it.
Stop being the only person who can ship.
Similar repos
Contributors
Languages
JavaScript
73.4%
HTML
10.1%
TypeScript
7.3%
Shell
5.5%
Python
3.8%