
See what people are saying
README
Animator
Type an idea, get a narrated hand-drawn whiteboard explainer video.
python -m animator --prompt "How do planes fly?" -o plane.mp4
One command writes the script, draws each scene, records the narration, and animates every icon while its sentence is being spoken. A 4–5 scene video takes about a minute.
Examples
All three were generated from a single prompt each, with no editing afterwards.
 | 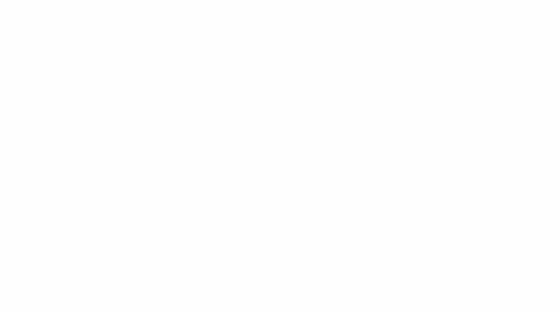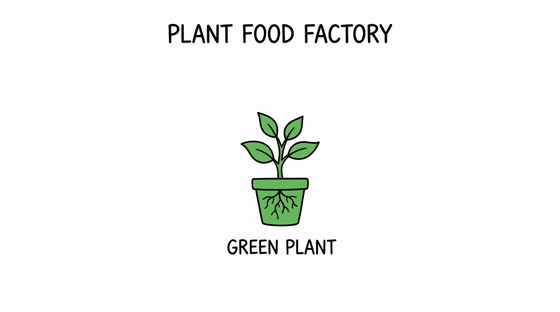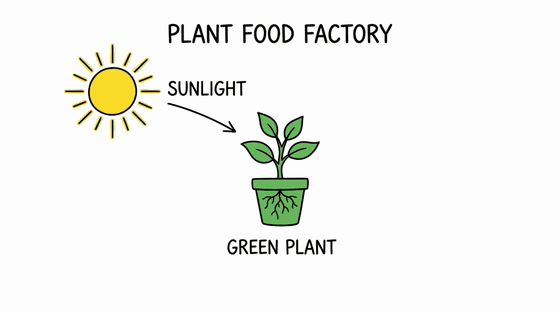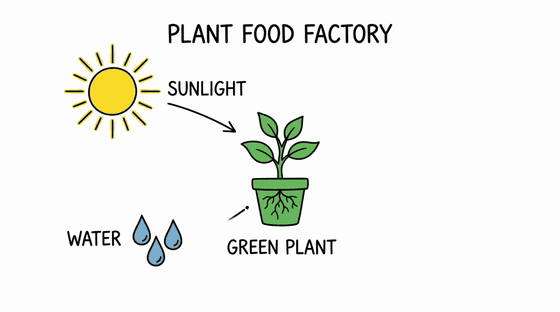 | |
| Einstein's Famous Equation 4 scenes · 1:39 examples/einstein_emc2.mp4 | How Photosynthesis Works 5 scenes · 1:50 examples/photosynthesis.mp4 | How Wings Create Lift 5 scenes · 1:36 examples/plane_flight.mp4 |
Click a preview to open the full video with sound.
How it works
"How do planes fly?"
   │
   ├─ 1. Storyboard   Gemini writes scenes made of beats: one sentence + one icon each
   ├─ 2. Images       Gemini draws each scene as a 16:9 whiteboard frame
   ├─ 3. Narration    Gemini TTS speaks each scene; the pauses mark where each beat starts and ends
   ├─ 4. Regions      Gemini finds each icon in the image and assigns it to its beat
   └─ 5. Animation    The local engine draws each icon during its beat → MP4
Steps 2–4 run for all scenes in parallel. Step 5 runs locally on CPU: it writes text stroke by stroke, traces outlines from their real endpoints, fills shapes with brush strokes, and draws branching line art one path at a time. A small bundled CRAFT model tells text apart from shapes. No GPU is needed.
Setup
You need Python 3.10+ and FFmpeg.
# 1. FFmpeg
brew install ffmpeg                # macOS
sudo apt install ffmpeg            # Ubuntu / Debian
# Windows: https://ffmpeg.org/download.html, then add its bin folder to PATH

# 2. Python dependencies
python -m venv .venv
source .venv/bin/activate          # Windows: .venv\Scripts\Activate.ps1
pip install -r requirements.txt

# 3. API key (only for --prompt and --detect-regions)
cp env.example .env                # then paste your key into .env
Get a key at Google AI Studio. The .env file is loaded automatically and is git-ignored.
Usage
From a prompt
python -m animator --prompt "How photosynthesis works" -o photosynthesis.mp4
| Flag | What it does |
|---|---|
--scenes N | Exact number of scenes (default: Gemini decides, usually 3–6) |
--voice NAME | Gemini TTS voice (default Kore) |
--quality low|medium|high | 20fps/500k, 24fps/1500k (default), 24fps/3000k |
--save-storyboard | Keep the script, images, audio and region plans in <output>.storyboard/ |
--gemini-model, --image-model, --tts-model | Override the Gemini models |
-v | Show progress logs |
From your own images
No API key is needed for these.
# fixed length, silent
python -m animator scene.png --duration 8 -o scene.mp4

# paced to your narration
python -m animator scene.png --audio scene.wav -o scene.mp4

# several scenes joined in order
python -m animator a.png b.png --audio a.wav b.wav -o lecture.mp4
To control the drawing order, pass a region plan with --regions plan.json. To have Gemini work out the order from the image and narration text instead, use --detect-regions --narration "...". Add --save-regions to keep the detected plan so you can edit it and render again.
Images work best as ink on white: clean marker drawings with a few flat colours. Photos, gradients and dark backgrounds don't animate well.
From Python
from animator import Scene, SnippetRegionPlan, render_video

plan = SnippetRegionPlan.model_validate_json(open("a.regions.json").read())
render_video([Scene("a.png", audio="a.wav", region_plan=plan)], "out.mp4", quality="high")
Customise the style
Every prompt sent to Gemini is a plain text file in animator/prompts/:
| File | Controls |
|---|---|
storyboard.txt | Script structure, tone, story arc, recurring character |
image_style.txt | Art style of every frame (doodle icons, colours, spacing) |
scene_image.txt | How each scene's icons and layout are described to the image model |
region_detection.txt, region_beats.txt | How icons are found and matched to sentences |
Edit them and run again. No code changes are needed.
Project layout
animator/
  prompts/      every prompt, as editable .txt files
  gemini/       storyboard → images → narration → regions → pipeline
  engine.py     drawing engine (ordering, stroke tracing, fills)
  render.py     scenes → MP4 via FFmpeg
  cli.py        command line
  api/          HTTP API for the web app (python -m animator.api)
frontend/       React web app (Supabase sign-in, studio)
examples/       sample videos
Troubleshooting
ffmpegnot found: install FFmpeg (see Setup) and open a new terminal. The pip package calledffmpegis not the same thing.needs GEMINI_API_KEY: put the key in.env, orexport GEMINI_API_KEY=....- 429 / rate-limit warnings: these calls are retried automatically with backoff. On the free tier, use fewer scenes with
--scenes 3. - A caption appears before it is spoken: run with
--save-storyboardand checkscene_XX.regions.json. Each region'sbeatdecides when it draws.
Similar repos


Languages
Python
100.0%
See what people are saying
README
Animator
Type an idea, get a narrated hand-drawn whiteboard explainer video.
python -m animator --prompt "How do planes fly?" -o plane.mp4
One command writes the script, draws each scene, records the narration, and animates every icon while its sentence is being spoken. A 4–5 scene video takes about a minute.
Examples
All three were generated from a single prompt each, with no editing afterwards.
| | |
| Einstein's Famous Equation 4 scenes · 1:39 examples/einstein_emc2.mp4 | How Photosynthesis Works 5 scenes · 1:50 examples/photosynthesis.mp4 | How Wings Create Lift 5 scenes · 1:36 examples/plane_flight.mp4 |
Click a preview to open the full video with sound.
How it works
"How do planes fly?"
   │
   ├─ 1. Storyboard   Gemini writes scenes made of beats: one sentence + one icon each
   ├─ 2. Images       Gemini draws each scene as a 16:9 whiteboard frame
   ├─ 3. Narration    Gemini TTS speaks each scene; the pauses mark where each beat starts and ends
   ├─ 4. Regions      Gemini finds each icon in the image and assigns it to its beat
   └─ 5. Animation    The local engine draws each icon during its beat → MP4
Steps 2–4 run for all scenes in parallel. Step 5 runs locally on CPU: it writes text stroke by stroke, traces outlines from their real endpoints, fills shapes with brush strokes, and draws branching line art one path at a time. A small bundled CRAFT model tells text apart from shapes. No GPU is needed.
Setup
You need Python 3.10+ and FFmpeg.
# 1. FFmpeg
brew install ffmpeg                # macOS
sudo apt install ffmpeg            # Ubuntu / Debian
# Windows: https://ffmpeg.org/download.html, then add its bin folder to PATH

# 2. Python dependencies
python -m venv .venv
source .venv/bin/activate          # Windows: .venv\Scripts\Activate.ps1
pip install -r requirements.txt

# 3. API key (only for --prompt and --detect-regions)
cp env.example .env                # then paste your key into .env
Get a key at Google AI Studio. The .env file is loaded automatically and is git-ignored.
Usage
From a prompt
python -m animator --prompt "How photosynthesis works" -o photosynthesis.mp4
| Flag | What it does |
|---|---|
--scenes N | Exact number of scenes (default: Gemini decides, usually 3–6) |
--voice NAME | Gemini TTS voice (default Kore) |
--quality low|medium|high | 20fps/500k, 24fps/1500k (default), 24fps/3000k |
--save-storyboard | Keep the script, images, audio and region plans in <output>.storyboard/ |
--gemini-model, --image-model, --tts-model | Override the Gemini models |
-v | Show progress logs |
From your own images
No API key is needed for these.
# fixed length, silent
python -m animator scene.png --duration 8 -o scene.mp4

# paced to your narration
python -m animator scene.png --audio scene.wav -o scene.mp4

# several scenes joined in order
python -m animator a.png b.png --audio a.wav b.wav -o lecture.mp4
To control the drawing order, pass a region plan with --regions plan.json. To have Gemini work out the order from the image and narration text instead, use --detect-regions --narration "...". Add --save-regions to keep the detected plan so you can edit it and render again.
Images work best as ink on white: clean marker drawings with a few flat colours. Photos, gradients and dark backgrounds don't animate well.
From Python
from animator import Scene, SnippetRegionPlan, render_video

plan = SnippetRegionPlan.model_validate_json(open("a.regions.json").read())
render_video([Scene("a.png", audio="a.wav", region_plan=plan)], "out.mp4", quality="high")
Customise the style
Every prompt sent to Gemini is a plain text file in animator/prompts/:
| File | Controls |
|---|---|
storyboard.txt | Script structure, tone, story arc, recurring character |
image_style.txt | Art style of every frame (doodle icons, colours, spacing) |
scene_image.txt | How each scene's icons and layout are described to the image model |
region_detection.txt, region_beats.txt | How icons are found and matched to sentences |
Edit them and run again. No code changes are needed.
Project layout
animator/
  prompts/      every prompt, as editable .txt files
  gemini/       storyboard → images → narration → regions → pipeline
  engine.py     drawing engine (ordering, stroke tracing, fills)
  render.py     scenes → MP4 via FFmpeg
  cli.py        command line
  api/          HTTP API for the web app (python -m animator.api)
frontend/       React web app (Supabase sign-in, studio)
examples/       sample videos
Troubleshooting
ffmpegnot found: install FFmpeg (see Setup) and open a new terminal. The pip package calledffmpegis not the same thing.needs GEMINI_API_KEY: put the key in.env, orexport GEMINI_API_KEY=....- 429 / rate-limit warnings: these calls are retried automatically with backoff. On the free tier, use fewer scenes with
--scenes 3. - A caption appears before it is spoken: run with
--save-storyboardand checkscene_XX.regions.json. Each region'sbeatdecides when it draws.
Similar repos
Languages
Python
100.0%