Grounded Docs MCP Server: Open-Source Alternative to Context7, Nia, and Ref.Tools
See the codeDocs MCP Server solves the problem of AI hallucinations and outdated knowledge by providing a personal, always-current documentation index for your AI coding assistant. It fetches official docs from websites, GitHub, npm, PyPI, and local files, allowing your AI to query the exact version you are using.
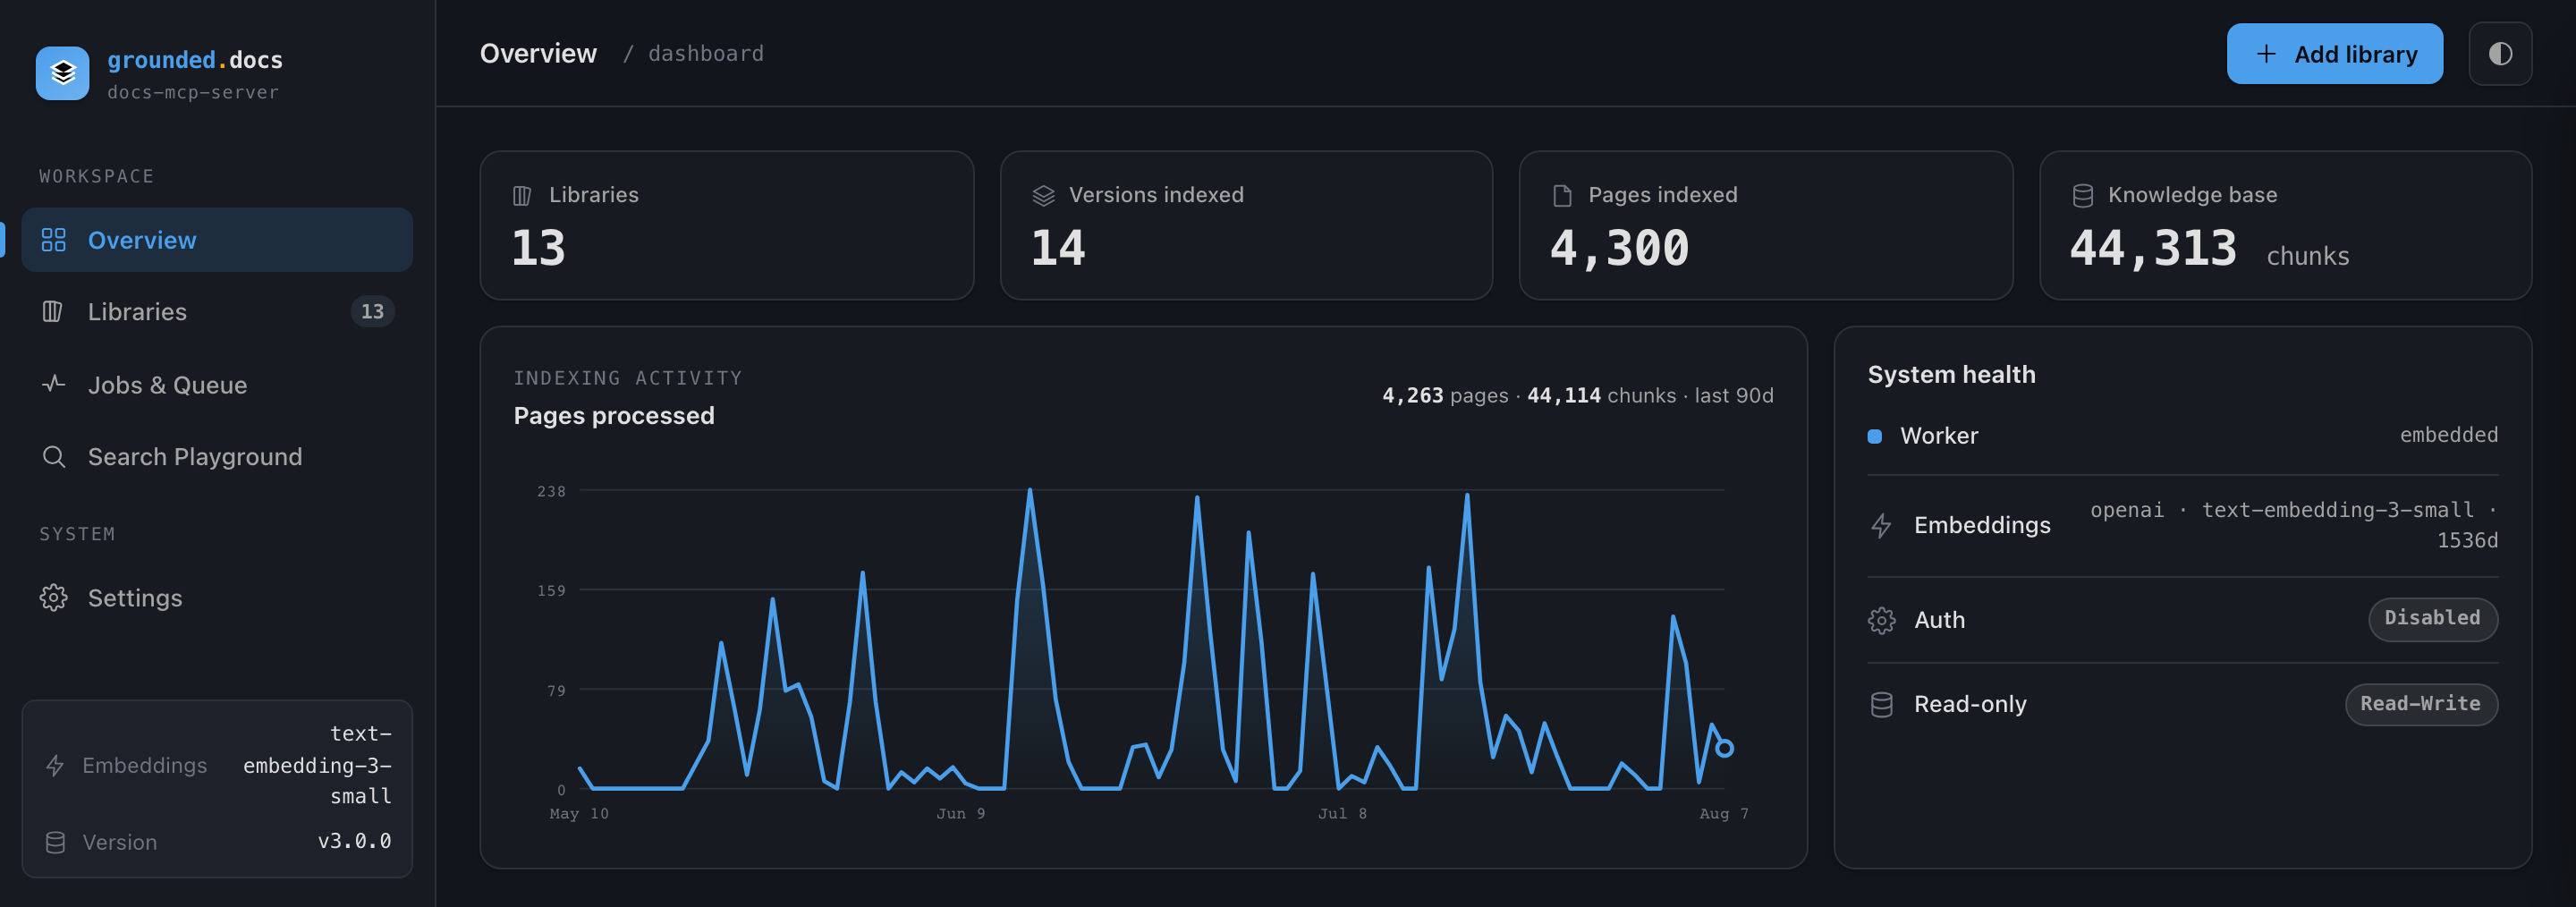
The open-source alternative to Context7, Nia, and Ref.Tools.
| Category | Formats |
|---|---|
| Documents | PDF, Word (.docx/.doc), Excel (.xlsx/.xls), PowerPoint (.pptx/.ppt), OpenDocument (.odt/.ods/.odp), RTF, EPUB, FictionBook, Jupyter Notebooks |
| Archives | ZIP, TAR, gzipped TAR (contents are extracted and processed individually) |
| Web | HTML, XHTML |
| Markup | Markdown, MDX, reStructuredText, AsciiDoc, Org Mode, Textile, R Markdown |
| Source Code | TypeScript, JavaScript, Python, Go, Rust, C/C++, Java, Kotlin, Ruby, PHP, Swift, C#, and many more |
| Data | JSON, YAML, TOML, CSV, XML, SQL, GraphQL, Protocol Buffers |
| Config | Dockerfile, Makefile, Terraform/HCL, INI, dotenv, Bazel |
See Supported Formats for the complete reference including MIME types and processing details.
For agents and scripts, the CLI is usually the simplest way to use Grounded Docs.
1. Index documentation (requires Node.js 22+):
npx @arabold/docs-mcp-server@latest scrape react https://react.dev/reference/react
Scraping a library version that already exists fails rather than overwriting it. Re-index it with --replace, or update it in place with refresh:
npx @arabold/docs-mcp-server@latest scrape react https://react.dev/reference/react --replace
For hash-routed SPA docs sites, enable hash preservation explicitly:
npx @arabold/docs-mcp-server@latest scrape my-spa https://docs.example.com/#/guide --preserve-hashes
2. Query the index:
npx @arabold/docs-mcp-server@latest search react "useEffect cleanup" --output yaml
3. Fetch a single page as Markdown:
npx @arabold/docs-mcp-server@latest fetch-url https://react.dev/reference/react/useEffect
--output json|yaml|toon to pick a structured format.fetch-url keep their text payload on stdout.--quiet to suppress non-error diagnostics or --verbose to enable debug output.The skills/ directory contains Agent Skills that teach AI coding assistants how to use the CLI — covering documentation search, index management, and URL fetching.
If you want a long-running MCP endpoint for Claude, Cline, Copilot, Gemini CLI, or other MCP clients:
1. Start the server:
npx @arabold/docs-mcp-server@latest
2. Open the Web UI at http://localhost:6280 to add documentation.
3. Connect your AI client by adding this to your MCP settings (e.g., claude_desktop_config.json):
{
  "mcpServers": {
    "docs-mcp-server": {
      "type": "http",
      "url": "http://localhost:6280/mcp"
    }
  }
}
The HTTP endpoint speaks MCP over Streamable HTTP, for protocol revision 2026-07-28 as well as earlier revisions. See Connecting Clients for VS Code (Cline, Roo) and other setup options, and Reverse Proxy Deployment to serve it under a path such as https://example.com/docs.
scrape_docs also accepts preserveHashes: true for documentation sites that use hash-based client-side routing.
Use it only for hash-routed SPAs; normal sites typically use hash fragments for in-page anchors.
scrape_docs rejects a library version that already exists (including one still queued or that failed); pass replace: true to rebuild it, or use refresh_version to update it in place.
docker run --rm \
  -v docs-mcp-data:/data \
  -v docs-mcp-config:/config \
  -p 6280:6280 \
  ghcr.io/arabold/docs-mcp-server:latest
The Docker image defaults to HTTP on 0.0.0.0:6280, serving the Web UI, API, and MCP endpoint. For stdio clients, use docker run --rm -i ghcr.io/arabold/docs-mcp-server:latest --protocol stdio. See Installation for configuration overrides.
Using an embedding model is optional but dramatically improves search quality by enabling semantic vector search.
Example: Enable OpenAI Embeddings
OPENAI_API_KEY="sk-proj-..." npx @arabold/docs-mcp-server@latest
See Embedding Models for configuring Ollama, Gemini, Azure, and others.
--preserve-hashes, MCP preserveHashes, or the Web UI "Preserve Hash Routes" checkbox only for docs sites that route with URLs like #/guide.scrapeMode=fetch, the scraper automatically upgrades the job to Playwright because plain fetch cannot evaluate client-side hash routes.preserveHashes setting by default, and CLI/Web refresh entrypoints can override it explicitly.llms.txt at the documentation subpath and site root before normal crawling. When found, the curated links become additional crawl seeds, and pages discovered this way prefer .md URL variants such as /guide/index.html.md or /page.html.md before falling back to the original page.Accept: text/markdown, text/html;q=0.9, */*;q=0.8 by default. Servers that support Markdown content negotiation, including Cloudflare Markdown for Agents, can return Markdown directly so the scraper bypasses HTML-to-Markdown conversion for cleaner output.Accept headers are preserved when provided.We welcome contributions! Please see CONTRIBUTING.md for development guidelines and setup instructions.
This project is licensed under the MIT License. See LICENSE for details.
67 followers · starred Jul 2025
427 followers · starred Dec 2025
77 followers · starred Sep 2025
59 followers · starred May 2025
Grounded Docs MCP Server: Open-Source Alternative to Context7, Nia, and Ref.Tools
See the codeDocs MCP Server solves the problem of AI hallucinations and outdated knowledge by providing a personal, always-current documentation index for your AI coding assistant. It fetches official docs from websites, GitHub, npm, PyPI, and local files, allowing your AI to query the exact version you are using.
The open-source alternative to Context7, Nia, and Ref.Tools.
| Category | Formats |
|---|---|
| Documents | PDF, Word (.docx/.doc), Excel (.xlsx/.xls), PowerPoint (.pptx/.ppt), OpenDocument (.odt/.ods/.odp), RTF, EPUB, FictionBook, Jupyter Notebooks |
| Archives | ZIP, TAR, gzipped TAR (contents are extracted and processed individually) |
| Web | HTML, XHTML |
| Markup | Markdown, MDX, reStructuredText, AsciiDoc, Org Mode, Textile, R Markdown |
| Source Code | TypeScript, JavaScript, Python, Go, Rust, C/C++, Java, Kotlin, Ruby, PHP, Swift, C#, and many more |
| Data | JSON, YAML, TOML, CSV, XML, SQL, GraphQL, Protocol Buffers |
| Config | Dockerfile, Makefile, Terraform/HCL, INI, dotenv, Bazel |
See Supported Formats for the complete reference including MIME types and processing details.
For agents and scripts, the CLI is usually the simplest way to use Grounded Docs.
1. Index documentation (requires Node.js 22+):
npx @arabold/docs-mcp-server@latest scrape react https://react.dev/reference/react
Scraping a library version that already exists fails rather than overwriting it. Re-index it with --replace, or update it in place with refresh:
npx @arabold/docs-mcp-server@latest scrape react https://react.dev/reference/react --replace
For hash-routed SPA docs sites, enable hash preservation explicitly:
npx @arabold/docs-mcp-server@latest scrape my-spa https://docs.example.com/#/guide --preserve-hashes
2. Query the index:
npx @arabold/docs-mcp-server@latest search react "useEffect cleanup" --output yaml
3. Fetch a single page as Markdown:
npx @arabold/docs-mcp-server@latest fetch-url https://react.dev/reference/react/useEffect
--output json|yaml|toon to pick a structured format.fetch-url keep their text payload on stdout.--quiet to suppress non-error diagnostics or --verbose to enable debug output.The skills/ directory contains Agent Skills that teach AI coding assistants how to use the CLI — covering documentation search, index management, and URL fetching.
If you want a long-running MCP endpoint for Claude, Cline, Copilot, Gemini CLI, or other MCP clients:
1. Start the server:
npx @arabold/docs-mcp-server@latest
2. Open the Web UI at http://localhost:6280 to add documentation.
3. Connect your AI client by adding this to your MCP settings (e.g., claude_desktop_config.json):
{
  "mcpServers": {
    "docs-mcp-server": {
      "type": "http",
      "url": "http://localhost:6280/mcp"
    }
  }
}
The HTTP endpoint speaks MCP over Streamable HTTP, for protocol revision 2026-07-28 as well as earlier revisions. See Connecting Clients for VS Code (Cline, Roo) and other setup options, and Reverse Proxy Deployment to serve it under a path such as https://example.com/docs.
scrape_docs also accepts preserveHashes: true for documentation sites that use hash-based client-side routing.
Use it only for hash-routed SPAs; normal sites typically use hash fragments for in-page anchors.
scrape_docs rejects a library version that already exists (including one still queued or that failed); pass replace: true to rebuild it, or use refresh_version to update it in place.
docker run --rm \
  -v docs-mcp-data:/data \
  -v docs-mcp-config:/config \
  -p 6280:6280 \
  ghcr.io/arabold/docs-mcp-server:latest
The Docker image defaults to HTTP on 0.0.0.0:6280, serving the Web UI, API, and MCP endpoint. For stdio clients, use docker run --rm -i ghcr.io/arabold/docs-mcp-server:latest --protocol stdio. See Installation for configuration overrides.
Using an embedding model is optional but dramatically improves search quality by enabling semantic vector search.
Example: Enable OpenAI Embeddings
OPENAI_API_KEY="sk-proj-..." npx @arabold/docs-mcp-server@latest
See Embedding Models for configuring Ollama, Gemini, Azure, and others.
--preserve-hashes, MCP preserveHashes, or the Web UI "Preserve Hash Routes" checkbox only for docs sites that route with URLs like #/guide.scrapeMode=fetch, the scraper automatically upgrades the job to Playwright because plain fetch cannot evaluate client-side hash routes.preserveHashes setting by default, and CLI/Web refresh entrypoints can override it explicitly.llms.txt at the documentation subpath and site root before normal crawling. When found, the curated links become additional crawl seeds, and pages discovered this way prefer .md URL variants such as /guide/index.html.md or /page.html.md before falling back to the original page.Accept: text/markdown, text/html;q=0.9, */*;q=0.8 by default. Servers that support Markdown content negotiation, including Cloudflare Markdown for Agents, can return Markdown directly so the scraper bypasses HTML-to-Markdown conversion for cleaner output.Accept headers are preserved when provided.We welcome contributions! Please see CONTRIBUTING.md for development guidelines and setup instructions.
This project is licensed under the MIT License. See LICENSE for details.
67 followers · starred Jul 2025
427 followers · starred Dec 2025
77 followers · starred Sep 2025
59 followers · starred May 2025