
README
AToken: A Unified Tokenizer for Vision
This repository is the official implementation of AToken: A Unified Tokenizer for Vision.
Overview
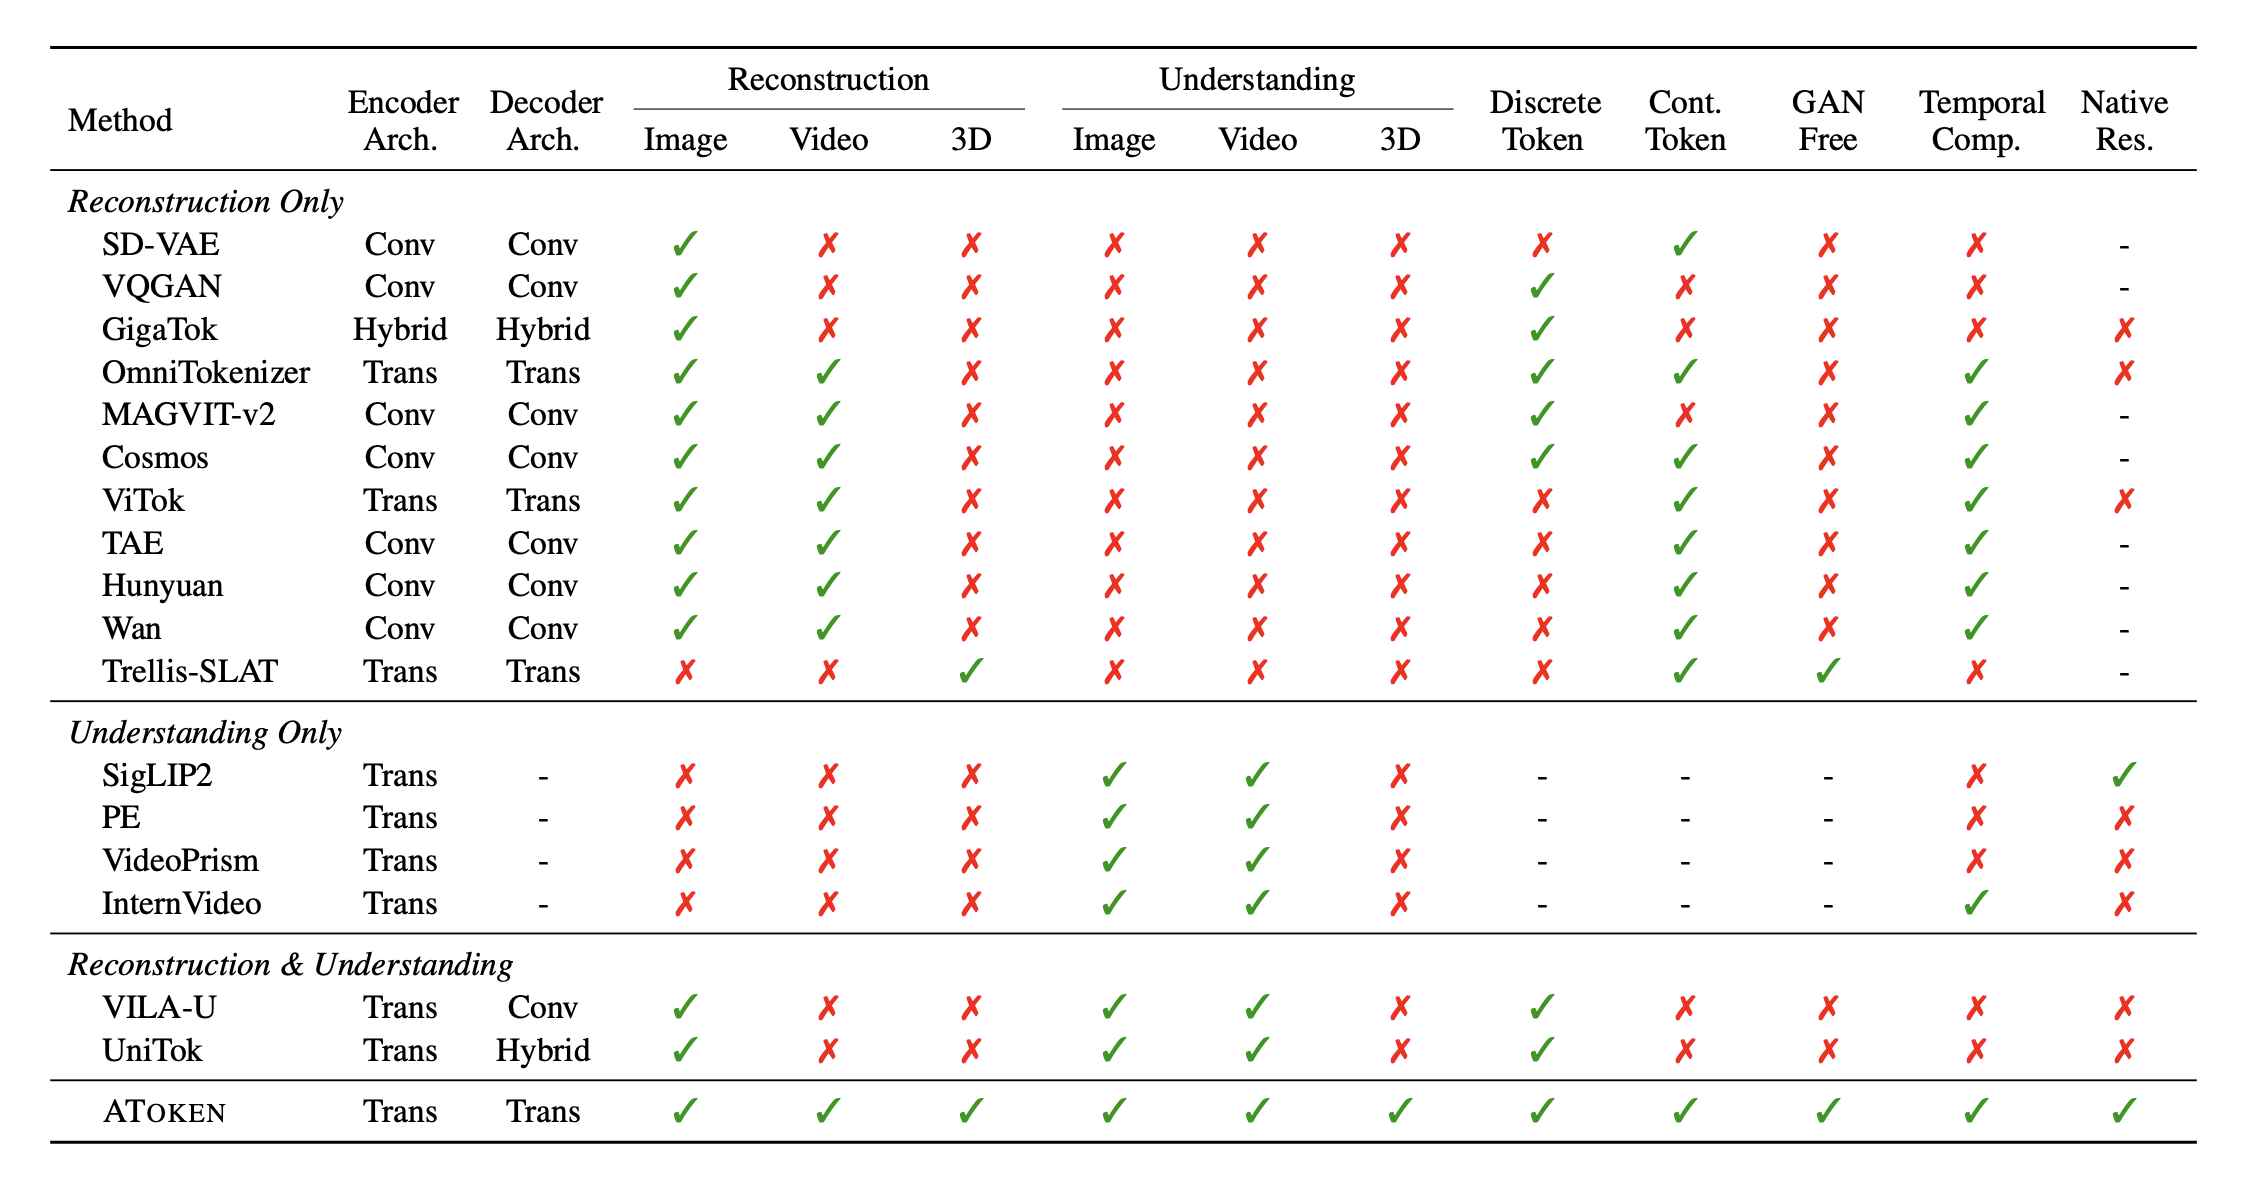
AToken is a unified vision tokenizer that handles multiple modalities (images, videos, and 3D) for both understanding and reconstruction through a single framework. It provides both continuous and discrete token representations, enabling flexible integration with various vision and multimodal systems.
Pretrained models
ViT models pretrained on SigLIP So400M:
| Model | Modalities | Token Type | Config | Download |
|---|---|---|---|---|
| AToken-So/C | Image, Video, 3D | Continuous | atoken-soc.yaml | link |
| AToken-So/D | Image, Video, 3D | Discrete | atoken-sod.yaml | link |
| 3D Decode GS | 3D | - | 3d_decode_gs.yaml | link |
Early Stage Models
Pre-trained weights from intermediate training stages:
| Model | Modalities | Token Type | Config | Download |
|---|---|---|---|---|
| AToken-So/C-s1 | Image | Continuous | atoken-soc-s1.yaml | link |
| AToken-So/C-s2 | Image, Video | Continuous | atoken-soc.yaml | link |
Download All Checkpoints
You can download all checkpoints at once using the provided script:
bash ./download_checkpoints.sh
Installation
# Clone the repository
git clone https://github.com/apple/ml-AToken.git
cd ml-AToken

# Install full dependencies.
pip install -e "."

# Install flash-attn:
pip install flash-attn --no-build-isolation
Install diff-gaussian-rasterization and run the install_gs.sh script to set up Gaussian Splatting dependencies:
git clone https://github.com/autonomousvision/mip-splatting.git
cd mip-splatting/submodules/diff-gaussian-rasterization && pip install . && cd ../../../
bash install_gs.sh
Quick Start
Interactive Examples
We provide comprehensive examples for all modalities and tasks in examples.ipynb
Basic Usage
- Load the Model
import torch
from atoken_inference.atoken_wrapper import ATokenWrapper

model_path = 'checkpoints/atoken-soc.pt'
config_path = 'configs/atoken-soc.yaml'

wrapper = (
    ATokenWrapper(config_path, model_path)
    .cuda()
    .to(torch.bfloat16)
)
- Prepare Your Image
# download and normalize the image.
url = "IMAGE_URL"
response = requests.get(url)
img = Image.open(BytesIO(response.content)).convert('RGB')
img_tensor = torch.from_numpy(np.array(img))  # (H, W, C)
img_tensor = (img_tensor.float() / 255.0) * 2 - 1  # normalize to [-1, 1]
img_tensors = [img_tensor]
- Encode and Reconstruct
# Encode all images as sparse.
img_sparse = wrapper.image_video_to_sparse_tensor(img_tensors)
task_types = ['image'] * len(img_tensors)  # One task type per image
kwargs = {'task_types': task_types}
rec, image_feat, x_no_proj = wrapper.inference(img_sparse, **kwargs)

img_list = sparse_to_img_list(
    img_sparse.cpu(), [4, 16, 16], task_types=task_types
)
rec_list = sparse_to_img_list(
    rec.cpu(), [4, 16, 16], task_types=task_types
)
Batch Processing
For processing multiple images or videos from folders, see test_atoken.py for a complete example.
License
AToken code is under Apple Sample Code License and model weights are released under the Apple ML Research Model TOU License. See LICENSE, MODEL-LICENSE for additional details.
Citing AToken
@article{lu2025atoken,
  title={Atoken: A unified tokenizer for vision},
  author={Lu, Jiasen and Song, Liangchen and Xu, Mingze and Ahn, Byeongjoo and Wang, Yanjun and Chen, Chen and Dehghan, Afshin and Yang, Yinfei},
  journal={arXiv preprint arXiv:2509.14476},
  year={2025}
}
Contributors


Similar repos


Languages
Jupyter Notebook
96.5%
Python
3.4%
README
AToken: A Unified Tokenizer for Vision
This repository is the official implementation of AToken: A Unified Tokenizer for Vision.
Overview
AToken is a unified vision tokenizer that handles multiple modalities (images, videos, and 3D) for both understanding and reconstruction through a single framework. It provides both continuous and discrete token representations, enabling flexible integration with various vision and multimodal systems.
Pretrained models
ViT models pretrained on SigLIP So400M:
| Model | Modalities | Token Type | Config | Download |
|---|---|---|---|---|
| AToken-So/C | Image, Video, 3D | Continuous | atoken-soc.yaml | link |
| AToken-So/D | Image, Video, 3D | Discrete | atoken-sod.yaml | link |
| 3D Decode GS | 3D | - | 3d_decode_gs.yaml | link |
Early Stage Models
Pre-trained weights from intermediate training stages:
| Model | Modalities | Token Type | Config | Download |
|---|---|---|---|---|
| AToken-So/C-s1 | Image | Continuous | atoken-soc-s1.yaml | link |
| AToken-So/C-s2 | Image, Video | Continuous | atoken-soc.yaml | link |
Download All Checkpoints
You can download all checkpoints at once using the provided script:
bash ./download_checkpoints.sh
Installation
# Clone the repository
git clone https://github.com/apple/ml-AToken.git
cd ml-AToken

# Install full dependencies.
pip install -e "."

# Install flash-attn:
pip install flash-attn --no-build-isolation
Install diff-gaussian-rasterization and run the install_gs.sh script to set up Gaussian Splatting dependencies:
git clone https://github.com/autonomousvision/mip-splatting.git
cd mip-splatting/submodules/diff-gaussian-rasterization && pip install . && cd ../../../
bash install_gs.sh
Quick Start
Interactive Examples
We provide comprehensive examples for all modalities and tasks in examples.ipynb
Basic Usage
- Load the Model
import torch
from atoken_inference.atoken_wrapper import ATokenWrapper

model_path = 'checkpoints/atoken-soc.pt'
config_path = 'configs/atoken-soc.yaml'

wrapper = (
    ATokenWrapper(config_path, model_path)
    .cuda()
    .to(torch.bfloat16)
)
- Prepare Your Image
# download and normalize the image.
url = "IMAGE_URL"
response = requests.get(url)
img = Image.open(BytesIO(response.content)).convert('RGB')
img_tensor = torch.from_numpy(np.array(img))  # (H, W, C)
img_tensor = (img_tensor.float() / 255.0) * 2 - 1  # normalize to [-1, 1]
img_tensors = [img_tensor]
- Encode and Reconstruct
# Encode all images as sparse.
img_sparse = wrapper.image_video_to_sparse_tensor(img_tensors)
task_types = ['image'] * len(img_tensors)  # One task type per image
kwargs = {'task_types': task_types}
rec, image_feat, x_no_proj = wrapper.inference(img_sparse, **kwargs)

img_list = sparse_to_img_list(
    img_sparse.cpu(), [4, 16, 16], task_types=task_types
)
rec_list = sparse_to_img_list(
    rec.cpu(), [4, 16, 16], task_types=task_types
)
Batch Processing
For processing multiple images or videos from folders, see test_atoken.py for a complete example.
License
AToken code is under Apple Sample Code License and model weights are released under the Apple ML Research Model TOU License. See LICENSE, MODEL-LICENSE for additional details.
Citing AToken
@article{lu2025atoken,
  title={Atoken: A unified tokenizer for vision},
  author={Lu, Jiasen and Song, Liangchen and Xu, Mingze and Ahn, Byeongjoo and Wang, Yanjun and Chen, Chen and Dehghan, Afshin and Yang, Yinfei},
  journal={arXiv preprint arXiv:2509.14476},
  year={2025}
}
Similar repos
Contributors
Languages
Jupyter Notebook
96.5%
Python
3.4%